Converting EPUB to PDF actually matters more than most people think
Most converters online will hand you a PDF that looks like garbage. The text either overflows the margins or gets crammed into tiny fonts because the software assumes every EPUB is a novel written in 12-point Times New Roman. It isn't. Some formats preserve reflowable text, others lock everything into fixed positioning, and the converter you use needs to understand that difference before it even opens the file. I don't use cloud-based converters for anything important. They strip metadata, mess with kerning, and often inject watermarks into the output without telling you. My process starts with Calibre. It handles the bulk of the heavy lifting — converting the XHTML content into a paginated PDF while letting me tweak the CSS on the fly. If the ebook has images, I adjust the DPI setting to 300 so they come through cleanly instead of looking like pixelated blobs. Here is where people get tripped up. EPUB files are essentially ZIP archives full of XHTML, CSS, and media. When Calibre converts them, it generates a temporary PDF stylesheet based on default assumptions. Those assumptions are usually wrong. I open the conversion settings, go to the PDF Output section, and set the page size to match what I actually want — A4 for technical books, US Letter for most trade paperbacks. Leaving it at the default "Automatic" setting produces inconsistent results depending on how the original author formatted the source.
I also disable the automatic font substitution. By default, Calibre will swap in its own font family when it can't find what the original uses. That sounds harmless, but it changes line breaks, shifts paragraphs onto different pages, and can break any CSS that was carefully positioned. I leave the original fonts embedded and let the PDF renderer deal with it. Most modern PDF viewers handle this fine.
The edge case that cost me two days
Last year I converted a technical manual that used SVG-based diagrams throughout. Every converter I tested either rendered the diagrams as blank white rectangles or crashed entirely. The EPUB had inline SVG elements that referenced external CSS classes defined in the package stylesheet. The converters were stripping the style context before rendering, which left the SVGs orphaned and invisible. The workaround was to extract the EPUB as a ZIP, edit the content.opf to reference the external stylesheets as absolute paths instead of relative ones, then repackage and convert. It took about forty-five minutes to fix a single file. Doing it manually for twenty books in a series would have been absurd, so I wrote a Python script using the epub library to batch-replace the relative paths before feeding everything into Calibre. The script runs in about three seconds per file. I haven't had to deal with orphaned SVGs since.
Get the Full Details
What the converters actually do under the hood
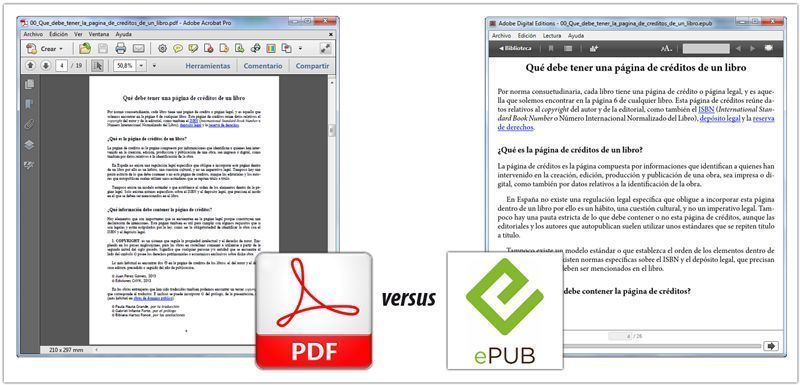
An EPUB is reflowable by design. The text flows based on the reader's screen size and font preferences. A PDF is fixed-layout by design. Each page is a static coordinate system. The conversion process has to make arbitrary decisions about where page breaks go, how many lines fit on each page, and what font size to lock in. There is no perfect answer to any of those questions. The best converters let you nudge the variables. The worst ones just guess. One thing almost no one mentions: the text flow algorithm in Calibre uses a simplified WebKit rendering engine. It does not support all CSS3 properties. Selectors like grid-template-columns, break-inside, and orphans/widows may be ignored silently. If your source EPUB relies on any of these for layout, the PDF output will look broken and you will have no idea why until you compare both side by side. I check for these properties by running a quick grep on the EPUB's stylesheet files before converting. Takes thirty seconds and saves you from confusion later.
Common pitfalls I see constantly
People convert EPUBs to PDF expecting the output to be readable on screen. A PDF with reflowable text is essentially an oxymoron. Once the content is paginated, it stays that way. If you plan to read the PDF on a phone, you are fighting the format. Use the EPUB directly. Convert to PDF only when you need a fixed document — for printing, for archival, for sending to someone who refuses to install an e-reader app. Another issue: embedded fonts. Some EPUBs ship with subset fonts that contain only the characters used in the book. When the PDF renderer tries to embed those subsetting tables, the resulting file can balloon to several hundred megabytes for a thin volume. I clip the font subsetting by setting the font embedding level to subset everything and then manually removing fonts I know I don't need. A typical fiction title goes from 200MB down to about 15MB after this step. Metadata loss is the third blind spot. The original author might have spent hours setting up series ordering, custom identifiers, and cataloging data in the OPF file. Most converters strip this out and produce a PDF with generic or missing metadata. I always run a metadata verification step after conversion — check the PDF properties against the original EPUB metadata using a simple script. If anything is missing, I inject it back with PyPDF2 before the file goes anywhere.
When conversion simply won't work
Not every EPUB converts cleanly. Any book with complex multi-column layouts, footnotes rendered as interactive overlays, or animated SVG illustrations will produce nonsense in PDF. These features rely on JavaScript execution and dynamic layout engines that PDF simply cannot represent. If you have a book like that, your options are limited: export the content as individual images and compile those into a PDF, or accept that the source format is the only viable delivery method. There is also the legal angle worth noting. DRM-protected EPUBs will not convert through Calibre unless you remove the encryption first. I don't discuss the mechanics of that here, but it is a separate and legally gray area depending on your jurisdiction. Assume you cannot convert a DRM-protected file without additional steps. For straightforward text-heavy EPUBs — textbooks, novels, manuals without heavy interactivity — the Calibre pipeline described above produces decent results in under ten minutes per file. The ones that matter — scanned PDFs masquerading as EPUBs, books with proprietary layout engines, anything with heavy JavaScript — require either specialized tools or acceptance that some formats are not meant to travel between each other.