Getting Real With Forms Data Analysis
Forms data looks straightforward at first glance because you fill something out and see numbers later. The reality is messier. People type differently, some fields get left blank, and the export formats your tools give you are rarely clean. I spent years watching teams treat a form export like it was a structured spreadsheet when it wasn't even close. The process starts with extracting responses from whatever system collected them, then cleaning and structuring that raw data before anything useful can be done with it. Most tools dump your results into CSV or JSON, and both come with their own headaches. CSV treats every cell as a string unless you coerce it otherwise. JSON responses often nest values inside arrays that require flattening before analysis. I learned this the hard way when a single dropdown question returned as [\"cherry\", \"blue\"] instead of two clean columns. That one row had to be split and pivoted, which ate an afternoon I could have spent on actual insight work. The typical workflow I use involves three phases: extraction, normalization, and analysis. Extraction means pulling the raw responses from your form platform, whether that's Google Forms, Typeform, Airtable, or something custom. Normalization means making sure every response follows the same structure so you can compare them. Analysis is where you actually answer the question you collected the data for in the first place.
When I was building a survey pipeline for a product team, one field came back as a free text box even though it was supposed to be a dropdown. Someone had misconfigured the form backend, and about forty percent of the responses contained unstructured text in that field. I ended up writing a script that matched keywords against the free text entries and mapped them back to the closest dropdown option. It wasn't elegant, but it saved the dataset from being discarded entirely.
Setting Up Your Extraction Pipeline
Most form platforms offer direct API access, but the quality of that access varies wildly. Google Forms gives you a read-only API that returns answers in a flat structure, which is relatively easy to work with. Typeform returns nested JSON that requires more transformation. Custom HTML forms that post to a database require you to query the database directly. Each path has tradeoffs. If you are using a low-code or no-code platform, you can usually connect your form export to tools like Zapier, Make, or n8n to automate the transfer. These platforms handle basic transformations, but they break down when you need conditional logic or complex field mapping. I found that a Python script pulling data directly from the API gave me far more control than any automation tool, even though it took longer to set up initially. One thing nobody warns you about is response deduplication. If your form doesn't enforce unique submissions properly, you will get duplicate entries. I once analyzed a dataset of two thousand responses and discovered three hundred of them were duplicates because the form allowed multiple submissions from the same email address without a proper flag. You should implement a deduplication step early, preferably by creating a composite key from the most reliable identifying fields available.
Get the Full Details

Cleaning and Structuring the Raw Output
Raw form exports are almost never ready for analysis. Common issues include inconsistent date formats, mixed data types in the same column, hidden characters in text fields, and missing values that are represented differently across platforms. One platform uses empty strings for blanks while another uses the literal text \"None.\" Both create problems if you don't handle them consistently. I keep a standard preprocessing script that handles these issues before any analysis begins. It coerces data types, normalizes dates to a single format, trims whitespace, and flags missing values using a consistent convention. This script runs on every new export so the downstream analysis always sees the same data shape. The initial investment in building this pipeline pays for itself quickly, usually cutting preprocessing time from several hours down to under fifteen minutes per export. Another practical consideration is how your analysis tool handles different data types. Excel treats columns inconsistently unless you explicitly format them. Pandas requires you to specify dtypes upfront or deal with the default behavior, which sometimes misclassifies numeric-looking strings as objects. I recommend always declaring your expected data types during ingestion rather than letting the tool guess. Getting this wrong causes silent errors that are difficult to trace later.
Running the Actual Analysis
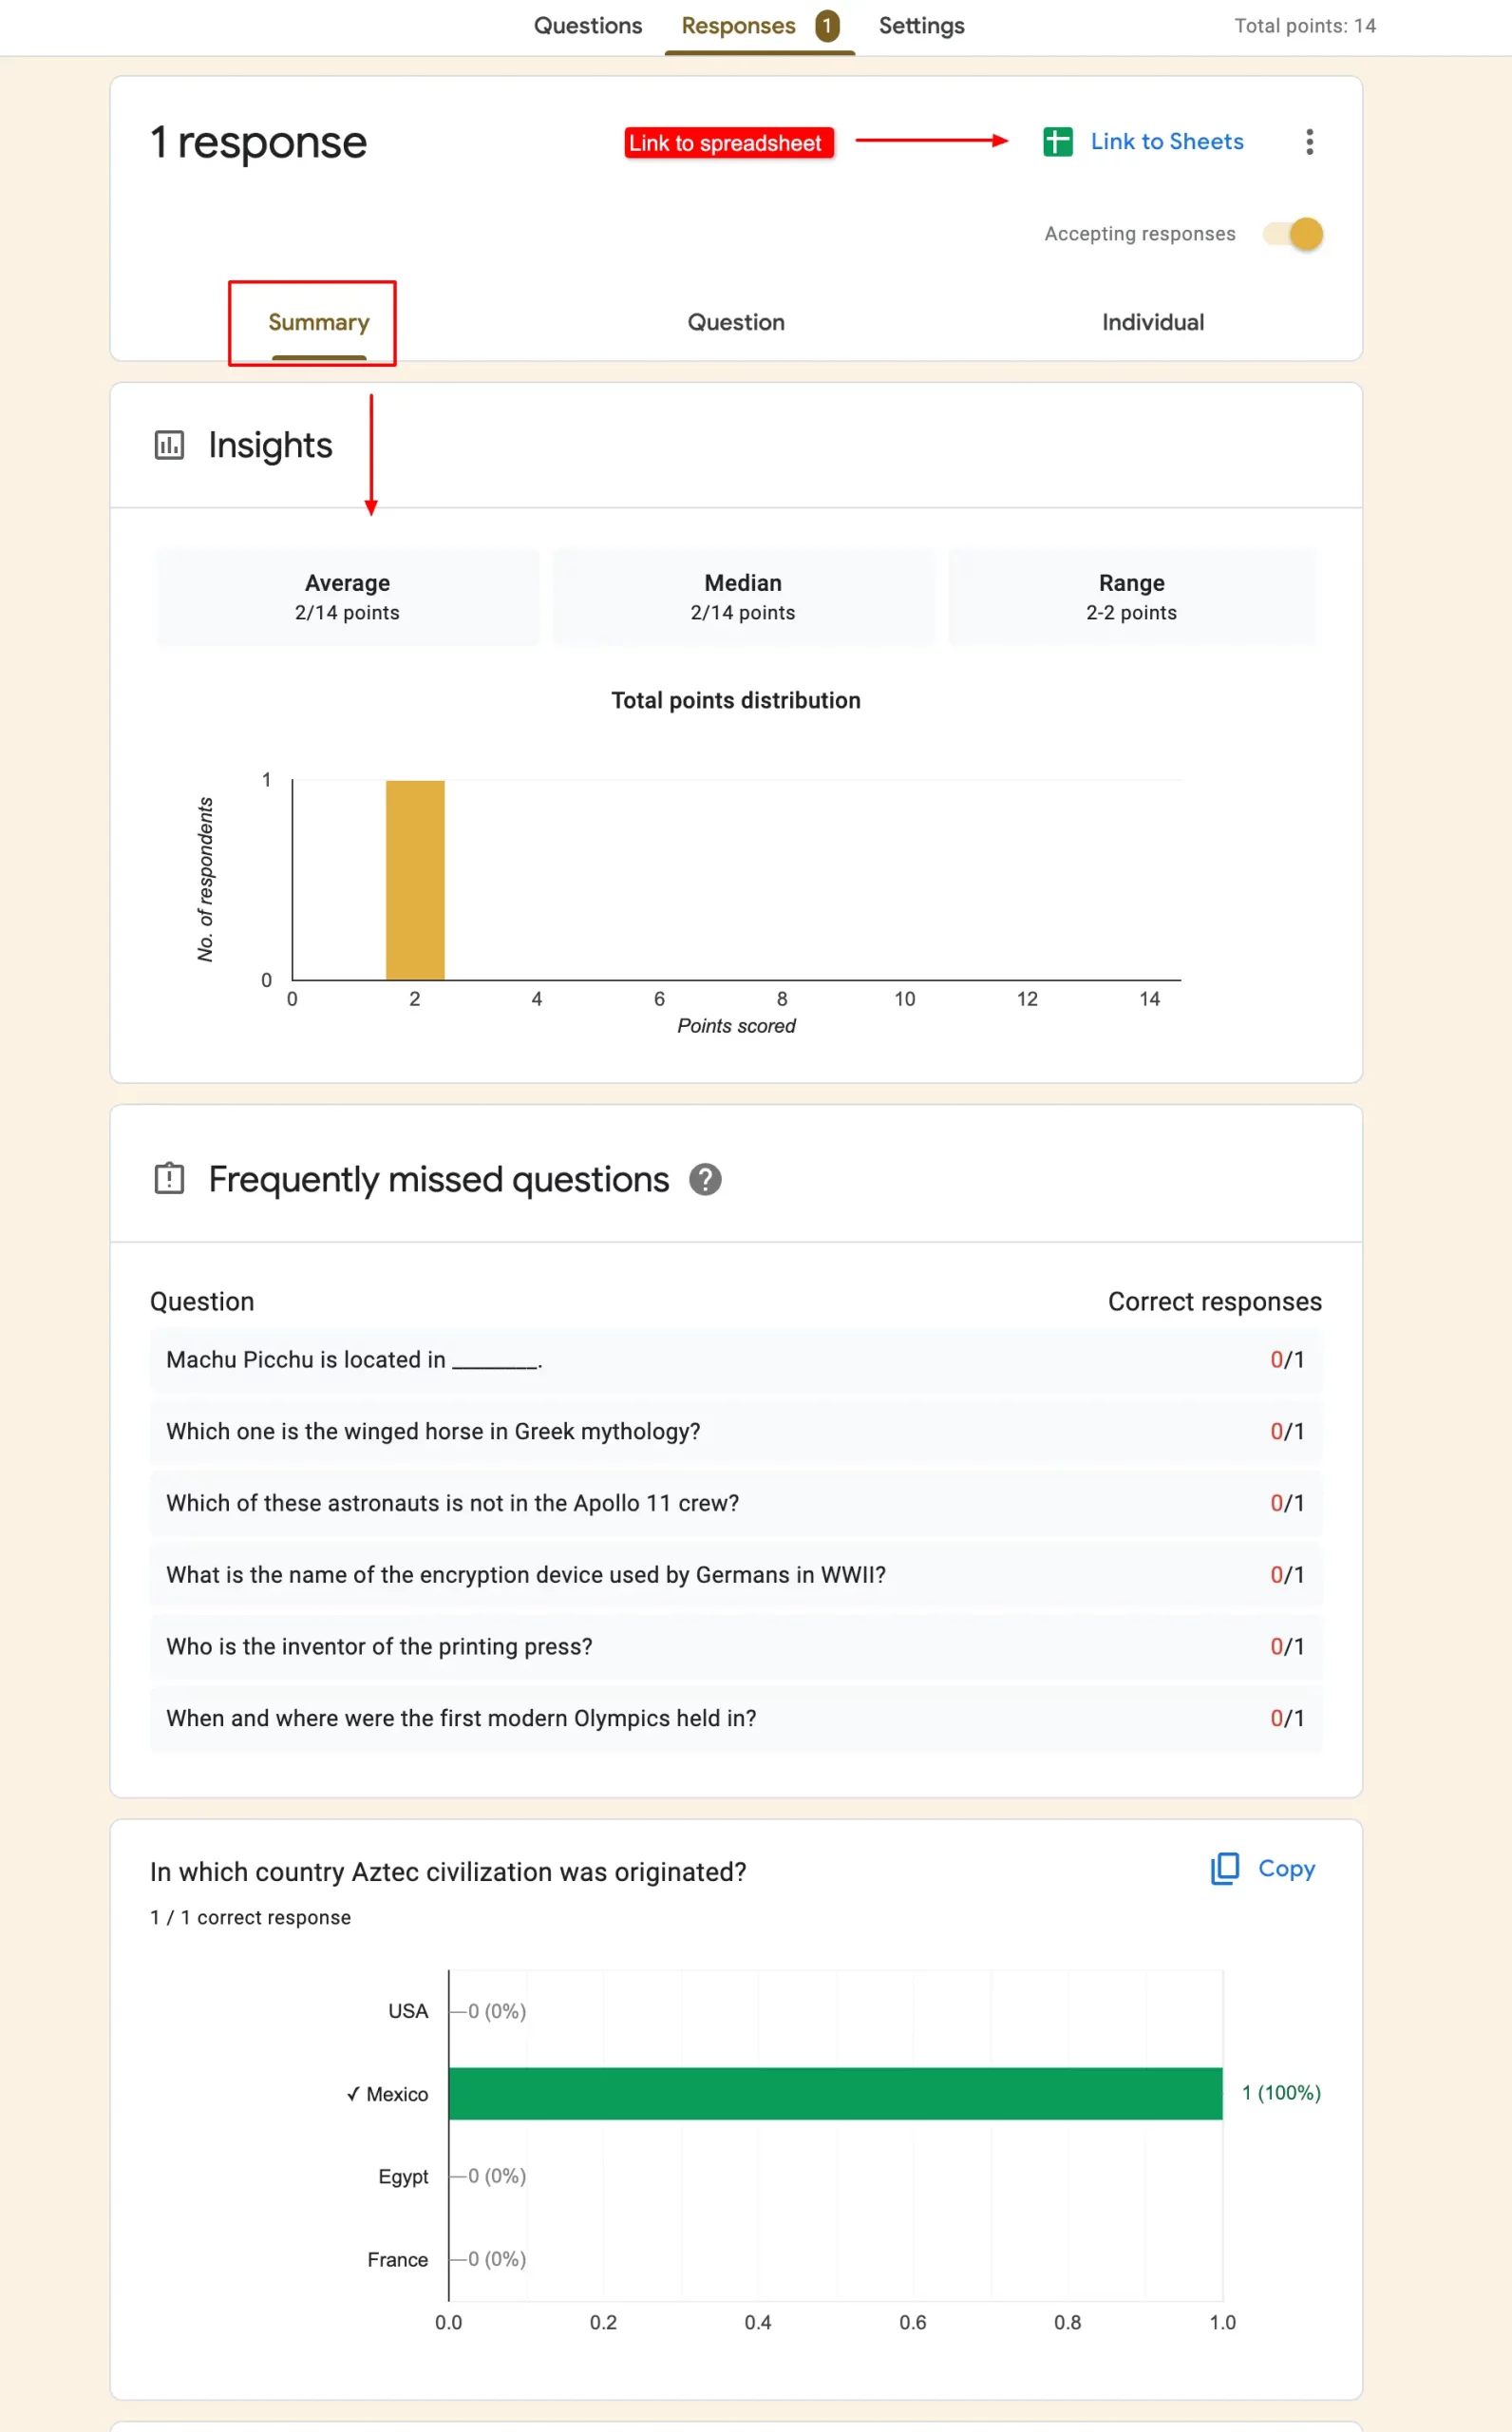
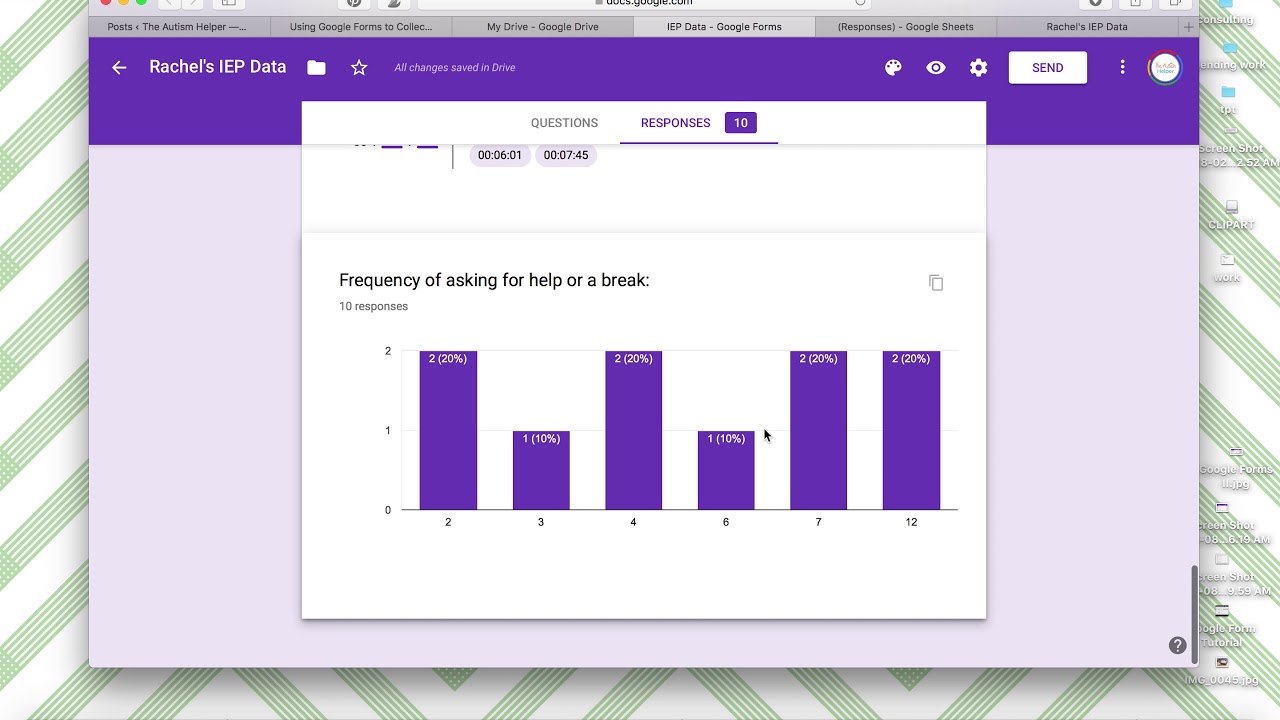
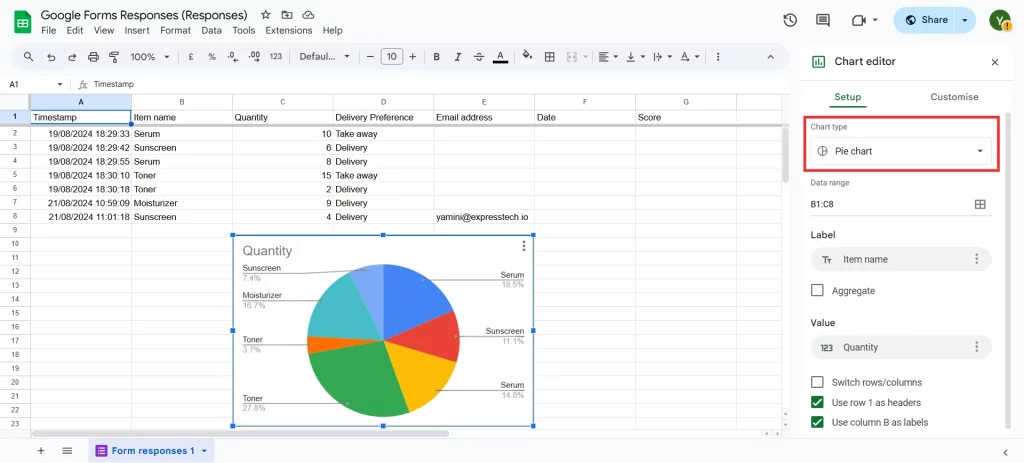
Once your data is clean, the analysis itself depends entirely on what question you are trying to answer. If you need descriptive statistics, cross-tabulations, or trend analysis over time, tools like pandas, Excel, or a BI platform will suffice. If you need predictive modeling or segmentation, you will likely need to move into a statistical environment or a dedicated ML tool. Frequency analysis is usually the starting point. Counting occurrences of each response option gives you a baseline understanding of your data before you attempt anything more complex. From there, you can move into cross-analysis, looking for relationships between fields. I often use pivot tables for quick exploration and pandas DataFrames for anything that requires repetition or automation. One counter-intuitive insight from experience is that the hardest part of forms data analysis is often not the technical work but defining what you are actually analyzing. People collect forms to answer questions they haven't clearly stated. Before writing any code or building any dashboard, you should be able to write down the specific decisions this analysis will inform. Without that clarity, you end up producing charts that are technically correct but practically useless.
Common Pitfalls in Forms Data Analysis
The most common mistake is treating all responses as equally valid without checking for quality. People rush through surveys, select the same option for every question, or provide nonsensical answers. I once worked with a dataset where approximately twenty percent of respondents finished a thirty-question survey in under two minutes. Those responses were clearly low quality and skewed several key findings until I filtered them out. Another frequent issue is selection bias that goes unnoticed. If your form is shared through a single channel, your sample will reflect the demographics of that channel rather than your intended population. This is particularly problematic when companies send satisfaction surveys only to customers who already have an account, because those respondents are self-selected and typically more engaged than the broader customer base. Time-based analysis also introduces its own complications. Response patterns can shift over the life of a form. Early respondents often behave differently from late respondents, and seasonal effects can influence answers in ways that are easy to miss if you treat the entire dataset as a single static collection. Splitting your analysis by submission date range is a simple practice that catches many of these issues before they contaminate your conclusions.

When Forms Data Analysis Fails Completely
There are situations where this approach simply does not work, and it is important to recognize those early rather than wasting time. Open-ended text responses without any structured fields provide limited analytical value unless you invest heavily in natural language processing. Even with NLP, the signal-to-noise ratio in free text is usually poor enough that the effort rarely justifies the output. Small sample sizes are another hard constraint. If your form received fewer than fifty responses, statistical analysis becomes unreliable regardless of how clean your data is. In those cases, qualitative review of individual responses is often more productive than attempting quantitative analysis. Highly complex forms with conditional logic that routes respondents through different paths can produce datasets where not every field is populated for every respondent. The resulting sparsity makes traditional cross-analysis difficult, and the structure of the data itself may require a different analytical framework than the one you initially planned. If you anticipate this kind of structure, it is worth designing your analysis around the branching logic before you collect the data rather than trying to reconstruct it afterward.
The bottom line is that forms data analysis works well when your questions are structured, your sample is reasonable, and you have already decided what the analysis should tell you. When those conditions aren't met, you are better off adjusting your data collection method or choosing a different approach entirely.