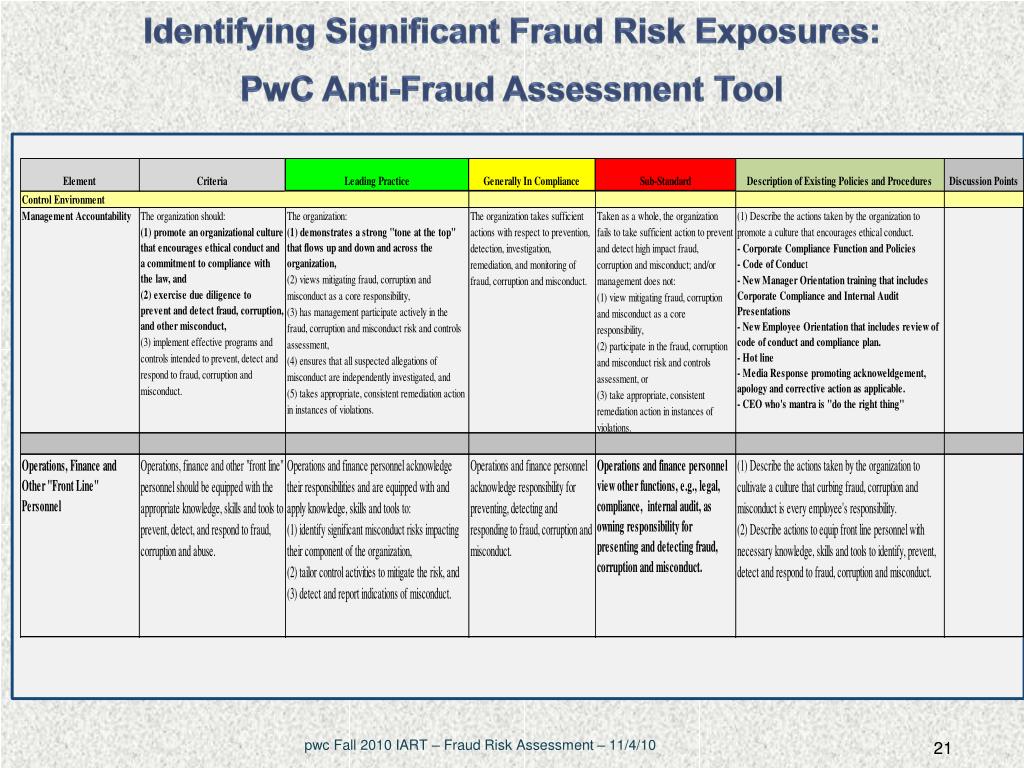
Most teams approach fraud risk assessment as a compliance checkbox exercise. That works until you need the assessment to catch something real. A proper assessment isn't about filling out a template your audit committee sends around in October. It is about mapping out where money can move through your systems without anyone noticing, then deciding which of those pathways actually matter.
I spent three years running fraud risk programs for payment platforms before moving into consulting. The thing nobody tells you is that the assessment itself rarely looks like the final output. The first draft is always a mess of stakeholder interviews and outdated process maps. The second draft catches the stuff you missed. By the third version, you usually have something that actually holds up when someone asks why you approved a particular control gap.
Starting With a Fraud Risk Assessment Example
Let me walk through how one of our assessments actually played out. We were working with a mid-size digital lending platform that had built out its fraud detection after Series B funding. Their problem was straightforward on paper — they were seeing elevated chargeback rates in two specific geographies and needed to understand why their existing controls weren't catching it.
The first thing we did was map every touchpoint where a fraudulent application could enter the system. Account creation, identity verification, income documentation, device fingerprinting, and the initial underwriting decision. We then asked each team involved what they thought the top risks were at each stage. The answers didn't align with what the data was actually showing. That gap is where the assessment lives.
Data analytics and stakeholder perception rarely match up on day one. The fraud team thought account takeover was the primary vector. The product team was focused on identity theft. Operations was worried about document forgery. When we pulled six months of actual incident data, synthetic identities and employment fraud accounted for roughly 60 percent of confirmed losses. The rest was scattered across smaller vectors that looked big in conversation but small in volume.
The Method We Actually Use
We run the assessment through a structured scoring model that evaluates each identified risk on three axes. Likelihood is scored from one to five based on historical incident data and industry benchmarks. Impact is scored from one to five by calculating the average loss per incident type, including direct financial loss and regulatory exposure. Detectability is the hardest to score accurately. It measures how quickly and reliably the current controls can identify the fraud type in real time.
The risk score is calculated by multiplying likelihood by impact and dividing by detectability. This gives you a prioritized list of fraud risks ordered by urgency, not just by which department complains the loudest. We then recommend controls matched to the score tier. High-risk items get dedicated monitoring and manual review layers. Medium-risk items get automated detection rules with periodic validation. Low-risk items are documented and reviewed quarterly to confirm they haven't migrated upward.
This framework takes about two weeks to complete for a platform of moderate complexity. The scoping and data gathering phase takes the longest. You need transaction logs, chargeback reports, customer support tickets, and internal investigation notes from at least six months. If your engineering team hasn't instrumented proper logging, you will lose several days just trying to reconstruct basic event timelines.
Real Edge Cases That Break Standard Assessments
I ran into a situation last year that illustrates why generic fraud risk assessment example frameworks fail in practice. A fintech client came to us after their regulator flagged potential lapses in their anti-fraud controls. They had been using a standard third-party risk assessment template. Everything checked out on paper. The problem was that their assessment had never accounted for API-based application fraud at scale.
Their platform allowed third-party partners to submit applications through an API integration. The fraud controls in place were designed for direct web and mobile app submissions. They monitored device fingerprints, IP reputation, and behavioral patterns, but none of those signals worked the same way when requests came from server-side integrations instead of consumer devices. We found that approximately 30 percent of fraudulent applications that quarter had entered through the partner API channel. The standard controls simply weren't looking there.
We added a new risk category to the assessment specifically for API-submitted applications. The scoring reflected the different detection capability — lower detectability meant a higher risk score even though the raw volume of fraudulent API submissions was initially lower than direct-channel fraud. This re-scoring triggered a recommendation to implement server-side anomaly detection, partner authentication verification, and application volume threshold monitoring per partner. The assessment changed what they prioritized, and more importantly, what they funded.
Common Pitfalls That Waste Time
One of the most expensive mistakes I see is treating the fraud risk assessment as a static document. It needs a defined refresh cycle. Quarterly is the minimum for any organization with active fraud vectors. Six months is acceptable if your product and transaction volume haven't changed materially. Annual reviews are fine for small operations with no digital transformation happening. Anything less frequent and you are operating on outdated risk assumptions.
Another mistake is scoring impact without factoring in regulatory consequences. A $500 fraud incident might look low-impact in isolation. But if that incident triggers a regulatory inquiry or public disclosure requirement, the cost structure changes completely. We started including a multiplier for regulatory-exposed products. Payment services, lending, and healthcare-adjacent financial products all carry that multiplier. It adjusts the risk score upward in ways that reflect actual business exposure rather than just raw fraud loss figures.
When This Approach Fails
The scoring model breaks down in environments with insufficient historical data. If you have fewer than 200 confirmed fraud incidents in your dataset, the likelihood scores become unreliable. You are essentially guessing, and you will know it once a new fraud vector emerges that your model didn't predict. In those cases, we fall back to expert judgment and industry benchmarking, which introduces its own biases but at least makes the assumptions explicit instead of hiding them inside a false numerical precision.
The model also struggles with novel fraud types that don't fit existing categories. Every assessment I have seen that was built purely from historical data missed something significant within the first twelve months of the next fraud cycle. The counter-measure is building in a separate risk identification track that operates independently of the scoring model. This is usually handled through threat intelligence feeds, industry loss reports, and internal investigation debriefs.
A properly documented Fraud Risk Assessment Example gives you a foundation, not an answer. The framework tells you where to look and how to prioritize, but the actual risk landscape shifts constantly. The people who do this well are the ones who treat the assessment as a living process rather than a deliverable you submit and forget.
Gallery Fraud Risk Assessment Example
Top 10 Fraud Risk Assessment Templates with Examples and Samples
Top 10 Fraud Risk Assessment Templates with Examples and Samples
Top 10 Fraud Risk Assessment Templates with Examples and Samples
Fraud Risk Assessment - What It Is, Examples, How To Conduct?
Risk Assessment for Fraud Vulnerabilities