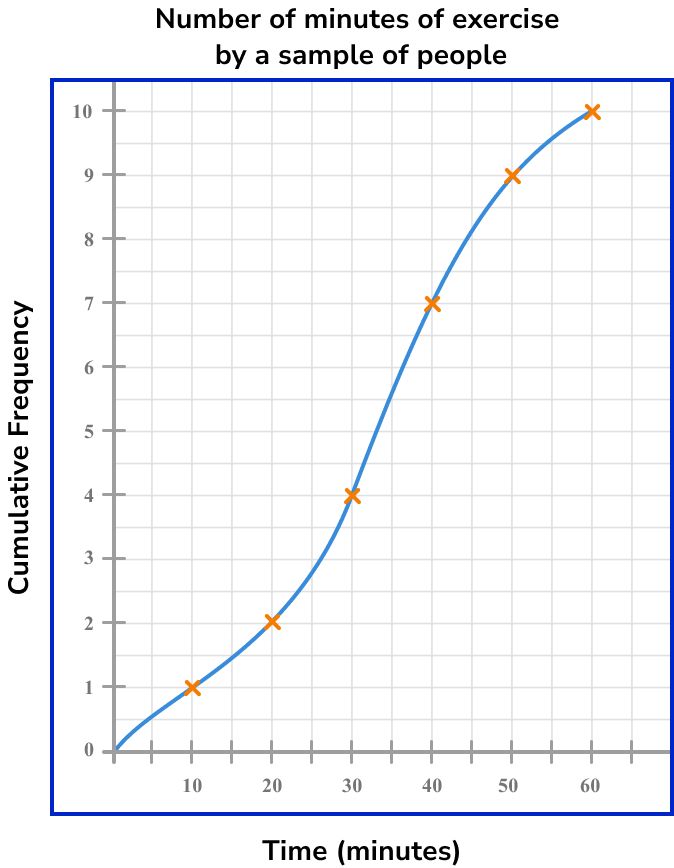
What Frequency Of A Graph Actually Means In Practice
Most people confuse this with basic chart types like bar graphs or line charts. It is not. Frequency of a graph refers to how you measure and display the rate at which events, values, or observations occur across a dataset — typically through histograms, frequency polygons, or grouped bar charts that show distributions rather than raw counts alone. I spent about three years working with network traffic data, and the first time someone asked me to produce a proper frequency distribution from raw packet capture logs, I wasted an entire week trying to force it through Excel. That was a mistake. The data had over four million entries with irregular time intervals. Excel chokes at around a million rows before it starts dropping precision. You need to handle this differently.
Frequency Of A Graph — How To Build One Correctly
Start with your raw data and decide what binning strategy makes sense for your distribution. This is where most people go wrong. They pick arbitrary bin sizes and wonder why the resulting frequency graph looks jagged or misleading. There are better ways. For continuous data, the Freedman-Diaconis rule is what I reach for first. It calculates bin width using the interquartile range and the number of data points. The formula is 2 times IQR divided by the nth root of n. This usually produces cleaner distributions than Sturges' formula, especially when your data is skewed or has outliers. Sturges tends to under-bin with large datasets. You end up with 10 bins for a million points and miss the actual shape of the distribution entirely. Here is the step-by-step process I use:
Sort your data. Calculate the IQR by subtracting the 25th percentile from the 75th percentile. Apply the Freedman-Diaconis formula to get your bin width. Round that bin width to a reasonable number — something like 0.5 or 1 or 10 depending on your scale. Create bins that cover the full range of your data. Count the observations falling into each bin. Plot those counts as bars or a polygon. Label your axes with the actual units. Do not skip the units. A histogram is the most common form of frequency graph. A frequency polygon connects the midpoints of each bin with straight lines, which makes it easier to overlay multiple distributions for comparison. If your data is categorical rather than continuous, you use a grouped bar chart instead. The principle is the same — count occurrences per category and display them visually.
Get the Full Details
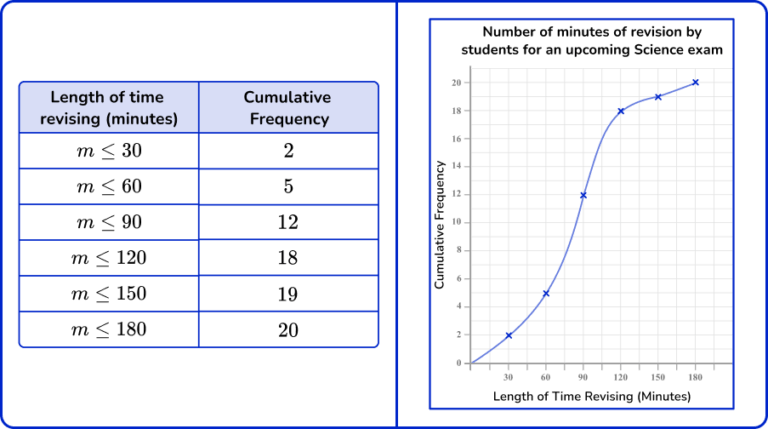
A Problem I Actually Faced And How I Fixed It
I had a dataset of customer support ticket response times that was extremely right-skewed. Most tickets resolved within 30 minutes, but a small number dragged on for weeks. When I applied a standard frequency graph with equal-width bins, the first three bins contained 94 percent of all observations. The rest of the distribution was crushed into invisible slivers on the right side. The graph was technically accurate but completely useless for communication. The workaround was switching to logarithmic binning. Instead of bins like 0-30, 30-60, 60-90, I used 0-30, 30-100, 100-300, 300-1000, and so on. This spread out the tail and revealed the actual sub-distributions I was missing. It also made the chart readable for anyone who had to look at it. I would recommend this approach any time your data spans more than two orders of magnitude. Another issue I ran into was overlapping frequency polygons when comparing multiple groups. With three or more distributions on the same axes, the lines become a tangled mess regardless of how carefully you choose your colors. The solution is to use semi-transparent fills under each polygon rather than just the line itself. Set the fill opacity to around 0.15 to 0.2. This lets viewers see where distributions overlap without sacrificing clarity. Solid fills at full opacity completely obscure everything behind them.
Tools That Actually Work For This
If your dataset is under 50,000 rows, Google Sheets will handle a frequency graph fine. Use the FREQUENCY function or just throw it into a pivot table and insert a chart from there. It takes about five minutes from raw data to a decent visualization. For larger datasets, Python with pandas and matplotlib is what I use. The pandas.cut function handles binning, and seaborn's histplot or displot functions do most of the heavy lifting with reasonable defaults. A typical workflow from raw CSV to published frequency graph takes me about 15 to 20 minutes including cleaning. Pure R with ggplot2 is equally capable and the syntax is slightly more concise for complex facetting when you need separate frequency graphs by category. Tableau works well if you are in an enterprise environment where everyone needs to self-serve this without writing code. Drag your measure onto columns, right-click and select "Create Bins," then build a bar chart. The bin size calculation is not as smart as Freedman-Diaconis by default, but you can override it manually. It usually takes about 10 minutes to set up once you know the steps.
When Frequency Graphs Fail Completely
They do fail sometimes. High-dimensional data is the main problem. If you are trying to show frequency across six or seven variables simultaneously, no single frequency graph can represent that clearly. You need a heatmap, a parallel coordinates plot, or you need to reduce the dimensions first using PCA or t-SNE. Don't try to force it into a histogram. Sparse data is another failure case. If your dataset has fewer than 100 observations and the values are spread across a wide range, your frequency graph will have mostly empty bins and a few tall ones. The distribution shape you see is essentially noise. In those situations, a strip plot or a simple sorted list with annotations is more honest than a frequency graph. Also be aware that frequency graphs show you the shape of a distribution but they do not tell you about relationships between variables. Two completely unrelated variables can each have an identical frequency distribution. If you need to understand correlations or dependencies, run a scatter plot or a correlation matrix alongside whatever frequency analysis you are doing. The frequency graph is a starting point, not the end point.

One more thing that trips people up: sample size matters more than most beginners realize. A frequency graph based on 50 data points looks smooth but the underlying distribution is unreliable. As a rule of thumb, you want at least 100 to 200 observations before the shape of a frequency graph becomes meaningfully stable. Below that, the binning choices dominate the visual output more than the actual data does. I usually flag this directly in reports when sample sizes are small so stakeholders do not read too much into the pattern.


