Design of experiments doesn't require a statistics degree, but it does require discipline most people skip.
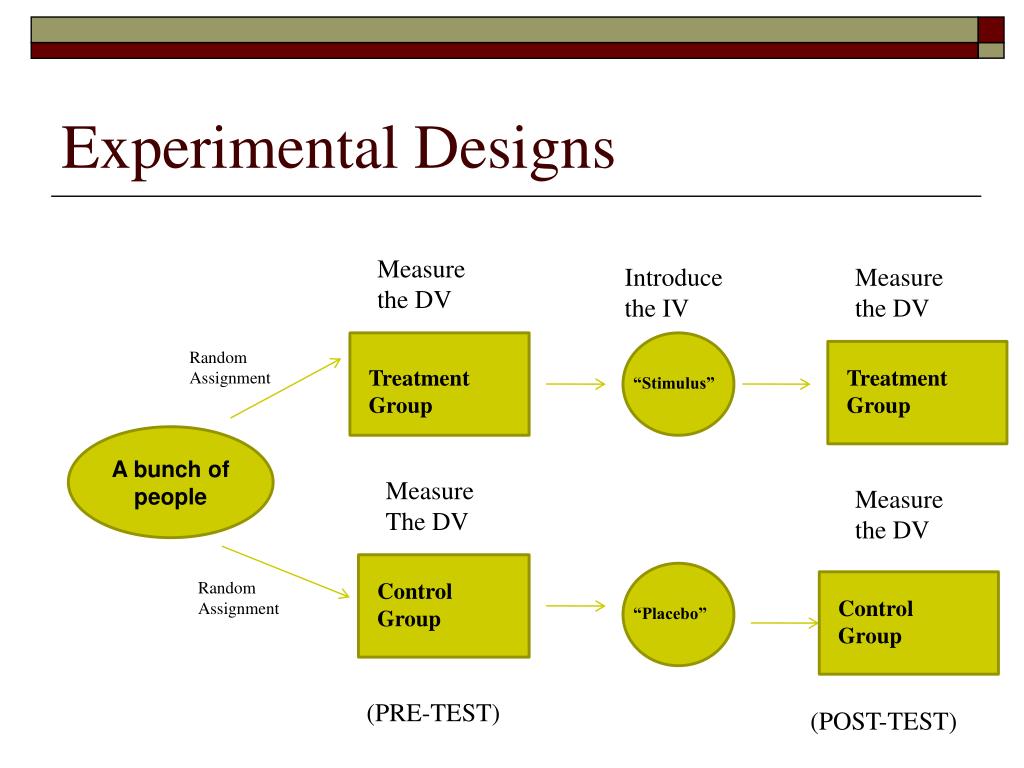
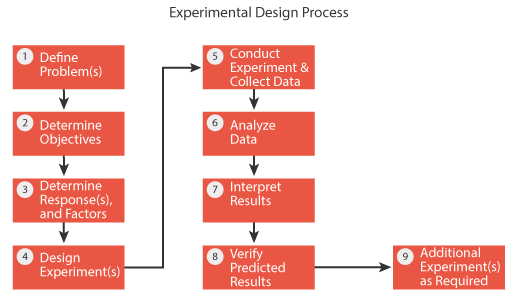
The people who use DOE well don't necessarily know more formulas. They tend to make fewer careless mistakes with factor selection, randomization, and aliases. I've watched good engineers waste three months of setup time because they didn't think through the experimental matrix before calling it a day. Here is how the process actually works in practice, stripped of textbook padding. At its core, DOE is just a structured way to vary inputs and observe outputs so you can separate real cause-and-effect from random noise. The alternative—changing one factor at a time, or just tweaking things until something looks better—is slower and frequently misleading. A properly designed experiment tells you not only which factors matter, but roughly how much they matter and whether they interact with each other. The typical workflow looks like this. You identify the response variable you care about first. Then you narrow the list of candidate factors down to the ones you can actually control during the run. You build an experimental matrix, usually starting with a two-level fractional factorial for screening. You randomize the run order. You run the trials. You analyze with ANOVA or regression. You check the residual plots. If the model passes diagnostics, you do a confirmation run at the predicted optimum settings and go from there.
It sounds mechanical because the mechanics matter more than intuition here. The part people underestimate is the initial factor reduction. I once spent two days building a 32-run DOE for a coating process before my engineer pointed out that two of the six factors were mechanically coupled on the equipment we had. Those two factors moved together no matter what we set them to, which meant we couldn't estimate their individual effects. We ended up dropping one, re-running the matrix at 16 runs, and got cleaner results in half the time. Factor screening isn't just a theoretical exercise. It is the difference between a usable model and a confounded mess.
Randomization, replication, and blocking
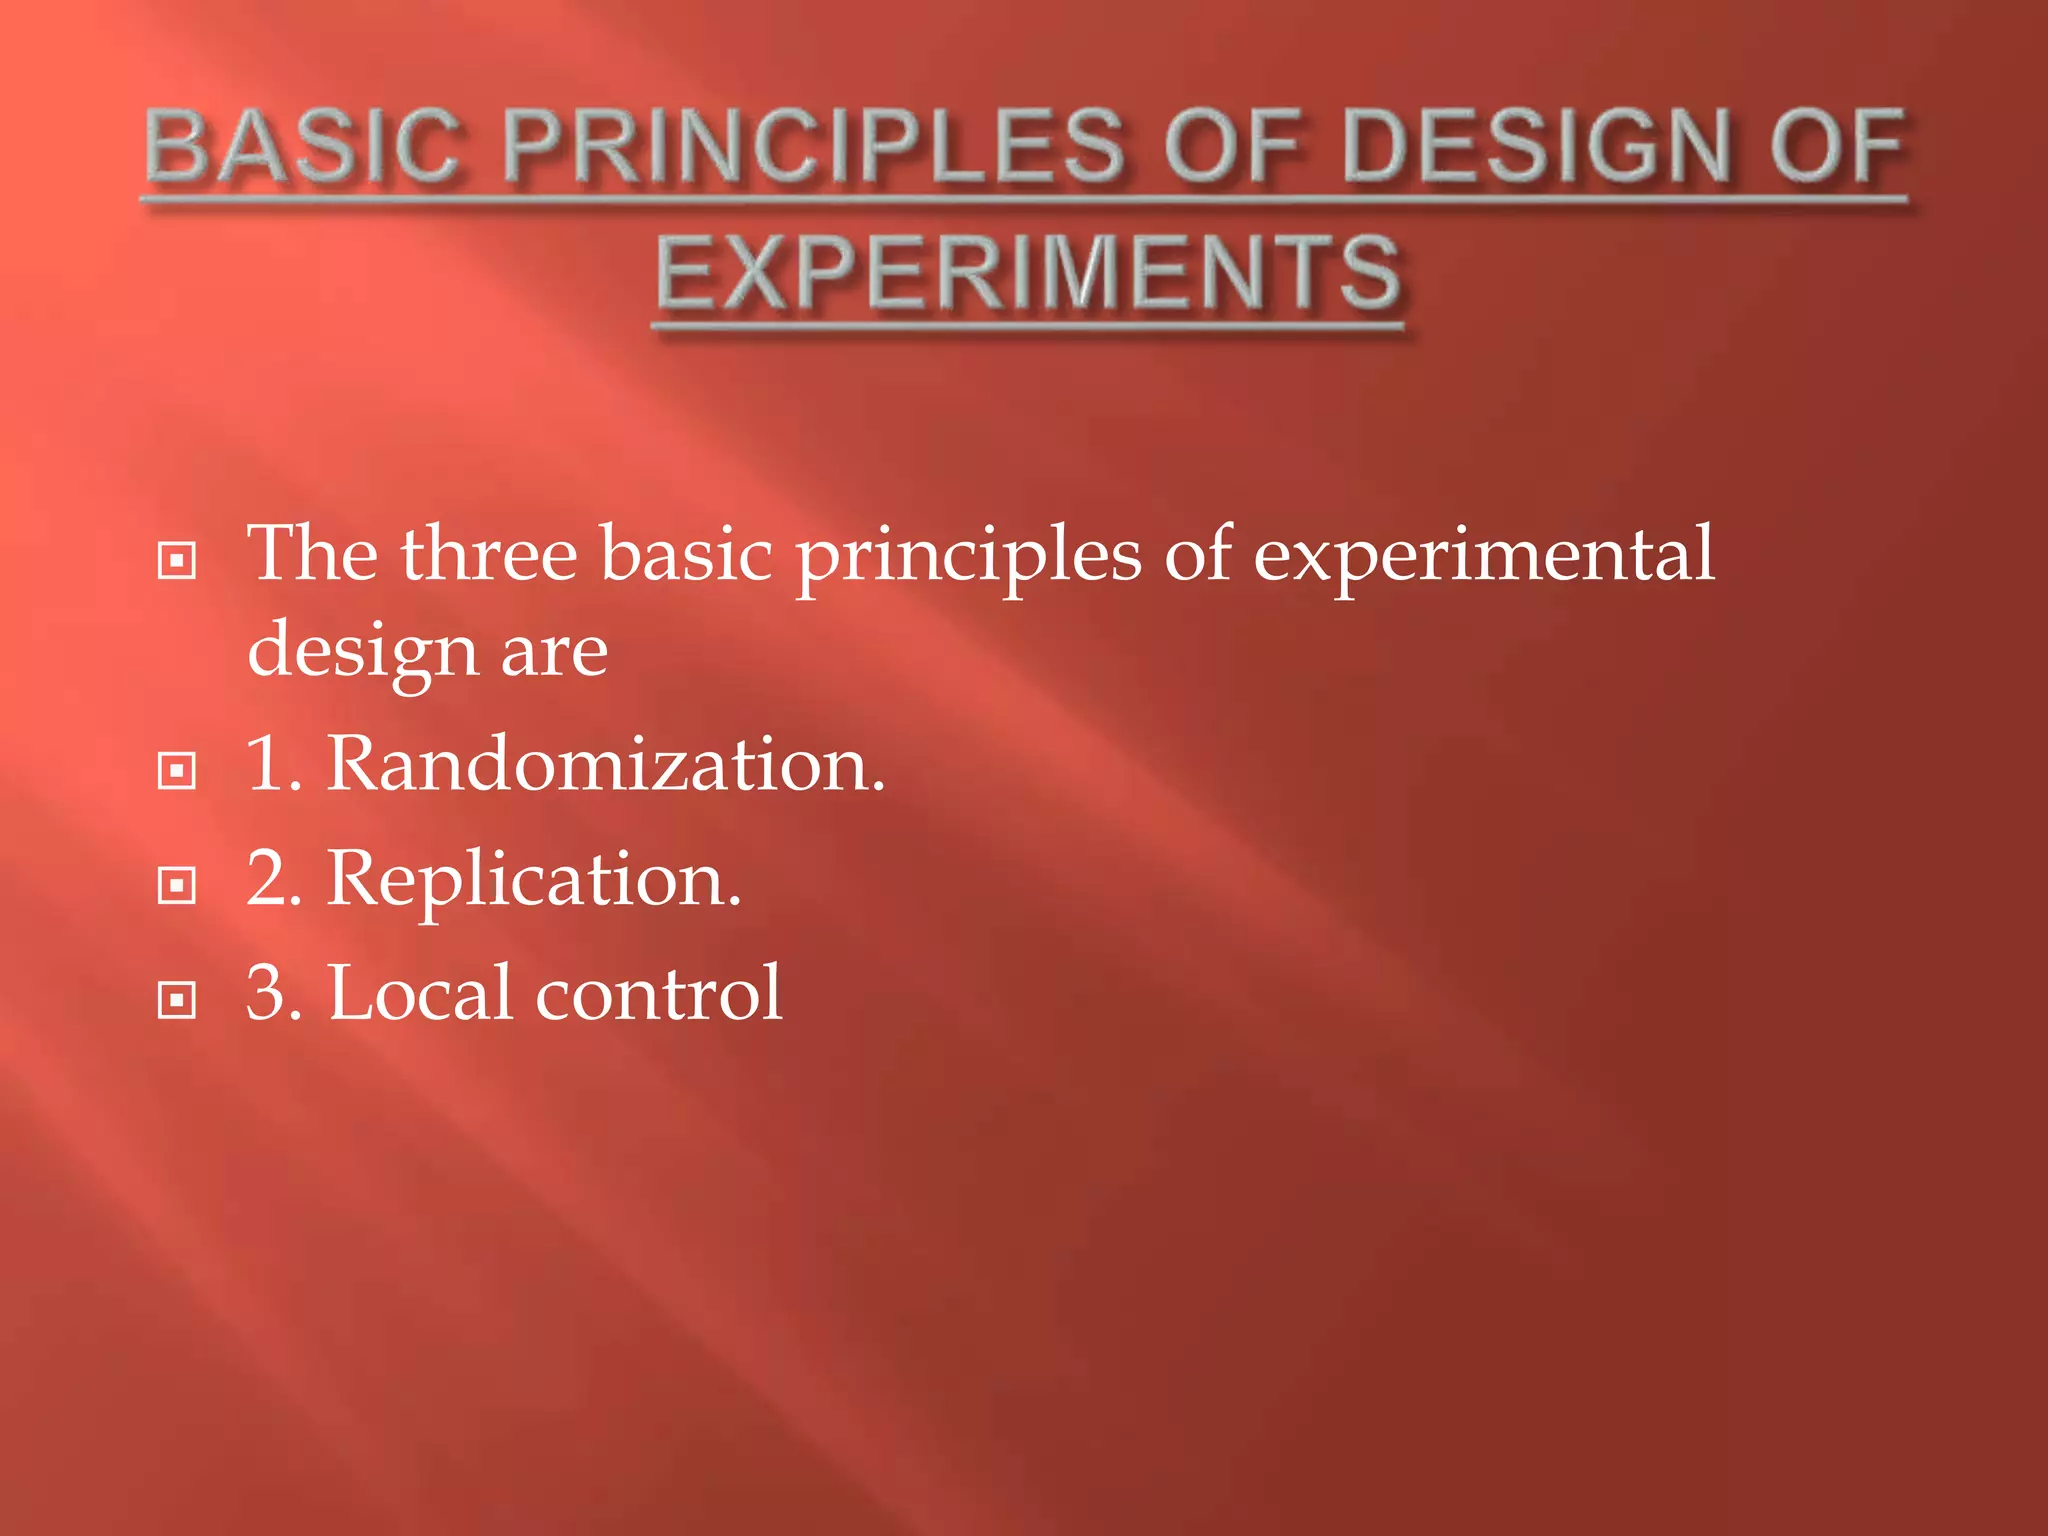
Randomization is not just a suggestion. It breaks the link between time-dependent drift and your factor levels. If you run all the low settings first and all the high settings second, any tool wear, ambient temperature change, or operator fatigue during the session will look like a factor effect. Randomization converts that drift into unstructured noise that the analysis can absorb. I always have my technicians generate the run order in software rather than writing it down manually. Even quick randomizations done by hand tend to cluster by factor level, especially when people get impatient halfway through. Replication means running the same treatment combination more than once. This gives you an estimate of pure experimental error without having to assume the error structure from the model itself. With two replicates per corner point in a 2^k design, you gain enough information to check for curvature and to build a legitimate lack-of-fit test. Without replication, you are stuck relying on pooled higher-order interactions as an error proxy, which is fragile and often wrong. Blocking is the practical response to nuisance variation you cannot randomize away. If you need to run experiments across two different material batches, or over two days with different ambient conditions, you treat the batch or day as a block. The block absorbs that systematic shift so it does not contaminate your factor estimates. The catch is that blocking reduces your degrees of freedom for error. Every block you add costs you one degree of freedom, and with small designs that cost adds up fast. I rarely run more than three blocks unless the nuisance variation is genuinely large.
Get the Full Details

Fractional factorials and aliasing
Fractional factorials cut run count by running only a fraction of the full 2^k combinations. A half-fraction of a 2^6 design drops you from 64 runs to 32. A quarter-fraction brings it to 16. The tradeoff is aliasing. Certain main effects and interactions become indistinguishable from each other because of the generator structure you chose. Resolution matters here. A Resolution IV design lets you estimate main effects without them being aliased with other main effects, but two-factor interactions may be aliased with each other. A Resolution V design protects main effects and two-factor interactions from each other, but requires more runs. The rule most people forget is that higher resolution does not automatically mean better. If your system obeys the sparsity of effects principle, which most physical systems do, a well-chosen Resolution IV design often gives you everything you need at half the cost of a Resolution V. Adding runs you do not need just inflates experimental overhead without improving the decision quality. I ran into a concrete aliasing problem on a plastic extrusion project. We built a 2^5-1 half-fraction design and found a strong effect attributed to barrel temperature. But when we examined the alias chain, that estimate was mixed with a two-factor interaction between screw speed and haul-off rate. The alias structure told us the effect we were reading could be either the main effect, the interaction, or both. We ran a fold-over design to break the alias, which doubled the runs from 16 to 32, but it gave us clean separation between those effects. The original model would have led us to adjust barrel temperature when the real lever was the speed-to-haul-off ratio. That kind of misattribution is invisible inside a single fractional run.
Analysis and model validation
The analysis stage is usually where the rubber meets the road. You fit a regression model, run ANOVA to identify significant terms, and then check residuals. Residual plots are not optional filler. They are your primary diagnostic for model adequacy. If the residuals show a funnel shape, you likely have heteroscedasticity and need a variance-stabilizing transformation. If they show a curved pattern against a factor, you have missing curvature and should consider axial points or a response surface design. If they cluster by run order, your randomization failed or something drifted during the session and you need to model that as a block or time covariate. P-value hunting is the most common analytical mistake. People treat any term below 0.05 as gospel and anything above as noise. In practice, p-values from DOE are approximate. They depend on the error estimate you are using, which depends on whatever you decided to pool or drop from the model. A term with a p-value of 0.07 might be practically important if the effect size is large relative to the process variation. A term with a p-value of 0.03 might be statistically significant but irrelevant if the coefficient moves the response by a negligible amount. I always look at both the magnitude of the effect and its confidence interval before committing to a change. Confirmation runs are where most teams cut corners. After you identify your optimum factor settings from the model, you must verify the prediction with actual runs at those settings. I typically run three confirmation replicates. Three gives you a reasonable check on both the mean prediction and the variability around it. If the confirmation result falls outside the prediction interval, your model is incomplete. That usually means you missed an interaction, a nonlinear term, or a lurking variable that the experimental design did not capture.
When DOE breaks down
Design of experiments is not a universal fix. It struggles in a few common scenarios, and knowing when to walk away matters more than forcing the method to work. The biggest failure mode is non-linearity in systems where the response curve has sharp thresholds or saturation points. A two-level factorial design assumes the response is approximately linear between the low and high settings. If your process has a hard cutoff at a certain parameter value, the model will miss it entirely. In those cases, you need either a response surface design with center and axial points, or you need to split the design space into separate regions and build local models for each. Trying to force a global linear model onto a threshold system produces garbage predictions. Another failure mode is single-unit experiments. If you can only produce one unit per condition, you cannot estimate pure error, you cannot replicate, and your diagnostics are almost worthless. This shows up frequently in chemical synthesis optimization and some semiconductor processes. The workaround is usually a sequential approach: run a small screening experiment to identify the most promising region, then invest in replication within that region, or switch to a Bayesian optimization framework that can handle limited data without requiring repeated runs at every point.

Expensive-to-run experiments also expose the cost structure of DOE. A full central composite design for five factors requires 32 factorial points, 10 axial points, and several center points. That is easily 50-plus runs before you even consider blocking or replication. For a process where each run costs thousands of dollars and hours of setup, this is prohibitive. In those situations, I lean toward D-optimal custom designs generated by software. They give you good model coverage with far fewer runs by selecting the most informative subset of candidate points rather than using a regular lattice. The tradeoff is that D-optimal designs sacrifice orthogonality and the clean alias structure of standard factorials, so the analysis is slightly less straightforward. But the cost savings are real and often decisive.
Practical workflow recommendations
Start with a clear response variable. Vague goals like "improve quality" produce vague experiments. Pick a metric you can measure consistently, such as tensile strength, defect rate per thousand units, or cycle time. Define the measurement system beforehand and check that it has acceptable repeatability and reproducibility. A flawed measurement system ruins any DOE faster than a poorly chosen design. Limit the factor list aggressively. More than six or seven factors in a screening design creates a combinatorial explosion that forces you into very low resolution. If you have more candidates, split them into rounds. Run a Resolution IV screen first, drop the inactive factors, then rebuild a tighter design with the survivors. Invest in proper randomization software. Minitab, JMP, Design-Expert, and Python libraries like pyDOE2 all handle run-order randomization. Do not type run orders by hand. Even a quick shuffle in Excel is better than mental randomization, which is biased toward clustering.
Document every run condition in real time. Not just the factor settings, but the ambient conditions, material lot numbers, tool wear state, and any deviations from the planned protocol. When residuals look strange during analysis, the log is where you find out why. I have traced entire anomalous residual patterns back to a single operator substitution on a Tuesday afternoon. Without the log, that clue disappears. Do not treat the final model as the final word. Production conditions drift. Supplier materials change. A model built on one material lot may not transfer cleanly to another. Plan for periodic re-validation, and keep a running record of which factors are stable versus which show sensitivity over time. The factors that matter most in the lab are not always the same ones that matter on the production floor.
Summary of what to watch for
The methods are straightforward. The discipline is not. Aliasing hides real effects inside inflated main effects. Poor randomization lets time drift masquerade as factor effects. Missing confirmation runs leave you confident in a model that may not predict reality. Factor creep turns a clean 16-run screen into an uninterpretable mess of correlated inputs. Design of experiments works when you respect its assumptions and verify its outputs. It fails when you treat it as a black-box optimization tool that produces answers without requiring you to understand what those answers actually represent. The experiments that save the most time are the ones where the design was planned carefully before the first run started, not the ones where the team pivoted three times because the initial results looked weird.