Why Your Multicore Code Is Probably Slower Than Single Thread
I spent three weeks last year debugging a data processing pipeline that used more CPU time on an 8-core machine than it did on a single core. It turned out I had seven threads fighting over a single lock every 200 milliseconds. That is not a rare situation. It is the most common mistake I see in production systems that claim to be parallel. The Fundamentals Of Parallel Multicore Architecture come down to two things: keeping threads fed with independent work, and keeping them from colliding with each other when they touch shared state. Everything else is optimization noise until those two are solid.
Fundamentals Of Parallel Multicore Architecture
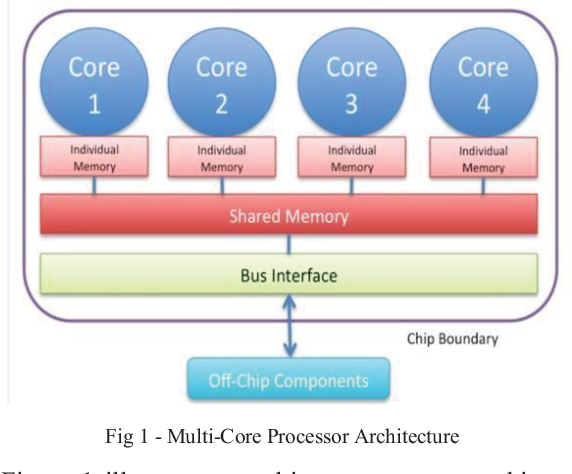
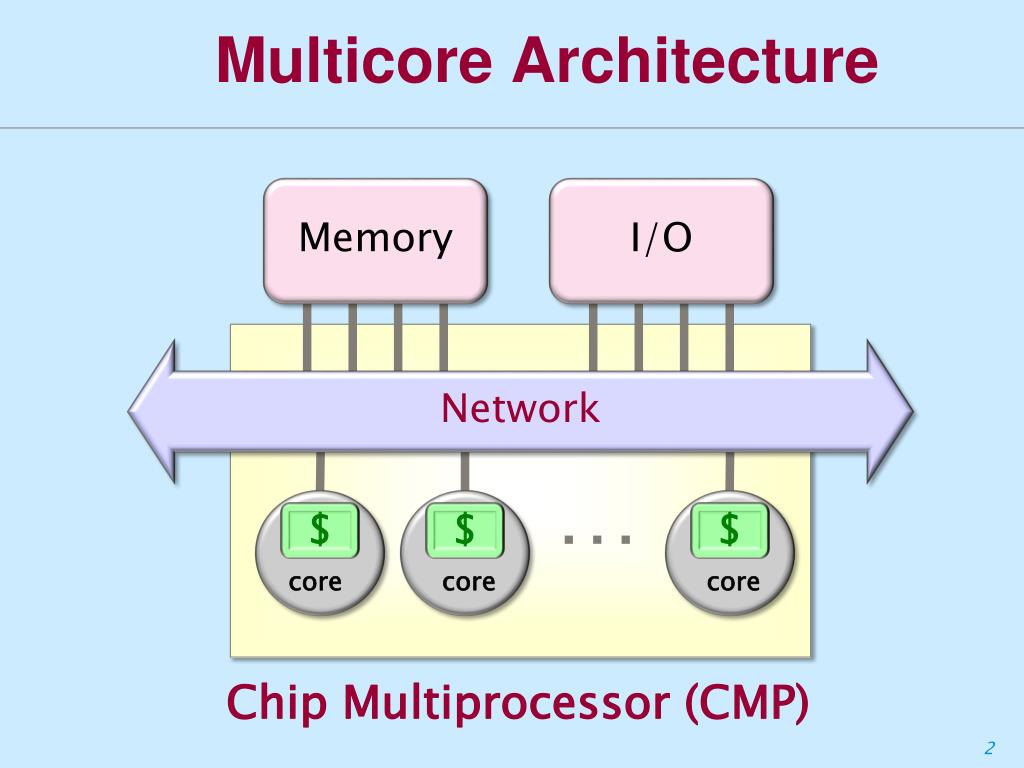
Modern processors do not have one big brain. They have multiple execution units wired to different caches, connected by an interconnect, all sharing main memory. That hierarchy matters for how you write parallel code. The difference between L1 and L2 cache hit time is often the difference between a thread doing useful work and a thread spinning uselessly. Start by understanding what your hardware actually gives you. A typical server CPU has two sockets, each with its own memory controller and PCIe lanes. Accessing NUMA-local memory is noticeably faster than reaching across the interconnect to the other socket. I learned that the hard way when I moved a message queue processor from a single-socket setup to a dual-socket machine and saw latency triple on certain message types. The fix was binding worker threads to specific NUMA nodes and routing message affinities accordingly. Once I did that, latency dropped back to where it was on the single-socket box. Here is the practical breakdown of what you need to get right.
Thread lifecycle management is not something you outsource. Creating and destroying threads for every unit of work adds overhead that scales poorly. I use a fixed pool sized to match the number of hardware threads minus two for monitoring and I/O workers. That has been the sweet spot in my experience across Java, C++, and Go projects. Data partitioning determines whether your parallelism works or falls apart. If you split your dataset into chunks that still require synchronized access to the same data structures, you have not parallelized anything. You have just added serialization points. I partition by key range or by index ranges that map to disjoint memory regions. When that is not possible, I use append-only structures and merge results in a final reduction phase instead of locking during the parallel work. Avoiding false sharing is where most people lose their speedup. Two threads on different cores writing to different variables that happen to share the same cache line will cause constant cache invalidation traffic. The cache coherency protocol kicks in and each write forces the other core to reload its cache line. On a 32-thread machine with poor data layout, I have seen 40 percent of total CPU time spent on cache coherency traffic instead of actual computation. The workaround is straightforward: pad your per-thread data structures to cache line boundaries. In C++ that means alignas(64). In Java, you can use allocation padding or switch to off-heap arrays with explicit index management. Go does not give you direct control over cache lines, so I restructure the data layout so per-goroutine state naturally falls into separate allocations.
Get the Full Details

Common Pitfalls That Kill Speedup
Granularity matters more than people admit. Dividing work into tiny tasks creates more scheduling overhead than the work itself. I once parallelized a matrix transpose where each thread handled a single row. The threading overhead consumed more than the computation. When I increased the granularity to blocks of 32 rows per thread, the runtime dropped by about six times. The optimal block size depends on your cache geometry and the cost model of your operation. Benchmark it with your actual data, not a synthetic example. Lock contention is the other killer. The textbook answer is "use lock-free data structures." That advice is mostly wrong for production systems. Lock-free code is extremely difficult to get right, and hardware atomic operations have real costs too. The better approach is to minimize the scope of shared state. If every thread works on its own data and shares nothing until a final merge, you need no locks during the parallel phase. I structure my pipelines this way: map phase with no shared mutation, then a reduce phase that serializes briefly at the end. This pattern gives me predictable scaling from 2 to 16 threads with almost no tuning. Synchronization primitives are not free. Even an uncontended mutex acquisition and release costs somewhere between 25 and 100 nanoseconds on modern hardware depending on the platform. A lightweight read-write lock is slightly cheaper for reads but more expensive for writes than a plain mutex. Condition variables add another layer of cost because they involve kernel transitions on some platforms. If you are doing fine-grained synchronization inside a hot loop, you are better off restructuring the algorithm than layering on more synchronization.
How to Actually Measure Your Parallel Performance
Time your code with the compiler optimizations on and realistic data volumes. The wall clock time will mislead you if you ignore CPU time. Run with perf on Linux or Instruments on macOS and look at cache miss rates, branch mispredictions, and context switches. These numbers tell you what is actually happening inside the hardware. When I saw cache-miss rates jump from 2 percent to 18 percent after adding more threads, I knew immediately that false sharing was the culprit even before I looked at the code. Amdahl's law is still relevant. If 15 percent of your workload is inherently sequential, the maximum speedup you can ever achieve is about 6.7x regardless of how many cores you throw at it. Identify the sequential portion early and aggressively. In practice, the sequential part is often smaller than people assume because they include garbage collection pauses or logging as sequential work. Separate measurement is important here. Profile your parallel code with the logging and serialization steps excluded to get a true picture of your parallelizable fraction. I also run a baseline single-thread version on the same machine. If your multi-threaded version is slower than single-threaded on a small input, you have overhead that dominates. Scale up the input and rerun. If speedup plateaus or degrades past a certain core count, you have either contention or oversubscription. Reduce the thread count to match your physical hardware threads and remove the hyperthreading overhead. Most real workloads scale well up to the number of physical cores and then flatten or regress on logical cores.
What Does Not Work and When to Walk Away From Multithreading
Thread-per-request architectures for I/O bound workloads are almost always a mistake on modern systems. Event loops or async runtimes handle thousands of concurrent connections with a handful of threads. The overhead of creating a new thread per request becomes prohibitive around a few thousand concurrent operations. I switched one of my services from a thread pool of eight hundred to an async I/O model and reduced memory consumption by roughly 70 percent while improving throughput by about 40 percent. GPU parallelism is not a universal answer. Transferring data to and from the GPU introduces latency that dominates for small computations. If your per-element work is less than a few microseconds and your dataset fits comfortably in CPU cache, the GPU overhead makes everything slower. GPUs shine when you have massive uniform workloads like image processing or numerical simulations where the arithmetic intensity justifies the transfer cost. Sometimes the right answer is not parallelism at all. A well-tuned database query with proper indexing often outperforms a custom parallel aggregation because the database engine already handles caching, partitioning, and memory management internally. Before building a custom parallel solution, check whether an existing tool solves 80 percent of the problem without the maintenance burden.

The fundamentals stay the same regardless of language or framework. Partition data so threads do not collide, manage thread lifetimes explicitly, measure everything, and accept that parallelism adds complexity that is only worth it when your workload is large enough to justify it. I stop recommending multithreading when the codebase growth outweighs the performance gain by more than two to one in terms of engineering effort. That is a conservative ratio, and in most cases it turns out to be generous.