
Gene Kranz and the Philosophy Behind "Failure Is Not An Option"
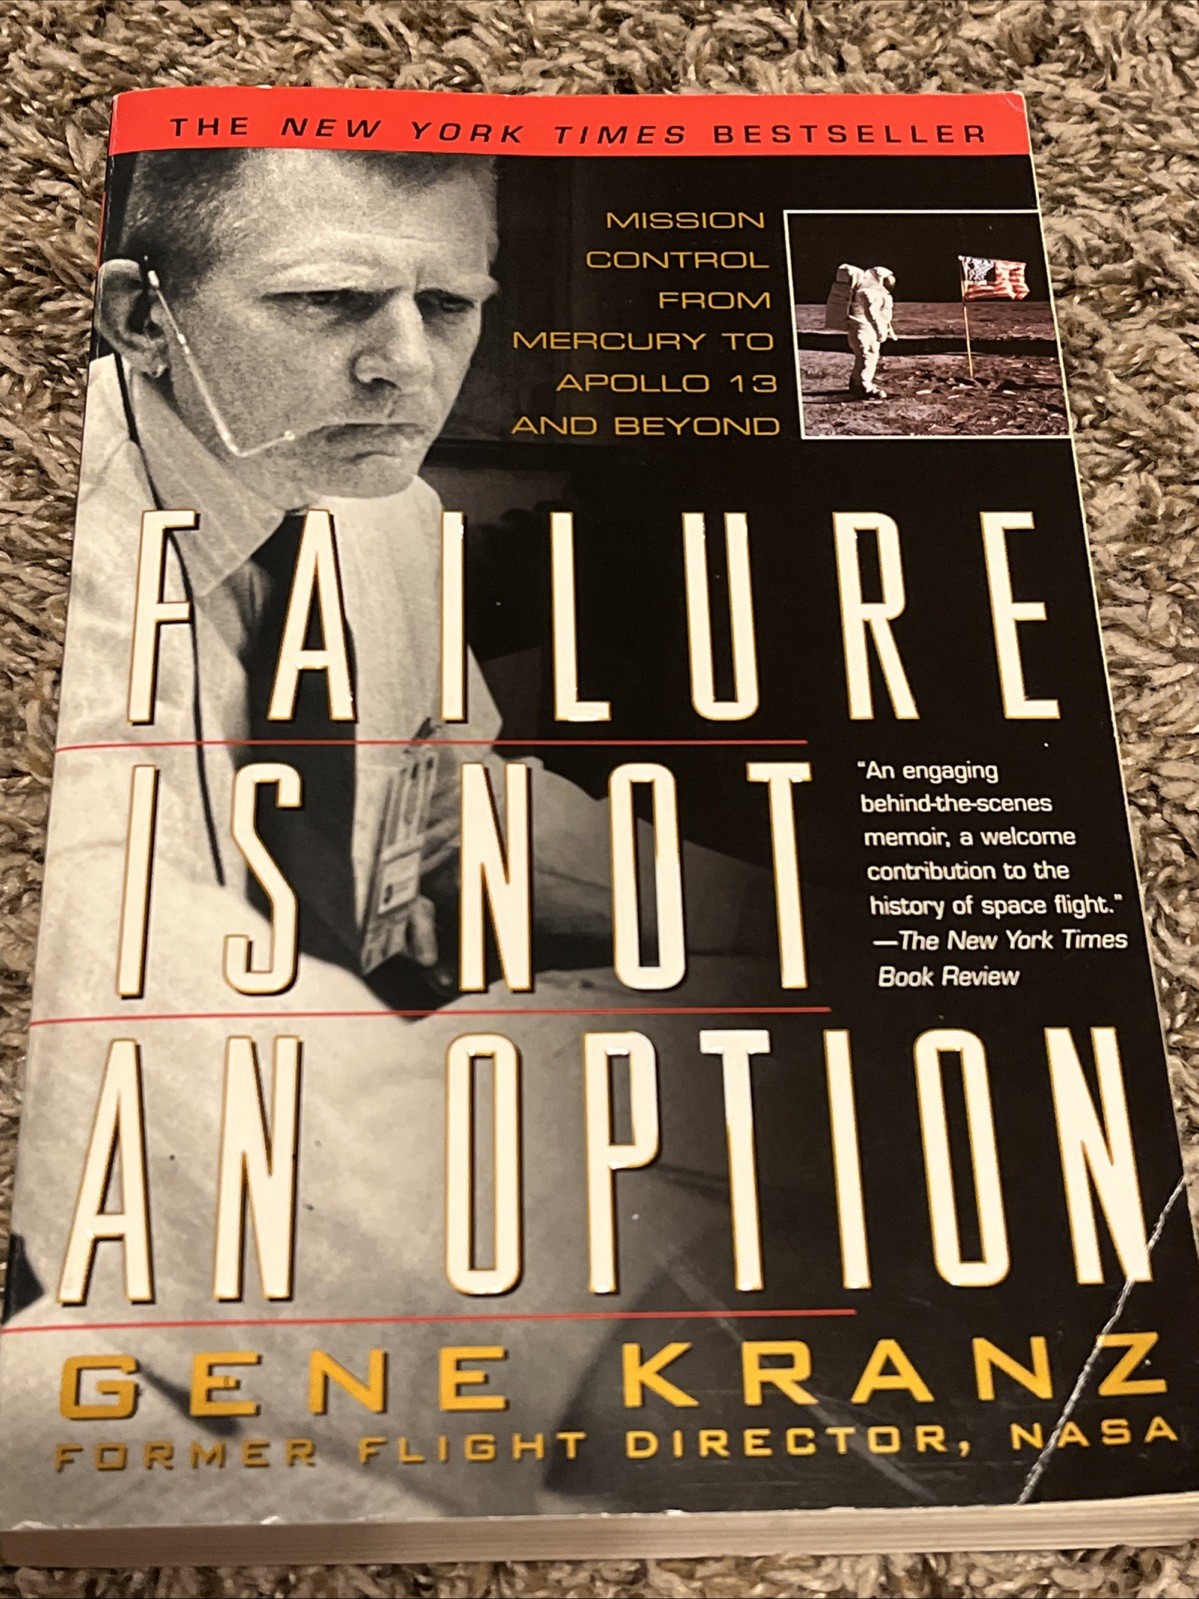
The Apollo 13 mission is one of those moments where everything that could go wrong did go wrong, and somehow it didn't go catastrophically wrong. That distinction matters more than people realize. Gene Kranz was the flight director during that mission, and his famous line "Failure is not an option" has become one of those quotes that gets thrown around everywhere from business seminars to motivational posters. But the actual context and what it meant in practice is more interesting than the soundbite suggests. Kranz wasn't talking about wishful thinking. He was running a control room full of people who had trained for exactly this scenario, and he was reminding them that the problem they were solving was solvable. The Apollo 13 oxygen tank explosion happened on April 13, 1970, at 22 08 minutes EST. Four hours later, Kranz had restructured the entire mission control team and was running it from the dark side of the moon with no direct line of sight to Earth. The quote comes from a NASA internal briefing, not from Kranz himself during the crisis. According to Randy Brinkley, the narrator of the Apollo 13 documentary, Kranz said something like "We've just been handed a failed mission" before delivering the line. The actual transcript records him saying "From this moment on, failure is not an option" to his team of engineers and technicians who had been working 18-hour shifts for three days straight.
What's often missed is that Kranz was being deliberately provocative. He knew the spacecraft was damaged, the crew was running on backup power, and they had no guarantee they'd make it back. By declaring failure wasn't an option, he was forcing everyone in that room to focus on solutions instead of problems. It was a management technique as much as a motivational statement. In practice, this approach required extreme discipline. Kranz had a habit of walking through the control room during crises and asking each controller their diagnosis in 30 seconds or less. If you couldn't articulate the problem clearly, he'd move to the next person and come back later. This seemed harsh in the moment, but it prevented the kind of analysis paralysis that kills more missions than anything else. I remember reading about how Kranz handled the CO2 scrubber problem. The crew needed a square filter in a round hole, and they had materials available in the command module and the lunar module. The ground team spent about three hours building a workaround using only socks, flight manuals, and tape. During that time, Kranz didn't celebrate any small victories or make speeches. He just kept asking "What's the next step?" and moving people to wherever they were needed most.
The Technical Reality Behind the Myth
Apollo 13 mission control operated with a staffing model that would seem excessive by modern standards. Each console had a primary operator, an alternate, and a support team. During the crisis, Kranz kept all three levels running simultaneously, which created redundancy but also communication overhead. He solved this by establishing a single chain of command: ground-to-controller, controller-to-astronaut, nothing else. The trajectory correction burns were particularly tricky. The Service Module engine was damaged and couldn't be used, so the crew had to fire the Lunar Module engine for about 35 seconds to adjust their return trajectory. This required precise timing because the LM was designed for lunar orbit operations, not trans-Earth injection burns. The ground team calculated the burn parameters using only hand-held computers and backup calculations. One counter-intuitive insight about Kranz's leadership style is that he actually encouraged dissent during crises. Controllers could challenge his decisions if they had technical justification, and he expected them to do so. This created a culture where junior engineers felt comfortable speaking up when they saw problems their superiors missed. The downside was that it required extremely competent people and created tension during high-stress moments.
Get the Full Details

Another common misunderstanding is that Kranz's approach worked because he was infallible. In reality, he made mistakes during the Apollo 13 crisis, and he owned them publicly. When he initially miscalculated the burn duration, he corrected it within minutes and moved on. This transparency built trust because everyone knew he wouldn't hide errors or blame others. The real limitation of this philosophy is that it doesn't scale well to organizations without rigorous training standards. Kranz's teams consisted of engineers who had spent years working together and understood each other's thinking. In less experienced groups, the same approach can create chaos because people don't share the same mental models or decision-making frameworks.
How to Apply This Thinking Without the Apollo 13 Budget
If you're trying to implement this kind of crisis management in a normal business environment, the key insight is that "failure is not an option" works only when you have alternatives ready. You can't declare failure off the table if you haven't thought through what happens when your primary plan doesn't work. The practical application involves creating decision trees for common failure modes before you need them. For a software system, this means having rollback procedures, manual overrides, and fallback architectures documented and tested. For a manufacturing process, it means having redundant supply chains, alternative vendors, and contingency production methods identified and ready to activate. In my experience implementing similar frameworks, the biggest bottleneck is getting people to think through failure scenarios without feeling pessimistic. The workaround is to frame it as "what would we do if this particular component failed?" rather than "when will this break?" The distinction matters because it activates problem-solving mode instead of worry mode.
The specific technique I use involves running "failure pre-mortems" before project launches. Instead of assuming success and hoping for the best, you imagine the project has already failed and work backward to identify what went wrong. This usually takes about 20 minutes per major component and catches problems that standard risk assessments miss. One edge case that surprises people is when this approach creates overconfidence. If your team believes failure isn't an option, they might skip validation steps or ignore warning signs because "we're not going to fail anyway." The countermeasure is to maintain separate "failure tracking" metrics that monitor warning indicators independently from the main success metrics.

Common Pitfalls When Implementing This Approach
The most frequent mistake is treating "failure is not an option" as a slogan instead of a discipline. You can post it on the wall all you want, but if your organization punishes people for reporting problems or doesn't invest in backup systems, the philosophy won't save you when things go wrong. Another trap is confusing this approach with denial. When you declare failure impossible, you might start ignoring early warning signs because acknowledging them feels like admitting defeat. The solution is to maintain separate "early warning" channels that operate independently from the main decision-making structure. I encountered a situation where a team used this philosophy to skip adequate testing because "we're not going to fail." They launched a system that crashed within hours because they hadn't validated the assumptions under realistic load conditions. The lesson was that "failure is not an option" applies to the outcome, not the process. You still need rigorous testing and validation.
The specific problem we faced was a database migration that appeared to succeed but had silent data corruption. Because the team believed failure wasn't possible, they didn't run comprehensive integrity checks after the migration. When the corruption was discovered three weeks later, it took about 40 hours to recover from backups and verify data consistency.
Alternative Approaches When This Philosophy Doesn't Fit
For organizations where the stakes are lower or the consequences of failure are acceptable, a different approach might work better. Instead of declaring failure impossible, you can focus on "failure resilience" – building systems that can absorb problems without catastrophic consequences. This shift from "no failure" to "graceful degradation" works well for consumer applications where occasional downtime is acceptable but data loss isn't. You design systems to fail safely, with automatic backups, manual overrides, and clear communication protocols when problems occur. The trade-off is that this approach requires more investment in redundancy and testing upfront. You spend time and money building backup systems that might never be used, but when failures do occur, the impact is minimized and recovery is faster.
For highly regulated industries like healthcare or aviation, the "failure is not an option" philosophy still makes sense because the consequences of failure are unacceptable. In these domains, you invest heavily in prevention, validation, and contingency planning because there's no margin for error. The key insight is that different contexts require different approaches. If you're building a mobile app that might occasionally crash, you don't need Apollo 13-level rigor. If you're designing a cardiac pacemaker, you do. The mistake is applying one philosophy universally without considering the actual risk profile.
Practical Steps for Implementation
If you want to start implementing this thinking in your organization, begin with a failure mode analysis of your most critical processes. Identify the top five things that could go wrong and document the consequences of each scenario. This usually takes about two weeks for a mid-sized organization and reveals blind spots you didn't know you had. Next, establish clear escalation procedures for each failure mode. Who makes the decision to activate the contingency plan? What information do they need before deciding? What's the timeline for response? Document these procedures and train people on them before you need them. The third step is creating a post-mortem culture where failures are analyzed openly without blame. This doesn't mean accepting poor performance, but it does mean understanding why mistakes happened so they don't recur. Teams that avoid post-mortems tend to make the same mistakes repeatedly because they never learn from them.
In practice, I've found that the most effective implementation involves weekly "failure briefings" where teams report near-misses and potential problems before they escalate. These briefings take about 15 minutes per person and catch issues that would otherwise grow into crises. The key is maintaining psychological safety so people feel comfortable reporting problems without fear of punishment.
When This Approach Actually Fails
The "failure is not an option" philosophy breaks down when you're dealing with truly novel situations where no precedent exists. If you've never encountered a particular type of failure before, you can't prepare for it in advance. In these cases, you need adaptive problem-solving skills instead of scripted responses. Another limitation is that this approach can create groupthink if everyone is so focused on preventing failure that they don't challenge flawed assumptions. The Apollo 13 team avoided this by maintaining independent verification channels where controllers could question decisions without appearing disloyal. I encountered a situation where a team's commitment to "no failure" led them to ignore warning signs because acknowledging problems felt like admitting vulnerability. They pushed forward with a flawed design because "failure isn't an option," and when it finally broke, the recovery took three times longer than it should have.
The specific workaround we implemented was creating separate "failure hypothesis" roles where someone was explicitly tasked with finding problems and proposing alternatives. This person reported directly to leadership and wasn't involved in the main decision-making process, which gave them the independence to speak truth to power without political consequences.
Key Takeaways for Practical Application
The core insight from Gene Kranz's approach is that "failure is not an option" works only when you have the discipline to prepare for every contingency. It's not a mantra you repeat; it's a mindset you demonstrate through rigorous planning, testing, and validation. The practical value is that this approach forces you to think through problems before they occur, which reduces reaction time when crises happen and increases confidence among team members who know there's a plan. In my experience, the most effective implementation combines this philosophy with realistic risk assessment. You declare failure impossible for outcomes you care about, but you remain honest about the probability of different failure modes and invest resources accordingly.
The specific technique that works best is maintaining separate "success metrics" and "failure indicators" that are tracked independently. Success metrics measure whether you're achieving your goals, while failure indicators monitor warning signs that something might go wrong. This dual tracking prevents the cognitive bias where people ignore problems because they're focused on success. For organizations looking to adopt this approach, start small with one critical process and expand gradually. The transition from "hope for the best" to "prepare for the worst" takes about six months for most teams, but the payoff in crisis readiness is immediate and measurable.
