Why your ChIP-seq data doesn't match the transcriptome
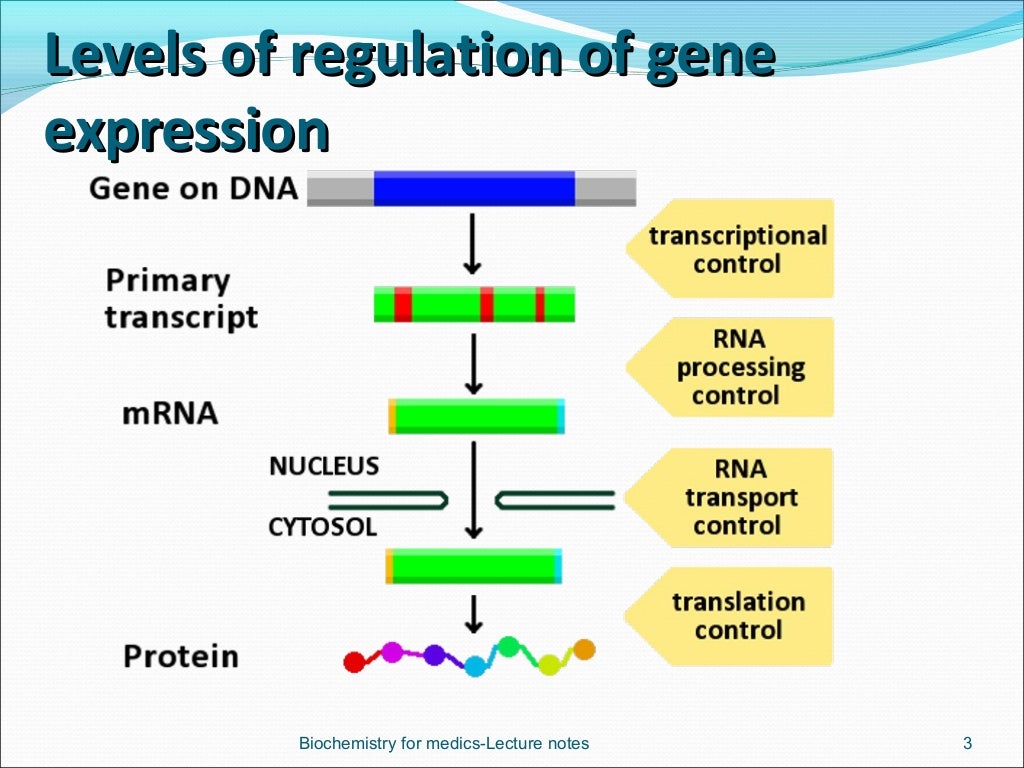
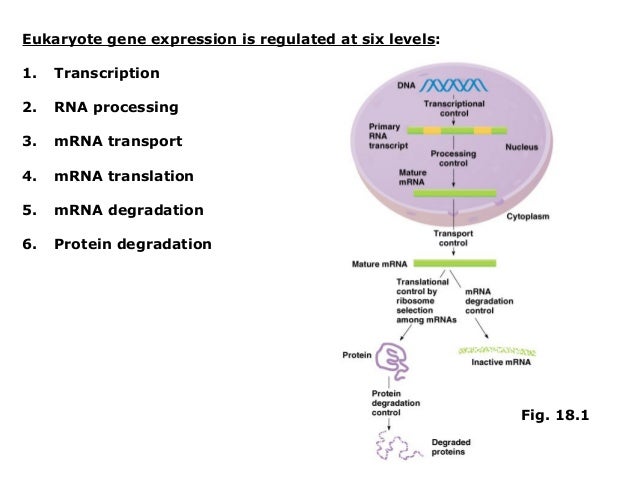
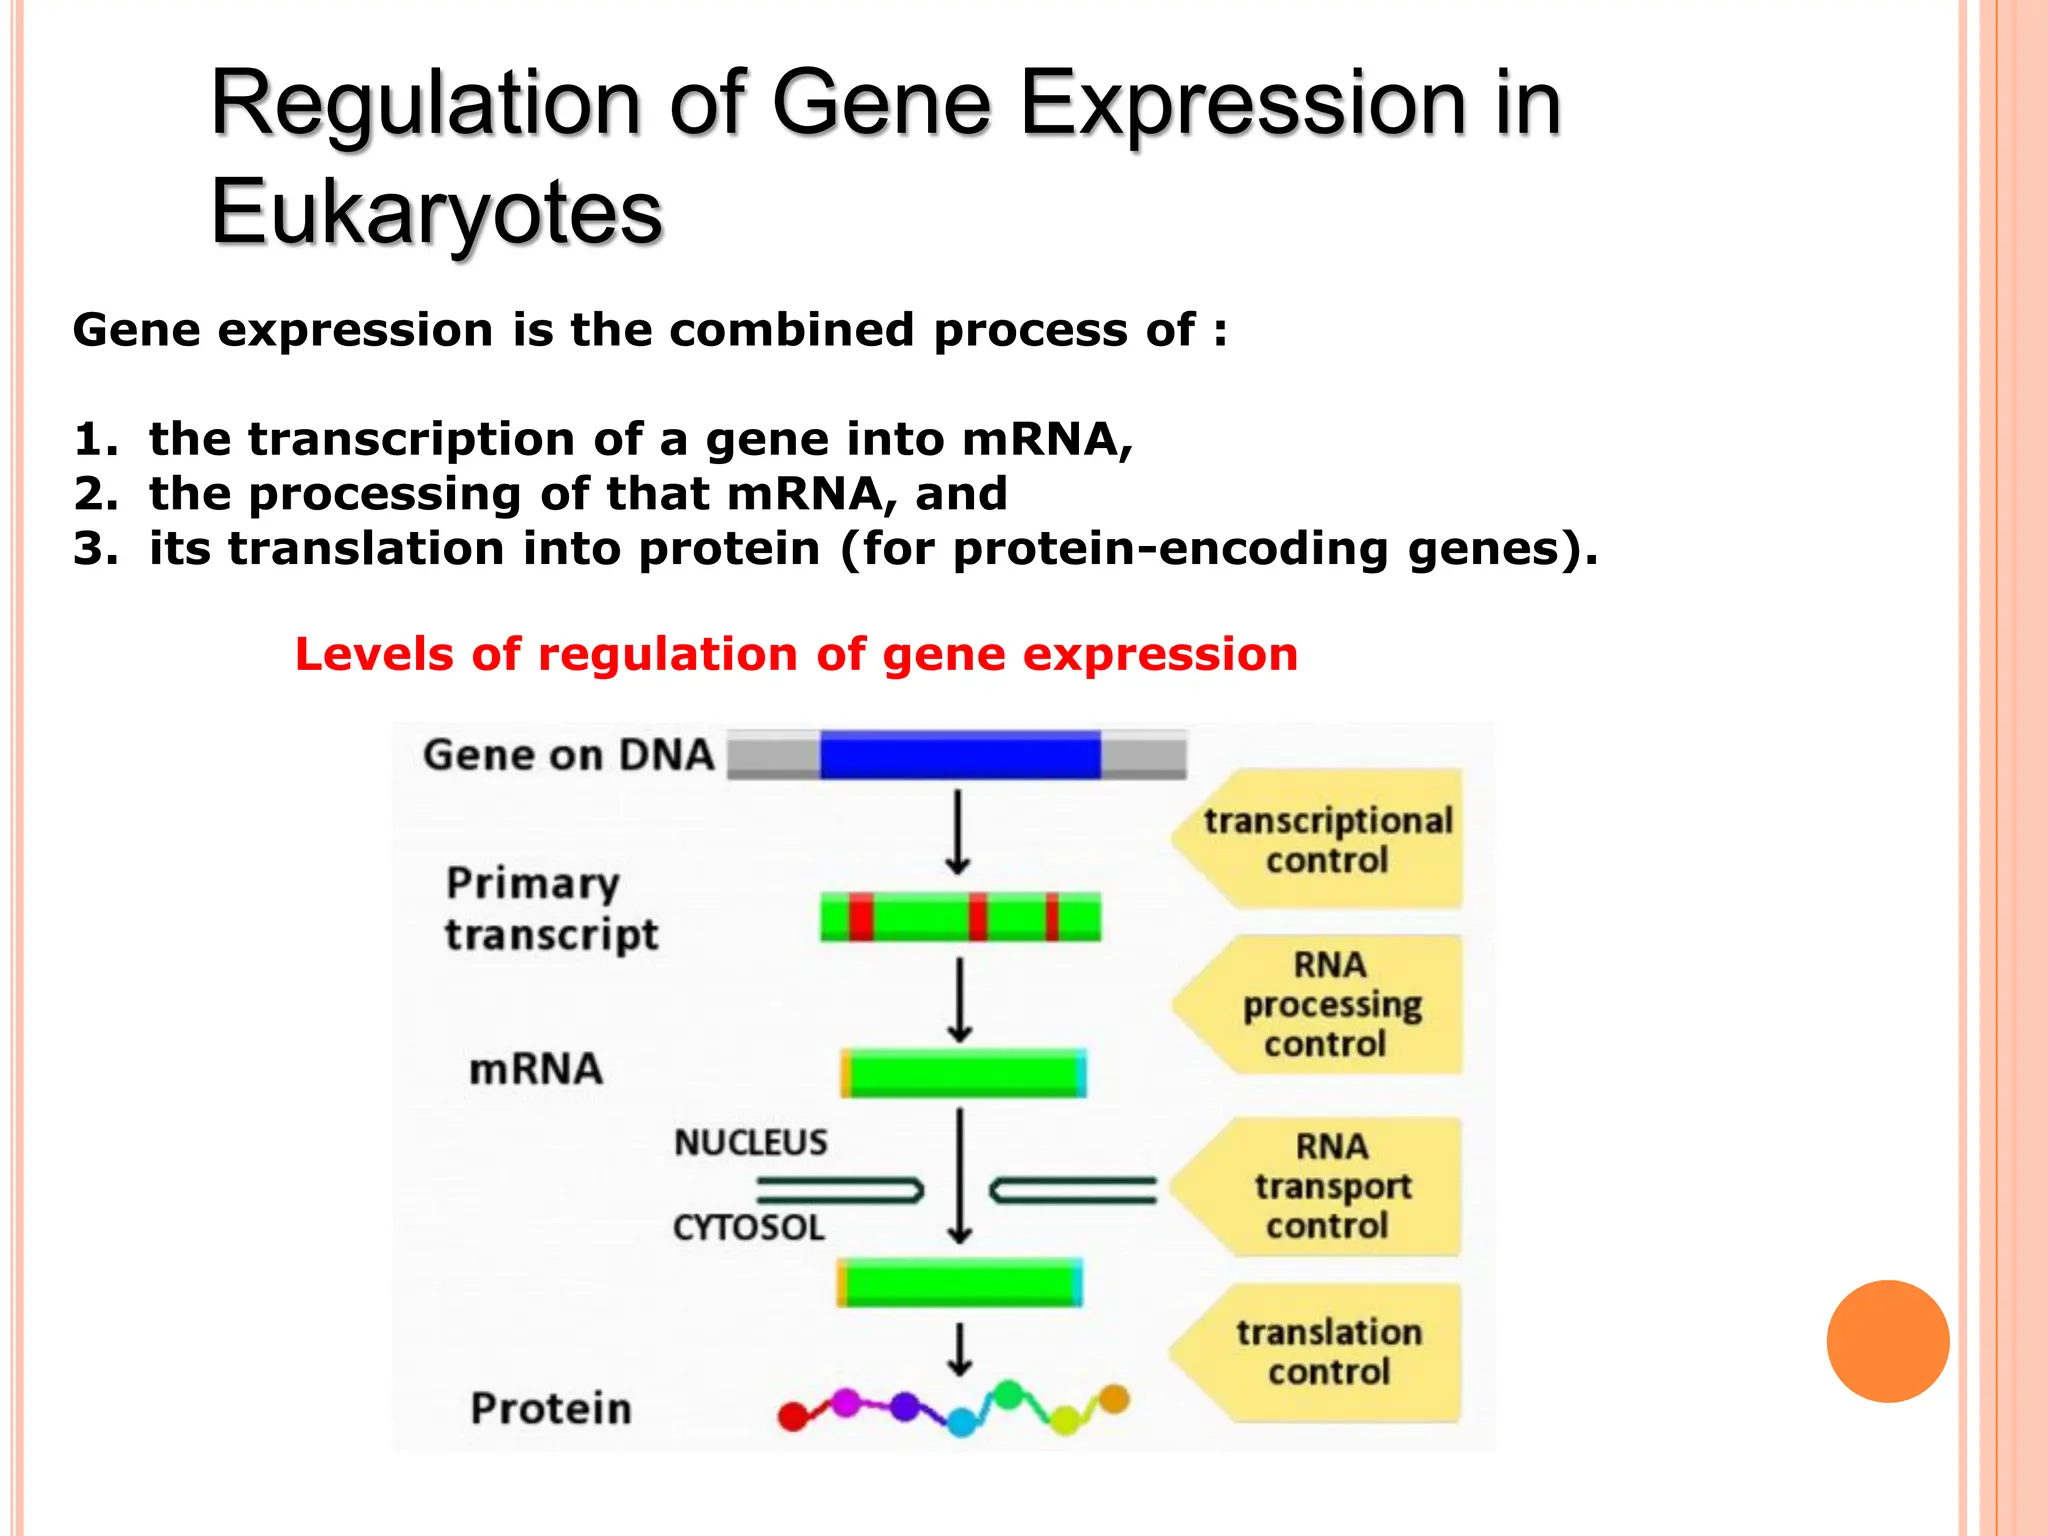
I spent three weeks trying to reconcile a transcription factor binding dataset with RNA-seq results from the same cell line, and the mismatch wasn't technical noise. It was the reality of eukaryotic gene regulation not being a simple on-off switch. When you pull down a factor like REST or NF-kB and see peaks at a promoter, the default assumption is that gene expression changes proportionally. That assumption breaks down almost immediately once you account for chromatin state, enhancer-promoter looping fidelity, and the fact that most binding events are neutral rather than instructive. Eukaryotic Gene Regulation In Eukaryotes involves multiple layers that don't always cooperate. Transcriptional control is only the first bottleneck. You have histone modifications that can reinforce each other or actively oppose one another. A H3K4me3 mark at a promoter signals active transcription potential, but without H3K36me3 during elongation, RNA polymerase II stalls and the transcript gets degraded by the nuclear exosome. I learned this the hard way when I was working with a line where Pol II was clearly recruited but protein output was undetectable by Western blot.
The practical workflow most people get wrong
Most protocols for studying these mechanisms start with a quick ChIP experiment and call it a day. That's insufficient for any system where context matters. A better approach builds from chromatin accessibility data into motif analysis, then validates with functional assays. ATAC-seq or DNase-seq gives you the lay of the land. Peaks in accessible regions tell you where the regulatory landscape is permissive. From there, motif enrichment analysis using tools like HOMER or MEME identifies which transcription factors are likely active in that chromatin state. I found that combining publicly available ENCODE datasets with your own conditions usually saves about two weeks of preliminary experimentation. If you're working with a rare cell type where generating fresh ATAC-seq data takes four days of optimization, checking whether matched epigenomic profiles already exist in the ENCODE portal or Roadmap Epigenomics can eliminate that entire step. Don't overlook the fact that ENCODE data is mostly from canonical cell lines. Primary cells and disease states frequently diverge from those reference maps.
Enhancer logic is the part nobody explains properly
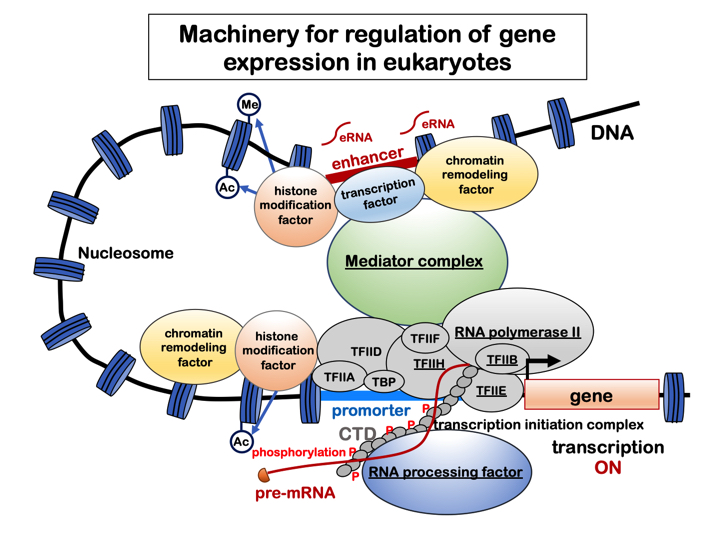
The conventional textbook diagram shows enhancers as simple wires connecting to promoters. In practice, enhancers operate through a combination of pioneer factor binding, mediator complex recruitment, and phase-separated condensate formation. Pioneer factors like FOXA1 or PU.1 can bind closed chromatin and initiate local opening. They don't work alone though. They recruit chromatin remodelers such as SWI/SNF complexes, and those complexes move nucleosomes in a direction-dependent manner that affects downstream binding sites. Here's the counter-intuitive part that most people miss: strong enhancers can actually compete with weaker ones for the same promoter. This is called enhancer competition or enhancer buffering. When you knockout a super-enhancer in a CRISPR screen, the gene expression often changes less than expected because secondary enhancers compensate. The compensation can take hours or even days to kick in depending on the locus. If you're measuring expression at a single time point after knockout, you might conclude the enhancer is dispensable when it's not. I encountered this exact problem with the BCL11A locus. Deleting what looked like the major enhancer showed minimal effect on beta-globin re-expression at 48 hours. It wasn't until day four that the compensatory enhancer activity became measurable through RT-qPCR. The workaround was switching from a single time point readout to a kinetic series spanning seven days with live-cell imaging of the reporter construct. That added about twelve hours of incubator monitoring but saved me from writing off a genuinely important regulatory element.
Get the Full Details
Epigenetic memory and its experimental consequences
DNA methylation and histone modifications create heritable states that persist through cell division without changes to the underlying sequence. This is why differentiated cells maintain their identity. It's also why your differentiation protocol might fail silently if the starting material has residual epigenetic marks from a previous lineage. I've seen stem cell projects stall because the donor cells carried methylation patterns from a tissue type that resisted complete reprogramming. Bisulfite sequencing remains the standard for mapping DNA methylation at single-base resolution. But there are important caveats. Not all cytosines behave the same across contexts. CpG methylation is the well-characterized pathway, but non-CpG methylation at CHG and CHH contexts becomes significant in neural tissue and embryonic stem cells. If you're only looking at CpG sites and your system has substantial non-CpG methylation, your picture is incomplete. Tools like Bismark handle the alignment well, but you need to explicitly request non-CpG reporting in your analysis parameters. Histone modification analysis through ChIP-seq has its own set of failures. Antibody specificity is the primary issue. Many commercial antibodies against marks like H3K27ac or H3K4me1 cross-react with nearby marks at rates that vary between lots. I recommend validating every antibody with a knockout control cell line when possible. A H3K27ac antibody that also pulls down H3K18ac will inflate your enhancer calls by misassigning promoter-proximal signal to distal regions. This can shift your entire interpretation of which enhancers are active.
Non-coding RNAs complicate the standard model
Mature messenger RNA gets all the attention in most courses, but regulatory non-coding RNAs are deeply embedded in eukaryotic gene control. XIST RNA coats the inactive X chromosome and recruits PRC2 for H3K27 trimethylation. LincRNAs like NEAT1 organize nuclear paraspeckles that sequester specific transcription factors. Enhancer RNAs, or eRNAs, are transcribed from active enhancers and while they're short-lived and unstable, their presence correlates strongly with enhancer activity. The challenge with eRNAs is detection. They're often polyadenylation-independent and rapidly degraded by exosomes. Standard RNA-seq library prep protocols that select for poly-A tails miss most of them entirely. If you want to capture eRNA signal, you need to use a ribosomal depletion protocol rather than poly-A selection, and you should treat samples with 5' to 3' exonuclease to enrich for capped transcripts while preserving the uncapped eRNAs. This adds roughly twenty minutes to your workflow but increases your enhancer detection sensitivity by an order of magnitude. I ran into a situation where a locus appeared silent by standard RNA-seq but showed massive enhancer activity through GRO-seq, which captures nascent transcription directly. The gene was producing eRNAs and having Pol II paused at the promoter, but productive elongation was blocked by a PRC2-mediated repressive domain. Only after treating the cells with a CDK9 inhibitor did the pause release and the full transcript appear. This taught me to never trust a single readout method when dissecting regulatory mechanisms.
Practical considerations for experimental design
If you're planning a study on Gene Regulation In Eukaryotes, the sample size question is more complex than in prokaryotic systems. Eukaryotic cells show much higher biological variability in regulatory states due to stochastic bursting, cell cycle effects, and microenvironmental differences. A power analysis assuming Poisson-distributed counts will underestimate what you need. I typically recommend minimum replicate counts of six for ChIP-seq and eight for ATAC-seq in heterogeneous populations. Single-cell methods reduce some of this problem but introduce their own dropout issues that require different statistical handling. Control experiments are non-negotiable. Input DNA controls for ChIP, IgG controls catch antibody artifacts, and spike-in controls like Drosophila chromatin normalize for differences in cell number and immunoprecipitation efficiency. Without spike-ins, you cannot distinguish true global chromatin changes from technical variation between samples. I've lost months of work because I skipped spike-in normalization and attributed a global reduction in H3K27ac to biological regulation when it was actually a pipetting error during the crosslinking step. Data analysis pipelines for eukaryotic regulation studies need to account for multi-layer integration. Tools like ChromHMM or Segway can jointly model multiple histone marks to define chromatin states across the genome. These hidden Markov model approaches reduce noise by requiring consistency across mark combinations rather than treating each modification independently. The tradeoff is computational cost. Running ChromHMM on a whole genome with five or six histone marks across multiple conditions can take twelve to forty-eight hours on a standard workstation depending on coverage depth.

Another practical note about temporal resolution. Gene regulatory networks operate on timescales ranging from seconds for transcription factor binding to hours for chromatin remodeling to days for stable epigenetic inheritance. Most experiments sample at a single time point because that's what fits into a normal lab schedule. But regulatory dynamics are continuous. If you're studying a drug response or a differentiation event, sparse time points will miss transient regulatory states that are functionally important. A practical compromise is to use a small number of early time points during the first hour after stimulus, then space them out over the next twenty-four hours. This captures the rapid initial response and the longer-term adaptations without requiring hourly sampling. Gene regulation in eukaryotes is not a linear cascade. It's a network with feedback loops, redundancy, buffering, and context-dependent behavior. The tools exist to map parts of it with reasonable resolution, but every method has blind spots. Acknowledging those blind spots upfront prevents a lot of wasted effort downstream. You'll get better results spending time understanding what your assay can't see than you will optimizing the parts it can.