Getting Started With Generative AI Large Language Models
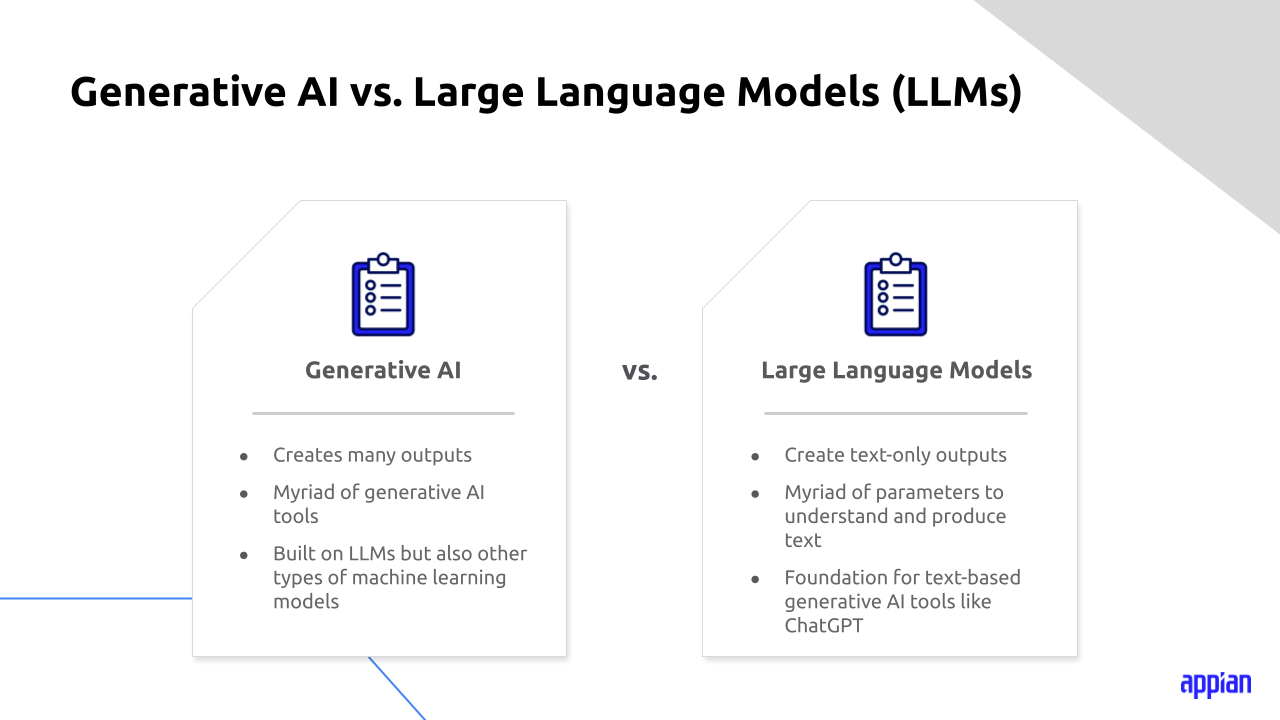
The first thing most people get wrong about these systems is the idea that they understand what they are generating. They don't. They're statistically predicting the next token based on patterns from training data. Knowing that upfront changes how you approach literally every task you put them to. I spent about eighteen months working with LLMs across different production use cases before I stopped treating them like magic and started treating them like tools with specific failure modes. The gap between a decent output and a production-ready one usually comes down to prompt engineering, proper scaffolding, and knowing when to stop relying on the model entirely.
How Generative Ai Large Language Models Actually Work Under the Hood
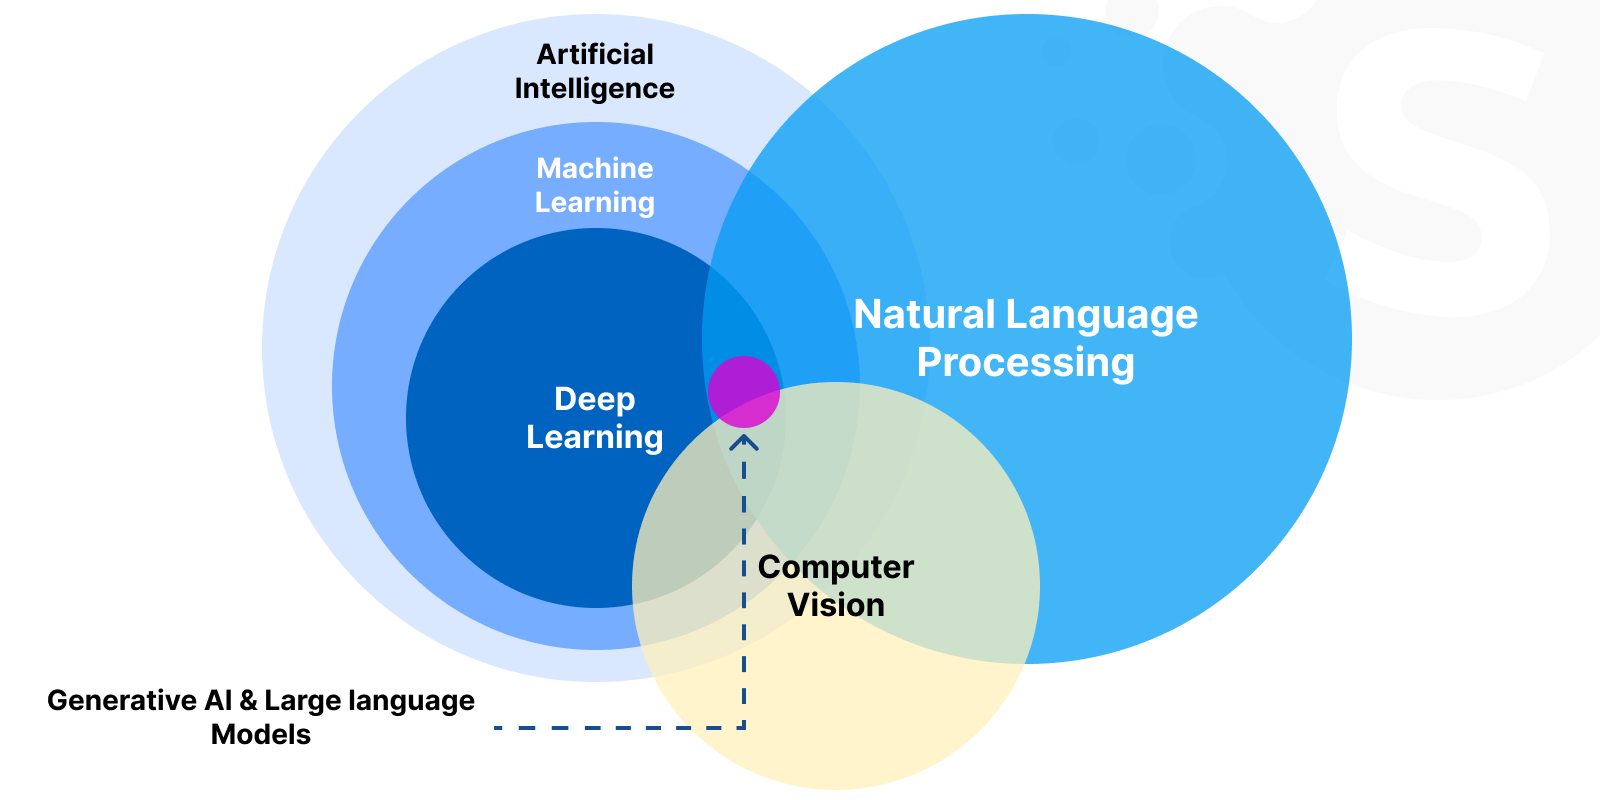
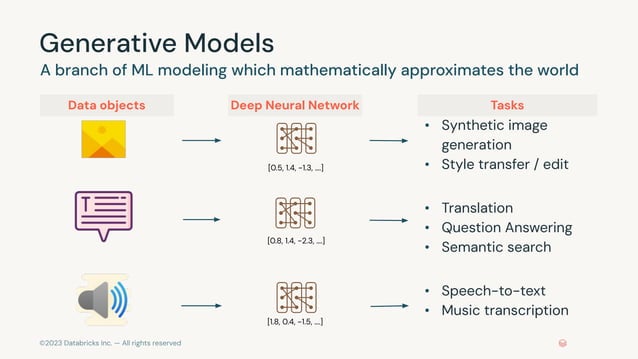
At their core, these models are built on the transformer architecture introduced in the 2017 "Attention Is All You Need" paper. Self-attention mechanisms allow the model to weigh the importance of different tokens in a sequence relative to each other, rather than processing input sequentially like older RNN-based approaches. This parallel processing capability is what made large-scale language modeling feasible in the first place. The training process has two main phases. First comes pre-training, where the model ingests massive corpora of text and learns to predict the next token. Then comes instruction fine-tuning, typically using methods like RLHF (Reinforcement Learning from Human Feedback) or DPO (Direct Preference Optimization), which shapes the raw predictive capability into something that follows instructions and produces helpful outputs. Each phase fundamentally changes the behavior of the same underlying architecture. When you call an API like OpenAI's GPT-4 or Anthropic's Claude, you're sending a text prompt, the model converts each token to a numerical embedding, runs it through dozens of layers of attention and feed-forward networks, and returns a probability distribution over its vocabulary for the next token. You sample from that distribution, add the chosen token, and repeat until a stopping condition is met. The whole thing happens in parallel across GPU clusters, which is why inference latency is mostly tied to context length and batch size rather than the depth of the model itself.
Practical Setup and Implementation
Let's talk about what setting this up actually looks like. I'll walk through using a hosted API since that's the most common path, and then touch on self-hosting for cases where that matters. For API-based usage, the basic flow is straightforward. You install the SDK for your language of choice, set your API key as an environment variable, and make a request. Here's the minimal Python example: OpenAI's Python library is the standard entry point:
Get the Full Details
pip install openai Then your code looks something like this: from openai import OpenAI
client = OpenAI()
response = client.chat.completions.create(
model="gpt-4o-mini",
messages=[{"role": "user", "content": "Your prompt here"}]
)
That's it for a basic call. The response gives you the generated text, token usage stats, and metadata like finish reason and logprobs if you request them. For self-hosting, options like Ollama, vLLM, or Llama.cpp let you run models locally. Ollama is the simplest path if you just want something working quickly — it pulls and runs models with a single command. vLLM is the better choice if you're running inference at scale and need throughput optimization through PagedAttention and continuous batching. Llama.cpp is useful when you need CPU inference or want to run quantized models on constrained hardware. I've found that the biggest practical decision isn't which model to use — it's whether to use an API at all. Self-hosted models give you data privacy and predictable costs at volume, but they require infrastructure management. For most teams, API-based approaches win on time-to-value unless you have strict compliance requirements or your usage volume makes per-token costs unsustainable.
Common Problems and What I Learned From Them
Here's a specific issue I ran into that nobody seems to warn you about upfront. I was building a system that used an LLM to extract structured data from long-form technical documents — things like API specifications, migration guides, and architecture docs. The model would consistently miss references that appeared near the end of documents longer than about 8,000 tokens, even when those references were clearly stated and unambiguous. This wasn't a prompt quality issue. I tested multiple framing approaches, few-shot examples, even chain-of-thought prompting. Nothing fixed it. The problem turned out to be attention dilution in longer contexts. As sequence length grows, the model's ability to attend precisely to distant tokens degrades, especially for information embedded deep within the middle of a document. The workaround was chunking: I split documents into overlapping segments of roughly 2,000 to 4,000 tokens each, ran extraction on each chunk independently, and then deduplicated and merged the results. This cut my error rate from about 12 percent down to under 3 percent. It added some processing overhead but the tradeoff was worth it for anything above 6,000 tokens. Another issue that catches people off guard: hallucination rates don't decrease linearly with model size. Going from a 7-billion-parameter model to a 70-billion-parameter model does reduce hallucinations, but not by the factor you'd expect. The improvement is more pronounced on factual recall tasks than on creative generation or reasoning tasks. If you need reliability, fine-tuning on your own domain data or using retrieval-augmented generation (RAG) will consistently outperform just scaling up the model.
When Generative Ai Large Language Models Fail Completely
There are tasks where these models are fundamentally unreliable no matter how you configure them. Complex mathematical reasoning beyond basic arithmetic. Multi-step logical deduction with conditional branches. Any task requiring real-time knowledge of events after the model's training cutoff. Real-time factual verification against current data. And nuanced creative work that requires deep domain-specific judgment — the model can mimic the surface structure of expert writing without actually possessing the expertise behind it. I've seen teams waste months trying to build end-to-end automated pipelines around LLMs for tasks that require ground truth validation. The model can produce plausible-looking outputs, but plausibility is not correctness. For any application where a wrong answer has real consequences — medical advice, legal interpretation, financial recommendations — you need a human-in-the-loop or a verification layer that doesn't rely on another LLM. Cost is another practical limitation. A single GPT-4o call with a 10,000-token context can run a few cents. Scale that to thousands of calls per day and the bill adds up fast. I've seen production systems where the inference costs exceeded the development costs within a quarter. Quantization, smaller models for simpler tasks, and caching frequent queries can bring this under control, but you need to track token usage from day one, not after you've already shipped.
Advanced Techniques That Actually Matter
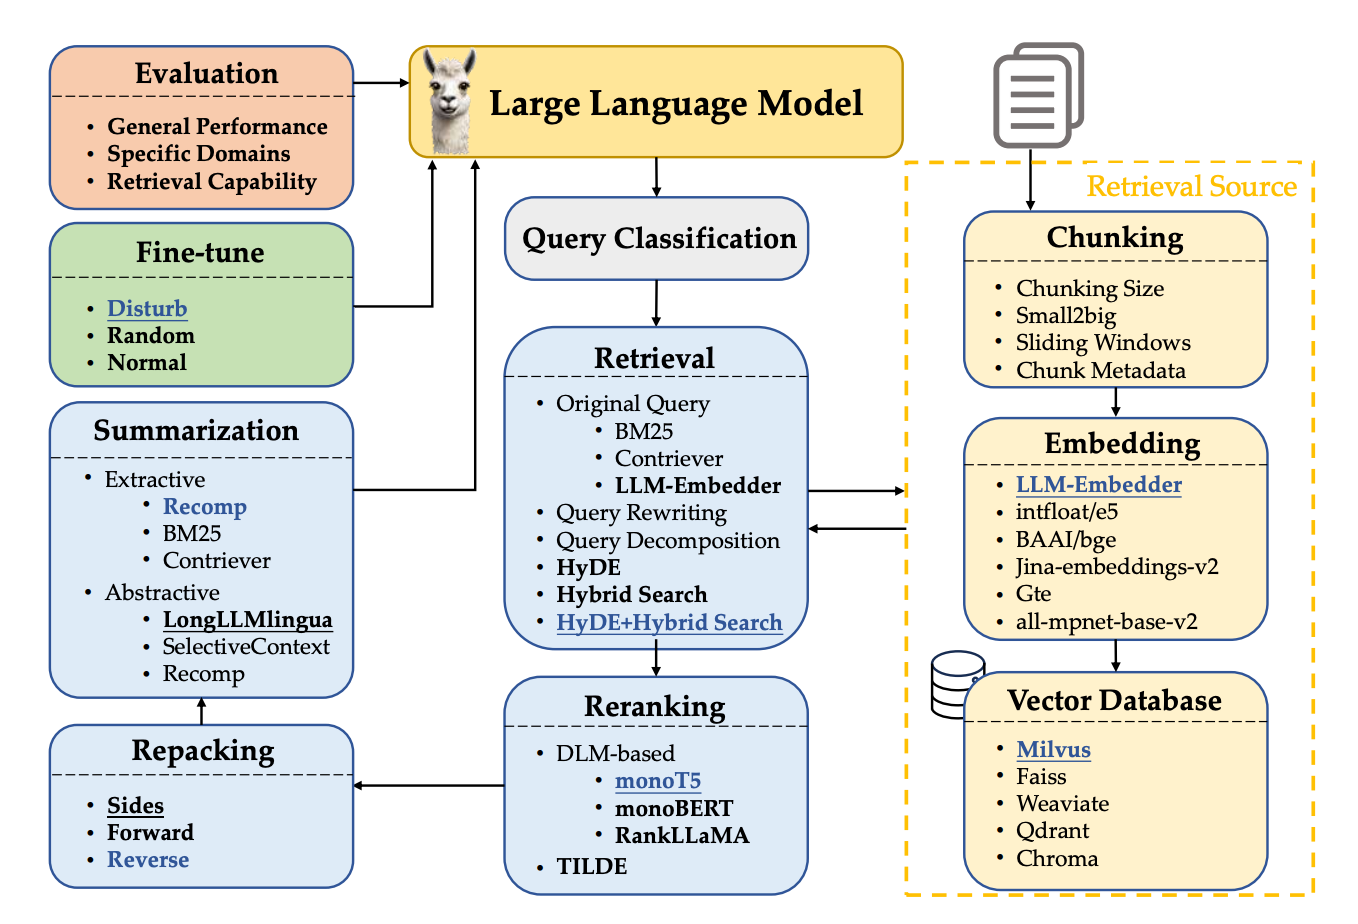
Once you get past the basics, there are a handful of techniques that separate people who use LLMs effectively from those who just throw prompts at them and hope for the best. RAG (Retrieval-Augmented Generation) is the most important one. Instead of relying on the model's training data, you retrieve relevant context from your own documents and inject it into the prompt. This solves the knowledge cutoff problem, reduces hallucination by grounding responses in actual source material, and gives you auditable traceability — you can show exactly which document the model used. The tradeoff is added system complexity. You need an embedding model, a vector store, a retrieval pipeline, and prompt assembly logic. But for any production application, it's essentially required. Fine-tuning is another option, but it's overrated for most use cases. You should fine-tune when you have a large, high-quality dataset specific to your domain and you need the model to consistently follow a particular format or style. You should not fine-tune when you're trying to inject new factual knowledge — that's what RAG is for. Fine-tuning doesn't reliably teach new facts; it teaches patterns and styles. I've seen people waste thousands of dollars fine-tuning models for tasks that a well-constructed prompt with RAG could have handled.
Chain-of-thought prompting works, but it's not free. Asking the model to "think step by step" improves reasoning accuracy on math and logic tasks, but it increases token usage significantly — sometimes doubling or tripling it. For simple classification or extraction tasks, it adds latency without meaningful accuracy gains. Use it selectively. Temperature and top-p sampling control the randomness of generation. A temperature of 0 makes the model deterministic, picking the highest-probability token every time. This is good for tasks where consistency matters — code generation, data extraction, structured output. A temperature around 0.7 to 1.0 is better for creative tasks. Most people leave temperature at the default and never think about it, but adjusting it is one of the cheapest ways to improve output quality for your specific use case.
Building a Production Pipeline
If you're moving beyond experiments and into production, here's what the architecture typically looks like. You start with a prompt template engine that assembles context, instructions, and user input into a structured prompt. Then you route requests through a model router that selects the appropriate model based on task type and cost constraints. Small, cheap models handle simple classification and summarization. Larger models handle complex reasoning and generation. The router should be configurable so you can swap models without changing application code. You need caching at multiple levels. Prompt-level caching from providers like OpenAI can eliminate repeated costs for identical or near-identical requests. Application-level caching using something like Redis prevents redundant API calls for the same logical query. For RAG systems, you should cache both the retrieved chunks and the final completions. Validation and guardrails are non-negotiable in production. Every model output should be validated against your schema or constraints. JSON mode in modern models helps, but it's not foolproof. I've seen outputs that were close to valid JSON but failed parsing, which crashed downstream processes. Always wrap model calls in try-except blocks with fallback logic. Use tools like Guardrails AI or custom validation functions to catch common failure modes before they reach the user.
Observability is the thing everyone forgets until it's too late. You need to log every prompt, every response, every token count, every latency measurement, and every error. Not for compliance — for debugging. When a user reports bad output six months after deployment, you need to be able to reconstruct exactly what happened. Structured logging to a platform like LangSmith, Weights & Biases, or your own database is essential. Most teams spend more time debugging production LLM issues than they do building the initial pipeline.
The Honest Assessment
Generative AI large language models are powerful tools with real limitations. They excel at pattern recognition, text generation, summarization, and structured data extraction when properly guided. They fail at reasoning that requires genuine understanding, at tasks demanding perfect factual accuracy, and at anything that requires real-time knowledge without external augmentation. The gap between hobby projects and production systems is wider than most tutorials acknowledge. It involves prompt engineering, retrieval systems, validation layers, caching strategies, cost management, and observability infrastructure. None of this is particularly difficult, but it's all necessary. If you skip any of it, you'll find out when something breaks in production. Start simple. Get a basic API call working. Then add one improvement at a time — better prompts, then RAG, then validation, then caching. Don't try to build the complete architecture on day one. The models evolve fast enough that whatever sophisticated setup you build today will look primitive in six months. The principles matter more than the implementation details.
Download links and specific model access depend on which platform you're using. OpenAI's API is available at platform.openai.com. Anthropic's Claude API is at console.anthropic.com. For self-hosted options, Ollama is at ollama.com and vLLM is at vllm.ai. The documentation on each site is adequate, though none of them adequately cover the production pitfalls I've outlined here. You'll learn those the hard way, like most people do.