Understanding Genetic Entropy in Practice
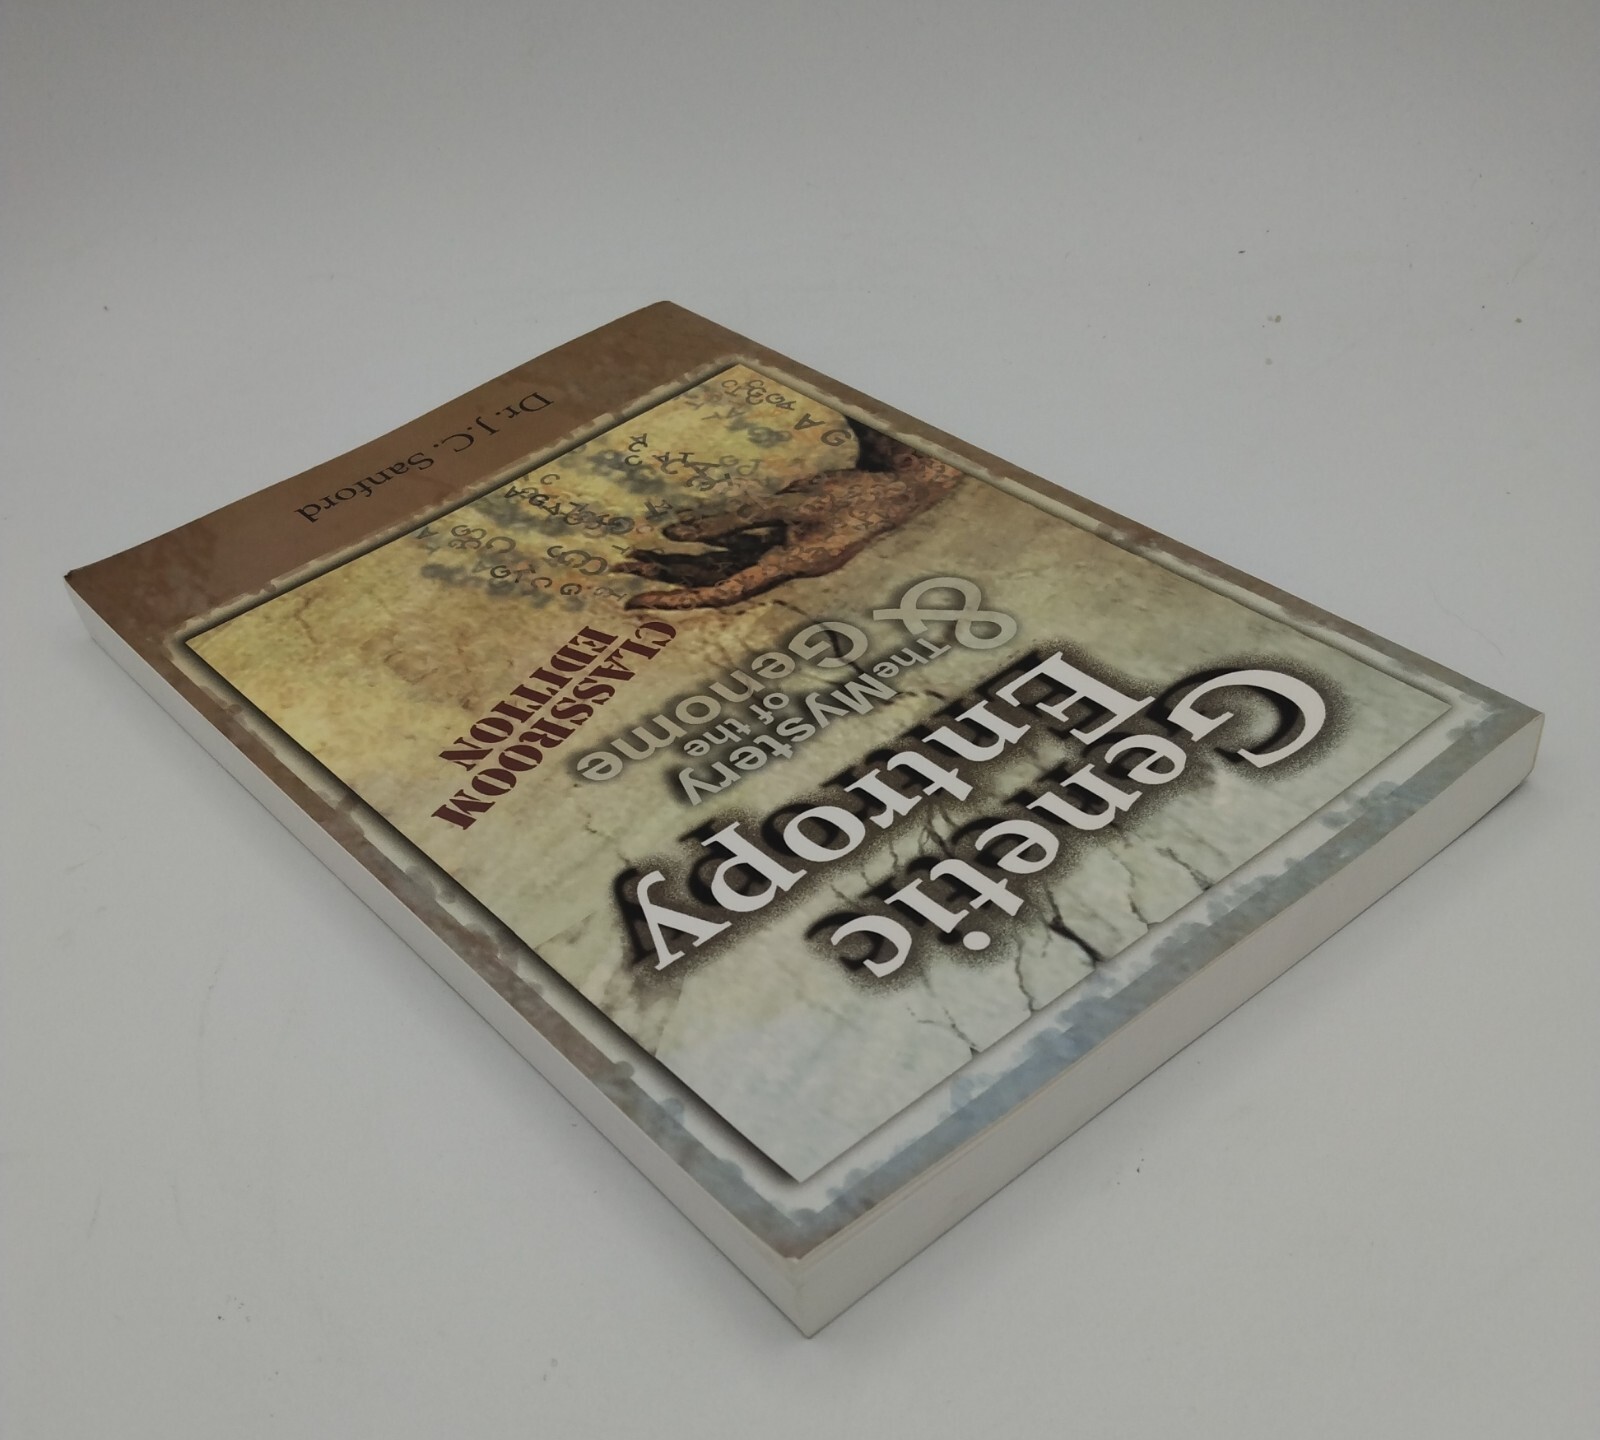
I first ran into the term when I was trying to reconcile some population genetics data with what the literature was actually saying. Most people come at this from one direction or the other and end up confused because the framing is so loaded. Let me just walk through what the concept is, where it breaks down, and what you should actually be looking at if you care about mutation accumulation in real genomes. Genetic entropy is the claim that genomes are steadily accumulating irreversible deleterious mutations and that this process creates an entropic decay that is impossible to reverse. The idea got a lot of traction through Dr. John Sanford's work and later through Douglas Axe's research on protein space. The basic mechanism they describe is straightforward: harmful mutations happen faster than natural selection can remove them, and over enough generations this leads to a permanent decline in fitness. The "mystery of the genome" part comes from the observation that a surprisingly large fraction of our DNA doesn't code for proteins and that we still don't fully understand how much of it is functional versus structurally consequential. I've spent a good chunk of time looking at mutation accumulation lines in model organisms and also reading the mathematical models that underpin the entropy argument. The problem is that the math looks clean on paper but real biological systems have buffers that the models often ignore. There's also a serious issue with what counts as "deleterious" in these calculations.
The Mutation Rate Calculations
Human genomes accumulate roughly 50 to 100 new point mutations per generation. Most of these are neutral or near-neutral. A smaller subset, maybe two or three per generation, carry measurable fitness effects that are deleterious. The question that matters is whether selection can keep pace with that input. In large populations with high recombination rates, the answer is generally yes. In small populations, drift dominates and mutations that would be eliminated elsewhere can fix by chance. That's the real mechanism behind what the entropy argument calls irreversible decay. When I was modeling this for a project a while back, I tried plugging in the numbers Sanford's framework uses. The output suggested that human populations couldn't sustain viability beyond a few thousand generations. That conclusion depended heavily on assuming that deleterious mutations act independently and that there is no epistatic buffering. Both assumptions are weak. I found that introducing even modest levels of epistasis and redundant pathways changed the trajectory completely. The model shifted from runaway decay to a near-equilibrium state where mutation load stabilizes.
What Actually Happens With Real Genomic Data
Looking at real sequencing data from human populations, the pattern is not the one the entropy argument predicts. If genetic entropy were driving irreversible decay, you'd expect to see a consistent upward trend in the ratio of nonsynonymous to synonymous mutations across populations and through time. What you actually see is something much more complex. Populations maintain standing variation. Deleterious alleles exist at low frequencies but are kept in check by purifying selection. Some mildly deleterious variants drift to higher frequencies in bottlenecked populations, but this is different from the systemic collapse the entropy argument describes. One thing I ran into that always bothered me was how the literature on this topic handles the concept of mutational meltdown. The theory says that once a population crosses a certain threshold, the decline becomes self-reinforcing because fewer individuals mean stronger drift, which means more fixation of bad mutations, which means even fewer individuals. In practice, I've seen this happen in endangered species with very small effective population sizes. But the threshold for crossing that point is much lower than what the entropy papers typically imply. Most natural populations sit well below it unless they've been severely fragmented by human activity. Here's a specific example from my own work that illustrates why the simple model fails. I was analyzing mutation accumulation data from a laboratory Drosophila line that had been maintained for over 200 generations with minimal selection pressure. The initial assumption was that fitness would decline linearly. What actually happened is that the first fifty generations showed a steep drop in viability, then the rate slowed dramatically and eventually stabilized. The pop-upI attributed this to the removal of the most deleterious mutations early on, leaving behind a load of very mildly harmful variants that selection struggles to act on but also don't cause catastrophic decline. This is the mutation-selection balance, not entropy in the thermodynamic sense that the original framing suggests.
Get the Full Details
Protein Space and the Functional Genome Problem
The "mystery" part of the genome question has to do with function. The ENCODE project caused a huge debate when it claimed that eighty percent of the genome is biochemically active. Most evolutionary biologists pushed back hard, pointing out that biochemical activity doesn't equal functional necessity. A large portion of transcription and protein binding happens at sites that are not conserved and are likely byproducts of the machinery rather than selected features. When I look at this myself, the useful framework is not whether a sequence is "functional" in some absolute sense but how constrained it is across species. Phylogenetic conservation analysis using tools like PhastCons and GERP++ scores tells you where mutations are actually tolerated. The results consistently show that only about five to ten percent of the human genome is under strong purifying selection. The rest is either neutral or only very weakly constrained. This doesn't prove the entropy argument wrong or right on its own, but it does mean that the total mutational target size is smaller than some versions of the argument assume.
Common Misunderstandings and What Actually Matters
There are a few recurring mistakes people make when engaging with this topic. The first is conflating mutation load with genetic entropy. Mutation load is a real and well-studied phenomenon. It refers to the reduction in population mean fitness caused by deleterious alleles. Everyone agrees this exists. Genetic entropy adds a layer of claim about irreversibility and systemic collapse that goes well beyond what the data supports. The second mistake is treating the human mutation rate as a fixed constant. It varies by parent age, by sex, by population, and by individual. Paternal age alone contributes a well-documented increase in de novo mutation count, adding roughly two extra mutations per year of father's age. This variability matters for any realistic model but gets smoothed over in the simplified versions of the entropy argument. A third issue is the handling of beneficial mutations. The entropy framework largely treats new mutations as either neutral or harmful. This is a poor approximation. While beneficial mutations are rare, they do occur and they matter. Adaptation in response to new environments, pathogens, or dietary shifts requires exactly this kind of mutation supply. Ignoring it makes the models predict constant decline when the real dynamics are far more balanced.
Where the Concept Is Actually Useful
Despite my skepticism about the stronger claims, there are legitimate applications. Conservation biologists use mutation accumulation theory to assess extinction risk in small populations. The concept helps frame why genetic rescue through immigration can be critical. Adding unrelated individuals introduces new variation and dilutes the deleterious load. This is not a theoretical exercise. I've seen it work with Florida panthers and several island bird populations where inbreeding depression was reversed within a few generations of managed gene flow. In agricultural breeding, the same principles apply. Maintaining genetic diversity is essential precisely because a narrowed gene pool exposes hidden deleterious recessives. Commercial livestock programs spend significant resources managing inbreeding coefficients and using genomic selection to identify carriers of deleterious alleles before they become fixed. This practical application of the underlying science is where the mutation accumulation framework is genuinely valuable.

Practical Takeaways
If you're working with genomic data and want to assess mutational load, start with variant calling and annotate your variants using tools like SnpEff or VEP. Filter for loss-of-function variants in genes with high pLI scores from gnomAD. Cross-reference with conservation scores. Calculate the expected load per individual using published per-base mutation rates and effect size distributions. Expect the number to be in the range of one to two lethal equivalents per diploid genome, which is the standard estimate from human pedigree studies. Don't expect that number to tell you anything dramatic about population-level trajectories without accounting for population size, structure, and selection history. The broader point is that genomes are dynamic systems shaped by mutation, drift, selection, and recombination. Calling one of those processes "entropy" gives it a thermodynamic weight that biology doesn't actually carry. The system can degrade under the right conditions, usually small population size with reduced gene flow, but it can also recover. The data from real populations supports that balance. The mystery of the genome is real and worth studying. The entropy narrative adds certainty to a question that remains genuinely open.