Why Your First NLP Project Will Break
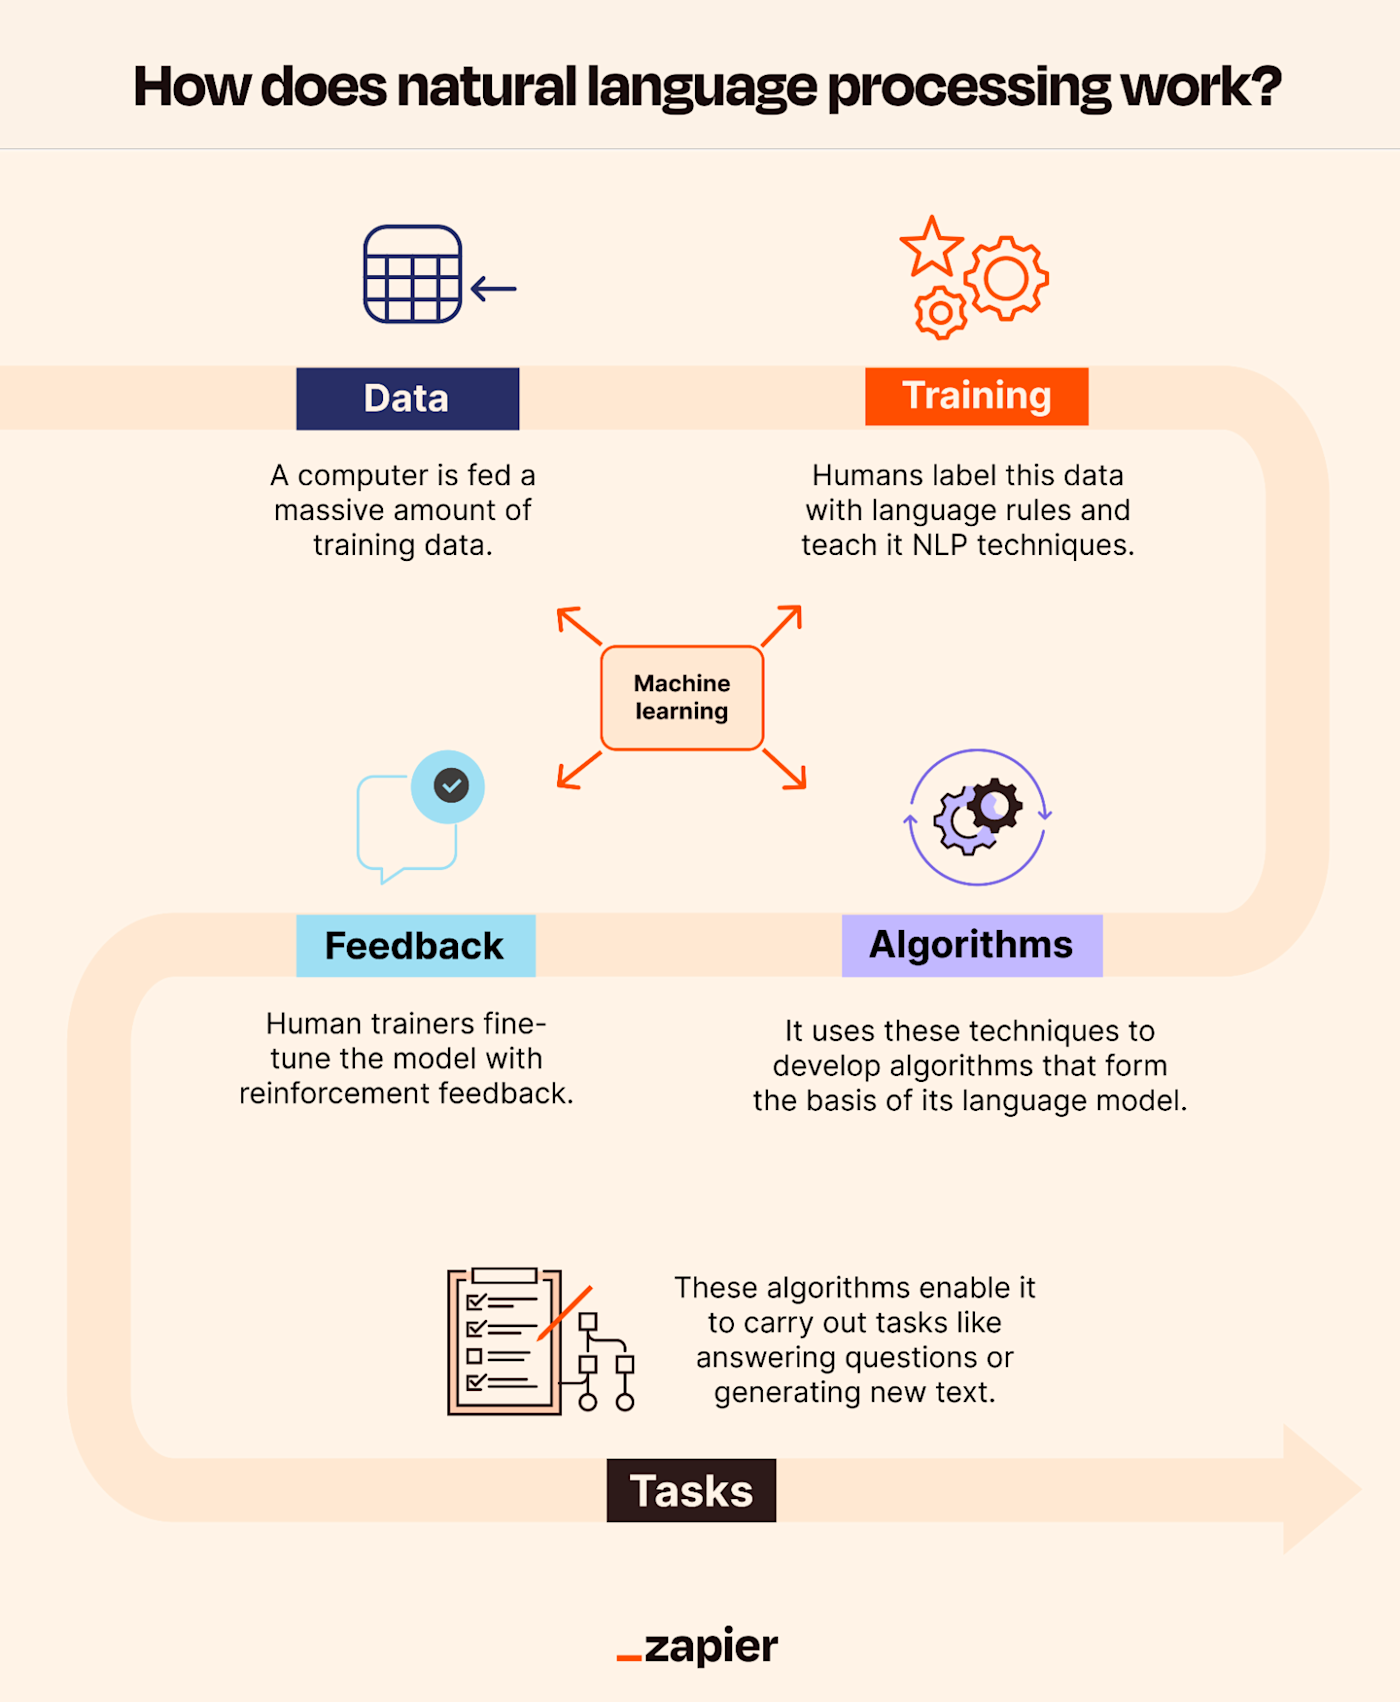
You'll read tutorials that make it look like you download a model, pass in some text, and get usable results. That's not how it works. The gap between a working demo and something that survives in production is where most people quit. I spent three months debugging a text classification pipeline before realizing the problem wasn't the model at all. It was my tokenization strategy handling nested parentheses in technical documentation, which turned meaningful tokens into garbage strings that confused the attention mechanism. Once I switched to a character-level fallback for those specific segments, the F1 score jumped from 0.61 to 0.79. That kind of thing doesn't show up in any beginner guide. Natural Language Processing sits somewhere between linguistics and statistics, and the field has moved fast. Twenty years ago you'd be hand-crafting features with TF-IDF and hoping. Now you fine-tune large pretrained models. But the core challenge hasn't changed: words carry meaning through context, and models need to capture that context in a form they can optimize over. The transformer architecture, introduced in 2017, dominates because attention mechanisms let models weigh the relevance of every token to every other token in a sequence. That's fundamentally different from LSTMs, which process left-to-right and lose information about earlier tokens. If you encounter older tutorials recommending recurrent models, skip them unless you have a specific reason. They're slower to train and generally underperform transformers on the same task.
Getting Started With Natural Language Processing
The practical entry point for most people is Python with the Hugging Face ecosystem. Install Python 3.10 or newer, set up a virtual environment, then install these packages: transformers, torch or tensorflow, datasets, and scikit-learn. That's roughly 90% of what you'll use. Don't overcomplicate the initial setup. Before you touch a model, understand your data. Load a small sample and manually inspect fifty examples. Count how many classes exist. Note whether your text contains unusual characters, URLs, code snippets, or mixed languages. This step takes maybe twenty minutes but prevents hours of confusion later. I once built a sentiment model on product reviews without checking for multilingual content. Roughly 15% of the training data was Japanese and Korean. The model learned to associate those scripts with neutral sentiment and produced garbage predictions for any mixed-language input. Tokenizers convert raw text into integer IDs the model understands. The standard choice is Byte-Pair Encoding, which handles out-of-vocabulary words by breaking them into subword units. Consider the word "unbelievable" tokenized by a BERT tokenizer: ["un", "##be", "##lie", "##v", "##able"]. The prefix indicates these tokens continue from the previous one. This is useful but not perfect. Domain-specific terms like "cryptocurrency" might split into ["cry", "##pto", "##cur", "##re", "##ncy"], losing semantic cohesion. For specialized domains, you often need to extend the tokenizer vocabulary with your own terms before training.
Here's a minimal example of loading a tokenizer and preprocessing a dataset:
Get the Full Details
from transformers import AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("bert-base-uncased")

def tokenize_function(examples):
    return tokenizer(examples["text"], padding="max_length", truncation=True, max_length=128)

max_length=128 is a reasonable starting point. Longer sequences cost more computationally.
Most tasks don't benefit from sequences above 256 tokens, and you pay roughly quadratic
attention cost as length increases.
Choosing a Base Model
The model you pick depends on your hardware, your task, and your tolerance for risk. BERT-base has 110 million parameters and fits comfortably on a consumer GPU with 8GB of VRAM. RoBERTa-base, a refinement of BERT, typically outperforms it by 1-2% on standard benchmarks because it was trained longer with more data and dynamic masking. DeBERTa is heavier and slower but handles context slightly better. DistilBERT offers about 40% fewer parameters than BERT with roughly 97% of its performance. That's worth considering if you need faster inference at the cost of a small accuracy drop. For multilingual tasks, take the multilingual variant: "bert-base-multilingual-cased" covers 104 languages but isn't optimized for any single one. If your task is monolingual, a language-specific model usually outperforms the multilingual one by a meaningful margin.
Fine-Tuning Process
Fine-tuning means taking a pretrained model and continuing to train it on your labeled data. The pretrained weights already encode general language knowledge. You're adapting that knowledge to your specific task. Use Hugging Face's Trainer API, which handles most of the plumbing: The learning rate is the most sensitive hyperparameter. Values between 1e-5 and 5e-5 are standard. Going above 5e-5 often causes the model to diverge and lose its pretrained knowledge entirely. I've seen this happen when someone copy-pasted a learning rate from a computer vision tutorial without adjusting it. The model's loss spiked and never recovered. Batch size matters too. Smaller batches introduce more noise into gradient updates, which can help generalization but may slow convergence. Larger batches train faster but sometimes generalize worse. The sweet spot for most people is between 16 and 32 on a single GPU. If you're training on CPU, drop to 8 or even 4.
Evaluation Metrics Matter More Than Accuracy
Accuracy is useless when your classes are imbalanced. If 80% of your data belongs to one class, a model that always predicts that class achieves 80% accuracy and is completely useless. Report precision, recall, and F1 score instead. For multi-class problems, micro-F1 gives you a global measure while macro-F1 treats all classes equally regardless of size. Set aside a held-out test set and don't look at it until training is completely finished. Every time you check the test set and adjust your approach, you're accidentally leaking information from your test data into your model selection process. This is one of the most common mistakes I see, and it inflates reported performance by 3-5% on average.
A Common Failure Mode I've Seen Repeatedly
Label leakage. This happens when your training data contains information in the text that directly reveals the answer. For example, if you're building a movie review sentiment classifier and your positive reviews consistently contain phrases like "best movie ever" while negative ones contain "worst film," the model learns shortcuts instead of actually understanding sentiment. It achieves high accuracy during training but fails on real data where those patterns don't appear so cleanly. The workaround is to check whether your model is relying on surface-level patterns rather than genuine linguistic understanding. Remove the most obvious sentiment-bearing phrases from your dataset and retrain. If performance drops dramatically, your model was overfitting to those cues. A robust model should maintain reasonable performance even when those shortcuts are removed.
Handling Long Documents
Standard transformers have a maximum sequence length, typically 512 tokens. Documents longer than that get truncated, which loses information. There are a few approaches here. You can split the document into chunks and average the predictions, which is simple but discards cross-chunk relationships. Sliding window approaches with overlapping segments are more thorough but multiply your computational cost. Specialized architectures like Longformer or BigBird support longer contexts natively but require more GPU memory and training time. For most practical purposes, chunking with overlap works well enough. Use a chunk size of 256 tokens and an overlap of 64 tokens. This preserves some context across boundaries without exploding memory usage. Average the per-chunk predictions using a softmax weighted by confidence scores.
When Pretrained Models Won't Work
Sometimes your domain is too specialized. Medical literature, legal documents, or highly technical engineering forums all contain terminology and structures that general-purpose models haven't seen. In these cases, you have two options. Continue pretraining on your domain corpus before fine-tuning, or use a retrieval-augmented approach where you pull relevant reference material at inference time. Continued pretraining is expensive. You need a substantial corpus, ideally hundreds of megabytes of clean text at minimum, and you need GPU access. A single fine-tuning run on a consumer GPU takes a few hours. Continued pretraining on a medium-sized corpus can take days. The second option, retrieval augmentation, is computationally lighter at inference time but adds latency from the retrieval step. Depending on your application, that extra latency might be acceptable or completely unacceptable.

Production Deployment Considerations
Training a model is the easy part. Running it in production reliably is where things get harder. Export your model to ONNX format for cross-platform inference compatibility. Use quantization to reduce model size and improve inference speed. A quantized RoBERTa model runs at roughly 2x the speed of the full-precision version on CPU with less than 1% accuracy loss. Remember that your model will see inputs it was never trained on. Out-of-distribution samples, adversarial prompts, malformed text. Build input validation and error handling into your pipeline. Catch tokenizer errors gracefully. Set reasonable time limits on inference calls. Log failed predictions so you can identify patterns in what's going wrong. The field moves quickly. Newer models like DeBERTa-v3 and Falcon variants push performance further, but they also demand more compute. For most projects, a well-finetuned RoBERTa or DeBERTa-base model on good data will outperform someone using a larger model on poor data. The data quality and task formulation matter more than the model size after a certain point. Focus on cleaning your data, getting the labels right, and evaluating properly. Everything else is optimization.