Understanding Gradients in Earth Science Workflows
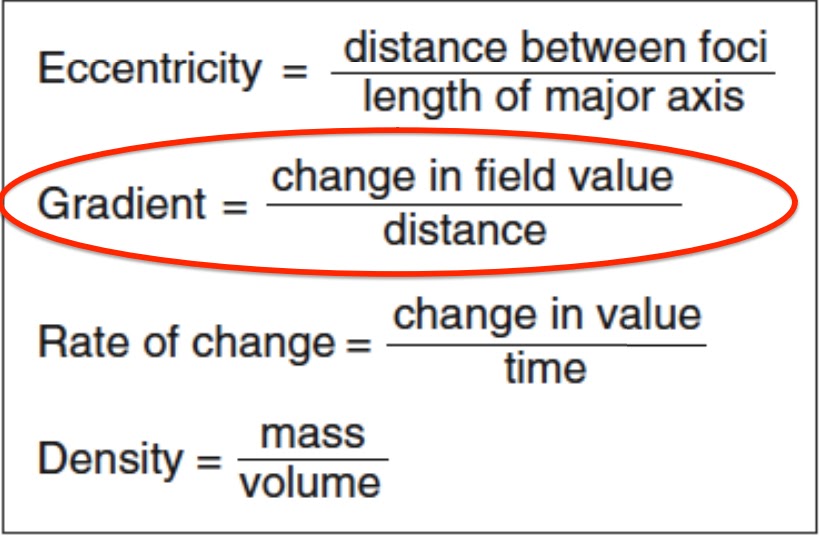
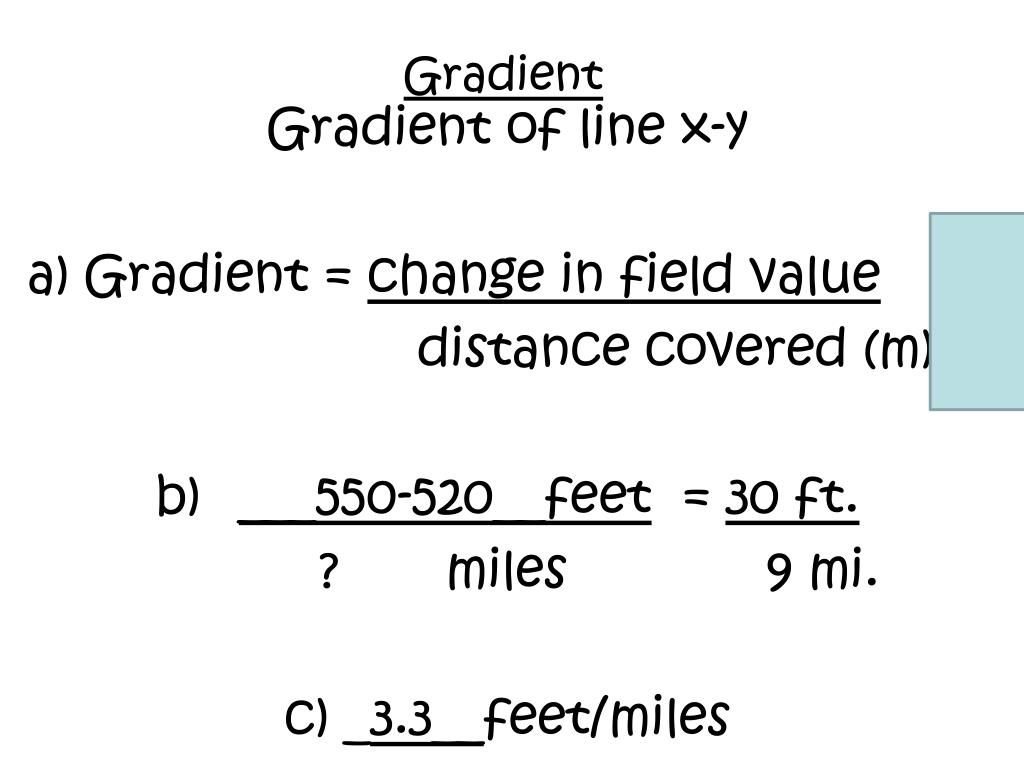
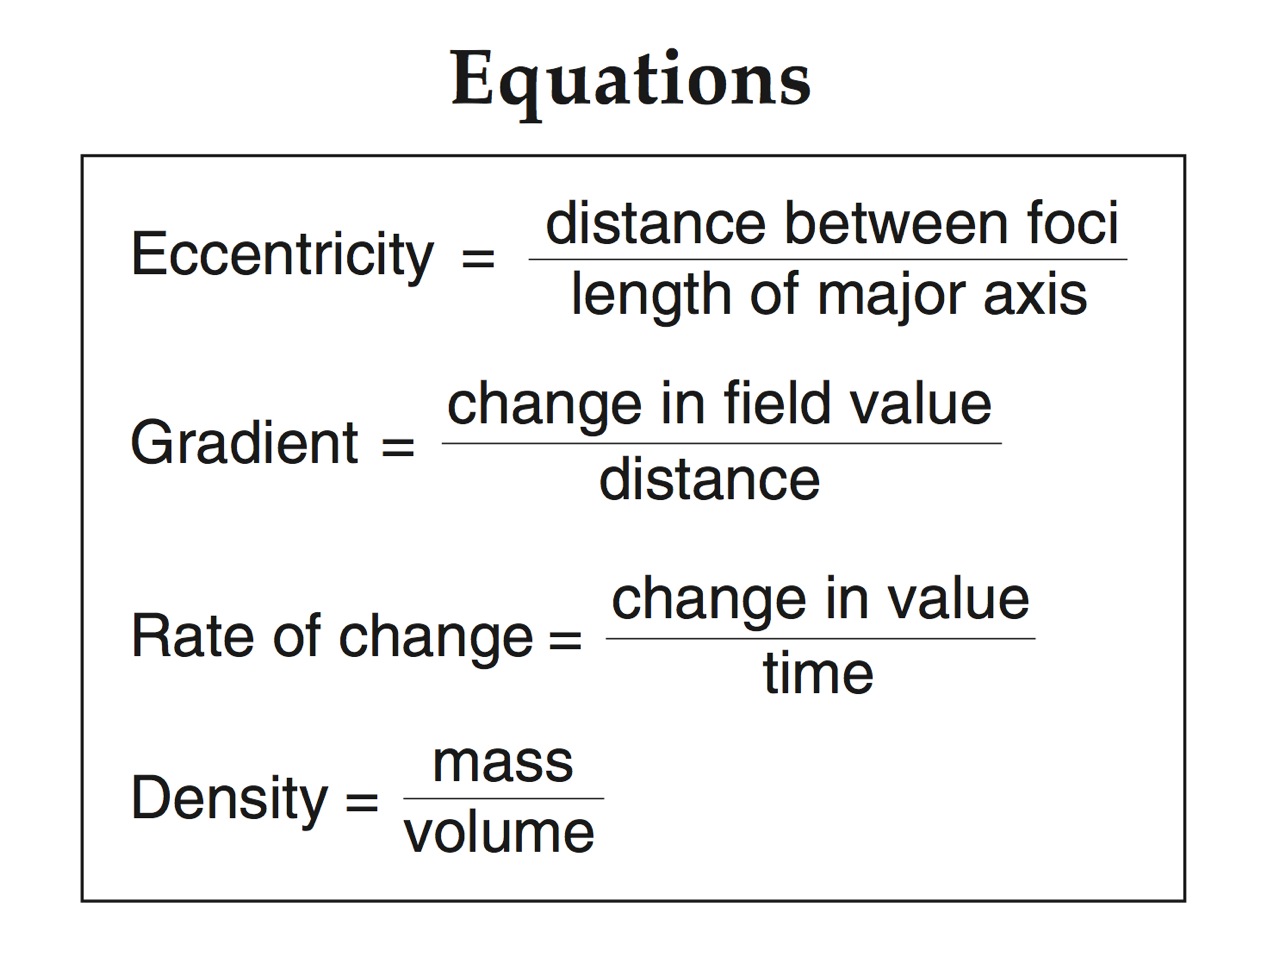
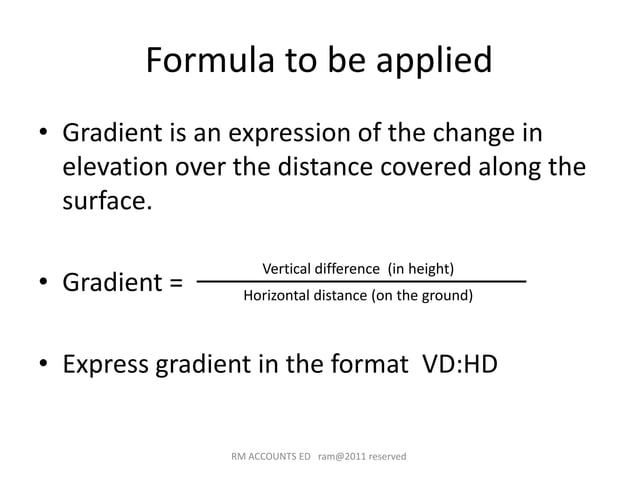
When I first started mapping terrain using numerical models, I treated gradient calculation like a trivial step in the pipeline. That changed quickly. A gradient in Earth Science is really just the rate of change of some scalar field across space — temperature, elevation, pressure, concentration, whatever you're measuring. But the math behind getting it right in practice is messier than most textbooks make it look. The core Gradient Formula Earth Science framework depends on what type of data you're working with. If you're dealing with raster DEM data at a fixed resolution, you typically use finite differences. For point clouds or irregular sampling, interpolation becomes part of the problem before you even get to the derivative. Most people skip that distinction and just run a standard Sobel or Prewitt operator on everything, which produces garbage results at coastlines and dataset boundaries.
Gradient Formula Earth Science: The Practical Breakdown
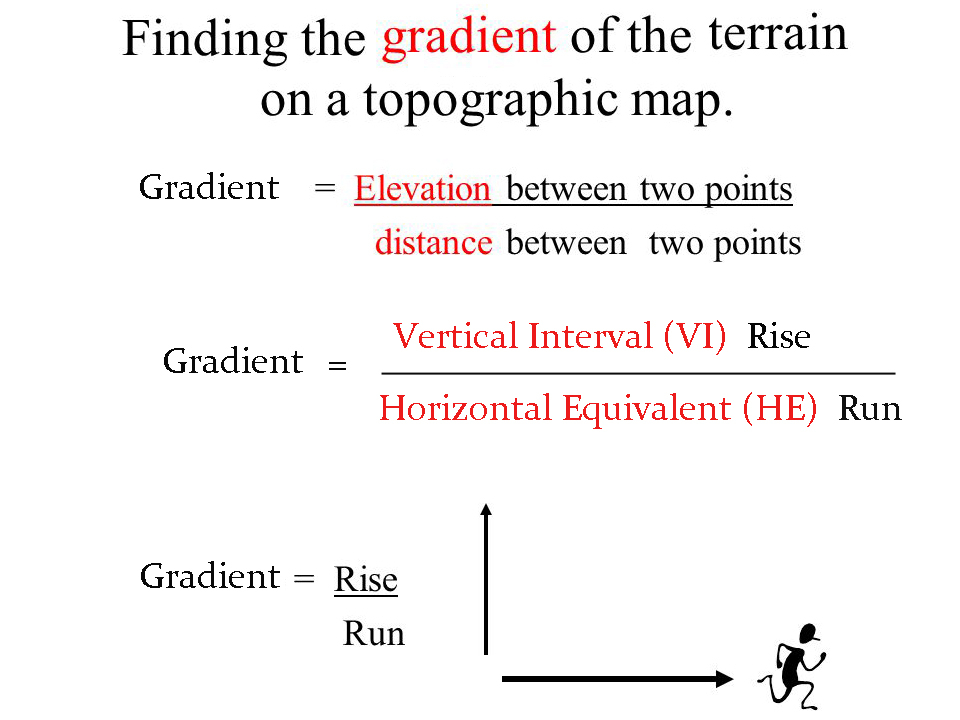
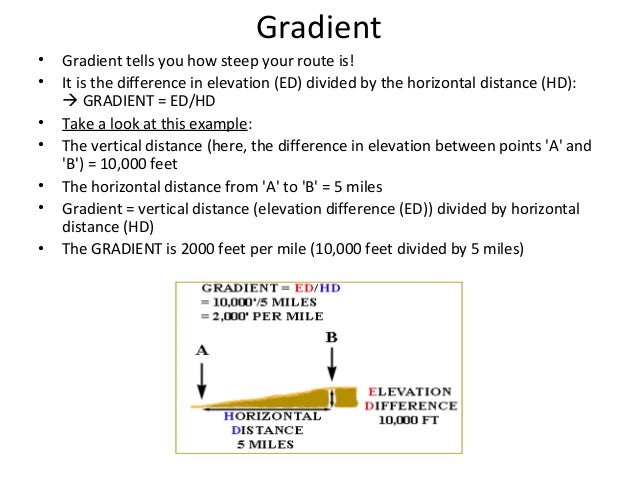
Here's how the basic two-dimensional gradient works for a scalar field f(x,y). The gradient vector is composed of partial derivatives along each axis. For a digital elevation model stored as a matrix, you approximate the x-component by taking the difference between the cell to the right and the cell to the left, divided by the cell spacing. Same idea for the y-component using the cell above and below. The magnitude of the slope at any given cell is the square root of the sum of those two squared components. That's it on paper. Real terrain is not that cooperative. I spent three weeks debugging a project where my gradient magnitudes were spiking to impossible values along a river valley. The DEM had a resolution of thirty meters, but the vertical accuracy was only about two meters due to LiDAR filtering artifacts. What was happening is that a single noisy point in a flat floodplain was creating a false vertical drop of several meters over a horizontal distance of thirty meters, producing gradient values that implied a near-vertical cliff where none existed. The fix wasn't a better formula. It was applying a conditional slope threshold — I masked out any cells where the raw gradient exceeded twenty degrees and recalculated using a localized median filter on the elevation values before re-running the differentiation. That brought the outlier spikes down to physically realistic ranges within about four hours of compute time instead of iterating on the kernel itself. Most tutorials don't mention that the choice of finite difference scheme matters enormously when your grid isn't uniform. If your sensor data has variable spacing — which is almost always the case with real survey data — using a simple central difference formula on an assumed regular grid will introduce systematic bias. The workaround is to use a weighted least-squares gradient estimator that accounts for the actual distances between neighboring points. It's computationally heavier, maybe thirty to fifty percent slower depending on your implementation, but it eliminates the grid-assumption error that silently corrupts a lot of published slope analyses.
Another thing that catches people off guard: gradient direction and aspect are not the same thing, even though they're closely related. The gradient vector points in the direction of steepest ascent. Aspect is the compass direction that the slope faces, which is conventionally measured from the downward-pointing direction. So aspect equals the gradient azimuth plus one hundred eighty degrees, modulo three sixty. When I see people conflating these in field reports, it usually means someone copied code from a GIS tutorial without understanding what the output actually represents. That matters when you're modeling solar radiation exposure or soil moisture redistribution, because a northeast-facing slope and a southwest-facing slope at the same gradient magnitude will have dramatically different energy budgets. For three-dimensional applications — say you're working with subsurface temperature or salinity data from borehole measurements — the gradient becomes a volume calculation. The same principles apply but now you're differentiating across three axes. The computational cost scales with the number of voxels and the size of your stencil. I've seen people try to run centered finite differences on a half-billion voxel dataset on a single CPU core and wonder why it took two days. Switching to a GPU-accelerated implementation with chunked memory access patterns dropped that to roughly forty minutes on consumer hardware. The algorithm didn't change. The memory hierarchy did. There are also cases where the gradient formula breaks down entirely and nobody warns you about that upfront. Fractured or faulted terrain with discontinuities across cell boundaries will produce meaningless gradient values right at the break. A normal finite difference scheme has no way to know that two adjacent cells are separated by a fault scarp rather than a continuous slope. You need to either mask out those zones using geological lineament data or switch to a gradient-preserving interpolation method that respects known discontinuities. Otherwise your slope map will show smooth transitions across geological boundaries that are actually vertical offsets of tens of meters.
Get the Full Details
For people just getting started, I'd recommend building a small test case with synthetic data before touching real terrain. Generate a known quadratic surface, compute its analytical gradient by hand, then compare it against your numerical implementation cell by cell. If your errors aren't on the order of the grid spacing squared for a second-order scheme, something is wrong with your indexing or your boundary conditions. This usually takes about fifteen minutes and saves you from chasing phantom bugs in production data for days. The takeaway is straightforward: the math is simple, the implementation is where things go wrong, and the edge cases are what define the quality of your result. Most of the work in gradient-based Earth Science analysis isn't deriving formulas. It's understanding what your data can and cannot support before you run the calculation.