Plotting Variables Without Overcomplicating It
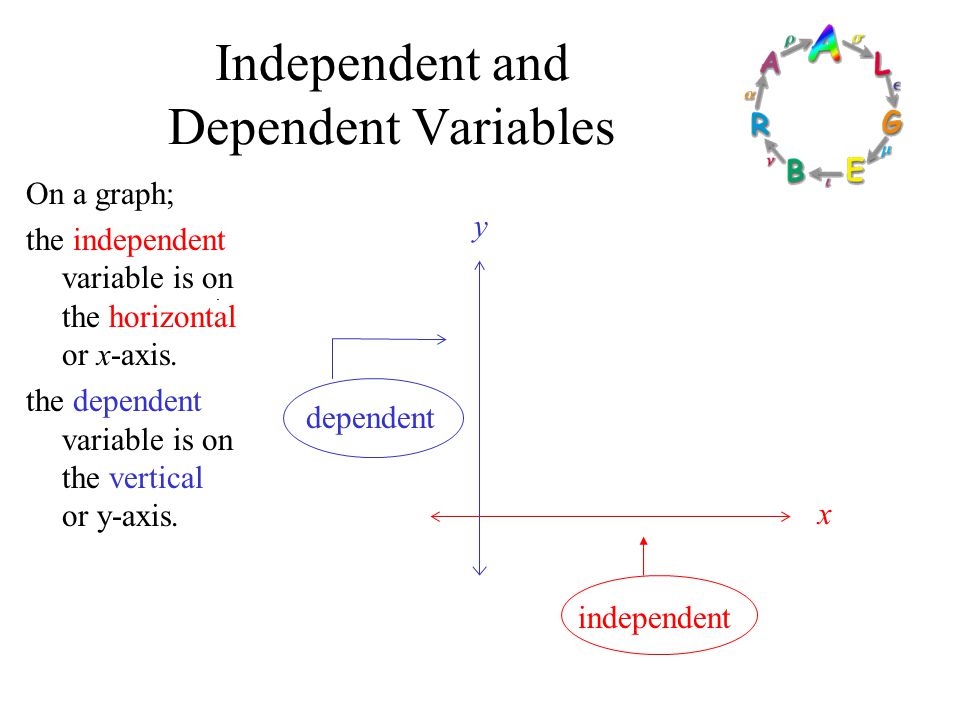
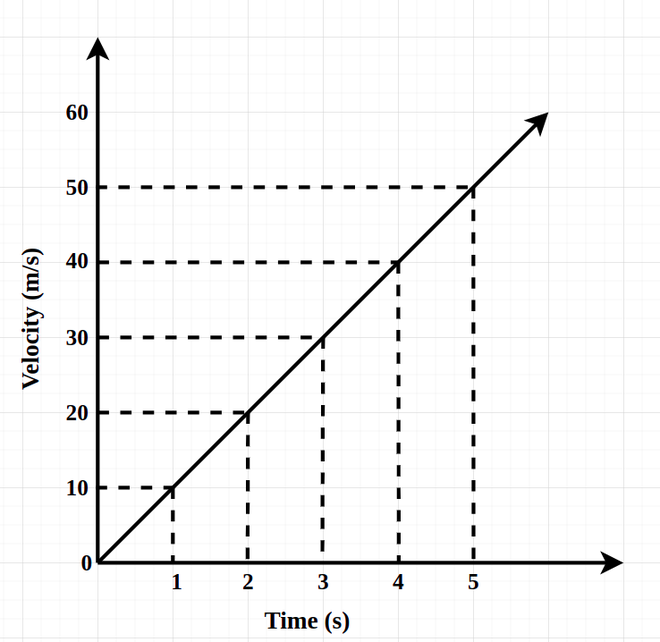
The actual mechanics are simpler than most people make them. You put the independent variable on the horizontal axis and the dependent variable on the vertical axis, then you plot your data points. That's the foundation. The stuff that goes wrong happens when people don't think through which variable actually depends on the other before they start charting. I've seen this mistake constantly in lab reports and business dashboards. Someone plots time on the y-axis and distance on the x-axis, then gets confused why their slope doesn't match their expectations. The slope is rise over run, so whatever you put on the vertical axis is what's changing as a result of whatever you put on the horizontal. Flip those two around and your interpretation flips too.
Graph Of Dependent And Independent Variable — How To Actually Set It Up
Start by identifying what you're controlling or what's happening on its own timeline. That's your independent variable. Everything else that responds to it is dependent. In a physics lab measuring free fall, you control time intervals. The distance fallen depends on those intervals. Time goes on the x-axis. Distance goes on the y-axis. In a business context, think about it differently. If you're testing how ad spend affects sales revenue, your budget allocation is independent because you decide it. Revenue is dependent because it responds to that allocation. Put spend on the horizontal axis, revenue on the vertical axis. The trendline slope tells you your return per dollar spent. That's immediately actionable. A flat slope means you're wasting money. A steep positive slope means you should probably scale up. Here's where people mess up the formatting. Excel defaults can be annoying. When you throw raw data at it without telling it which column is which, it sometimes assigns the axes backwards or treats your headers as data points. I always select the data range first, make sure my independent variable is in the left column, then insert a scatter plot. Line charts look cleaner but they assume equal spacing between x-values. If your time intervals are irregular, a scatter plot with lines connecting the dots is safer. The visual difference is subtle but your analysis won't be wrong.
One edge case I run into fairly often: categorical independent variables. Say you're comparing test scores across five different teaching methods. Methods aren't numbers you can meaningfully order, so treating the x-axis as a numerical scale will give you nonsense interpolation between categories. What I do instead is use a column chart or set the x-axis to text categories manually. Don't force a linear regression on qualitative groups. The statistical output will look precise but it's not valid. Another thing beginners miss is the difference between correlation and causation on a graph. Your dependent variable might track closely with your independent variable, but that doesn't mean one causes the other. I spent weeks debugging a model where temperature and ice cream sales both rose together, and the initial reading made it look like heat caused higher sales. It was just a seasonal correlation. Third variables were driving both. Always check for confounding factors before you present a graph as proof of anything. Log scales are another area where people get tripped up. When your dependent variable spans orders of magnitude, a linear axis compresses the early data into an unreadable cluster near the bottom. Switching the y-axis to logarithmic scale spreads things out. The tradeoff is that slopes no longer represent constant rates of change. A straight line on a log scale means exponential growth, not linear growth. If someone asks what the slope means, you need to know how to answer correctly. Saying "it's the rate" is wrong on a log axis. It's the percentage rate of change, or the growth coefficient depending on which log base you're using.
Get the Full Details

Here's a practical workflow I use: dump your data into a spreadsheet, verify there are no blank cells or text mixed into numeric columns, set up your axes with the independent variable first, add a trendline but don't just accept the default display of the R-squared value without checking the residual plot. If your residuals show a pattern instead of random scatter, your model is wrong even if R-squared looks impressive. I once had a dataset that gave an R-squared of 0.94 and looked perfect on the surface. The residual plot revealed a clear curve, meaning the relationship was quadratic, not linear. My original model would have underestimated outcomes at both extremes by roughly 18 percent. Fitting a second-degree polynomial corrected it completely. When you're presenting these graphs to someone who isn't technical, strip away everything that isn't necessary. Gridlines beyond the major ticks create visual noise. Legends are only needed when you have multiple series. Axis labels should include units. A graph showing "temperature" without saying Celsius or Fahrenheit is basically useless. Title your chart with what the reader should actually take away from it, not just "Results." Something like "Monthly Revenue Grows 12 Percent Per Unit of Ad Spend" tells the story faster than any caption underneath. Software choice matters less than you'd think. Python with matplotlib gives you precise control but requires writing code. Excel handles quick charts in seconds but fights you on customization. R is powerful for statistical graphics but has a steep learning curve. For most people doing routine analysis, Excel or Google Sheets covers the basics. If you need publication-quality output or complex multi-panel figures, move to Python. The transition usually takes about a day of practice to get comfortable with the syntax.
One final practical note: always save your raw data separately from your visualizations. I've lost count of the number of times someone edits their chart and accidentally changes the underlying data values without noticing. Keep a master file that never gets touched. The graph is a representation, not the data itself. When things go wrong—and they always do at some point—having the original source lets you rebuild from scratch instead of chasing ghosts.