The Actual Mechanics Behind Loot Table Implementation
Most developers approach loot tables as simple arrays with item IDs and probabilities. That works until your game ships and players notice the patterns. The reality is that a functional loot table system involves weighted pools, rarity tiers, scaling modifiers, and edge-case handling that most tutorials skip entirely. I built a loot system for a project where the initial design used flat percentage weights across all items. By week three of testing, we had players complaining about never seeing legendary drops, and the data confirmed they were getting them — just not in predictable patterns. The issue wasn't the math. It was that flat weights don't account for diminishing returns or the perception of randomness. Players remember bad runs far longer than good ones, and a pure weight system makes that feel even worse.
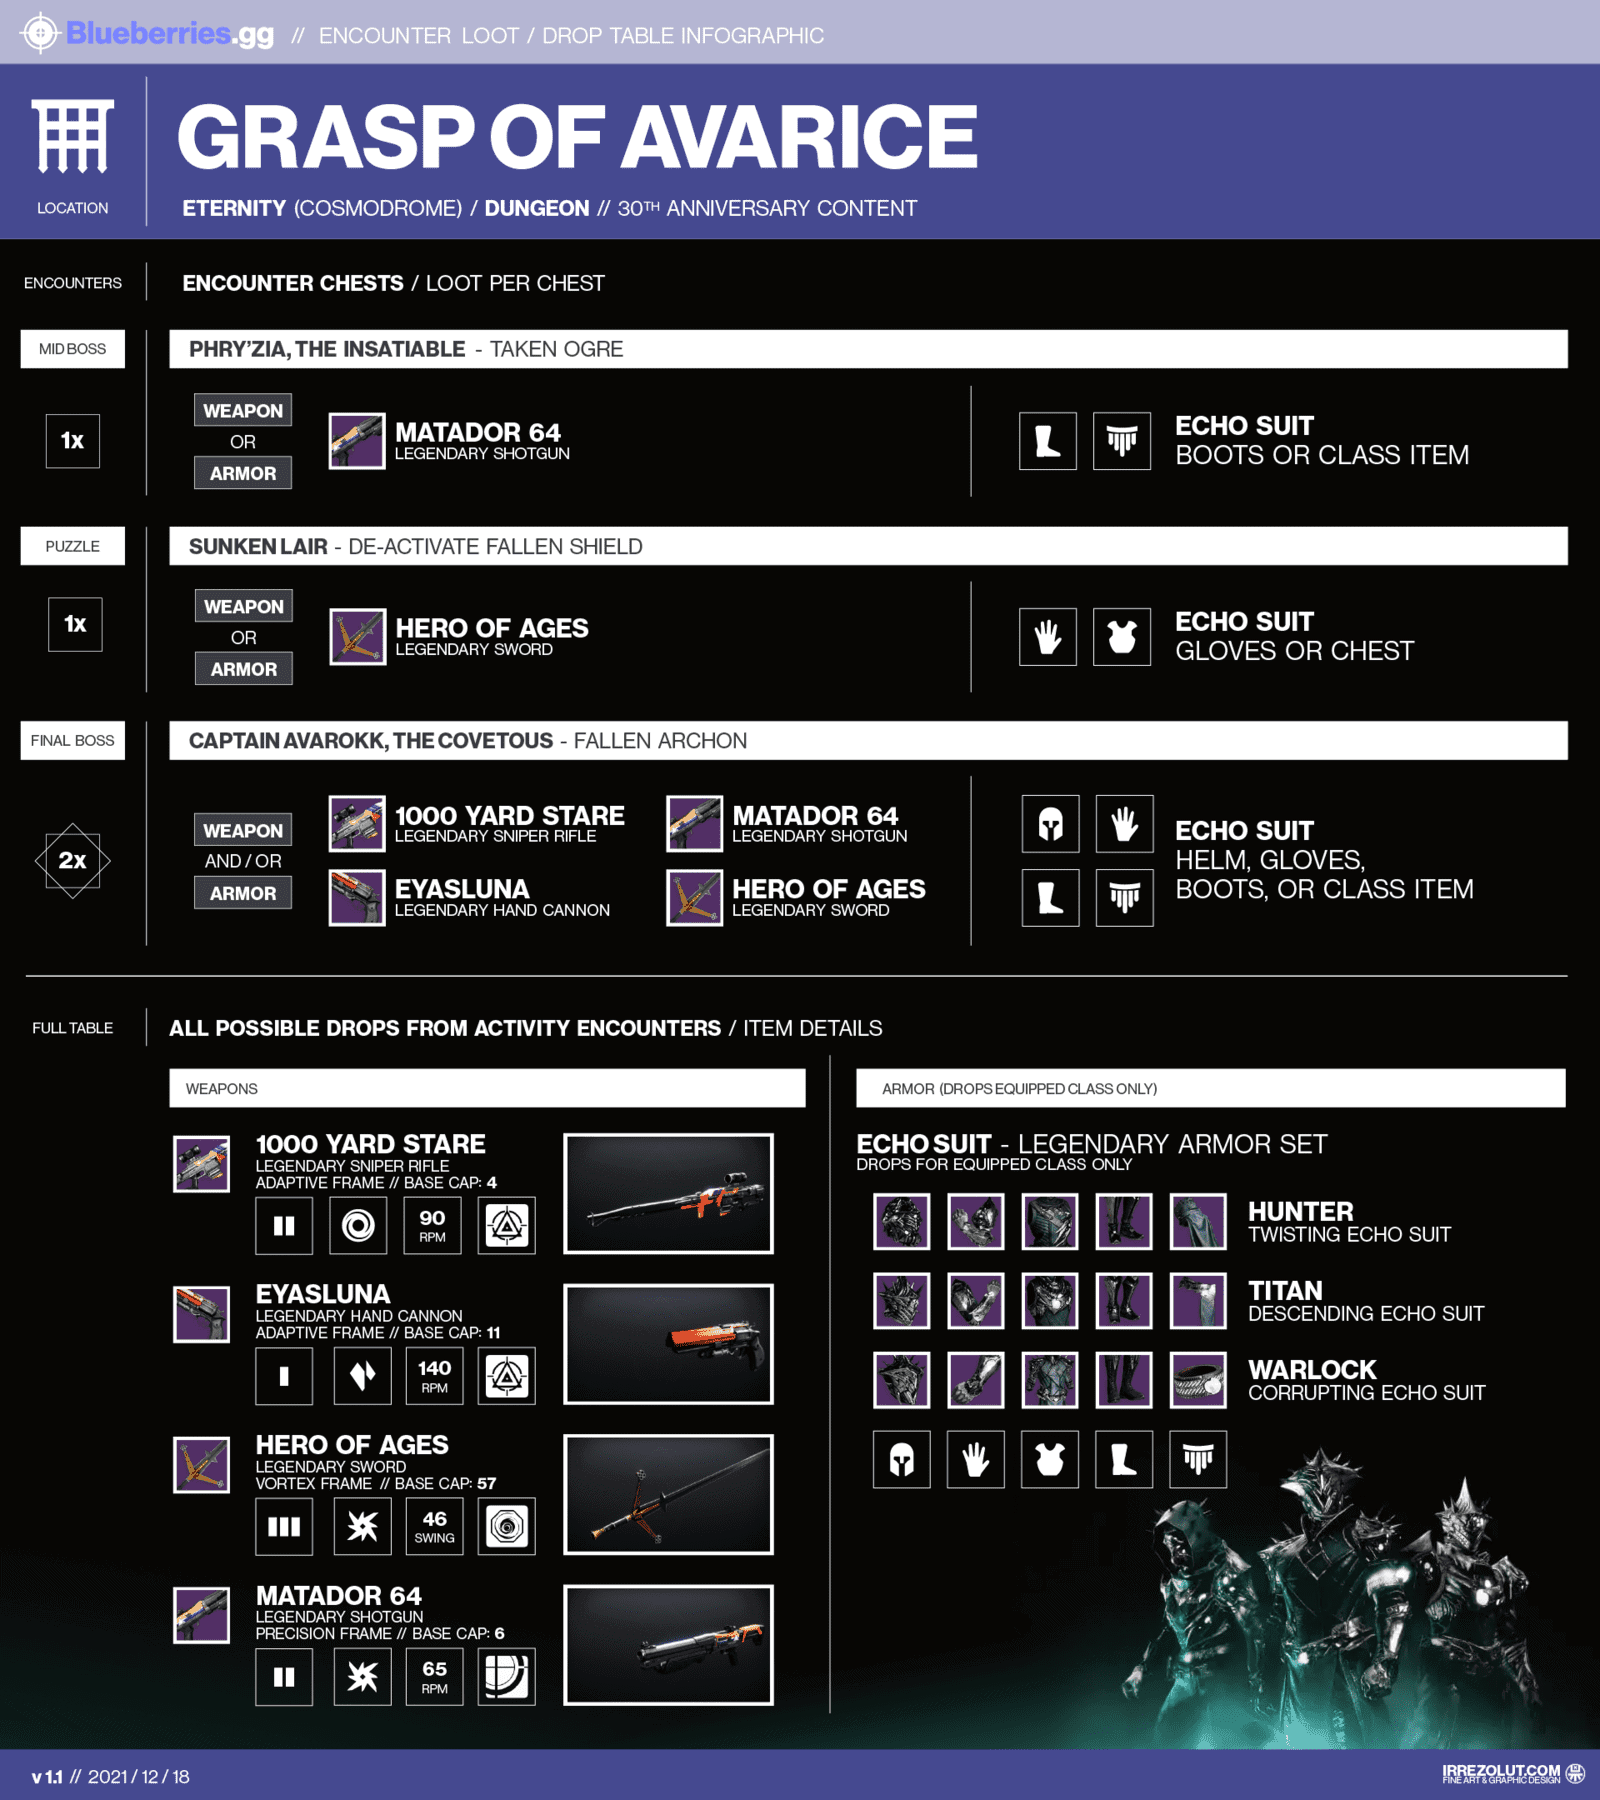
Grasp Of Avarice Loot Table
This concept revolves around how items are selected from a structured pool where each entry carries its own set of parameters beyond just a name and probability. There are multiple ways to structure this, and the approach you choose affects everything from memory usage to the feel of individual drops. The basic structure looks like this: you define a pool of entries. Each entry contains an item reference, a weight value, and optionally a rarity tier, quantity range, and conditional modifiers. When the system runs, it sums all weights, generates a random number across that total, and selects the matching entry. Simple on paper. The complications start when you layer in additional rules. Weighted selection alone creates one common failure mode. If you have ten items at equal weight, each has a 10% chance. That means in a streak of twenty drops, it is statistically normal for some items to appear zero times while others appear three or four times. Players interpret this as broken. The fix is straightforward: implement a pity timer or a modified lottery system where the probability of a rare item increases slightly with each consecutive non-drop of that item.
Another issue that catches people off guard is how quantity rolls interact with weight rolls. Some systems roll for quantity first, then for item type. Others do it the other way around. The order changes the distribution significantly. If you roll quantity first and get a multi-drop result, then pick from the pool for each quantity, common items dominate the result set. Rolling for item type first and then determining quantity gives you a different balance. Most well-designed systems handle these as separate phases with explicit ordering defined in the documentation.
Get the Full Details

Implementation Approaches and Tradeoffs
There are really three common architectures for loot table systems, and picking the wrong one creates technical debt that is painful to fix later. The first is the flat array approach. You store everything in a single list or dictionary. This is fast to implement and easy to debug. It becomes a problem when you have hundreds or thousands of entries because iterating through the full list on every drop is wasteful. More importantly, grouping by zone or enemy type requires manual management of which entries are active in each context. The second is the tiered hierarchy approach. You organize entries into rarity tiers — common, uncommon, rare, legendary — and roll within a tier first, then select an item from that tier. This gives you explicit control over drop distribution. A 95 percent common, 4 percent uncommon, 0.9 percent rare, 0.1 percent legendary setup guarantees that rare items appear at a predictable rate regardless of how many entries sit in each tier. This is the most common approach in commercial games and for good reason.
The third is the probability curve approach, where instead of discrete tiers you use a continuous function to determine rarity based on a random value. This is more complex to tune but produces smoother distribution curves. It is also harder for players to understand or for designers to adjust on the fly without running simulations. I ran into a specific problem with the tiered approach on a project where certain enemies had unique loot pools that overlapped with general pools. A boss could drop both a unique item and something from the standard pool. The initial implementation rolled once for the boss and once for the general pool, but because both pools had different rarity distributions, the unique item was effectively competing against common drops that had no business being in the same calculation. The workaround was to separate guaranteed unique drops from randomized pool rolls entirely. Unique items use a fixed probability check that runs independently before the loot table roll. This means the unique drop chance is never diluted by the size or composition of the general pool.
Scaling and Dynamic Modifications
Static loot tables are fine for a basic prototype. They fall apart when you need difficulty scaling, seasonal events, or player progression systems. The most robust systems support dynamic modifiers applied at runtime. Lucky drops are the simplest modifier. You add a percentage chance that any roll upgrades the item to the next rarity tier. This is easy to implement but dangerous if not bounded. A 10 percent lucky drop rate sounds generous until you run simulations and see how much it inflates high-tier item distribution across your entire economy. Bonus rolls are another common modifier. Instead of upgrading the tier, you grant an additional roll on the table. This increases overall drop volume without directly affecting rarity distribution. It is the cleaner approach for most games because it scales quantity rather than quality, which keeps your economy more stable.

Conditional modifiers are where things get complicated. Area-specific pools, class-specific restrictions, event time windows, and player reputation thresholds all need to be evaluated before a roll executes. The key is keeping these checks fast and deterministic. I learned this the hard way when a reputation system caused loot tables to return inconsistent results because the reputation value was being read mid-animation frame and the value changed between the check and the roll. The fix was caching the evaluation result at the start of the drop sequence and using that cached value for all subsequent calculations within that single drop event.
Common Pitfalls That Break Player Trust
There are several mistakes that don't cause technical failures but destroy player confidence in your system. The most damaging is inconsistent drop rates across patches. If you change weights without documenting it, players will notice through community data mining and assume you are hiding information. Even if the change was necessary for balance, the perception of opacity is worse than any balance issue. Another pitfall is what I call the empty drop. This happens when a loot table roll selects an entry but the item is unavailable due to inventory space, quest lock, or other conditions. If the system simply discards the result and reports nothing, players perceive this as a failure. The fix is to either reroll within the available subset or convert the result into currency or experience based on the item's value. Both approaches feel more honest than silence. Poor naming conventions in the data files also create unnecessary problems. I once inherited a system where item references used internal IDs like ITEM_0x4F2A instead of readable names. Debugging a drop rate issue required cross-referencing three different spreadsheets. If you are building this from scratch, use human-readable identifiers and keep a mapping file. The five minutes it takes to set this up saves hours later.
Testing and Validation
You should never ship a loot table system without empirical testing. Theoretical probability does not match player perception. Run at least ten thousand simulated drops per table and compare the actual distribution against the expected distribution. Look for outliers, not just averages. A table might show the correct legendary rate on average but have pathological edge cases where the rate drops to near zero in short sequences. Log the results. Store individual drop sequences so you can replay problematic cases. I built a simple replay tool that let me watch drop sequences play out with timing visible. This revealed that two different systems with identical statistical properties felt completely different because of clustering patterns. One system grouped similar items together more often, which made the world feel less varied even though the numbers were correct. The tools you need are not complicated. A spreadsheet can model basic weight systems. Python or any scripting language can run large-scale simulations. The real investment is in the testing discipline, not the technology.