Getting GSEA Working in R Without Losing Your Mind
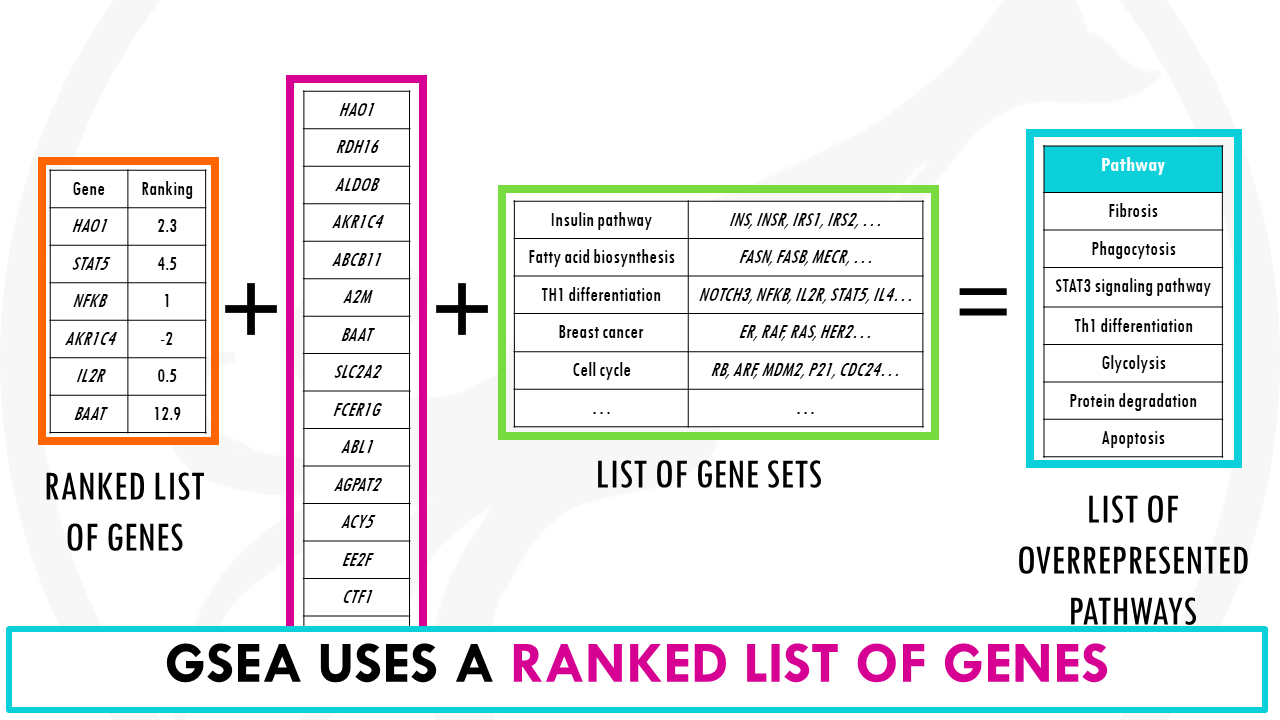
GSEA (Gene Set Enrichment Analysis) is a method for determining whether a predefined set of genes shows statistically significant, concordant differences between two biological states. The standard approach ranks all genes by a metric like signal-to-noise ratio or fold change, then walks down that ranked list calculating an enrichment score based on where gene-set members cluster. The result is an NES (normalized enrichment score) and an FDR q-value. That is the theory. The practice involves figuring out which R package actually does what you need and why your runs keep hanging. The two packages you will actually use are clusterProfiler and fgsea. They solve slightly different problems. clusterProfiler wraps the whole workflow including visualization and annotation. fgsea is a fast implementation of the original Korotkevich algorithm and is usually what people turn to when they have large gene sets and many permutations to run. You install them the normal way with BiocManager and devtools respectively. Both depend on graph-based infrastructure, so make sure your Bioconductor version is reasonably current or you will hit dependency conflicts that are not immediately obvious from the error messages.
What Gsea Analysis In R Actually Looks Like
Here is a minimal fgsea example that works for most differential expression results. You start with a named numeric vector of log2 fold changes, sorted in descending order. The names are gene identifiers matching your gene set database. If the names do not match exactly, the gene set terms silently return empty and you will waste time debugging why your results look blank. Then you load MSigDB or another collection, run fgsea(), and pull out the significant terms. The function call itself takes about 10 to 30 seconds for a typical RNA-seq experiment with 20,000 genes and 1,000 permutations. That is dramatically faster than the original GSEA Java implementation, which takes roughly 45 minutes to an hour on the same data on a standard laptop. The tradeoff is that fgsea uses a pre-ranked approach and you have to supply the ranked list yourself.
One thing that catches people off guard: fgsea defaults to 1,000 permutations. That is fine for a quick check but produces noisy FDR estimates. If you are publishing, bump it to at least 10,000. The runtime goes up roughly linearly, so expect 2 to 3 minutes instead of 15 seconds on a typical machine. Anything below 1,000 permutations gives you q-values that look dramatic but shift noticeably when you rerun. I spent three days last year troubleshooting why my GSEA results looked biologically plausible but the gene sets kept failing to pass FDR correction. The issue turned out to be that I had used row names from a DESeq2 results table as the gene identifiers, and those were Ensembl IDs with version numbers appended. The MSigDB gene sets use clean Ensembl IDs without versions, so every single match failed silently. I stripped the version numbers with sub("\\.[0-9]+$", "", names(rankedList)) and the analysis completed correctly on the second attempt. This is probably the most common mistake I see, and it is not obvious because the function does not throw an error when matches are zero.
Get the Full Details

Advanced Nuances That Beginner Tutorials Skip
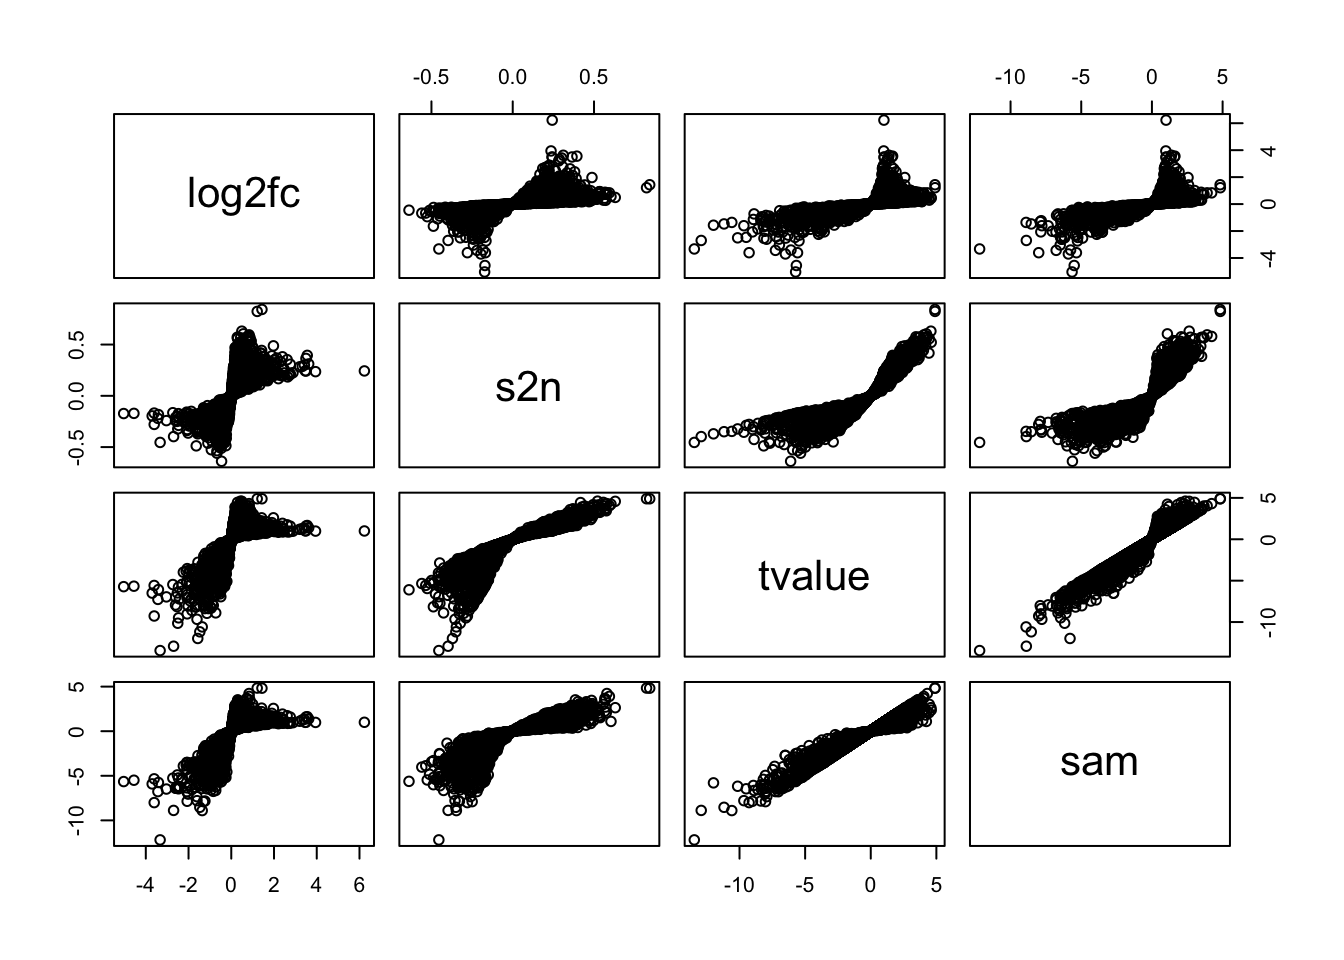
The ranked list metric matters more than most people realize. Using a simple t-statistic or log2FC alone can bias results toward highly variable genes rather than biologically relevant ones. A signal-to-noise ratio or a Wald statistic from DESeq2/edgeR gives you a more balanced ranking. I usually compute the rank vector from the DESeq2 results directly using the stats column, which captures both effect size and dispersion. Another counter-intuitive point: the enrichment score is not inherently directional in the way people expect. A positive NES means the gene set is enriched at the top of the ranked list, but that top could be upregulated or downregulated depending on how you ordered the vector. If you reverse the sign convention mid-analysis, your entire interpretation flips and nobody notices until you are writing the figure legends. Always verify the ordering direction by checking a known positive control gene set before you trust the output. There is also the issue of gene set size filtering. Very small sets (fewer than 15 genes) and very large sets (more than 500 genes) produce unstable enrichment scores. fgsea lets you filter these with the minSize and maxSize arguments, and you should use them. I typically set minSize = 15 and maxSize = 500. Skipping this step floods your results with noise terms that look interesting but fail replication.
Limitations and When to Walk Away
GSEA assumes that gene sets are independent and non-overlapping to some degree, but MSigDB collections are heavily interconnected. A single differentially expressed gene can contribute to dozens of significant pathways, making it hard to tell whether you are seeing distinct biology or just correlated annotations. This is not a flaw in the method, but it is a real interpretive problem that no p-value adjustment fully resolves. The method also struggles with subtle but coordinated changes across a gene set. If most genes in a pathway shift slightly rather than a few genes shifting a lot, the enrichment signal weakens considerably. In those cases, alternatives like camera or roast from the limma package can be more sensitive because they model inter-gene correlation explicitly. I recommend running GSEA alongside a limma-based method when your effect sizes are modest, and then comparing the overlap manually rather than picking one and discarding the other. Runtime is another practical constraint if you are doing single-sample GSEA on hundreds of samples. ssGSEA via the GSVA package is an option, but it transforms the expression matrix into enrichment scores per sample, which requires choosing a kernel bandwidth parameter and can introduce batch effects if your samples were processed in separate runs. There is no one-size-fits-all setting here.
Package Sources and Installation
clusterProfiler is on Bioconductor. Install it with BiocManager::install("clusterProfiler"). fgsea is available on CRAN, so a standard install.packages("fgsea") works. For MSigDB gene sets, the msigdbr package is the easiest route and downloads human, mouse, and Drosophila collections directly into R without manual file handling. It caches the data after the first download, which takes about two minutes on a normal broadband connection. If you prefer the original Broad Institute GSEA software instead of an R-based pipeline, the Java application is still the reference implementation, but it requires downloading gene set files separately, writing your own input files in the correct format, and managing permutations through a graphical interface. The R workflow is faster for iterative analysis once you get past the initial setup friction. The most important practical tip is to save the ranked list and the gene set object before running fgsea. If your session crashes or the permutation count is insufficient and you need to rerun with more permutations, having the inputs cached saves you from recomputing the differential expression step, which can take 20 minutes to an hour depending on your dataset size and whether you are using DESeq2 or limma-voom.