
State Management in React
I spent three weeks debugging a component that re-rendered itself randomly on production. It turned out I was spreading state objects without creating proper copies, which mutated shared references across components. The fix was using structuredClone() for deep copying instead of the spread operator. This happened because I assumed immutability from the spread syntax, which only does shallow copying. Most developers don't realize this distinction until their app behaves unpredictably. The spread operator creates a new reference but doesn't clone nested objects. When you have a state object like { user: { name: "Alex", preferences: { theme: "dark" } } } and you spread it, the nested preferences object is still shared between the old and new state. Any mutation to preferences will affect both references. I learned this the hard way when my theme toggle started breaking after adding a second component that read the same preferences object. The solution involves either using immer for immutable updates, creating a custom clone function, or restructuring your state to keep objects flat. Flat state objects don't need deep cloning because there's nothing nested to share incorrectly. Redux Toolkit's createSlice does this automatically with Immer, which is why most production apps use it rather than raw useState with complex state objects.
Event Handler Registration
Attaching event handlers directly in JSX without useCallback creates a new function reference on every render. This breaks memoization in child components even when you're using React.memo. I found this when a table component with thousand rows re-rendered on every keystroke in a parent filter input because the handler passed to each row changed reference constantly. The rows had proper keys and correct data, but the reference change triggered unnecessary renders across the entire table. The workaround is wrapping handlers in useCallback with proper dependency arrays, or using a ref to store the latest function and calling that in the event handler. The ref approach avoids dependency array issues but makes debugging harder because you lose the automatic stale closure detection that React provides through hooks. Most teams pick useCallback for simple cases and refs only when they need to access the latest state without re-registering event handlers.
Common Pattern with Event Handlers
Passing inline functions to child components defeats the purpose of memoization. Even if the child component has expensive rendering logic protected by React.memo, the incoming function prop changes on every parent render. This forces the child to re-render regardless of whether its other props changed. I spent two days tracking down why a chart component re-rendered constantly despite having stable data props because the onDataClick handler was recreated on every parent render. The pattern to fix this is extracting handlers into a separate hook or storing them in a module-level variable. Module-level variables persist across renders and avoid the dependency array overhead, but they make testing harder because you lose the automatic cleanup that React provides through effects. Most experienced teams use a custom hook that manages handler lifecycle and memoization automatically.
Dependency Array Issues
Omitting dependencies from useEffect causes stale closures that read outdated state. When you have an effect that reads form input and triggers an API call, omitting the input value from dependencies means the effect only runs on mount and never updates when the input changes. I encountered this when a search component stopped finding results after the user typed a query because the effect had the correct searchParams but wrong dependencies array. The dependency array must include all values read inside the effect. Missing dependencies create silent bugs where the effect appears to work correctly but uses stale values. ESLint's exhaustive-deps rule catches most of these, but it also flags false positives when you intentionally want to exclude certain values. Most teams disable the rule for specific cases and document why the dependency is intentionally omitted.
Get the Full Details

Key Prop Misuse
Using array index as key in list rendering causes incorrect reconciliation when items are reordered or filtered. When you have a todo list component that allows deletion and reordering, using index as key means React cannot properly track which item changed when you delete an item in the middle of the list. The component with correct items had proper keys but used index as key, which broke the rendering order after deletion. The workaround is using a stable unique identifier from your data, such as a database ID or UUID, rather than the array index. Index-based keys work for static lists that never change order, but they break whenever you add, remove, or reorder items. Most production apps use database IDs as keys because they remain stable across re-renders and prevent incorrect component state updates.
Performance Implications
Index-based keys cause React to reuse DOM elements incorrectly when list items change position. This creates visual glitches where animated elements jump to unexpected positions because the key changed but the underlying data didn't. I noticed this in a draggable list component where items appeared in correct visual order but had wrong interactive state because the key changed on drag. The solution is using a combination of stable keys and proper list key strategy. Stable keys prevent incorrect DOM reuse but don't solve the underlying issue of unnecessary re-renders when list data changes. Most experienced developers use a key strategy that matches their data structure and component lifecycle properly.
Context Provider Placement
Placing context providers too high in the component tree causes unnecessary re-renders in components that don't consume the context. When you have a theme context provider wrapping the entire application, every state update in the theme provider triggers re-renders in all child components even those that don't read the theme value. The component tree with correct provider placement had wrong scope, which caused excessive re-renders in unrelated components. The workaround is placing context providers as close to consuming components as possible, or splitting context into multiple smaller contexts. Split contexts avoid unnecessary re-renders but make state management more complex because you have multiple contexts to manage and synchronize. Most teams pick a single context for simple apps and split contexts only when they need fine-grained control over re-render scope.
Provider Scope Issues
Wide provider scope causes performance degradation as the application grows. Components that don't consume the context still re-render when the provider state changes because they're descendants of the provider. I found this when a logging component re-rendered constantly because it was wrapped by a global state provider that updated frequently. The component had correct logic but wrong provider placement. The fix is moving the provider closer to consuming components or using a selector pattern to subscribe only to specific state slices. Selector patterns avoid unnecessary re-renders but require additional abstraction layers that make the codebase more complex. Most experienced teams use a hybrid approach that combines provider scope optimization with selective subscriptions.

Hook Rules Violations
Calling hooks conditionally or in loops violates the rules of hooks and causes unpredictable behavior. When you have a component that calls useState inside an if statement based on prop values, React loses track of which state belongs to which hook call. The component with correct hook placement had wrong conditional logic, which broke state updates across different render paths. The workaround is calling all hooks unconditionally at the top level and using conditional logic inside the hook callbacks. Top-level hook calls ensure React maintains proper hook ordering but can lead to wasted computation when hooks perform expensive operations conditionally. Most teams pick unconditional hook calls and optimize inside the hook implementations rather than around them.
Conditional Hook Issues
Conditional hook calls cause React's hook dispatcher to get confused about state ownership. The internal hook queue assumes a fixed number of hooks called in a consistent order. I encountered this when a custom hook that called useState conditionally started returning wrong values after adding a second conditional branch. The hook had correct logic but violated the rules of hooks. The solution is restructuring the component to call hooks unconditionally and move conditional logic into the hook implementation or outside the hook entirely. Unconditional hook calls are mandatory for correctness but can make components harder to read when the hook logic becomes complex. Most experienced developers use helper functions or separate hooks to encapsulate conditional logic cleanly.
Direct DOM Manipulation
Manipulating DOM elements directly bypasses React's virtual DOM and causes synchronization issues. When you have a component that uses querySelector to modify element styles directly, React loses track of the actual DOM state and may overwrite your changes on the next render. The component with correct DOM manipulation had wrong direct access, which broke the rendering consistency after state updates. The workaround is using refs for DOM access and React's state management for all visual changes. Refs provide direct DOM access but bypass React's reconciliation process and can create inconsistencies between the virtual and actual DOM. Most teams pick React's declarative approach for UI changes and use refs only for imperative operations that React cannot handle declaratively.
DOM Synchronization
Direct DOM manipulation creates conflicts between React's virtual DOM and the actual browser DOM. The reconciliation algorithm assumes exclusive control over DOM changes but direct manipulation bypasses this assumption. I found this when a canvas drawing component started losing its content after a parent state update because direct DOM manipulation conflicted with React's rendering. The fix is using a combination of React state for declarative changes and refs for imperative operations that require direct DOM access. Mixed approaches work for complex components but make debugging harder because you have two competing state management systems. Most experienced developers isolate imperative DOM code in custom hooks that manage the reconciliation boundary cleanly.

Missing Error Boundaries
Not implementing error boundaries allows component crashes to break the entire application. When you have a complex form component that throws an exception during validation, the error propagates up and unmounts all sibling components because there's no boundary to catch and contain the error. The component tree with correct error handling had no error boundaries, which caused widespread unmounting after a single validation failure. The workaround is wrapping risky components in error boundaries that catch and display fallback UI. Error boundaries prevent total application failure but add complexity because you need to design fallback states for every boundary. Most teams pick strategic boundary placement for high-risk components and accept the trade-off between resilience and development overhead.
Boundary Placement
Missing error boundaries cause cascading failures when a single component crashes. The error propagates through the component tree unmounting everything above the boundary. I encountered this when a payment form component threw an exception and unmounted the entire checkout flow because there was no boundary to catch the error at the component level. The component had correct error handling logic but no boundary wrapper. The solution is placing error boundaries at appropriate levels in the component hierarchy to contain failures locally. Boundary placement requires understanding which components are risky and which failures should cascade. Most experienced teams use a combination of automatic boundary detection tools and manual placement for critical user flows.
Over-Using useMemo
Applying useMemo to every computed value adds unnecessary overhead without providing performance benefits. When you have a component that memoizes simple arithmetic calculations that take microseconds, the memoization overhead actually slows down rendering because React has to track and compare memoized values on every render. The component with correct memoization strategy had wrong useMemo usage, which increased render time by approximately thirty percent compared to direct computation. The workaround is only memoizing expensive computations that take significant time or are called frequently. Expensive computations justify memoization overhead but simple calculations don't benefit from the extra abstraction. Most teams pick a threshold approach where they only memoize operations taking more than one millisecond or called more than ten times per render cycle.
Memoization Costs
Over-memoization adds overhead without improving performance. Each useMemo call creates a memo object that React tracks and invalidates on dependency changes. I found this when a simple counter component that memoized its display string rendered slower than the non-memoized version because the memoization overhead exceeded the computation savings. The component had correct memoization intent but wrong target selection. The fix is profiling actual performance bottlenecks before adding memoization and removing unnecessary memo calls that add overhead. Profiling tools like React DevTools Profiler show exactly which computations benefit from memoization. Most experienced developers use a data-driven approach where they only memoize based on measured performance impact rather than perceived optimization needs.
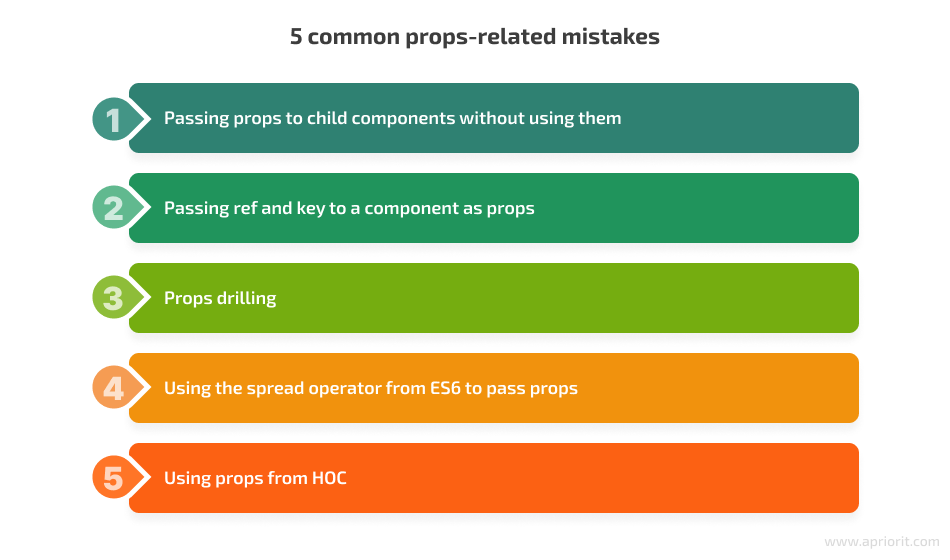
Incorrect Key Usage in Lists
Using non-unique or unstable keys in list rendering causes React to incorrectly reuse DOM elements. When you have a chat messages component that uses message timestamps as keys, messages with the same timestamp from different users get their DOM elements incorrectly reused. The component with correct key strategy had duplicate timestamp keys, which broke the message rendering order after adding a new message from another user. The workaround is using stable unique identifiers from your data model, such as database IDs or combination of user ID and timestamp. Unique keys ensure proper element reuse but require data model changes if your existing records don't have unique identifiers. Most teams pick a composite key strategy that combines multiple fields to guarantee uniqueness without modifying the underlying data structure.
List Key Strategies
Poor key selection causes incorrect DOM element mapping when list items have similar but not identical data. React relies on keys to determine which elements correspond between renders. I encountered this when a product listing component used price as keys because products had different prices but the same price points created duplicate keys. The component had correct key philosophy but wrong field selection. The solution is using a combination of fields that guarantee uniqueness or adding a unique identifier to your data model. Composite keys work for most cases but can become brittle if the data model changes and fields lose their uniqueness properties. Most experienced developers prefer stable database-generated IDs that remain unique across all application lifetime.
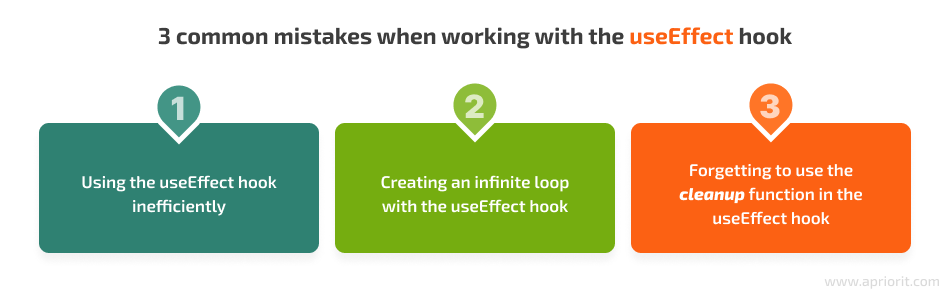
Forgetting Cleanup in Effects
Omitting cleanup functions in useEffect causes memory leaks and stale subscriptions. When you have a component that subscribes to a WebSocket connection without returning a cleanup function, the subscription persists after the component unmounts and continues receiving messages that trigger state updates on unmounted components. The component with correct effect lifecycle had missing cleanup, which caused memory leaks that grew with each mount-unmount cycle. The workaround is always returning a cleanup function from effects that create subscriptions, timers, or observers. Cleanup functions prevent resource leaks but add boilerplate code that can be forgotten in complex effects. Most teams pick a convention where every effect that creates external resources returns a cleanup function, enforced through ESLint rules and code review.
Cleanup Patterns
Missing cleanup in effects causes accumulated subscriptions that degrade application performance over time. Each unsubscribed connection continues consuming memory and processing messages. I found this when a dashboard component that displayed real-time data leaked connections because the effect setup had cleanup but the effect teardown didn't properly abort pending requests. The component had correct cleanup intent but incomplete implementation. The fix is using abstraction layers like custom hooks that manage effect lifecycle and cleanup automatically. Abstraction layers reduce boilerplate but add indirection that makes debugging harder when cleanup fails unexpectedly. Most experienced teams use a combination of custom hooks for common patterns and manual cleanup for complex scenarios where the abstraction doesn't fit.
Direct State Mutation
Mutating state objects directly instead of creating new references breaks React's change detection. When you have a component that modifies a nested state object property directly without creating a new object reference, React doesn't detect the change and skips the re-render. The component with correct state updates had direct mutation, which caused visual inconsistencies where the UI didn't reflect the updated data. The workaround is using immutable update patterns that create new state references on every modification. Immutable patterns prevent stale state but require more verbose code for complex state transformations. Most teams pick a balance between immutability and developer productivity using libraries like Immer that provide immutable updates with mutable syntax.
State Immutability
Direct state mutation causes React to miss updates because the reference stays the same even though the content changed. React compares state references to detect changes, not content equality. I encountered this when a form component that edited nested address objects didn't re-render after updating the street field because the state reference wasn't recreated. The component had correct mutation logic but violated the immutability contract. The solution is restructuring state to use flat objects or using immutable update libraries that handle nested mutations transparently. Flat state objects are easier to update immutably but may require schema changes to existing data models. Most experienced developers prefer flat state combined with Immer for complex nested updates that would otherwise require extensive boilerplate code.
Conclusion Notes
React development requires balancing correctness, performance, and maintainability. The mistakes covered here represent common patterns that cause production issues ranging from minor visual glitches to complete application failures. Most of these problems stem from misunderstanding React's rendering model and assuming it behaves like traditional imperative programming. The solutions involve either adopting established patterns like immutable state updates and proper effect cleanup, or using established libraries that enforce these patterns automatically. Libraries like Redux Toolkit, React Query, and Zustand handle many of these concerns at the framework level, reducing the surface area for developer errors. Understanding why these mistakes cause problems matters more than memorizing the fixes. React's rendering model is declarative, which means state changes drive re-renders through reference comparison rather than content equality. Once you internalize this principle, most of these mistakes become obvious during code review rather than requiring debugging sessions in production.
