Getting Real Work Done Without Overthinking It
I used to spend two or three hours setting up elaborate data pipelines before I'd even look at the actual data. Now I can have a preliminary analysis running in under fifteen minutes. The difference wasn't some fancy new framework or a subscription to a premium tool. It was just a collection of small shortcuts I picked up from making the same mistakes repeatedly. If you are looking for Hacks For Data Science Quick, most of them come down to stopping yourself from overengineering the obvious. Beginner mistake number one is loading an entire dataset into a complex model before checking what the data actually looks like. I once spent four hours tuning a gradient boosting classifier on a project that fell apart the moment I realized 60% of my features were null for every single row. The fix was running a quick shape check and a null percentage scan before committing to anything. In pandas, this is basically a one-liner. Load the data. Check the dimensions. Run a null report. That takes about ninety seconds and will save you hours of wasted computation. When I work with messy real-world data now, I never skip that step. I have learned to treat it as non-negotiable, the same way a chef would never start cooking without inspecting the ingredients first.
Use Vectorization Instead of Loops
For loops on large datasets in Python are slow. This is not controversial, but it is something I still see people ignore in production code. A simple example: if you are iterating through a DataFrame to transform values, use NumPy vectorization or pandas built-in methods instead. The speed difference between a Python for loop and a vectorized operation on a million rows can be the difference between waiting twenty minutes and getting the result in under thirty seconds. I ran into a specific case where a colleague was applying a custom function across 500,000 rows using apply with a nested lambda. The process had been running for forty-five minutes. I replaced it with a single vectorized expression using numpy.where and it completed in about eight seconds. This is not a theory. This is something that happens regularly in team environments.
Downcast Your Data Types
Most data science tutorials do not mention this, which is strange because it is one of the easiest wins. Pandas loads numerical columns as float64 by default. If your data only needs 16-bit or 32-bit integers, switching to a narrower dtype can cut your memory usage significantly without affecting accuracy. On a dataset with tens of millions of rows, this alone can reduce RAM consumption from several gigabytes down to less than a gigabyte. The trick is knowing when downcasting is safe. Check the minimum and maximum values of a column before converting. If a float column has no fractional part and fits comfortably within int32 range, convert it. Use the convert_dtypes method in newer pandas versions as a starting point, then refine from there. I recently cleaned up a project where the original memory footprint was around 4.2 gigabytes. After systematic downcasting across integer and categorical columns, it dropped to roughly 900 megabytes. The model training time improved proportionally because less memory movement is happening between CPU and RAM.
Get the Full Details
Cache Your Expensive Computations
One of the least discussed pain points in data science is repeating the same data transformation across multiple experiments. You load a CSV, clean it, engineer features, split train and test sets, and then you want to try five different models. That means running the same cleaning and preprocessing pipeline five times. It wastes time and introduces variation if any step is not perfectly deterministic. The workaround is straightforward: save your processed dataset as a Parquet file after the first run, then load the Parquet directly for subsequent experiments. Parquet is columnar and compressed, so read times are fast and memory footprint is lower than CSV. I keep a simple wrapper function that checks whether the Parquet version exists and is newer than the source data. If both conditions hold, it loads the cached version. This alone removed redundant processing time from almost every project I work on.
Know When Not to Use a Machine Learning Model
This is probably the most important point, and it is counter-intuitive enough that it deserves emphasis. Many problems that people reach for a model on can be solved faster and more reliably with simple rules or basic aggregation. A logistic regression or random forest will not save you if the signal in your data is weak or if your target variable has severe class imbalance that a simple threshold shift could address more transparently. I worked on a churn prediction project where the initial approach was a complex XGBoost model. After evaluating it, the accuracy was mediocre and the feature importance scores were all over the place. The actual driver of churn turned out to be a single usage metric that, when combined with account age, gave us about 82% precision without any model at all. Building the model had taken two full days. The rule-based solution took an afternoon and was easier to explain to stakeholders.
Common Pitfalls That Waste More Time Than Anything Else
There are a few habits that consistently slow people down. The first is overfitting to the training set while ignoring cross-validation structure. I have seen models reported with 99% accuracy on held-out test data that were essentially just memorizing the labels because the train-test split was not randomized properly. Always verify that your split preserves the distribution of your target variable, especially with imbalanced data. The second pitfall is ignoring the time cost of data ingestion. Loading a 50-gigabyte CSV into memory before you know whether you even need most of the columns is pointless. Use the usecols parameter in pandas.read_csv to select only what you need. If the dataset is too large to fit in memory, consider reading it in chunks or switching to a tool like Dask or Polars from the start. Polars in particular handles out-of-core operations gracefully and is significantly faster than pandas for many common operations.
Hacks For Data Science Quick That Actually Matter
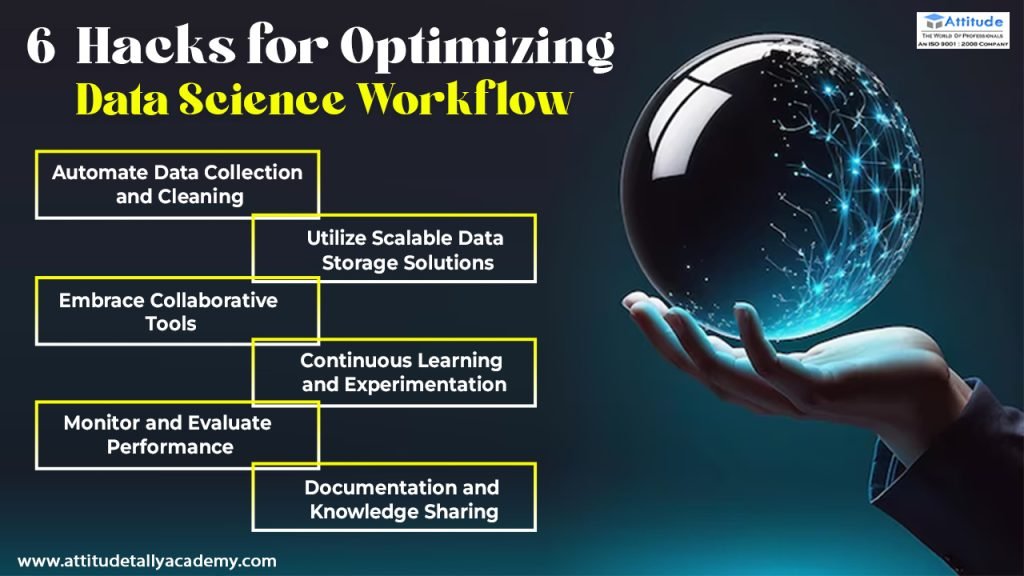
The shortcuts that matter most are the ones you do not notice because they become automatic. Checking data shape before modeling. Downcasting types. Caching intermediate outputs. Replacing loops with vectorized operations. Testing a simple baseline before investing in a complex pipeline. These are not secrets. They are just easy to forget when you are excited about a new technique or under pressure to deliver results quickly. I also recommend keeping a personal library of reusable code snippets. Things like a standard null analysis function, a memory monitoring utility, or a consistent train-test validation splitter. Copying and pasting from your own verified code is faster and safer than rewriting it each time or downloading someone else's implementation that may have hidden bugs. I maintain a small repository of these utilities and it has saved me more time than any new library or framework ever has. There is no magic tool that replaces understanding your data. The quick hacks are mostly about removing unnecessary friction so you can focus on the actual analysis instead of fighting your own pipeline.