So You Need to Get Through Sociology Faster
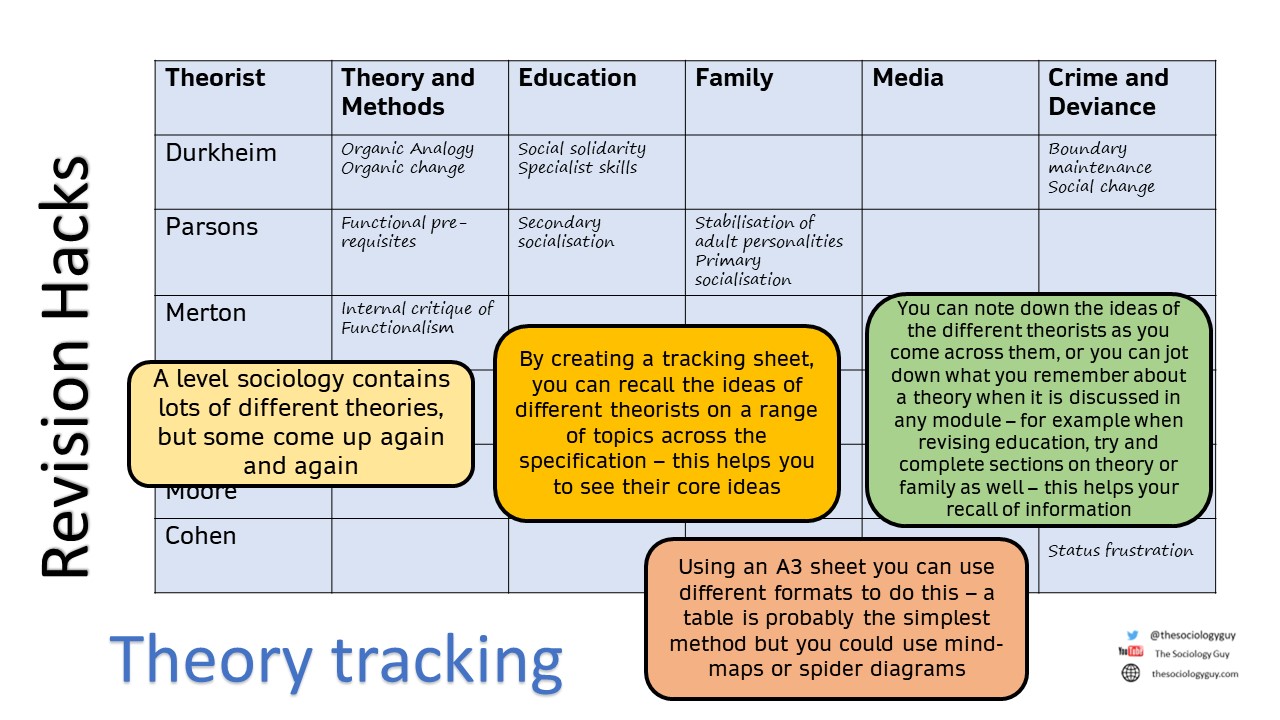
I spent way too long in grad school figuring out that the standard approach to reading papers and writing papers was designed for people who had no deadlines. There are actual ways to compress the timeline. Most students just don't know them because nobody in their program teaches them. The material below covers what I actually used during my dissertation and through years of teaching undergrad methods courses. Let me start with something that sounds simple but costs most people three weeks they don't have. When you're doing a literature review, stop reading every paper from start to finish. It's not how research actually works and pretending otherwise is how people drown in PDFs. Read the abstract, then the first paragraph of the discussion, then the conclusion. If the paper is relevant after those three sections, go back and read the methods. This cuts your reading time from roughly 45 minutes per paper to about 12 minutes. The papers you skip this way tend to be either irrelevant or poorly written anyway, so you're filtering twice. I ran into a specific problem last year when a student was trying to synthesize 80 papers on social capital for a thesis chapter. She was reading them cover to cover and hadn't written a single paragraph after four weeks. I told her to switch to the abstract-discussion-conclusion skim and tag each paper with one of three labels: core, supporting, or discard. She finished the chapter in nine days. That's not a guarantee for everyone, but it's the pattern I see when people stop treating every source like it requires the same level of attention.
Here's something most people get wrong about qualitative data analysis. You don't need to code every single transcript before you can start writing. That's a bottleneck that adds weeks to a project with zero analytical benefit. Open your second interview, read through it, and start making notes about patterns you're seeing. Write those observations down in real time. By the time you finish your eighth interview, you'll have a rough thematic structure that you can refine while you keep collecting data. This is how grounded theory actually works in practice, even though the textbooks make it sound like you need to do all the coding first. The real problem with this approach is that you might miss subtleties in the early interviews because you're already forming hypotheses. I dealt with this on my own ethnography work by keeping a separate running log where I wrote down things that didn't fit my emerging themes instead of ignoring them. Those disconfirming cases ended up being the most important part of my analysis. If you're working with large survey datasets, use Python or R from the start rather than waiting until after you've cleaned everything in SPSS. Setting up a quick script to handle recoding, missing value detection, and basic descriptives takes about 20 minutes once you know the syntax and saves you at least a few hours of manual clicking. I've seen people spend two days cleaning a dataset in SPSS that a five-minute pandas script could have handled. The learning curve is real if you've never coded, but basic syntax is straightforward and there are templates online for standard sociology data projects. Don't let the learning curve scare you away. The alternative is spending entire weekends on tasks that should take an hour.
When it comes to writing literature reviews specifically, the reverse outline method is worth using. Finish your first draft without worrying about flow or transitions, then take a highlighter and mark the main claim of each paragraph in a different color. If two adjacent paragraphs are highlighting the same color, merge them or delete one. If a section has no highlight at all, rewrite it or cut it. This catches the most common problem in student papers: paragraphs that are technically accurate but don't actually advance an argument. A lit review should be making a case, not listing summaries. Statistical methods get a reputation for being impossibly difficult, but a lot of what sociology grad programs teach as essential is unnecessary for most projects. Logistic regression, OLS, and basic chi-square tests will cover maybe 70 percent of undergraduate and early graduate work. Everything else—multilevel modeling, structural equation modeling, event history analysis—is useful but not required until you're working on specific questions that demand it. Learn to do the basics well. A cleanly specified OLS regression with proper diagnostics is more valuable than a half-understood SEM model that you can't defend. There's a real tradeoff here though. If your research question involves hierarchical data like students nested in schools or respondents nested in neighborhoods, skipping multilevel models will produce biased standard errors. The bias is usually small in well-designed studies but it compounds quickly in messy real-world data. Know your research design before you decide what methods to invest time in learning.
Get the Full Details
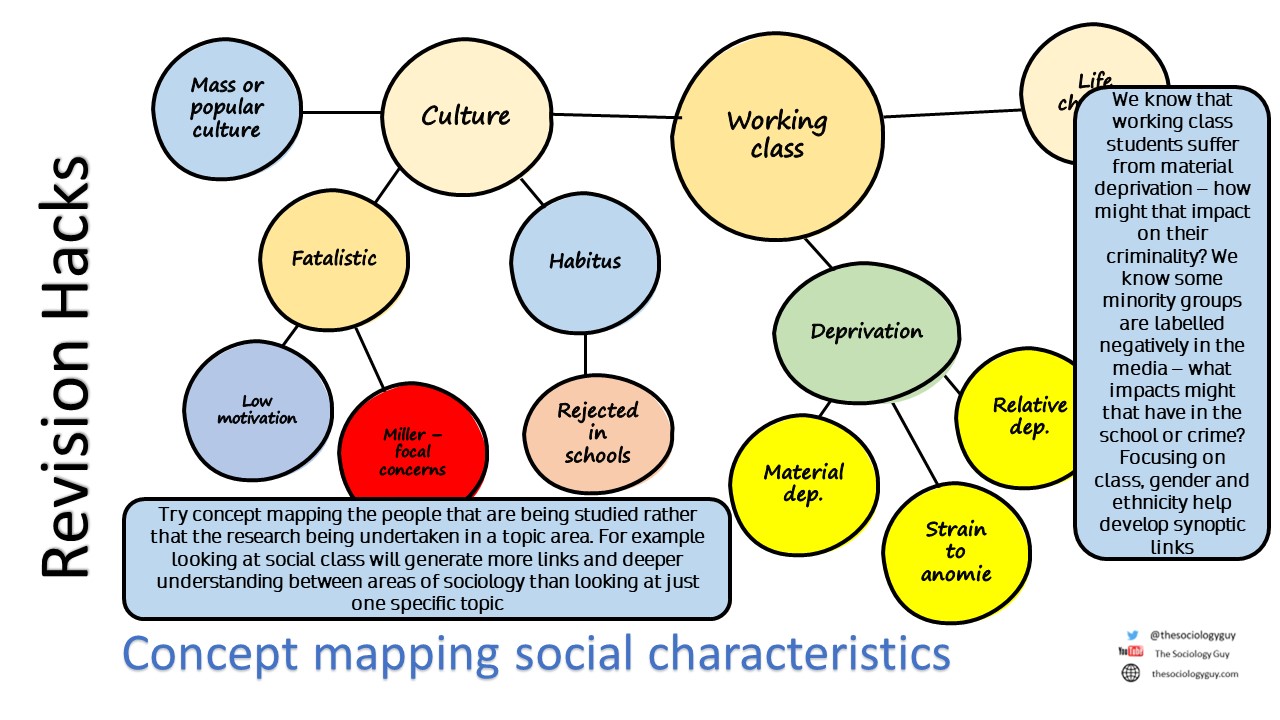
For note management, stop using different apps for different purposes. One system handles everything. I use a single note-taking app where every paper gets one entry containing the citation, a three-bullet summary, and a tag for the theme it relates to. That's it. No fancy organization systems, no color codes that take longer to maintain than the notes are worth. The system breaks down if your project involves more than roughly 150 sources, at which point you need something more robust like Zotero with better tagging conventions or a database-driven approach. But for most thesis projects, the simple system works fine and doesn't become a chore. Time estimates matter more than people admit. A standard literature review with 40 sources takes most students about six to eight weeks following the conventional approach. Using the reading shortcut and reverse outline method described here, it typically takes two to three weeks for someone at the master's level. The difference isn't intelligence or effort. It's just doing the parts in the right order. One thing I've noticed that nobody talks about enough: most sociology students underuse secondary data repositories. The GSS, ISSP, WVS, and various national panel studies have cleaned, weighted data that's ready to go. You don't need to collect your own survey data for many research questions. I had a student who spent three months designing and piloting a survey when she could have found the exact variables she needed in the GSS with a two-hour search. IRB approval alone would have taken another month. Use existing data whenever your research question allows it.
There are downsides to relying on existing datasets, obviously. You're constrained to whatever variables other researchers decided to measure, which means your operationalization might not perfectly match your theoretical construct. Response rates on older waves of major surveys are declining, and weighting can't fully correct for nonresponse bias. These issues are manageable if you acknowledge them in your limitations section, but they're easy to overlook when you're rushing to get results. If you want a practical starting point for the coding workflow I mentioned earlier, the havenr package in R or the statsmodels library in Python both have straightforward examples for common sociological analyses. Spend an afternoon working through a tutorial using a sample dataset like the General Social Survey. That's faster than trying to learn from documentation alone, and you'll have a working script you can adapt for your own data. The biggest thing holding people back from working faster is usually perfectionism about their first draft. Write badly first. Your first draft is supposed to be bad. The revision is where the work happens. I've read too many papers by experienced researchers that show signs of multiple revision passes—paragraphs that were clearly rewritten, citations that got moved around, arguments that tightened over successive drafts. None of that shows in the final product, but every minute of that revision time came from allowing myself to write sloppily at first.
Read widely but selectively. You don't need to read everything published in your subfield. Pick three to five key journals and scan the table of contents weekly. When something looks relevant, apply the skim method. When nothing looks relevant, move on. This keeps you current without consuming your entire week. Most people overinvest in staying current and underinvest in actually producing work. There's a difference between speed and rushing. Speed means doing the right things efficiently. Rushing means skipping steps you haven't skipped yet and discovering later that you forgot something important. The hacks I've described above are about efficiency, not shortcuts that create gaps in your analysis. If you apply them thoughtfully, you'll finish faster and your work will hold up to scrutiny just as well as anything produced at the slower pace. The field moves fast enough that learning these techniques early saves you from the panic of realizing halfway through a project that you're working in the most inefficient way possible. I wish someone had told me most of this before I started.