Breaking Down the Actual Process
You start by getting raw footage. Usually between 15 and 30 seconds, sometimes longer if someone does it very carefully. The first thing you need is a shot where the entire hand-washing sequence stays in frame, and the lighting doesn't change mid-action. Then you define the atomic steps before you open any annotation tool. That second part is where most people go wrong. They open the tool and start clicking around, then realize halfway through that their step definitions don't map to what's visible on screen. I learned that the hard way on a project where we annotated over 400 sequences and had to redo the first pass because our original taxonomy grouped "wetting hands" and "applying soap" as one step, even though visually they are completely distinct phases with different temporal markers.
Standard Hand Washing Task Analysis Structure
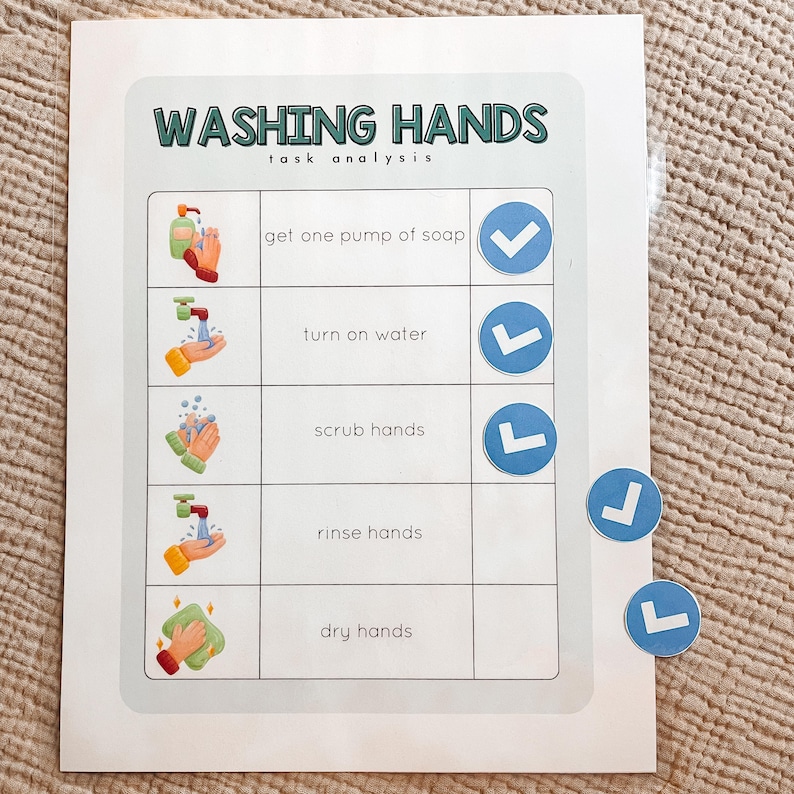
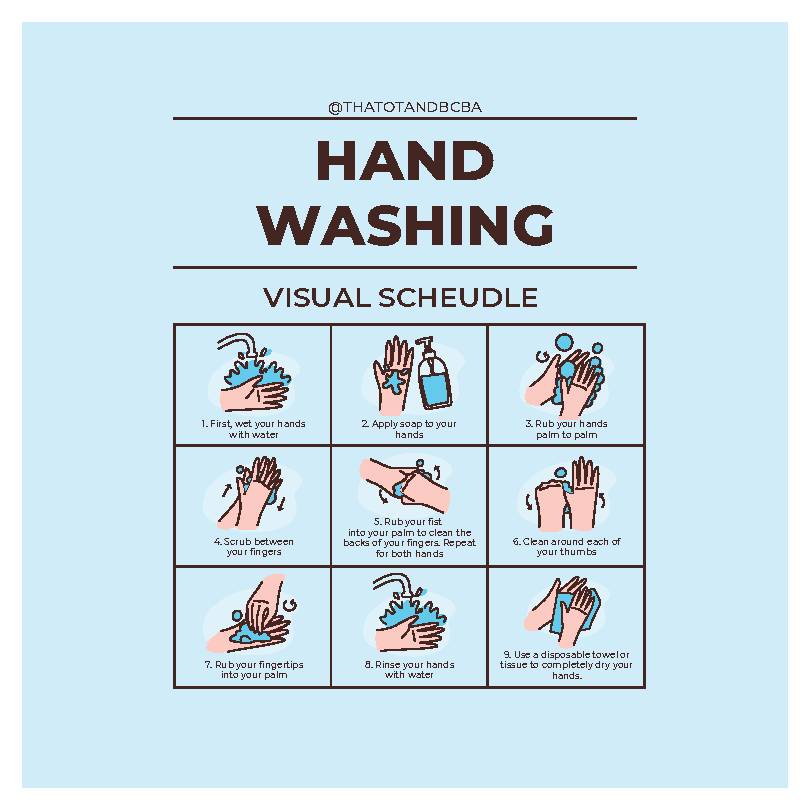
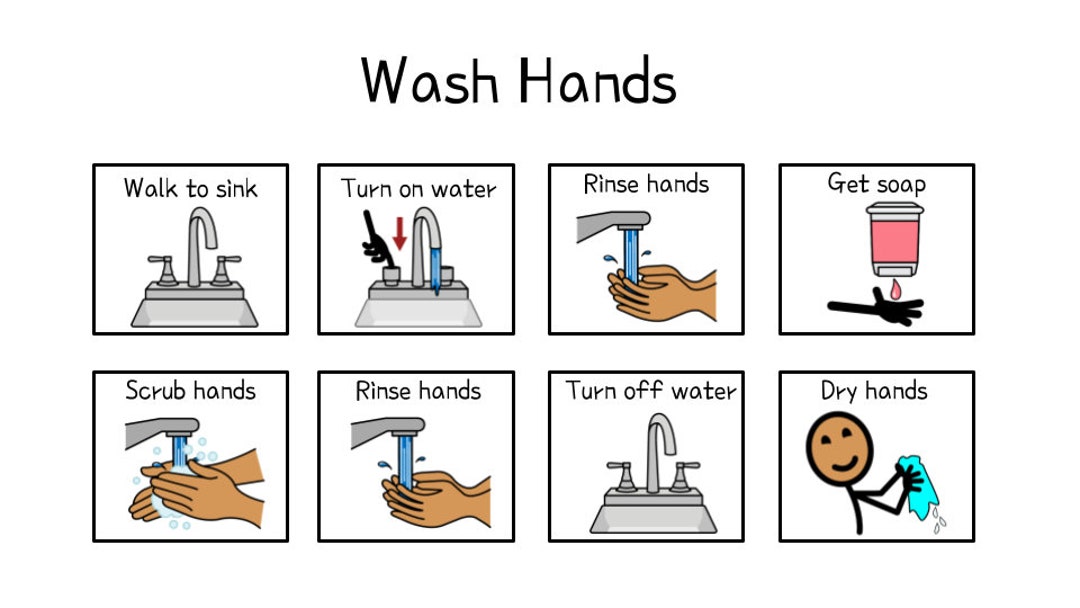
A typical breakdown runs about eight to twelve steps depending on how granular you need to be: Wet hands under running water, apply soap, lather palms, lather back of each hand, interlace fingers, clean thumbs with a rotational grip, scrub fingertips against the opposite palm, rinse thoroughly, dry with a clean towel, and turn off the faucet using the towel. Each step needs a clear start frame and end frame. Not a region. Specific frames. The rub cycles are where things get messy. Some people do twenty full cycles. Some do six. The question you have to answer upfront is whether your analysis tracks the total rub duration as one step or breaks it into sub-cycles. I recommend the former unless you have a very specific research question about rhythm or coverage.
The Annotation Tool and Practical Setup
I use CVAT for most of this work. It handles keyframing well, supports polygon and point annotations, and the CLI export lets me script post-processing without leaving the terminal. Label Studio works fine for smaller projects where you don't need frame-level precision. For anything requiring temporal segmentation down to the second, neither tool does the heavy lifting automatically, so you write a small script that at least pre-splits the video by timestamp so you aren't manually scanning through forty seconds of footage looking for transition points. Set your frame rate first. Most videos land between 24 and 30 fps. If you're working with action recognition models, 15 fps is usually sufficient and cuts your processing time roughly in half. If you're targeting something like gesture detection where finger movement matters, stick with the native frame rate or higher. Here is the actual workflow I follow. Load the video. Define the step hierarchy as a JSON structure before touching the timeline. Annotate in chronological order, starting with the steps that have the clearest temporal boundaries, which is usually wetting and rinsing. The middle steps, the rubbing and lathering, are the ambiguous ones. You come back to those after the clean steps are locked down. It forces your internal clock to anchor to the obvious landmarks first.
Get the Full Details

Where the Process Actually Breaks Down
The most common issue I run into is soap application ambiguity. Does pressing the dispenser count as a separate step? Does rubbing the soap between palms count separately from lathering? Different teams answer this differently, which means you cannot compare results across projects unless the taxonomy is identical. I standardize mine by treating soap application as the moment the soap makes contact with skin, not the moment the dispenser is pressed, and I combine the initial palm rub into the lather step. It is arbitrary, but consistency beats theoretical correctness here. Another edge case that tripped me up on a recent project involved the rinsing phase. We had annotators marking the end of rinsing whenever the water stopped, but in about twelve percent of our clips, people turned the water off before fully rinsing and then went back to it. The result was a noisy label where the rinse step ended prematurely. I added a rule that rinsing must include a continuous water flow segment of at least three seconds after the last soap-contact frame, and if the water turns off before that threshold is met, the sequence gets flagged for manual review. That cut our post-annotation correction rate from roughly eighteen percent down to about four percent.
Counter-Intuitive Things Beginners Miss
Temporal granularity matters more than step count. A model trained on twelve perfectly annotated steps will often underperform a model trained on eight steps with precise frame boundaries. The difference is that the training signal is cleaner. You can always merge adjacent steps later. You cannot create temporal precision out of nothing. The second thing is that the drying step is almost never annotated, even though it is visually distinct and takes five to eight seconds. If your use case involves hand state classification or hygiene compliance detection, leaving drying out introduces a blind spot. I always include it unless the client explicitly says otherwise, and I flag it as optional in the project documentation so people know they can remove it if it is irrelevant to their model. A third nuance: hand size and skin tone affect visibility of certain sub-movements. Interlacing fingers is harder to annotate consistently across darker skin tones if the lighting is flat and overhead. The joint deflections are subtler. I adjust by adding a secondary light source at a forty-five-degree angle during capture, or I fall back to close-up shots for the finger-sequence steps when the wide shot is ambiguous. This is not a post-processing fix. It is a capture-stage decision that saves hours of re-annotation later.
Limitations and When to Stop
This method works well for controlled, studio-quality footage. It degrades quickly with naturalistic recordings where people wash their hands in cars, at outdoor stations, or with partial occlusion. I have seen projects attempt full task analysis on phone-recorded videos and end up with annotation agreement scores below sixty percent, which is essentially random for most downstream tasks. If your source material is uncontrolled, consider switching to a higher-level annotation scheme that labels the overall activity as occurring without breaking it into sub-steps, or use a sampling strategy that only includes clips meeting a minimum quality threshold. There is also the issue of inter-annotator agreement. When I run a fresh round of annotation, Cohen's kappa on frame boundaries typically lands between zero point five and zero point six five for the middle rubbing steps, and above zero point seven for wetting and rinsing. If your agreement drops below zero point five on a step, the step definition is too vague. Redefine it before continuing. Pushing forward with bad definitions just multiplies errors through the dataset. For projects where real-time detection matters more than historical analysis, consider shifting from offline temporal annotation to a rule-based extraction pipeline. You can approximate the key steps using accelerometer or gyroscope data from a wearable, or use optical flow to detect the onset and offset of repetitive rubbing motions. It is less precise but scales to thousands of videos without requiring hours of manual labeling per clip.

The final output you should have after completing a Hand Washing Task Analysis is a structured dataset with step labels, frame ranges, and a short justification file for any ambiguous segments. Without the justification file, someone reviewing the dataset six months later will have no idea why a particular boundary was drawn where it was, and you will spend more time reconstructing decisions than you saved by skipping that step.