Working With Population Genetics Equations
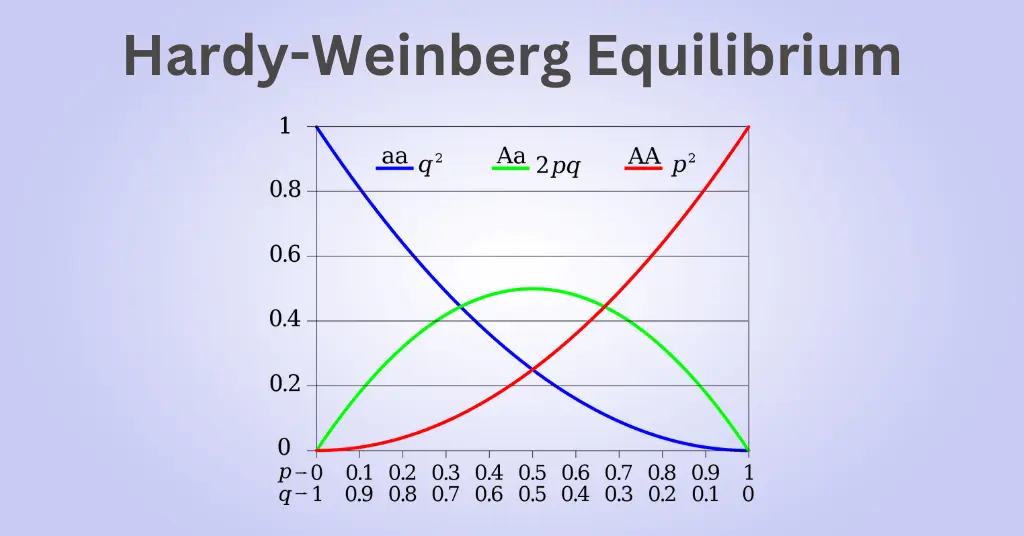
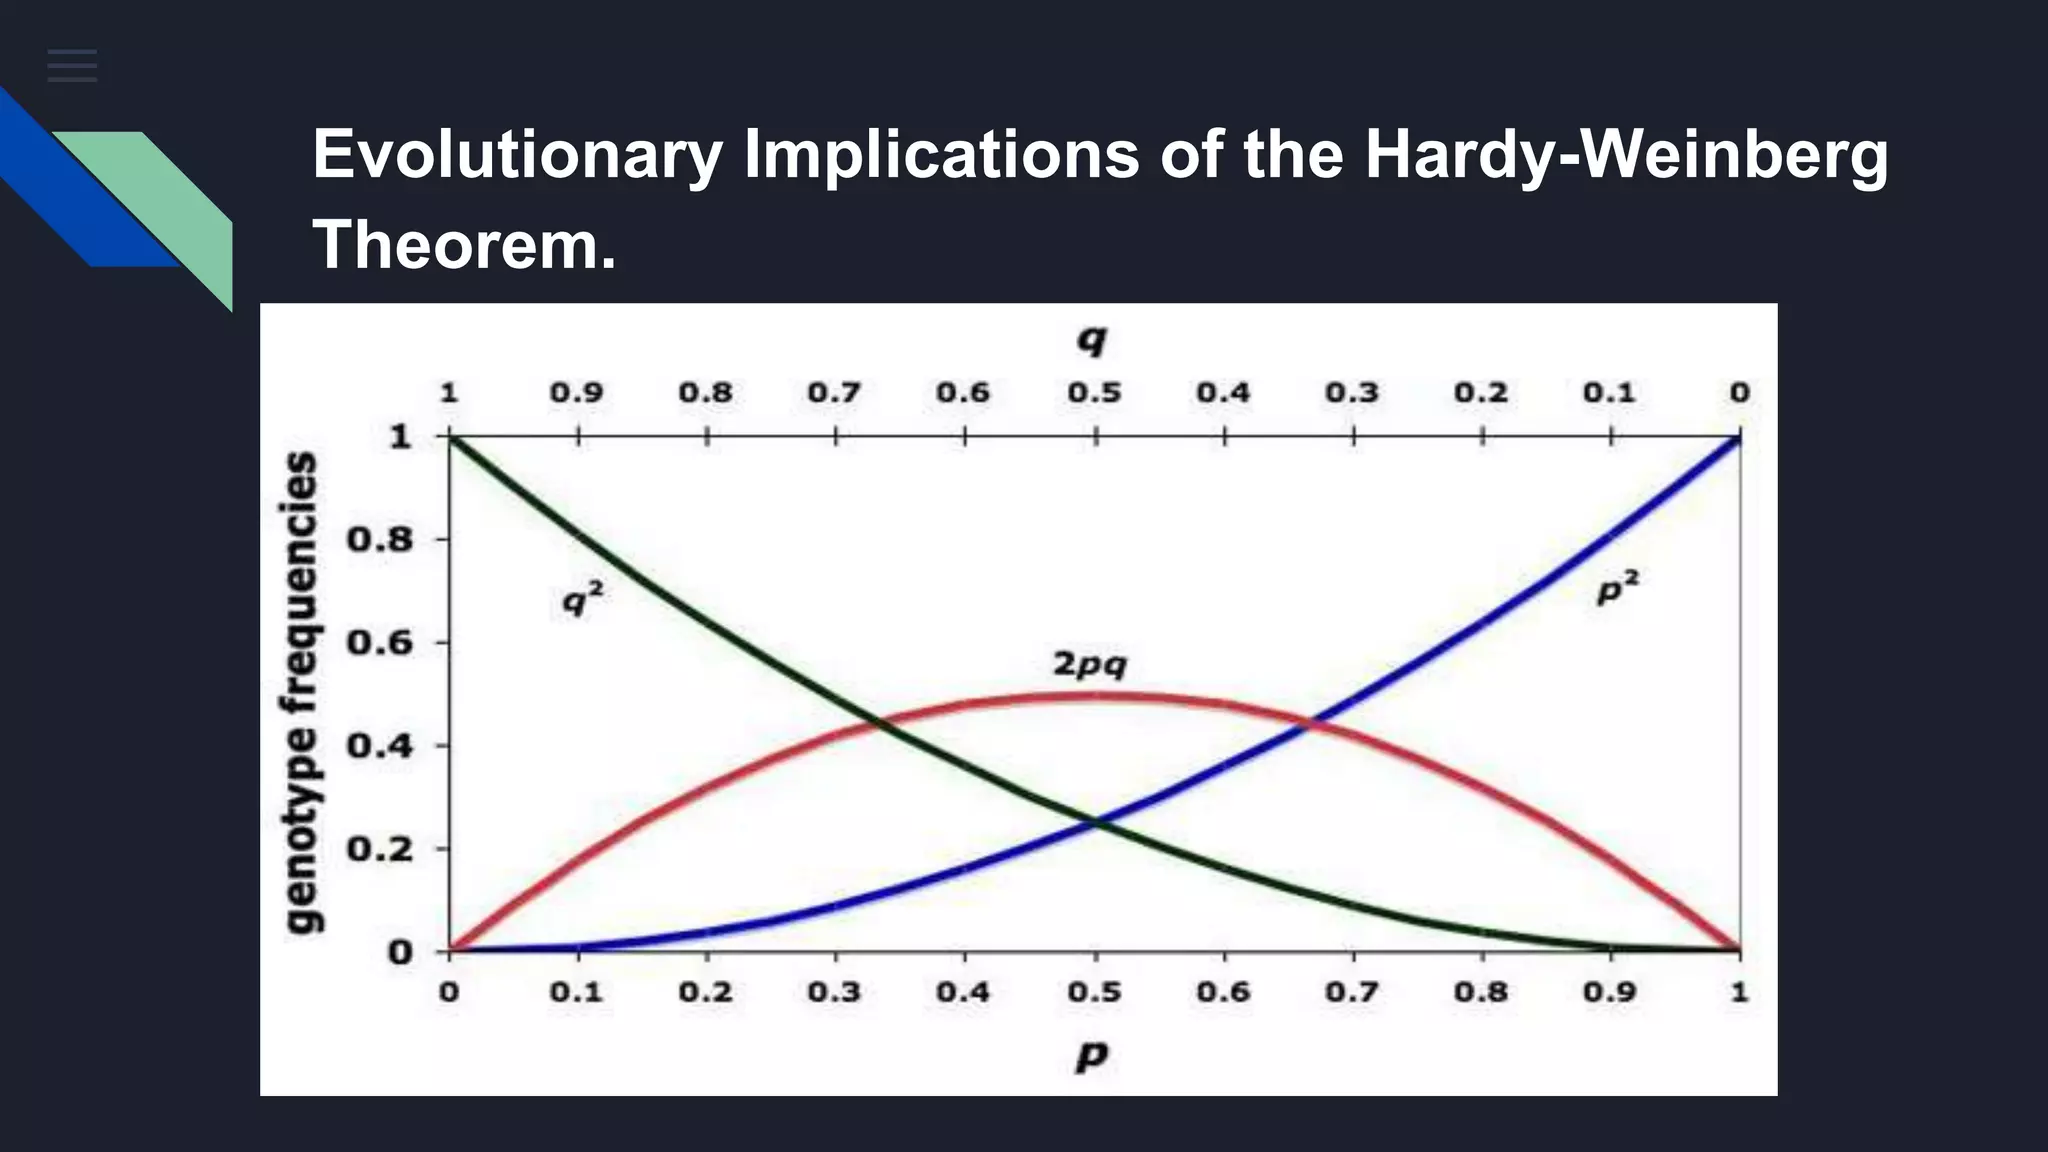
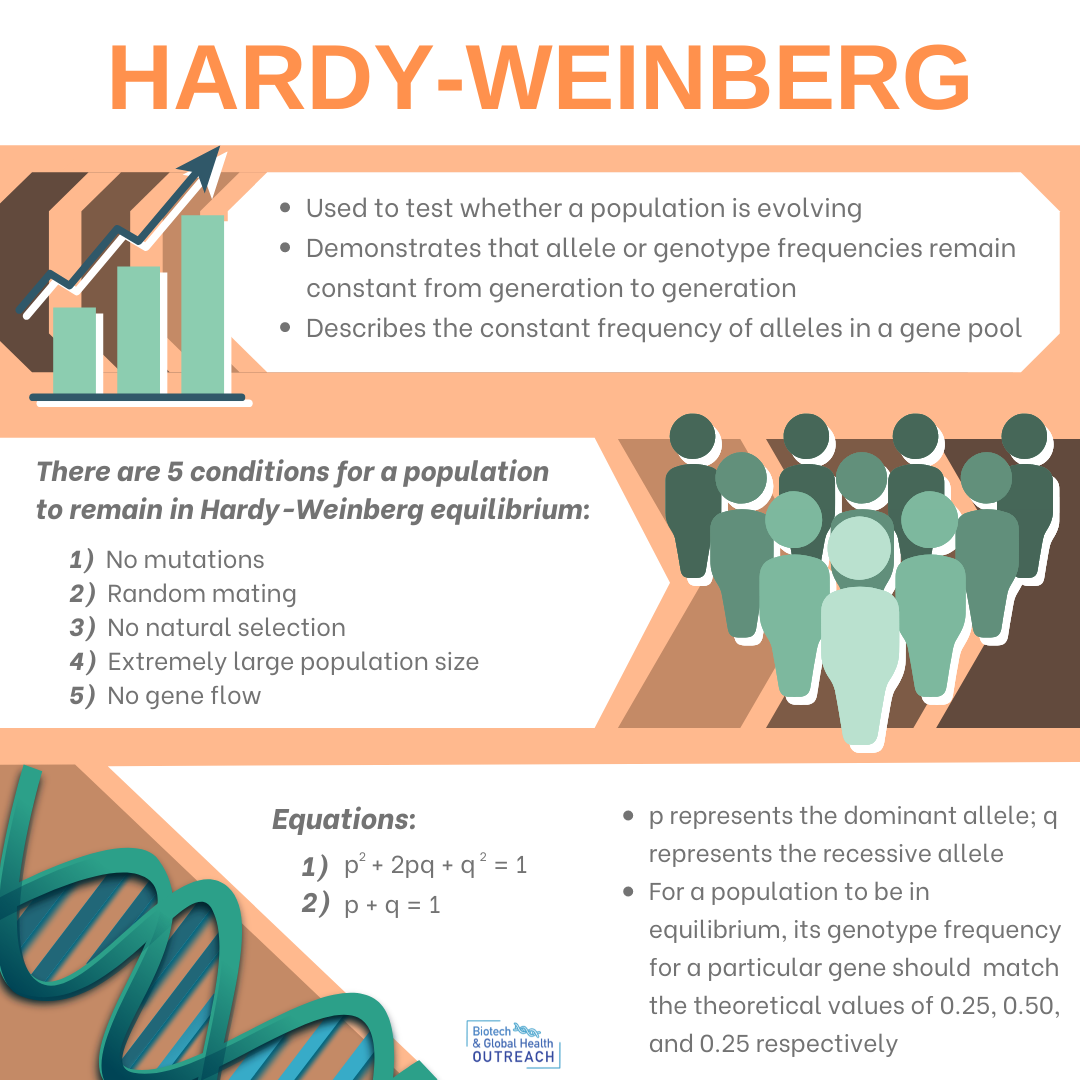
When you first encounter the Hardy And Weinberg Principle, it looks like a clean mathematical shortcut. It isn't. The equations give you a baseline expectation for allele and genotype frequencies, but real populations rarely behave that way. I spent years trying to make these formulas fit field data, and what I learned is more useful than any textbook definition. The core idea is straightforward enough. If you have a locus with two alleles, A and a, where the frequency of A is p and the frequency of a is q, then p + q = 1. The genotype frequencies under equilibrium would be p² for AA, 2pq for Aa, and q² for aa. That's it. That's the whole framework. The principle states that in the absence of evolutionary forces—no selection, no mutation, no migration, no genetic drift, and random mating—these frequencies remain constant across generations.
Getting Started With The Hardy And Weinberg Principle
Here's how I actually approach these calculations. Most people start with genotype counts from a population sample and work backward to allele frequencies. You count the number of each genotype, calculate allele frequencies directly, then compare observed genotype frequencies to expected ones using a chi-square test. I usually start by extracting allele counts from raw genotype data. If you have 100 individuals and they're diploid, that's 200 alleles total. Count how many carry each allele, divide by 200, and you have your p and q values. From there, calculate expected heterozygosity as 2pq. Compare that to what you actually observed. The difference tells you whether the population is deviating from equilibrium. The chi-square test follows a standard formula: sum the squared difference between observed and expected values, divided by the expected value, across all three genotypes. One degree of freedom if you're estimating p and q from the data. If the p-value comes out below 0.05, something is happening. Selection, inbreeding, population structure, genotyping error—it could be any of those.
I ran into a real problem last year working with a dataset of stickleback fish. The observed heterozygosity was significantly lower than expected across multiple loci. My initial assumption was inbreeding. I ran F-statistics, checked for population structure with PCA, and everything pointed toward a Wahlund effect rather than actual inbreeding. The population I thought was a single unit was actually two subdivided groups mated within their own clusters. When I separated them and recalculated, the deviation disappeared completely. This happens constantly. People assume inbreeding when they should be looking at structure.
Get the Full Details

What The Equations Miss Completely
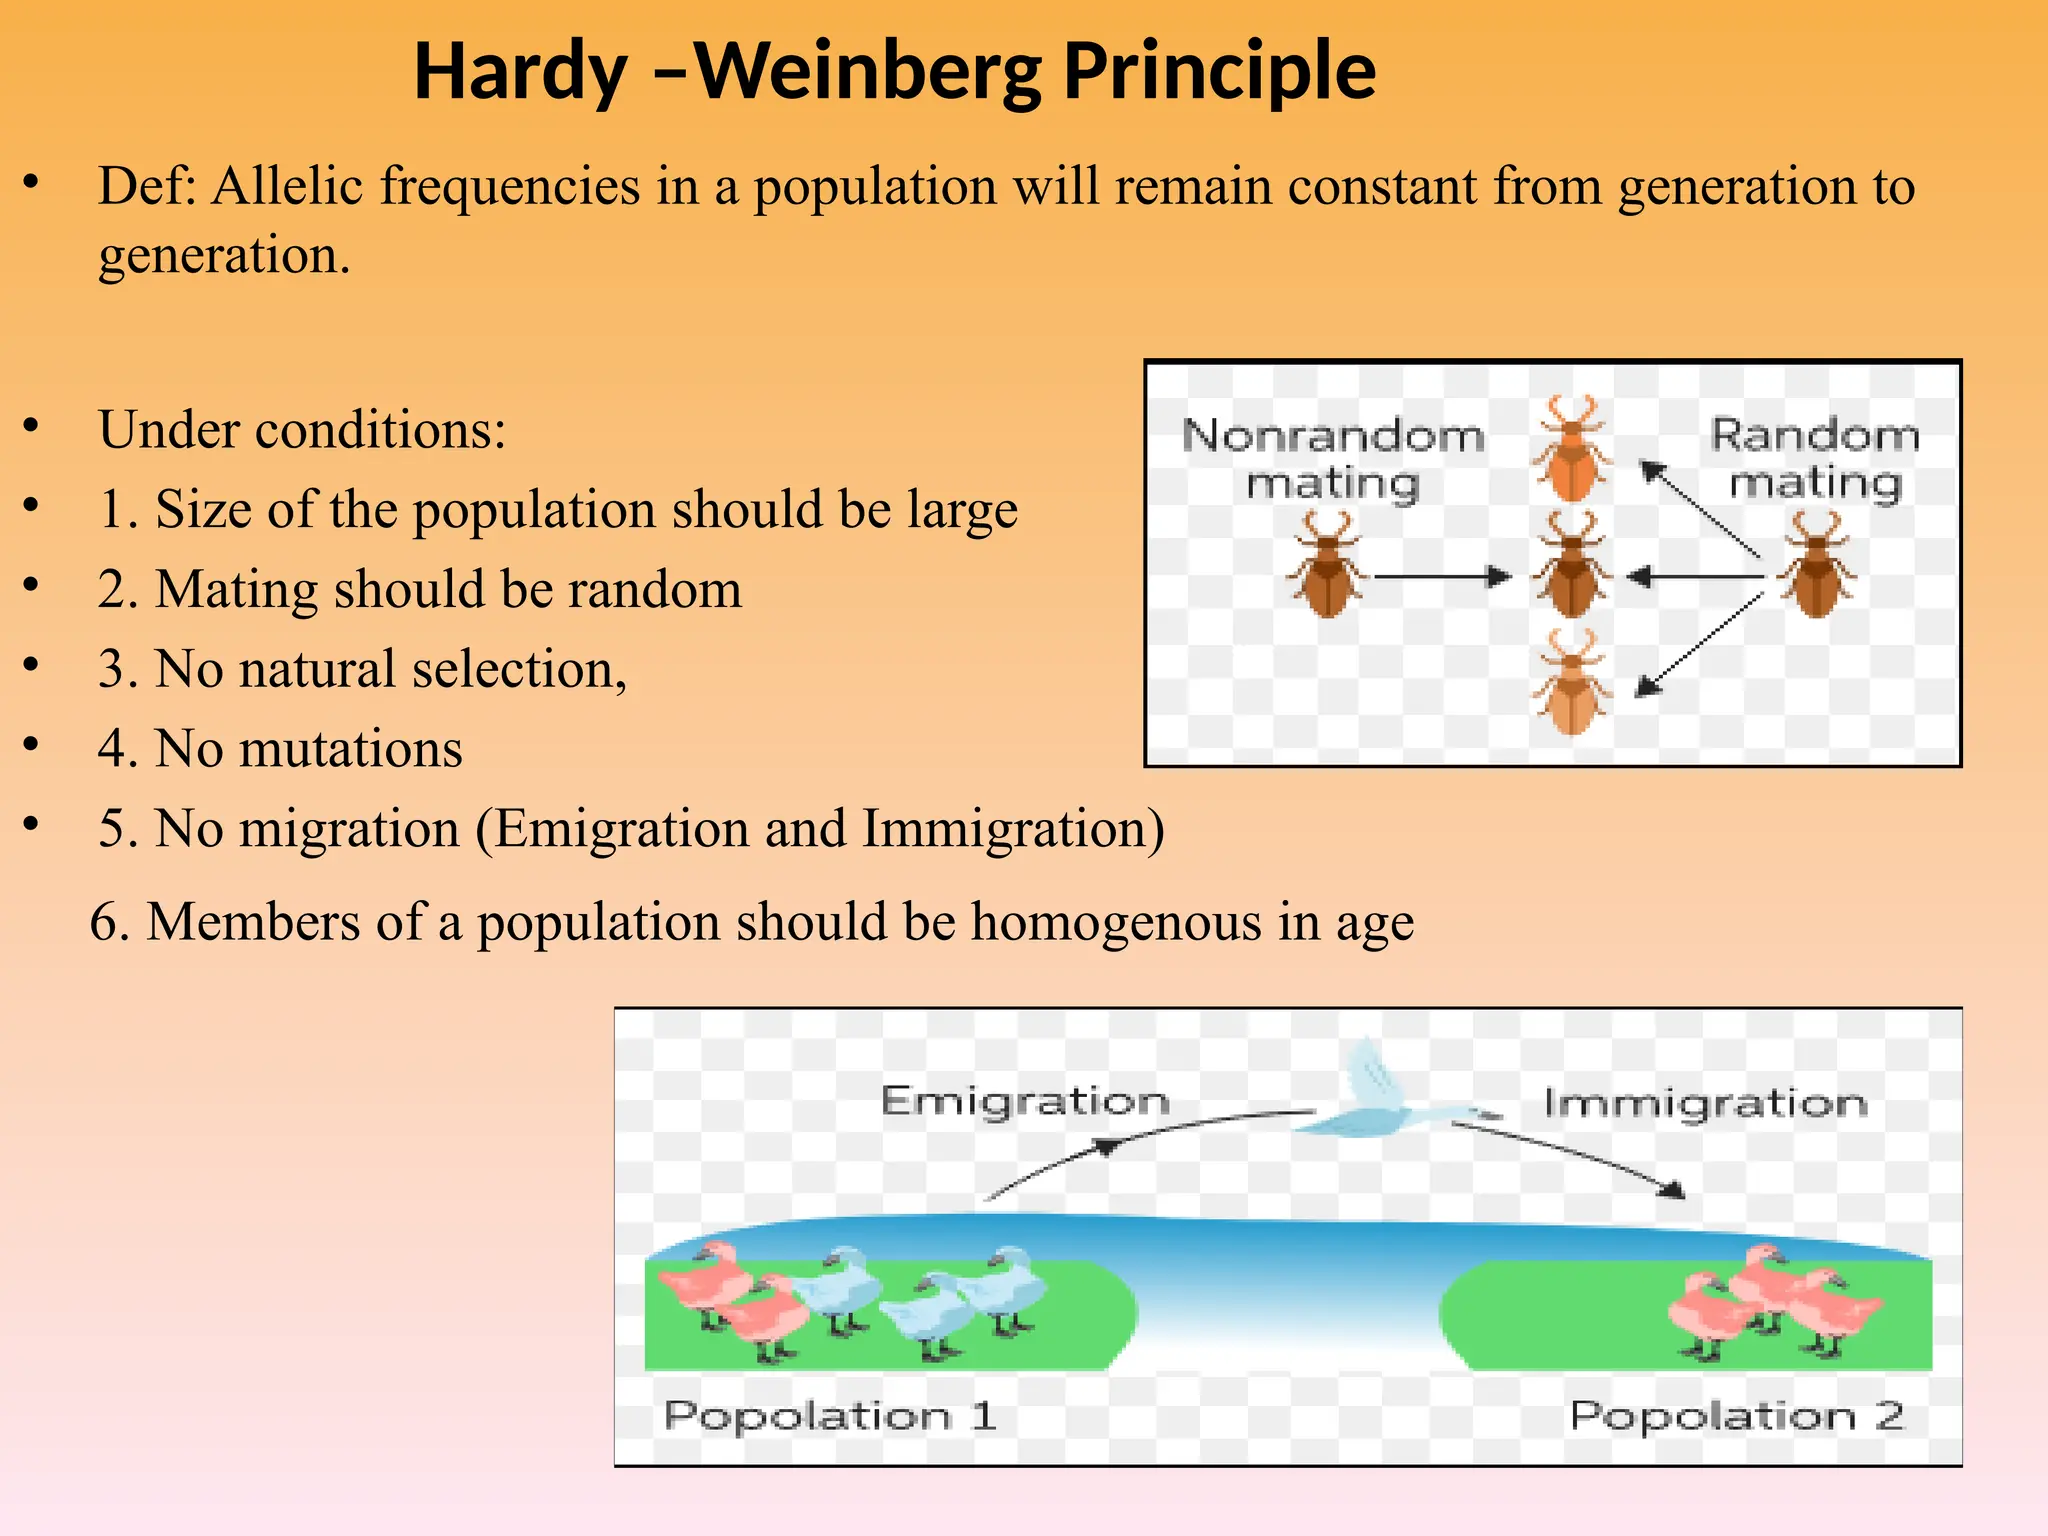
The principle assumes an infinitely large population. That's the first unrealistic condition. In any real study, you're working with finite samples, and sampling error itself creates apparent deviations. A small sample can look like selection when it's just noise. Always check your effective population size before drawing conclusions about evolutionary forces. Another thing beginners miss is that the Hardy-Weinberg Principle doesn't tell you which force is responsible for a deviation. It only tells you that one is. The equation is a null model, not a diagnostic tool. You need additional data and tests to figure out what's actually going on. I also see people misuse the equilibrium assumption when testing for selection at a single locus. If the population is already structured, a significant deviation from Hardy-Weinberg expectations might just reflect that structure rather than local adaptation. I've seen papers where authors claim positive selection without ruling out population subdivision. It's a sloppy practice that's become uncomfortably common.
The assumption of random mating is another fragile point. Many organisms don't mate randomly. Assortative mating based on phenotype or geography creates heterozygote deficits that look identical to inbreeding. Without pedigree data or spatial information, you cannot distinguish between these scenarios using HWE tests alone. When dealing with polyploid organisms or sex-linked loci, the standard equations break down entirely. The diploid framework doesn't translate. I once worked with a tetraploid plant species where the simple p² + 2pq + q² model was completely wrong. You need different formulations for autotetraploids with double reduction, and even then the math gets complicated fast. The standard chi-square approach gives misleading results in those cases. Microsatellite data and SNPs behave differently under HWE testing too. With highly polymorphic microsatellites, you often have many alleles, and the degrees of freedom explode. Exact tests become necessary instead of chi-square approximations. With SNPs, the main issue is genotyping artifacts. Homopolymer errors in NGS data can create false heterozygotes or homozygotes that look like HWE deviations. I always filter my variant calls for sequencing artifacts before running any HWE test. A bad filter saves you from chasing ghosts in the data.
If your goal is simply to estimate allele frequencies or expected heterozygosity without testing for equilibrium, you don't need the full framework. The allele counting method works fine on its own. The principle only matters when you're using it as a null hypothesis to detect evolutionary processes. Otherwise it's just algebra. There are also computational tools that handle the math automatically. PLINK, Genepop, and R packages like genepi will run HWE tests across thousands of loci in minutes. The default settings work for most standard datasets, but you should always verify that your software is using the right test for your data type. Exact tests versus chi-square make a real difference with small samples or rare alleles. The main limitation nobody talks about is that HWE testing has very low power when allele frequencies are extreme. A rare allele at 0.01 frequency will almost never show a statistically significant deviation unless your sample is enormous. You can have serious biological processes acting on a rare variant and the test won't catch them. This is important for disease association studies where causal variants are often rare.
I recommend combining HWE analysis with other approaches rather than relying on it alone. F-statistics give you a measure of population structure. Linkage disequilibrium analysis reveals non-random association between loci. Temporal sampling across generations can directly show whether allele frequencies are changing. The equilibrium principle is a starting point, not an endpoint. For practical field work, I usually run a quick HWE check as a quality control step first. If a significant portion of my loci are deviating, I know there's something wrong with the data collection or the sample isn't what I thought it was. It's a screening tool more than a scientific result. The actual science comes after you've identified and explained the deviation. The mathematics behind this are about 90 years old and they still work for their intended purpose. They just don't work for purposes they were never designed for. Keep the expectations realistic and the conclusions proportionate to what the data actually supports.