
Hibernate Interview Prep That Doesn't Waste Your Time
Most people studying for Java backend roles spend weeks going through random question lists on random websites. The results are usually generic answers that don't help you actually think through problems in an interview. I have gone through this process enough times for other people to stop guessing and use a system. Here is what actually works when preparing for Hibernate related questions.
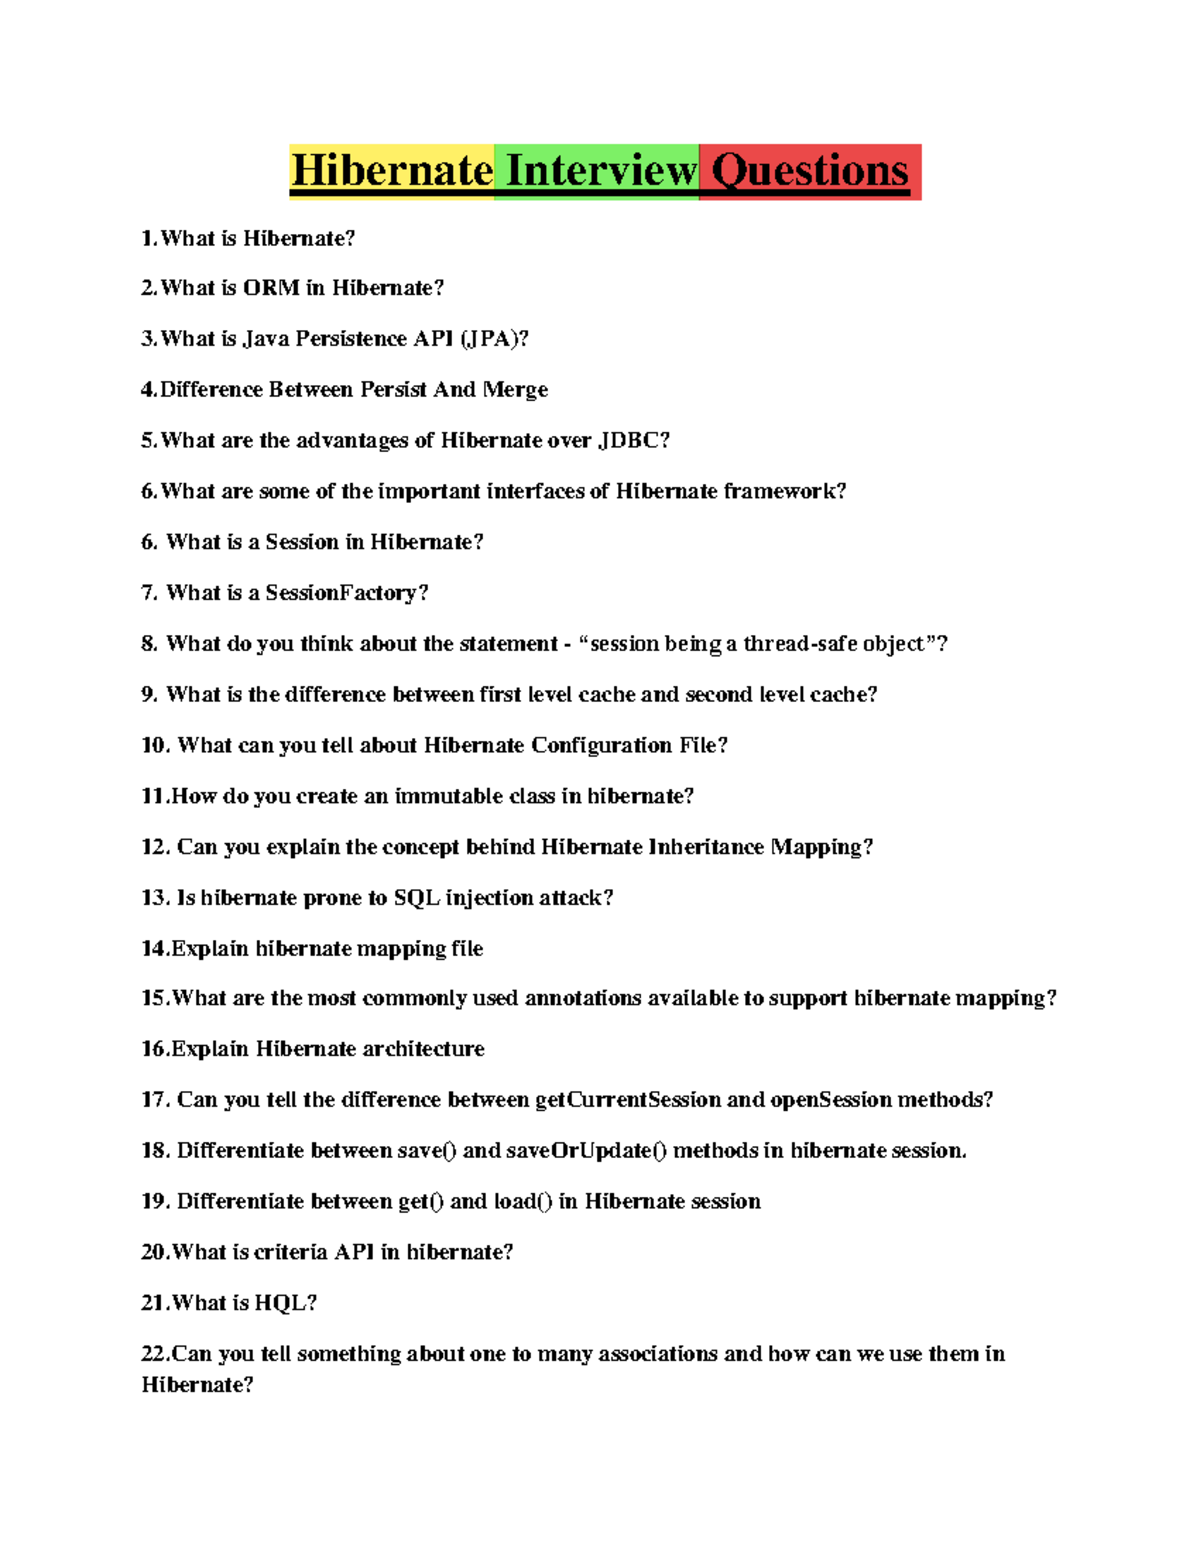
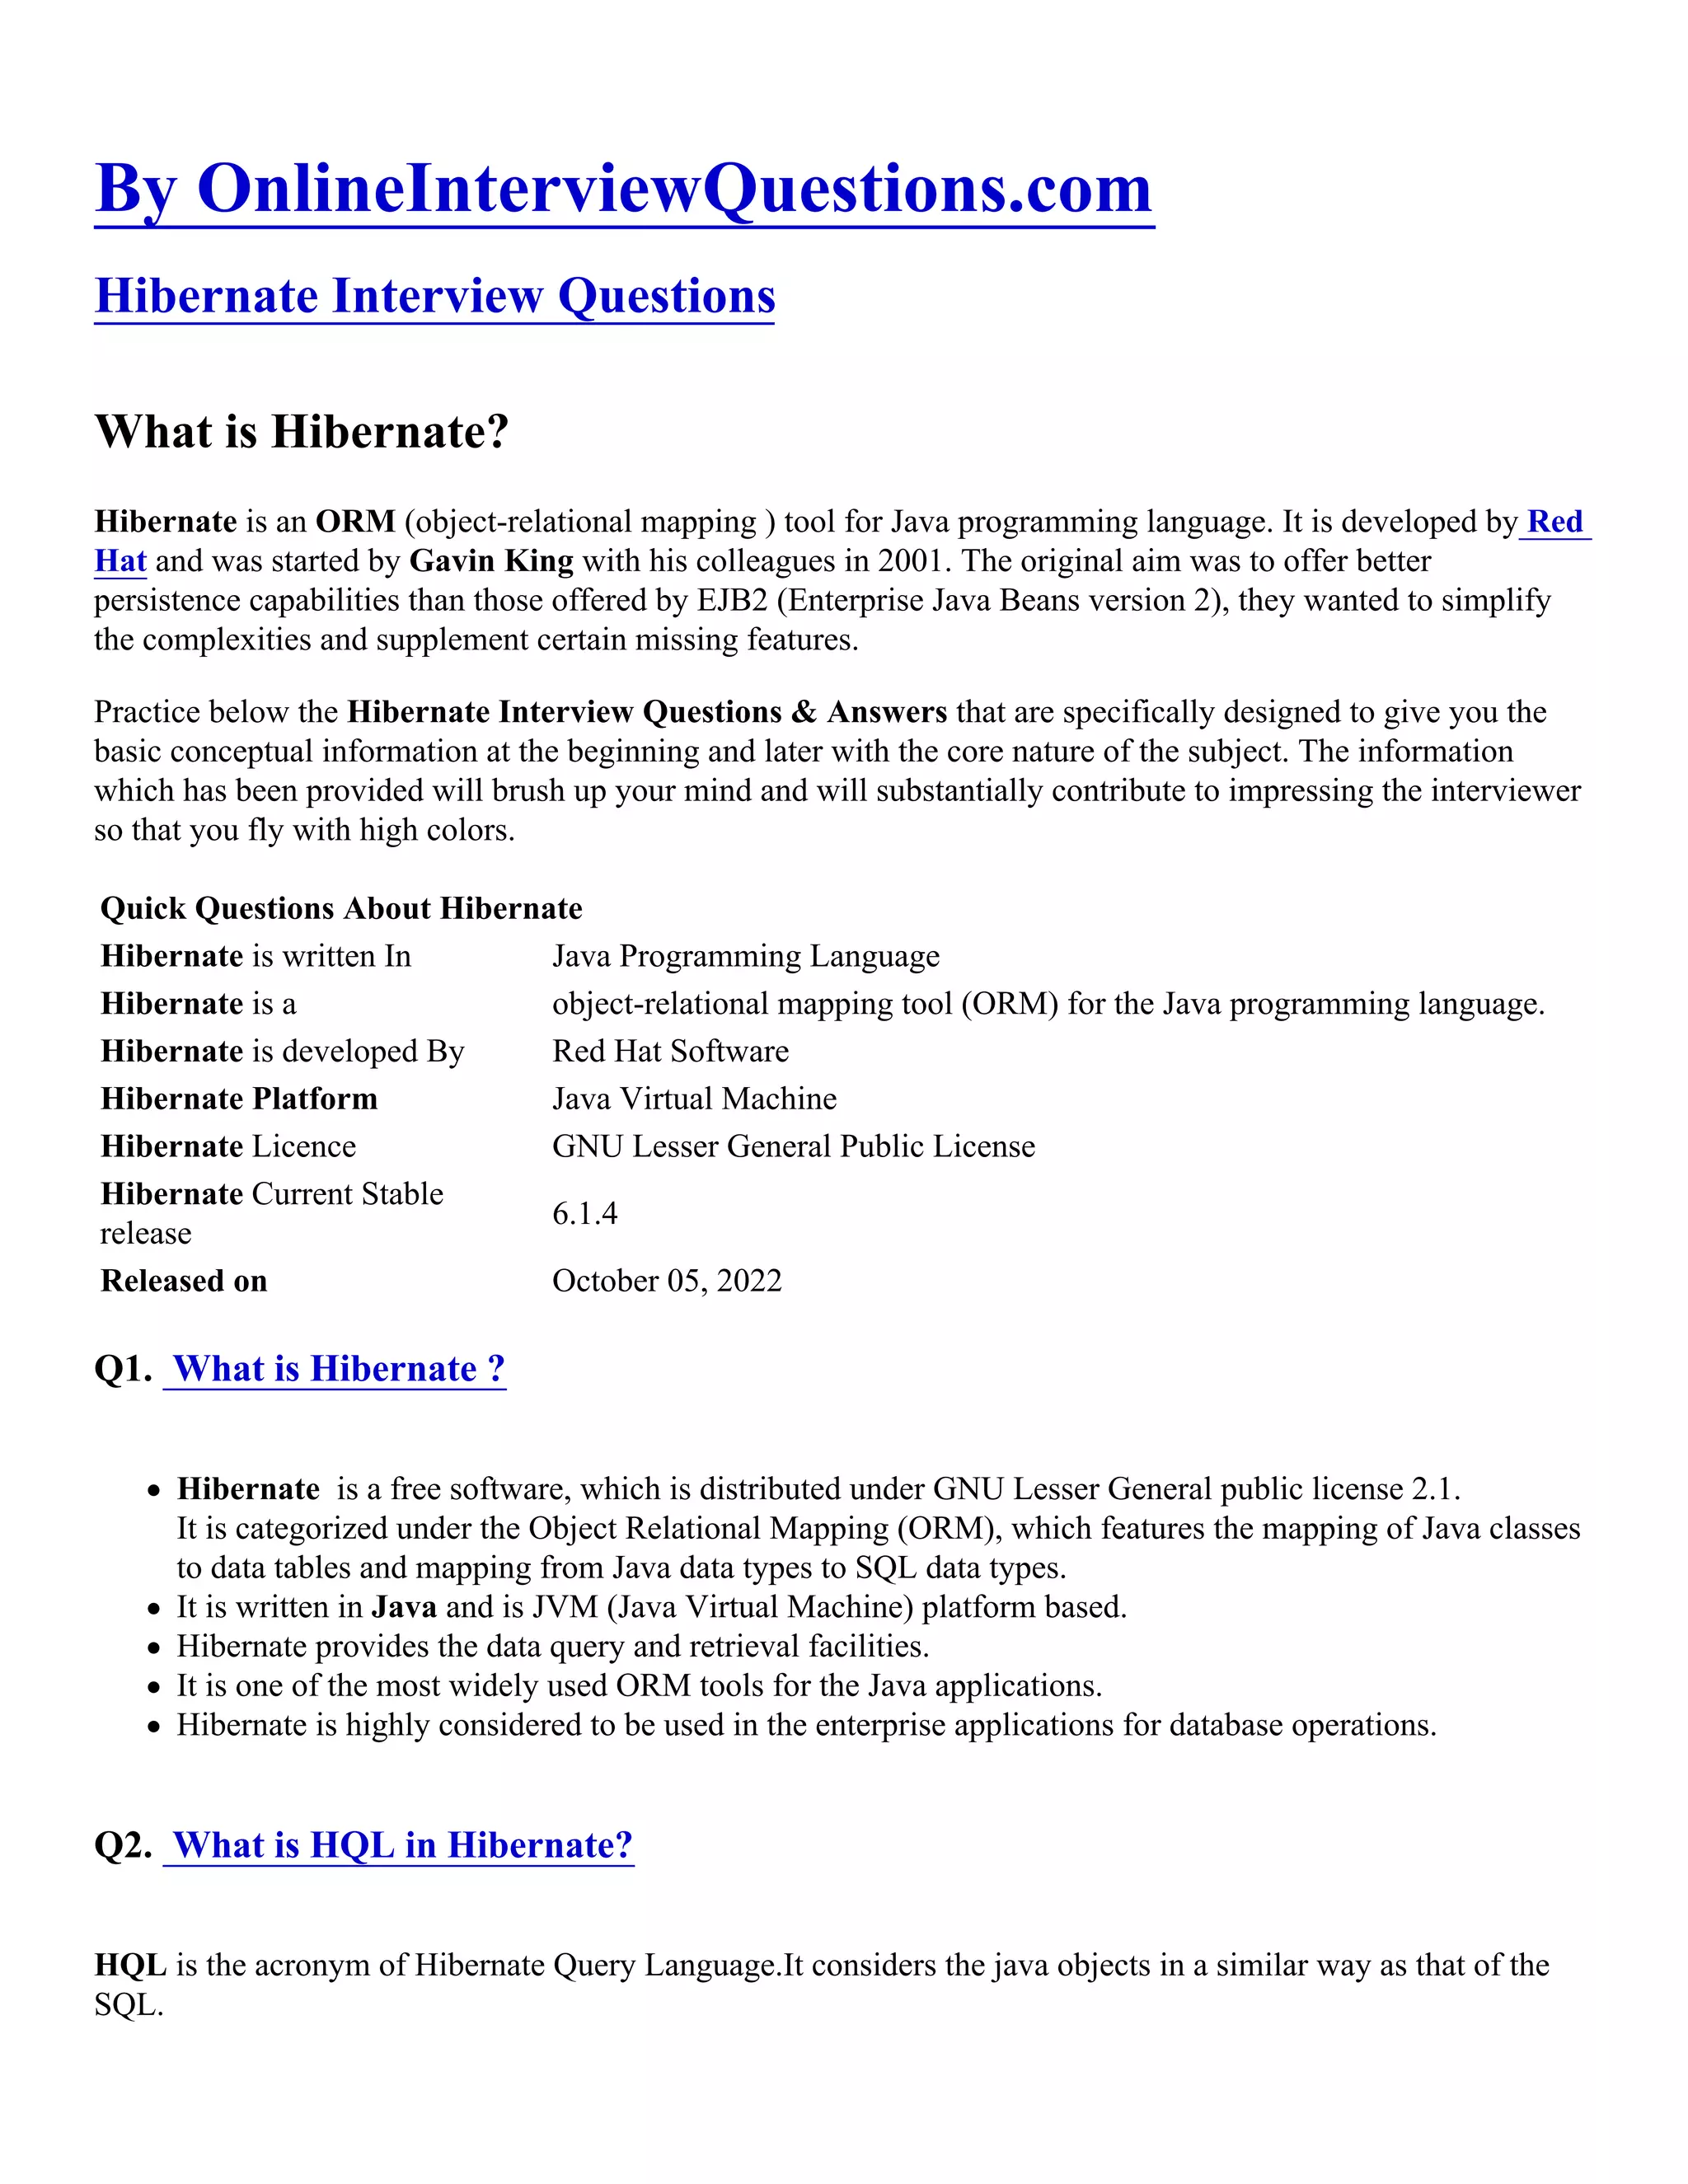
Hibernate Interview Questions And Answers You Should Actually Know
Let me start with the query language. Candidates always get comfortable with JPQL without understanding what happens underneath. When you write a JPQL query, Hibernate translates it into SQL. The catch is that the translation process is not free, and it does not always produce optimal SQL. I once had a production issue where a simple JPQL query with a left join was generating an N+1 problem at the SQL level because of how the join was being mapped. The application looked fine in testing because the test data set was small. In production with millions of rows, the response times jumped from 200 milliseconds to over 15 seconds. The fix was switching to a native SQL query with an explicit join, which cut the response time back down. That is the kind of thing interviewers actually want to hear about, not just the definition of a persistence context. First level cache is managed by the Persistence Context and is enabled by default. It is tied to the Session object lifespan. Every entity loaded or saved during a single session is stored there. If you call getSession().find(User.class, 1L) twice in the same session, the second call does not hit the database. It returns the cached instance. This is useful and usually free performance for most applications.
Second level cache operates across sessions and requires explicit configuration. It is not enabled by default. You need a cache provider like EhCache or Hibernate's own cache implementation. The configuration lives in hibernate.cfg.xml or your application properties. You also need to annotate entities or mappings with the cacheable flag. If you skip any of those steps, the second level cache will silently do nothing, and you will be looking for bugs in the wrong place. Lazy loading is one of those features that everyone says they understand but few have actually debugged. A proxy object is created when you load an entity with lazy associations. The real data is fetched only when you access the lazy field. This fails when you access a lazy field outside of an open transaction or session. You get a LazyInitializationException. The workaround used to be keeping the session open until the view renders, which was terrible for performance. The modern approach is either fetching the data you need inside the service layer using JOIN FETCH, or using open session in view pattern with proper timeout configuration, though most teams I have worked with prefer explicit data transfer objects. The entity lifecycle states are another area where people give surface level answers. An object is transient when it is new and not associated with any session. It becomes persistent when you call save, persist, or merge and the session tracks it. Detached means it was persistent at some point but the session is now closed. Understanding transitions between these states matters more than memorizing definitions. I once saw a candidate correctly describe all four states but then fail to explain why calling merge on a detached entity that has been modified since it was loaded would overwrite their changes with the database value. That is a common real world bug.
Get the Full Details
Batch processing in Hibernate is not automatic. If you are saving thousands of records in a loop, you need to configure batch size explicitly. The property is hibernate.jdbc.batch_size. Without it, each insert is sent individually. With it set to something like 50, Hibernate batches them together and the insert time drops significantly. I found this out the hard way when a daily job that used to take 40 minutes was taking 6 hours after we switched from direct JDBC to Hibernate without adjusting the configuration. Optimistic locking uses a version column. You add a version field to your entity annotated with @Version. When two transactions try to update the same row, the second one fails with an OptimisticLockException because the version has changed. This avoids table level locks. The downside is that you need to handle the exception gracefully in your application code. Some frameworks wrap this automatically, but if you are writing plain Hibernate, you handle it yourself. Criteria API is type safe and avoids string based queries. It is built into JPA, so you do not need extra dependencies. However, the Criteria API can become verbose quickly. I generally use it for dynamic query building where the conditions change at runtime, and stick to JPQL or native queries for static ones. Named queries defined on the entity class are a good middle ground.
Hibernate is not a silver bullet. It introduces overhead compared to raw JDBC. For simple CRUD operations this overhead is negligible. For high throughput bulk operations or complex analytical queries, raw JDBC or a dedicated query builder like jOOQ might be a better choice. The cache layers add complexity that you do not need unless your application actually has repeatable reads across sessions. Adding a second level cache to a low traffic internal tool is usually just adding maintenance burden. When interviewing, you will be asked about transaction management. PROPAGATION_REQUIRED is the default and most common propagation level. It joins an existing transaction or creates a new one. PROPAGATION_REQUIRES_NEW suspends the current transaction and starts a fresh one. This is useful when you need an operation to commit independently, like logging to an audit table. The tradeoff is that you lose the atomicity between the parent and child operations. Draft vs Persistent vs Detached entity transitions during a single transaction are where most subtle bugs appear. If you modify a persistent entity and then the transaction rolls back, the changes are discarded. If the entity is detached and you modify it, the session does not know about those changes until you call merge. This is a common source of lost updates when developers assume the session is always tracking their object.
One thing that does not get enough attention is the difference between save() and persist(). save() returns the generated identifier immediately and can trigger a flush. persist() does not guarantee the identifier is available right away and follows JPA spec more closely. In practice this rarely matters in simple applications, but in applications where you need the ID before committing, save() is the one you use. Interviewers who dig into this are testing whether you have actually read the documentation or just copied answers from a list. The entity relationship mappings are another area where the simple cases are well known but the edge cases cause production issues. @ManyToMany without an explicit join entity creates a join table automatically. This works until you need additional columns on the join table, like a timestamp or status field. At that point you have to break it into two @ManyToOne relationships with a separate entity. I have seen teams do this migration in production because they did not plan for it early enough. Plan for it from the start. Inheritance strategies in Hibernate are another common interview topic. Table per class creates a separate table for each concrete class. Joined tables share a base table and add subclass tables. Single table uses one table with a discriminator column. Each has tradeoffs. Single table is efficient for reads but creates many nullable columns. Joined tables are normalized but require joins. Table per class avoids nulls but duplicates columns. The discriminator column approach can become a maintenance headache when you have dozens of subclasses and the query optimizer struggles with the large table.
Native SQL queries bypass Hibernate's translation layer entirely. They are faster to write when you need database specific features, but they lose portability. If you switch from PostgreSQL to MySQL, a native query with PostgreSQL specific syntax will break. Use them sparingly and only when the database specific features are actually necessary. Finally, profiling your Hibernate application is usually more useful than reading about it. The hibernate.show_sql property and the format_sql property give you basic visibility. For anything serious, use a tool like p6spy or enable Hibernate statistics through jmx. I tracked a performance regression once by enabling hibernate.generate_statistics and looking at the query execution counts. A specific endpoint was executing 47 queries per request when it should have been one. Without that data, I would have been looking in the wrong place for hours.


