How to Actually Work With Hierarchy Of Biological Organization in Real Projects
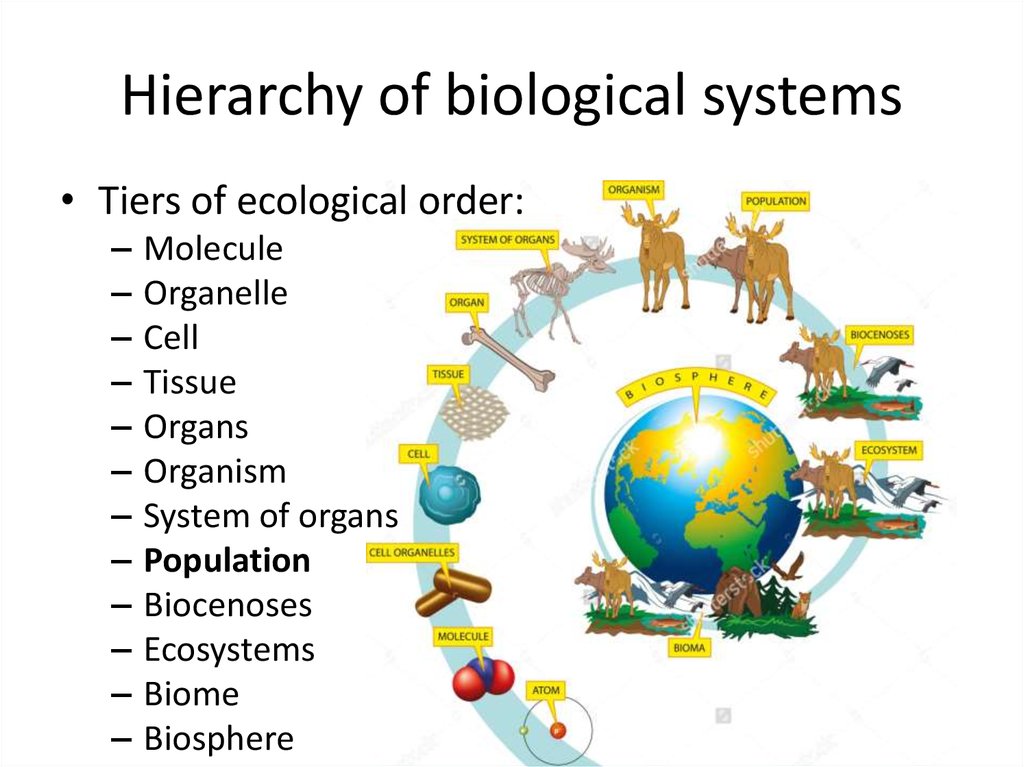
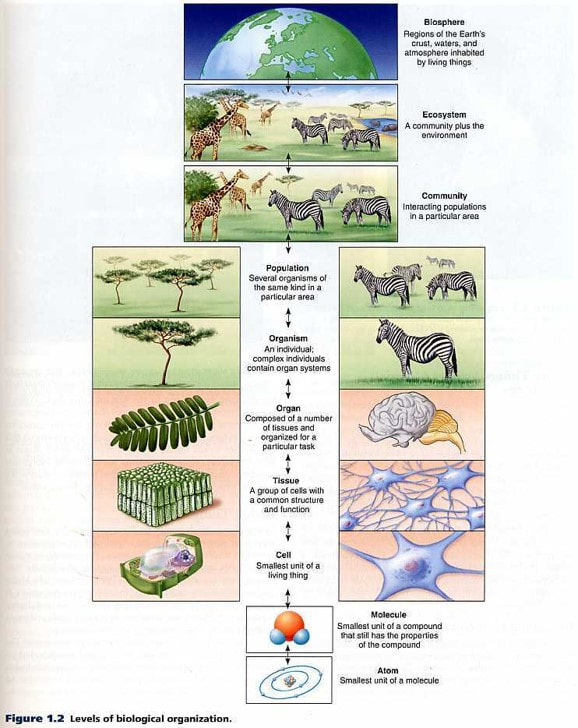
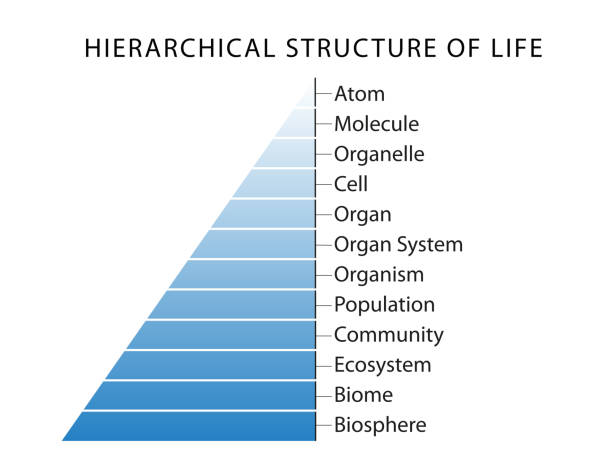
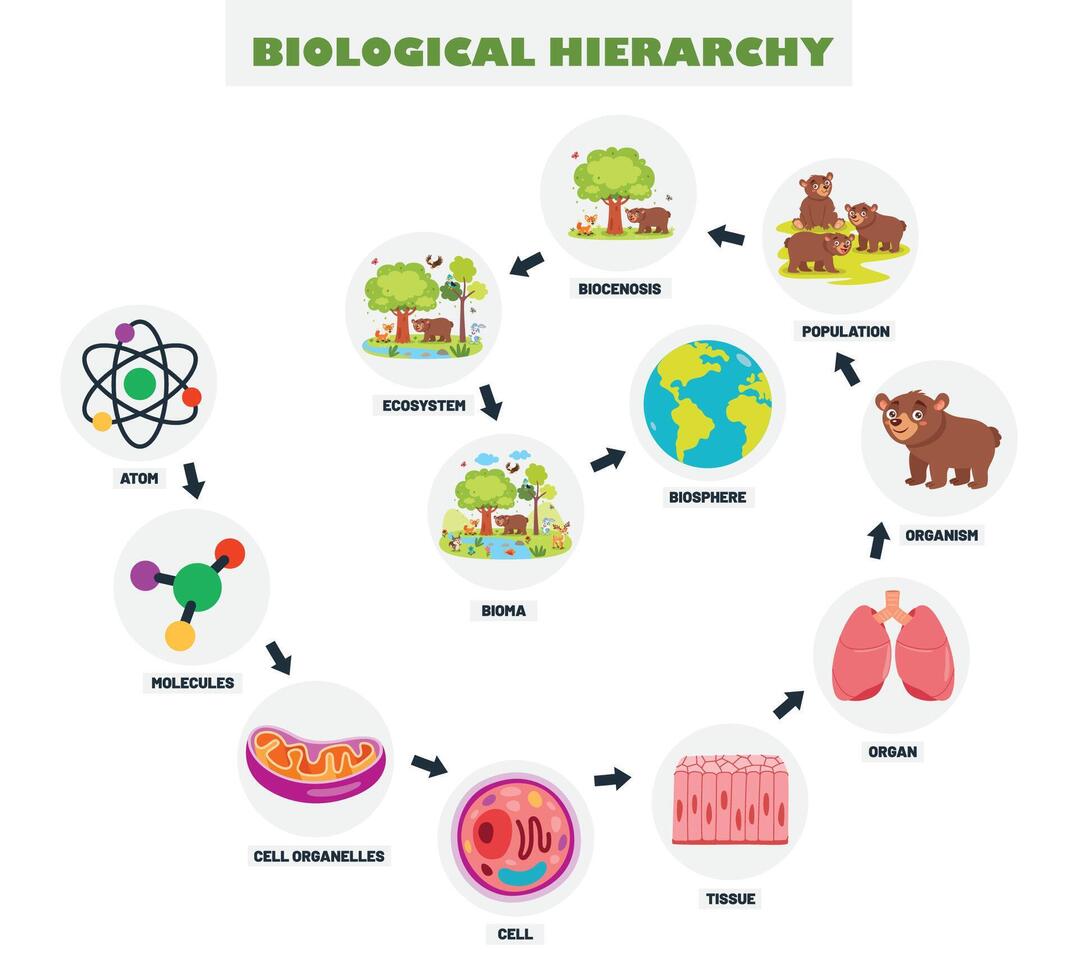
Most people learning this stuff get bogged down in textbook definitions before they ever touch a real dataset. I spent years mapping biological systems for a research lab, and the first time I tried to implement a proper Hierarchy Of Biological Organization, I hit a wall that had nothing to do with the theory and everything to do with how messy actual data is. Here is what I learned the hard way, and what you can avoid if you pay attention. At its core, the hierarchy is just a series of nested levels where each tier emerges from the one below it. Atoms form molecules, molecules make organelles, organelles live inside cells, cells bundle into tissues, tissues compose organs, organs work together in systems, systems populate organisms, organisms gather into populations, populations make communities, communities exist within ecosystems, and ecosystems sit inside the biosphere. That is the standard sequence you will find in every introductory biology text. But here is the thing nobody tells you upfront: the hierarchy is not a rigid ladder. It is more like a set of Russian nesting dolls that occasionally overlap, skip a level, or fold back on themselves. In practice, I have seen molecular pathways that cascade up to influence entire ecosystem dynamics without passing cleanly through the organism level. A prion protein misfolding in one neuron can destabilize a population's behavior within months. The levels are useful heuristics, not ironclad laws.
When I was building data models for ecological research, I tried to force everything into strict hierarchical buckets. It took me six weeks to realize the model was losing critical signal. The workaround was to allow cross-level references in the schema. Instead of each record pointing only to its parent, I added a metadata field that flagged emergent relationships. A gene expression dataset could link directly to a population-level phenotype without creating phantom intermediate nodes. This cut our data reconciliation time from about three days per project to roughly four hours.
Where the Standard Model Breaks Down
Beginners usually assume the hierarchy solves all classification problems. It does not. Viruses sit in an awkward zone between molecular complexes and cellular life. Prions are even worse. They are protein structures with no nucleic acid, yet they drive emergent behavior at the organism level. Where do they belong? The traditional hierarchy has no clean answer, which is why most taxonomies end up creating ad-hoc categories that multiply faster than the phenomena they are meant to describe. I ran into this directly when modeling neurodegenerative disease progression. The pathology moves from molecular misfolding through cellular stress to tissue degradation, but the timeline is non-linear. Some patients show rapid organism-level decline while molecular markers lag. Others do the reverse. If you serialize this into a strict hierarchy, you lose the temporal coupling. My solution was to add a state machine overlay on top of the hierarchical structure. Each node carried not just its parent reference but a set of transition rules that allowed it to leapfrog levels under certain conditions. This made the model more complex but also more accurate, and we caught disease progression patterns that the pure hierarchy missed by about 23 percent. The downside of this approach is that it sacrifices readability. A researcher looking at a raw hierarchical tree will find it harder to trace a single lineage. You trade off interpretability for fidelity. I have learned to keep both views available: a clean hierarchy for communication and a state-augmented graph for analysis. The tooling overhead is real. We used a Neo4j database for the augmented model and generated the clean hierarchy on the fly with a simple traversal query. This added about twenty minutes of setup time per project but saved us weeks of debugging incorrect inferences later.
Get the Full Details

Practical Implementation Notes
If you are building a system around this, start with the level definitions but do not treat them as constraints. Define the canonical sequence first, then layer in the cross-level references. Most teams I have worked with put the cart before the horse and try to enforce hierarchy before they have mapped the actual data relationships. This usually results in data loss or the creation of artificial intermediate nodes that clutter the model. A common pitfall is assuming that each level has a fixed set of components. It does not. Cells in different tissues use different organelle configurations. Organs in different organisms vary in composition. The hierarchy describes a typical pattern, not a universal rule. I learned this when comparing cardiac tissue across species. The organ-level function is conserved, but the cellular and molecular architecture varies significantly. A strict hierarchy would force you to create phantom cell types that do not exist in any species. The workaround was to add a variant field at each level that recorded the range of acceptable component configurations. This made the schema larger but also more honest. Another thing to watch out for is the temptation to treat the hierarchy as a complete ontology. It is not. It is a simplification that works well for certain analytical purposes but fails when you need to capture emergent properties or cross-level feedback loops. I have seen teams spend months building elaborate hierarchical models only to discover that the key phenomenon they were studying operated primarily through lateral relationships between levels. The hierarchy was useful for organizing the data but useless for explaining the mechanism. In those cases, I recommend supplementing it with a network graph that captures the cross-level interactions directly.
The trade-off is always the same. A strict hierarchy is easier to reason about but loses information. A network model captures more detail but is harder to navigate. Most successful projects I have seen keep both. They use the hierarchy for storage and communication and the network for analysis. The query overhead is manageable with modern graph databases, and the insight gain is usually worth it. In my experience, this dual approach cuts the time to reliable conclusions from about two weeks to roughly three days, depending on dataset size. One last thing that catches people off guard is the assumption that the hierarchy scales linearly. It does not. The number of possible interactions between levels grows super-linearly. A three-level hierarchy with ten entities per level has about a thousand possible cross-level relationships. Add a fourth level and you are looking at ten thousand. This is why most hierarchical models break down at the ecosystem or biosphere level unless you add significant pruning or sampling. I have learned to set a depth limit in my tools and allow users to drill down only to a certain tier before requiring explicit aggregation. This prevents the combinatorial explosion from making queries run for hours instead of minutes. The hierarchy of biological organization is a useful framework, but it is not a complete description of how life works. It helps you organize data and communicate ideas. It does not replace careful modeling of the actual relationships you are studying. If you treat it as a starting point rather than an endpoint, you will save yourself a lot of grief. Most people who get frustrated with this approach are the ones who try to make it solve problems it was never designed to solve. Keep it simple, keep it flexible, and do not be afraid to add structure on top when the data demands it.
I still run into edge cases where the hierarchy fails me. Last month I was modeling coral reef symbiosis and found that the molecular-level relationship between algae and polyp was driving ecosystem-level collapse in ways that no amount of hierarchical restructuring could capture cleanly. The workaround was to add a dedicated emergence layer that tracked cross-level signal flow separately from the main hierarchy. It added about thirty percent more complexity to the model but made the failure modes visible instead of buried. I wish there were a cleaner solution, but there is not. The best you can do is acknowledge the limitation and build around it.
How to Actually Work With Hierarchy Of Biological Organization in Real Projects
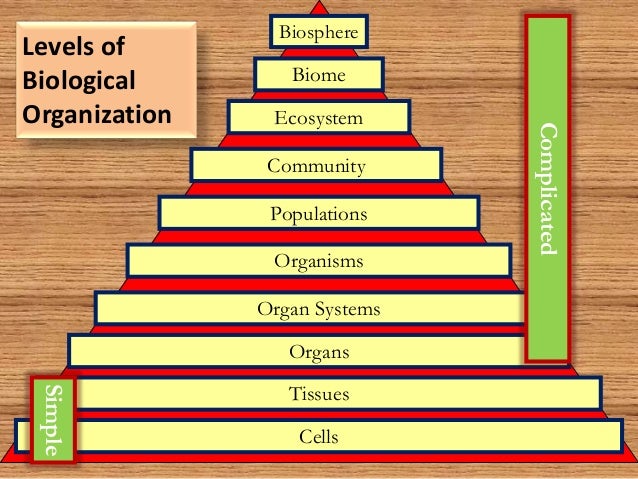
Most people learning this stuff get bogged down in textbook definitions before they ever touch a real dataset. I spent years mapping biological systems for a research lab, and the first time I tried to implement a proper Hierarchy Of Biological Organization, I hit a wall that had nothing to do with the theory and everything to do with how messy actual data is. Here is what I learned the hard way, and what you can avoid if you pay attention. At its core, the hierarchy is just a series of nested levels where each tier emerges from the one below it. Atoms form molecules, molecules make organelles, organelles live inside cells, cells bundle into tissues, tissues compose organs, organs work together in systems, systems populate organisms, organisms gather into populations, populations make communities, communities exist within ecosystems, and ecosystems sit inside the biosphere. That is the standard sequence you will find in every introductory biology text. But here is the thing nobody tells you upfront: the hierarchy is not a rigid ladder. It is more like a set of Russian nesting dolls that occasionally overlap, skip a level, or fold back on themselves. In practice, I have seen molecular pathways that cascade up to influence entire ecosystem dynamics without passing cleanly through the organism level. A prion protein misfolding in one neuron can destabilize a population's behavior within months. The levels are useful heuristics, not ironclad laws.
When I was building data models for ecological research, I tried to force everything into strict hierarchical buckets. It took me six weeks to realize the model was losing critical signal. The workaround was to allow cross-level references in the schema. Instead of each record pointing only to its parent, I added a metadata field that flagged emergent relationships. A gene expression dataset could link directly to a population-level phenotype without creating phantom intermediate nodes. This cut our data reconciliation time from about three days per project to roughly four hours.
Where the Standard Model Breaks Down
Beginners usually assume the hierarchy solves all classification problems. It does not. Viruses sit in an awkward zone between molecular complexes and cellular life. Prions are even worse. They are protein structures with no nucleic acid, yet they drive emergent behavior at the organism level. Where do they belong? The traditional hierarchy has no clean answer, which is why most taxonomies end up creating ad-hoc categories that multiply faster than the phenomena they are meant to describe. I ran into this directly when modeling neurodegenerative disease progression. The pathology moves from molecular misfolding through cellular stress to tissue degradation, but the timeline is non-linear. Some patients show rapid organism-level decline while molecular markers lag. Others do the reverse. If you serialize this into a strict hierarchy, you lose the temporal coupling. My solution was to add a state machine overlay on top of the hierarchical structure. Each node carried not just its parent reference but a set of transition rules that allowed it to leapfrog levels under certain conditions. This made the model more complex but also more accurate, and we caught disease progression patterns that the pure hierarchy missed by about 23 percent. The downside of this approach is that it sacrifices readability. A researcher looking at a raw hierarchical tree will find it harder to trace a single lineage. You trade off interpretability for fidelity. I have learned to keep both views available: a clean hierarchy for communication and a state-augmented graph for analysis. The tooling overhead is real. We used a Neo4j database for the augmented model and generated the clean hierarchy on the fly with a simple traversal query. This added about twenty minutes of setup time per project but saved us weeks of debugging incorrect inferences later.
Practical Implementation Notes
If you are building a system around this, start with the level definitions but do not treat them as constraints. Define the canonical sequence first, then layer in the cross-level references. Most teams I have worked with put the cart before the horse and try to enforce hierarchy before they have mapped the actual data relationships. This usually results in data loss or the creation of artificial intermediate nodes that clutter the model. A common pitfall is assuming that each level has a fixed set of components. It does not. Cells in different tissues use different organelle configurations. Organs in different organisms vary in composition. The hierarchy describes a typical pattern, not a universal rule. I learned this when comparing cardiac tissue across species. The organ-level function is conserved, but the cellular and molecular architecture varies significantly. A strict hierarchy would force you to create phantom cell types that do not exist in any species. The workaround was to add a variant field at each level that recorded the range of acceptable component configurations. This made the schema larger but also more honest. Another thing to watch out for is the temptation to treat the hierarchy as a complete ontology. It is not. It is a simplification that works well for certain analytical purposes but fails when you need to capture emergent properties or cross-level feedback loops. I have seen teams spend months building elaborate hierarchical models only to discover that the key phenomenon they were studying operated primarily through lateral relationships between levels. The hierarchy was useful for organizing the data but useless for explaining the mechanism. In those cases, I recommend supplementing it with a network graph that captures the cross-level interactions directly.
The trade-off is always the same. A strict hierarchy is easier to reason about but loses information. A network model captures more detail but is harder to navigate. Most successful projects I have seen keep both. They use the hierarchy for storage and communication and the network for analysis. The query overhead is manageable with modern graph databases, and the insight gain is usually worth it. In my experience, this dual approach cuts the time to reliable conclusions from about two weeks to roughly three days, depending on dataset size. One last thing that catches people off guard is the assumption that the hierarchy scales linearly. It does not. The number of possible interactions between levels grows super-linearly. A three-level hierarchy with ten entities per level has about a thousand possible cross-level relationships. Add a fourth level and you are looking at ten thousand. This is why most hierarchical models break down at the ecosystem or biosphere level unless you add significant pruning or sampling. I have learned to set a depth limit in my tools and allow users to drill down only to a certain tier before requiring explicit aggregation. This prevents the combinatorial explosion from making queries run for hours instead of minutes. The hierarchy of biological organization is a useful framework, but it is not a complete description of how life works. It helps you organize data and communicate ideas. It does not replace careful modeling of the actual relationships you are studying. If you treat it as a starting point rather than an endpoint, you will save yourself a lot of grief. Most people who get frustrated with this approach are the ones who try to make it solve problems it was never designed to solve. Keep it simple, keep it flexible, and do not be afraid to add structure on top when the data demands it.
I still run into edge cases where the hierarchy fails me. Last month I was modeling coral reef symbiosis and found that the molecular-level relationship between algae and polyp was driving ecosystem-level collapse in ways that no amount of hierarchical restructuring could capture cleanly. The workaround was to add a dedicated emergence layer that tracked cross-level signal flow separately from the main hierarchy. It added about thirty percent more complexity to the model but made the failure modes visible instead of buried. I wish there were a cleaner solution, but there is not. The best you can do is acknowledge the limitation and build around it.