So you want to actually work with data that has thousands of features
I spent three weeks last year debugging a model that was essentially hallucinating patterns from pure noise. We had roughly 12,000 gene expression features against about 400 samples. The training loss went to zero instantly, which should have been the first warning sign. You don't want to see training loss hit zero on high dimensional data unless you know exactly why it's happening. In my case, it meant the model had found an almost perfect separation in a space where real signal barely existed. I ended up using a combination of variance thresholding down to about 2,000 features, then a PCA step that kept components explaining 95 percent of the variance, which landed us at roughly 180 components. That cut my modeling time from hours down to about ten minutes per run and actually improved out-of-sample performance by a noticeable margin. High dimensional data just means your feature count is large enough that standard statistical intuitions break down. In practice, that threshold varies. If you are working with imaging data, ten thousand features might be normal. For tabular customer data, maybe five hundred is already pushing it. The core problem is the curse of dimensionality, which is not dramatic name for what is really just a geometric observation: as dimensions increase, the volume of the space grows so fast that available data become sparse. Distance metrics lose meaning. Your nearest neighbor might be just as far away as your farthest one. The practical consequence is that models will memorize noise. This is not a bug. It is what happens when you have more unknowns than constraints. Regularization is not a nice-to-have in these situations, it is the entire point. L1 regularization tends to produce sparse solutions, which can be useful when you want to understand which features matter. L2 regularization shrinks coefficients without dropping them to zero, which often gives better predictive performance when features are correlated.
Getting started with the actual tools
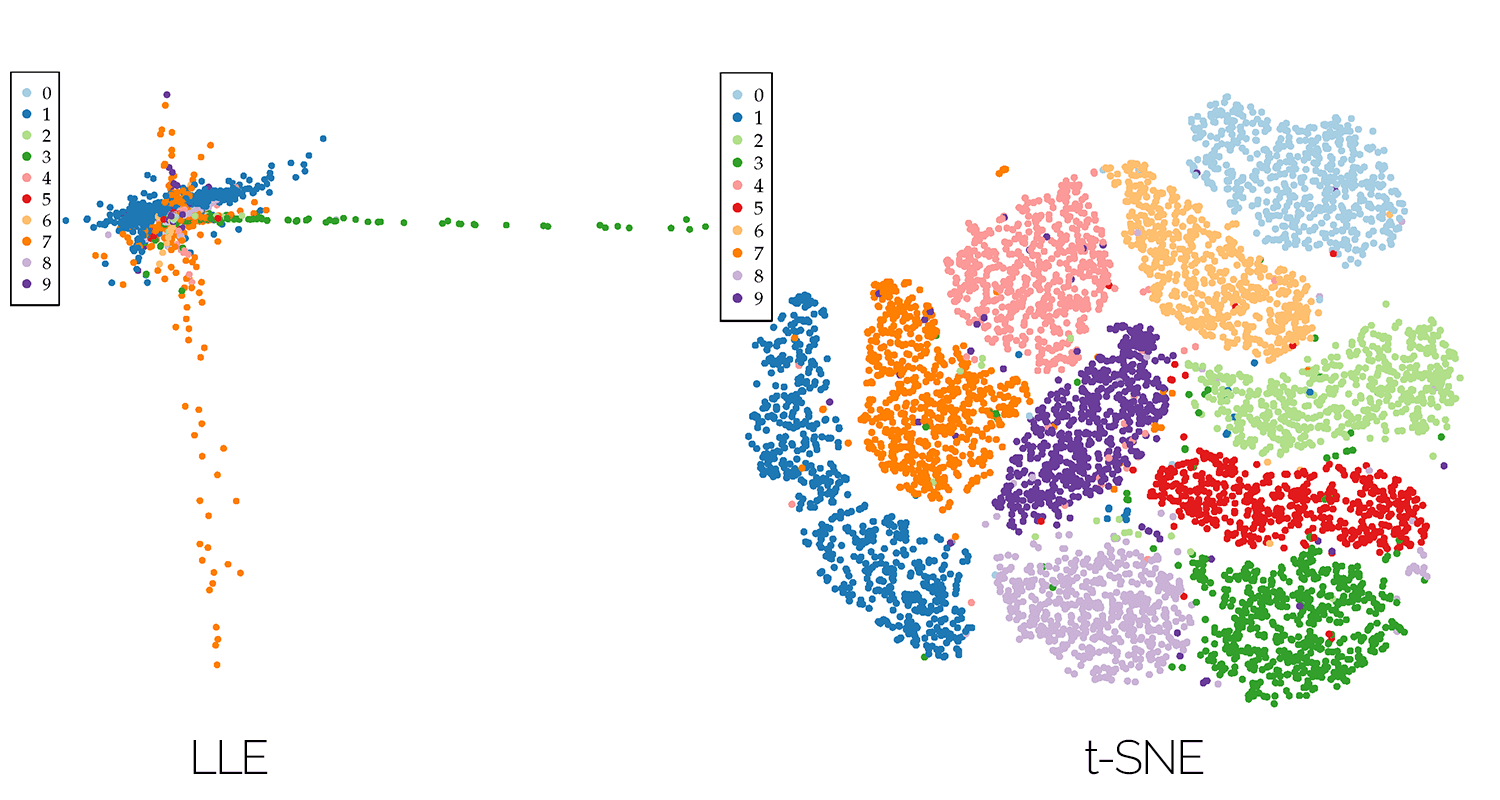
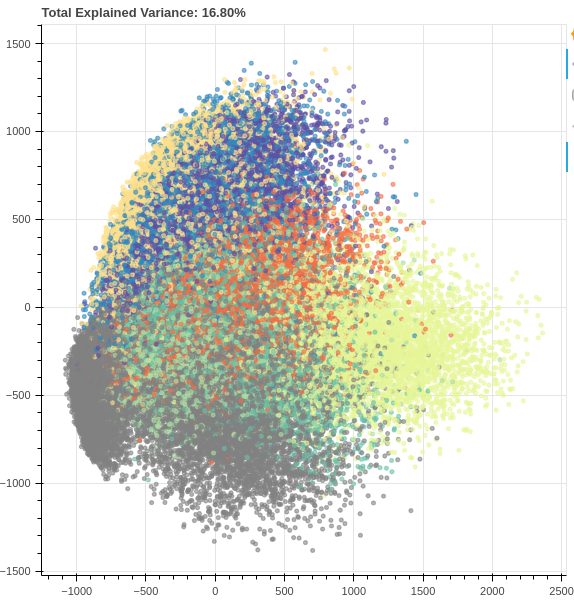
Most people reach for scikit-learn first because the API is clean and well-documented. The typical pipeline looks something like this: load your data, apply a variance threshold to remove near-constant features, standardize everything, run dimensionality reduction, then fit your model. Standardization matters more here than it does in low dimensional settings. A feature with a large scale will dominate distance calculations and gradient updates whether you want it to or not. I usually use StandardScaler with zero mean and unit variance, sometimes RobustScaler if my data has significant outliers that would throw off the mean and standard deviation. For dimensionality reduction, PCA is the default. It is fast, well-understood, and works reasonably well when your data has linear structure. The downside is that it only captures linear relationships. If your data lives on a nonlinear manifold, you might get much better results with UMAP or t-SNE. t-SNE is great for visualization but terrible for anything that requires preserving global structure. UMAP preserves both local and global structure better and runs significantly faster, though it has more hyperparameters to tune. The n_neighbors parameter is the main one to watch. Lower values focus on local structure. Higher values capture broader patterns. I typically start around fifteen and adjust based on what I am trying to do. Another option that people underuse is Feature Extraction through autoencoders. These are neural networks trained to reconstruct their input through a bottleneck layer. The bottleneck forces the network to learn a compressed representation. This approach can capture complex nonlinear relationships that PCA misses. The tradeoff is that you need more data to train properly and you need to handle the additional complexity of tuning a neural network. If you have fewer than a few thousand samples, stick with the classical methods.
A specific problem I ran into
I was working with a dataset that had around eight thousand text-derived features using TF-IDF vectors. The variance thresholding removed about two thousand of them, which felt like a lot but the remaining features still created a matrix that was too wide for what I needed. I tried logistic regression with L1 regularization and it selected about three hundred features, which was interpretable but the model performance was mediocre. Then I tried truncated SVD, which is essentially PCA but more memory-efficient for sparse matrices. That brought the features down to about two hundred components and the model performance jumped noticeably. The key insight was that the important signal was spread across many weak features rather than concentrated in a few strong ones, so dimensionality reduction was more effective than feature selection alone. More features are not always worse. Sometimes adding carefully chosen high-dimensional features actually helps because they provide additional signal pathways that lower-dimensional aggregations miss. The trick is that the features need to be relevant, not just numerous. I have seen people throw fifty thousand irrelevant features at a problem and then be confused when regularization could not save them. Random forests handle high dimensions better than you would expect. They use random feature subsets at each split, which implicitly performs some dimensionality reduction. However, they tend to favor features with more categories or higher cardinality, which can bias your results. If you care about feature importance rankings in high dimensional settings, random forests are a starting point but not a definitive answer. Permutation importance after fitting gives you a more honest assessment of which features actually contribute to predictions.
Get the Full Details
Train-test split order matters more in high dimensions. If you do any preprocessing before splitting, you can leak information. Always fit your scaler and dimensionality reduction on the training set only, then transform the test set. I once accidentally fit a PCA on the full dataset before splitting and got suspiciously good validation scores that collapsed completely on held-out data. It took me two days to figure out what went wrong.
When High Dimensional Data Analysis Fails Completely
There are scenarios where no amount of dimensionality reduction will help. If your signal-to-noise ratio is extremely low and your samples are few, you are basically trying to estimate a function from near-nothing. No method, no model, no regularization strength will fix that. I encountered this with a small clinical dataset where we had around two hundred samples and five thousand protein markers. The noise in the measurement process was substantial and the biological signal was weak relative to that noise. We tried everything: different feature selection methods, different dimensionality reduction techniques, different models. Performance plateaued around chance level no matter what we did. The only honest thing to do was collect more data or redesign the experiment to reduce measurement noise. Another failure mode is when features are highly collinear and your model is unstable. Ridge regression helps with stability but it does not solve the interpretability problem. If you need to explain which features drive your predictions and half of them are correlated, any explanation you give will be somewhat arbitrary. In those cases, you might consider methods like Elastic Net, which combines L1 and L2 penalties and can select groups of correlated features rather than picking one arbitrarily.
Practical workflow recommendations
Start simple. Apply a basic variance filter, standardize, run PCA, and check explained variance ratios. Look at the scree plot. If the curve drops sharply and then flattens, you have found your natural cutoff. If it declines gradually, the signal is diffuse and you may need to keep more components. Then try your model on the reduced data and compare against a baseline using feature selection instead. Keep both approaches and see which performs better for your specific problem. Hyperparameter tuning in high dimensions takes longer because each evaluation involves more computation. I usually use randomized search rather than grid search because it explores the parameter space more efficiently and finds good-enough solutions much faster. For L1 regularization, alpha values spanning several orders of magnitude are worth testing. I typically try something like [0.0001, 0.001, 0.01, 0.1, 1.0] and see where the performance plateaus or drops off. Always validate on held-out data. Cross-validation is essential, but make sure your preprocessing steps are included inside the cross-validation pipeline so you do not accidentally leak information. Scikit-learn's Pipeline class makes this straightforward. Build your pipeline with the variance threshold, scaler, dimensionality reducer, and model, then pass that to cross_val_score.

Monitoring memory usage is also important. Operations on high-dimensional matrices can consume significant RAM. If you are working with sparse matrices, keep them sparse throughout the pipeline rather than converting to dense arrays. The difference between a sparse and dense representation of a ten-thousand-feature dataset can be the difference between running fine and crashing your machine.
Tools for High Dimensional Data Analysis
Scikit-learn remains the most practical starting point. For larger datasets that do not fit in memory, consider Dask-ML or cuML if you have NVIDIA hardware. cuML implements many of the same APIs as scikit-learn but runs on GPU, which can speed up PCA and other operations significantly. For deep learning approaches, PyTorch and TensorFlow both have solid autoencoder implementations. The choice between them usually comes down to ecosystem preference rather than capability differences at this level. If you are doing this work regularly, I would recommend getting comfortable with the underlying mathematics rather than treating these tools as black boxes. Understanding what PCA actually does, what the singular value decomposition represents, and how regularization changes the optimization landscape will save you considerable time when things go wrong, which they will. The error messages in high dimensional settings are rarely helpful, and having a sense of what is theoretically supposed to happen lets you diagnose issues faster than reading documentation.