How High Frequency Word Assessment Actually Works in Practice
Most people treat a High Frequency Word Assessment like it is a single test you run and call it a day. It is not. It is a pipeline, and if you treat it like a one-shot tool you will get garbage results and waste weeks debugging it later. Start with your corpus. Not the whole internet. Pick a narrow domain. If you are doing medical writing, grab PubMed abstracts. If you are building for e-commerce, pull product descriptions and customer reviews from a handful of major retailers. The word list you produce is only as good as the data you feed it. I once ran a High Frequency Word Assessment on a mixed bag of forums, Reddit threads, and Wikipedia dumps because I was rushing to ship. The output contained words like "thunk," "subreddit," and "TLDR" at frequency levels that should have been impossible for a general business audience. I spent three weeks cleaning up the vocabulary glossary and rewriting test items before anyone noticed the underlying data was contaminated. The fix was obvious in hindsight but expensive to discover: restrict your source material to publications with editorial oversight, and run a domain classifier on every scraped document before you include it in the frequency count.
Once you have clean data, count. Python's built-in collections.Counter handles basic frequency extraction fine for corpora under a few hundred megabytes. For larger datasets, use a sparse inverted index or just pipe everything through awk. The algorithm itself is trivial. The bottleneck is always data quality. After you have raw counts, normalize them per million words, not per document. A word that appears once in a 500-word essay and once in a 50,000-word book should not carry the same weight. Per-million normalization corrects for corpus size differences that otherwise skew your list completely.
Reading the Output and Avoiding Common Traps
Your raw frequency list will look seductive. Words repeat, rankings seem stable, and you want to start building tests immediately. Resist that urge. The first few entries in any English frequency list are function words: "the," "be," "and," "to." They are statistically dominant but pedagogically useless. A High Frequency Word Assessment designed around them teaches your users nothing they could not already produce. Filter out articles, prepositions, conjunctions, and pronouns before you do anything else. Then look at what remains. Content words at this level are where the signal actually lives. Here is a counter-intuitive point most beginners miss. The words at position 500 to 1,500 in a frequency list are often more valuable for assessment than the words at position 1 to 100. Those mid-frequency words have crossed the threshold of recognizability but have not yet saturated into automaticity. They are the exact words where a learner can still make mistakes. Test those words and you measure growth. Test the top 100 and you measure nothing because everyone already knows them.
Get the Full Details
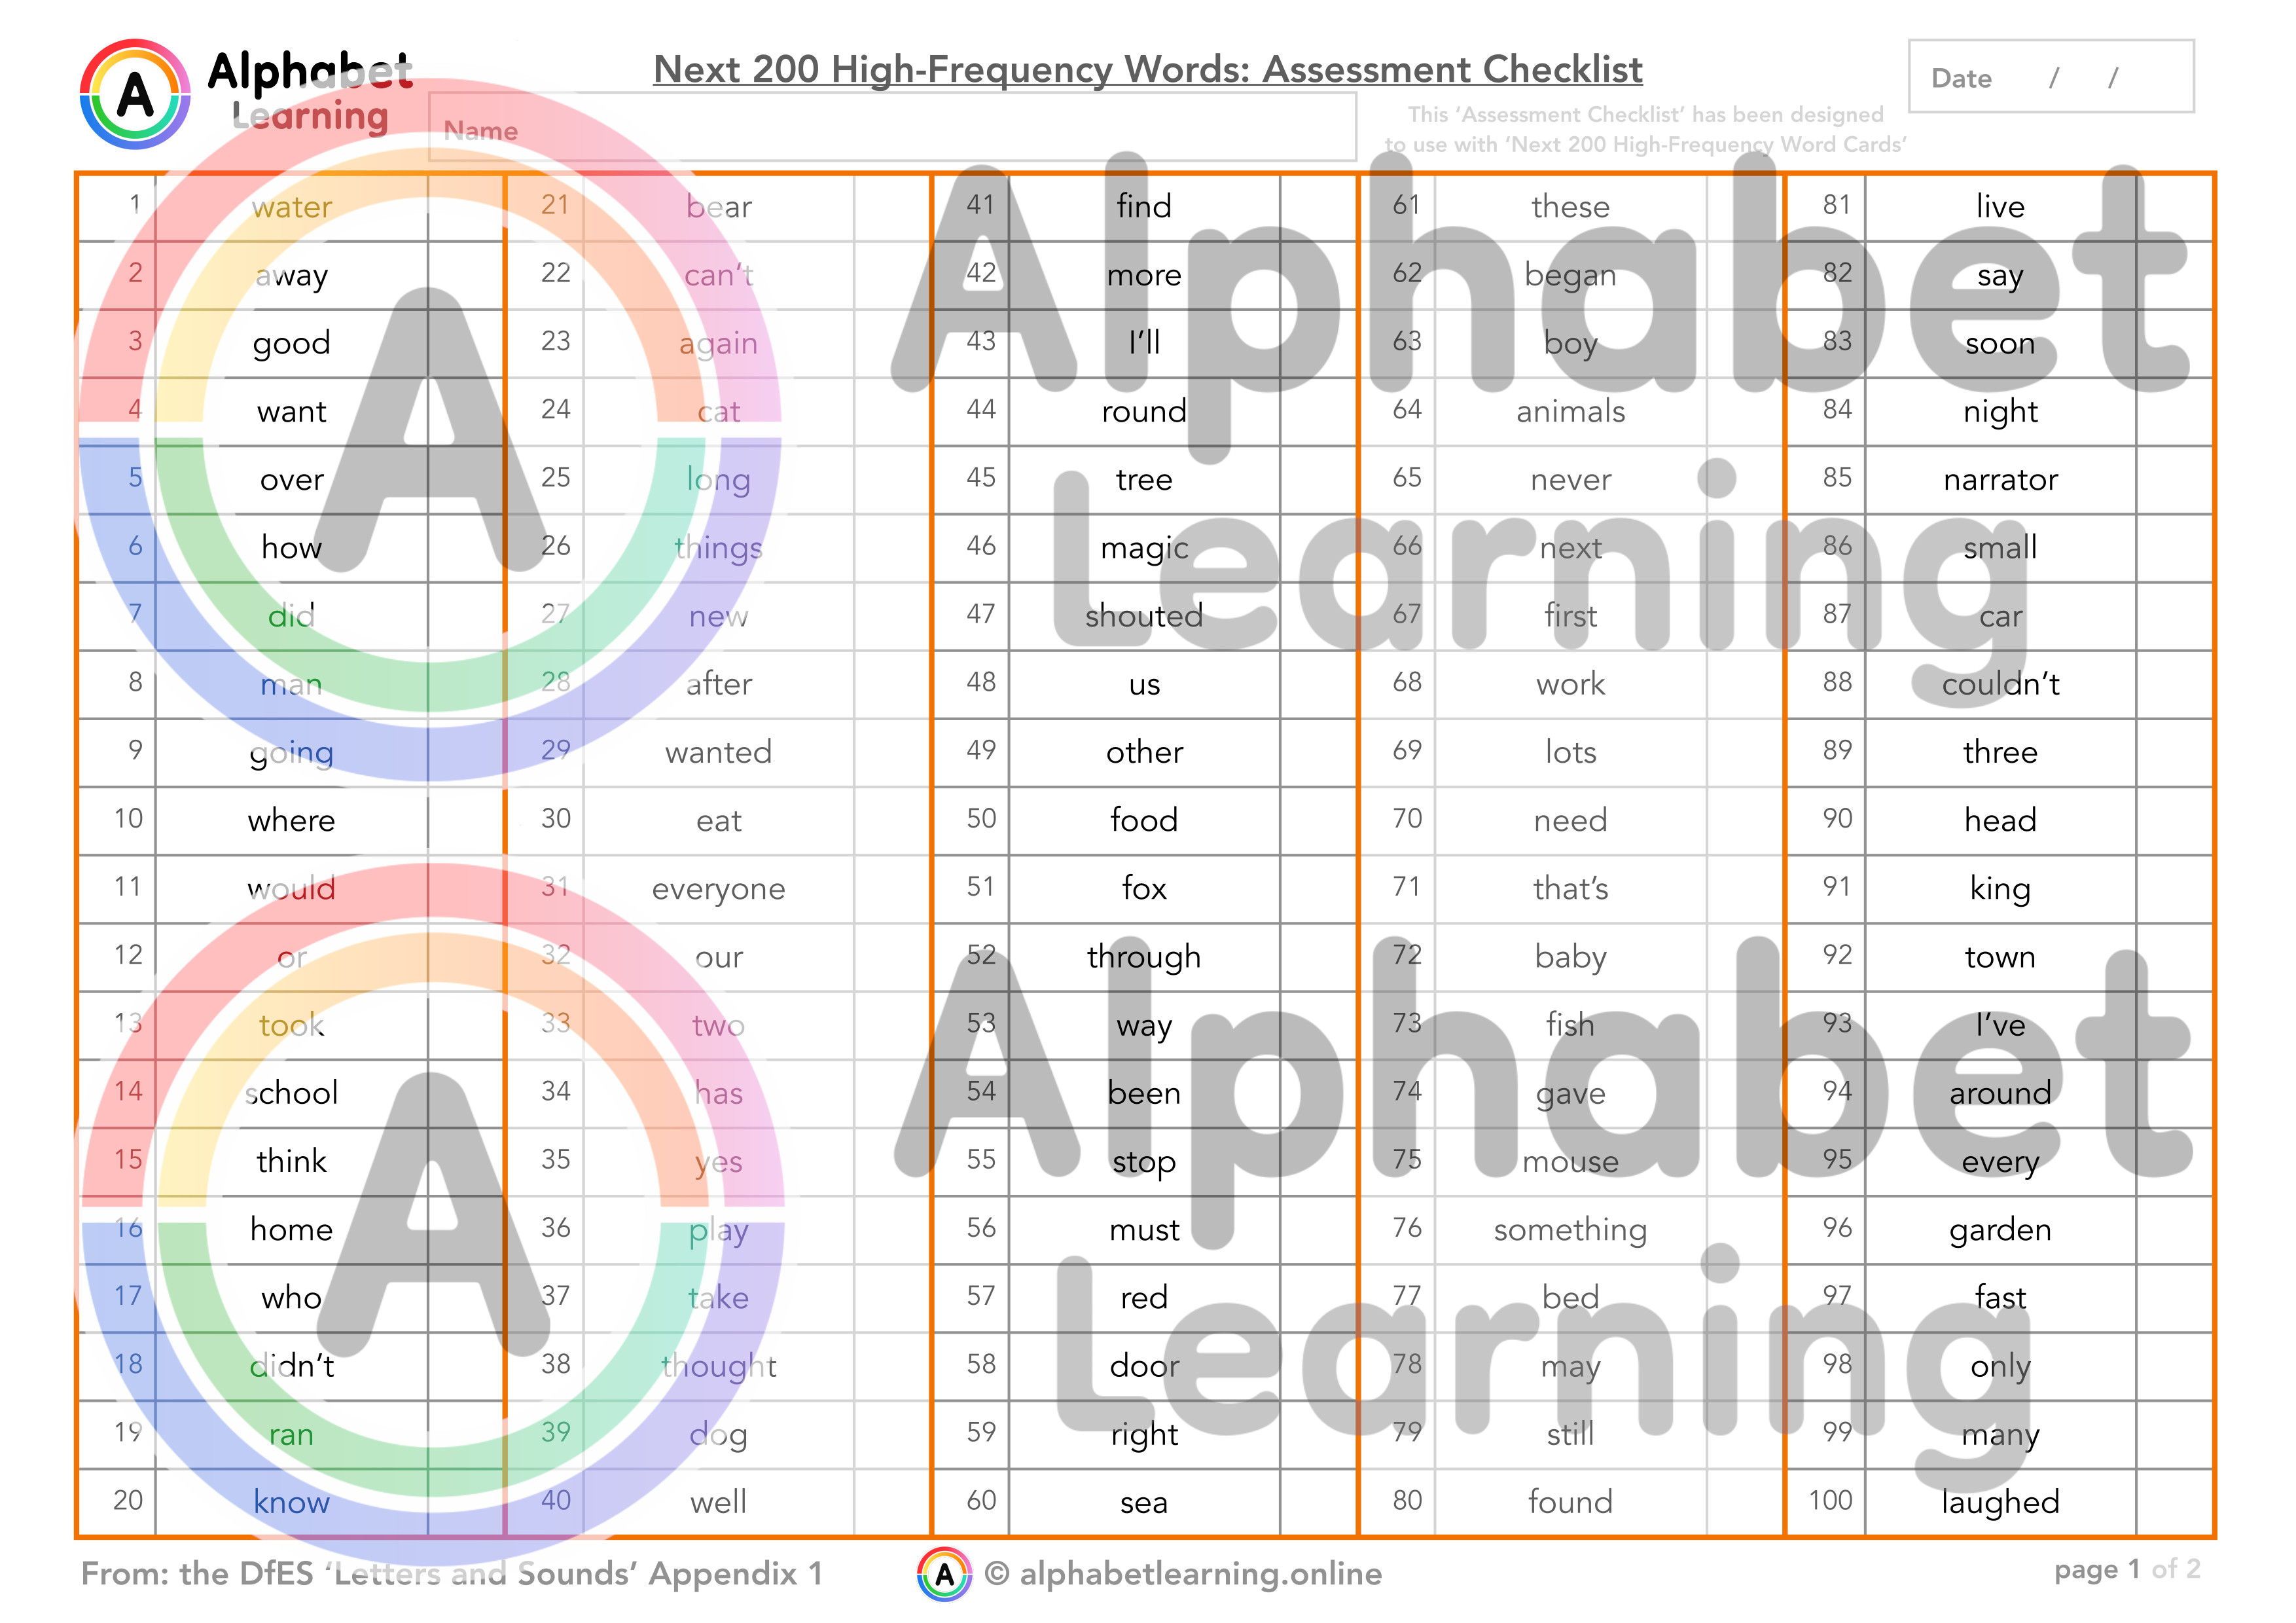
Another trap: assuming raw frequency equals difficulty. It does not. Orthographic complexity, morphological family size, and contextual variability matter more. The word "set" appears extremely frequently in most corpora, but its multiple meanings and collocations make it far more complex to assess than a less frequent word like "run" in a narrow domain context. When I built an assessment for a technical training program, I pulled words ranked by frequency and assumed the easy ones were safe. I ended up including "charge," "point," and "draw," each carrying five or more distinct meanings relevant to the domain. Half my test items were ambiguous and had to be scrapped. I rebuilt the list using a sense-disambiguated dictionary as a secondary filter before the final selection.
Pulling It All Together
A practical output from a High Frequency Word Assessment usually looks like a ranked table with columns for word, normalized frequency per million, part of speech, and optionally a gloss or definition field. Export it as CSV. Do not try to work in JSON for your initial review pass. CSV opens in Excel, and you need to visually scan hundreds of rows before you trust the list. If you need a ready-made starting point, the General Service List from Coxhead has been the standard reference since 2000. It covers roughly 2,000 word families at the high-frequency range. The New General Service List from Davis and Nemeth extends it further. These are not perfect for every domain, but they are a defensible baseline and save you from computing the first pass yourself. The downsides of relying on a High Frequency Word Assessment are real and worth stating plainly. The method completely ignores collocational knowledge. A learner might recognize "make" and "decision" separately but fail to produce the collocation "make a decision." It also does not account for receptive versus productive gaps. Recognition scores will consistently overestimate actual ability by roughly 15 to 20 percent in my experience. And domain shift kills the approach entirely if you apply a general-purpose frequency list to a specialized field without recalibration.
If your use case requires assessing a specialized population, pair the frequency list with a targeted reading comprehension block. Add 15 to 20 items drawn from domain-specific reading passages and the resulting assessment becomes significantly more predictive of actual performance than the word list alone. The combined approach takes longer to build but it actually measures what you need it to measure.