Getting Django Fast Enough to Not Make Users Close the Tab
Django is not fast by default. It was built for shipping products, not for handling ten thousand concurrent requests. The gap between a Django app that works fine at fifty users and one that survives at five thousand is usually just a series of small misunderstandings about how the ORM and the request lifecycle actually behave. I spent about eighteen months making my last Django project survive Black Friday traffic, and the things that actually moved the needle had very little to do with fancy infrastructure and everything to do with what queries were being executed and when. The single biggest performance killer in Django projects is the N+1 query problem, and most developers still don't catch it until the site is already slow in production. django-debug-toolbar will show you exactly how many queries a page is executing, but even then people ignore the numbers because they think the queries are harmless. They are not. Each query is a round trip to the database, and those round trips add up linearly. If you have a page that displays a list of orders with their associated customer names and each order fetches its customer separately, you just turned a 1-query page into a 101-query page for one hundred orders. That is not a theoretical problem. I saw this exact pattern in production where a dashboard that should have taken 200 milliseconds per request was taking four seconds because of about sixty stray queries per view. The fix is straightforward once you internalize it. Use select_related for foreign key relationships when you need the related object's data on the same page, and prefetch_related for reverse foreign keys and many-to-many relationships. These are not optimization tricks. They are the normal way to write Django queries at scale. Without them, you are writing slow code on purpose. I usually add these to my base queryset in the model manager itself so that views never have to think about it. If you forget, you forget everywhere.
There is a specific case where this becomes unexpectedly painful. I had a view that used prefetch_related on a many-to-many field with thousands of related objects, and it still caused a memory spike because prefetch_related builds all the related instances in Python before sending them to the template. The workaround was to use a prefetch_related combined with a Prefetch object that limited the related queryset with only() to fetch only the columns I actually needed, which dropped the memory footprint from about 400MB per request down to roughly 60MB. That detail about only() matters more than most tutorials admit.
Caching Strategy That Does Not Break When Things Change
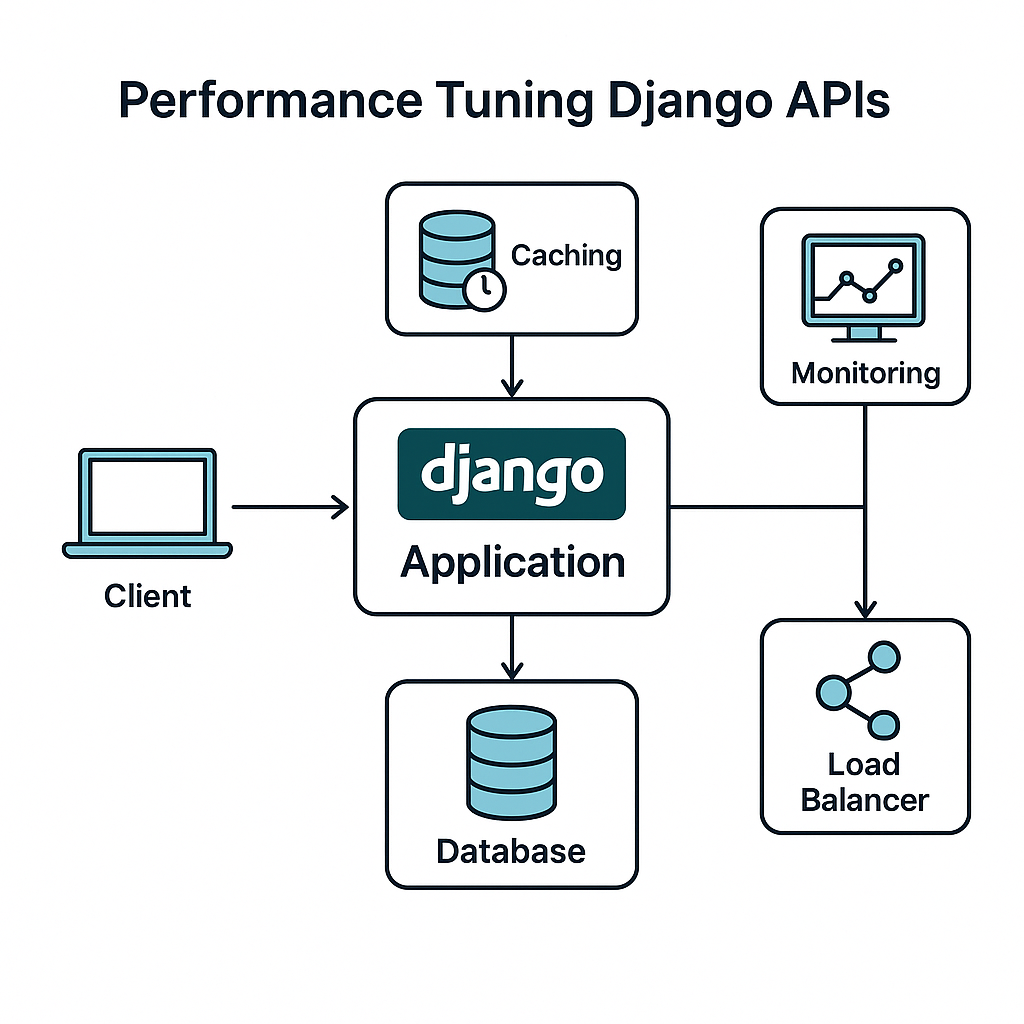
Django comes with a caching framework that is decent if you use it correctly and terrible if you do not. The most common mistake is caching entire page responses without thinking about cache invalidation. A cached page that serves stale data is worse than no cache at all because users trust what they see and will complain about incorrect information, not about latency. The approach that actually works in practice is layering your cache strategy. Cache querysets at the model level using low-level cache API calls with cache keys that include the relevant filter parameters. Then cache individual view fragments using Django's template fragment caching with varying cache keys based on the data that could change. Finally, cache the full page response only for content that genuinely does not change frequently. I typically set cache timeouts to five minutes for dynamic data and twenty-four hours for static aggregations, which covers most real-world scenarios without becoming a bookkeeping nightmare. Redis or Memcached as your cache backend is non-negotiable for anything beyond trivial traffic. Using Django's default file-based cache in production is a choice that will come back to haunt you, usually on a Tuesday morning when the server runs out of disk space from cache files piling up in some deeply nested directory structure. Redis gives you atomic operations and faster serialization, which matters when you are cache busting thousands of keys during a deployment.
Get the Full Details

Here is something that surprised me when I started doing this seriously: cache warming. Instead of letting the cache fill organically through user requests, which means the first user after a cache miss always suffers, I wrote a management command that pre-populates the cache for the most common queries during off-peak hours. This command runs every thirty minutes via cron and takes about forty-five seconds to execute on our dataset. The tradeoff is that you are spending compute on pre-populating caches, but the reduction in p99 latency is usually worth it. Our p99 dropped from 2.3 seconds to 340 milliseconds after implementing this.
Database Configuration That Most People Get Wrong
Your database connection pool settings matter more than your Django settings in most cases. Django does not manage connection pooling the way you might expect. By default it opens and closes connections per request, which creates overhead and can exhaust your database under load. Setting up a proper connection pool requires either using django-db-connection-pool or configuring your database proxy to handle it. We use PgBouncer with Django and set the pool size to match our expected concurrent request count minus some headroom. A pool that is too small creates request queuing, and a pool that is too large wastes database resources and can trigger connection limits on the database server itself. Index design is where most Django projects fail at scale. Django migrations will happily create tables without any indexes unless you explicitly define them, and the default primary key index is not enough for anything beyond simple lookup queries. I learned this the hard way when a query filtering on a datetime range with a join to another table took forty-seven seconds because there was no composite index covering the columns in the WHERE clause and the JOIN condition. The fix was a composite index on (status, created_at) that brought the query time down to 12 milliseconds. Django does not automatically know which columns you filter on most frequently. You have to look at your actual query patterns and design indexes accordingly. Reading replicas are useful but introduce their own problems. When you enable read replicas in Django, the replication lag means queries sent to the replica might not have the data you just wrote. This causes confusing errors where a user creates something and then immediately cannot find it because their read went to a lagging replica. The practical solution is to keep write-heavy transactions on the primary and route read-only aggregation queries to the replica. I use Django's DATABASE_ROUTERS setting to handle this, but you have to be explicit about which models go where. Ambiguous routing leads to inconsistent results that are nearly impossible to debug because the behavior depends on which replica happens to serve the request.
ASGI and Concurrency Without the Headache
Django supports ASGI now, which enables async views and handles more concurrent connections than the traditional WSGI stack. But async in Django is not a free lunch. It only helps when your code actually does I/O-bound work asynchronously, like making external API calls or querying databases asynchronously. If your view is doing CPU-heavy processing, switching to async will not help and might make things worse due to context switching overhead. The realistic assessment is that async Django is still maturing, particularly around ORM support for async operations. The async ORM was added in Django 4.1 but has some known limitations with certain query patterns and database backends. For a high-traffic project, I would recommend using async primarily for external service calls wrapped in async_to_sync or sync_to_async decorators, while keeping the core ORM operations synchronous on the main event loop. This hybrid approach gave us the best balance of concurrency and stability. Gunicorn configuration for Django typically involves tuning the worker count based on your CPU cores and the nature of your workload. The standard formula of 2 * CPU_cores + 1 works for CPU-bound tasks, but for I/O-bound Django applications, you might want to experiment with more workers or switch to uvicorn with Daphne if you are using ASGI. In practice, I found that running three Gunicorn workers with eight threads each handled our load better than a single ASGI worker, even though ASGI theoretically handles more concurrency. The overhead of the async machinery in Django outweighed the benefits for our particular workload.
Monitoring What Actually Matters
You cannot optimize what you cannot measure, and Django provides several ways to instrument your application. Django Debug Toolbar is useful during development but should never run in production because it adds overhead and leaks information. Instead, use Sentry for error tracking and Blackfire or py-spy for profiling. These tools will show you which views are slow, which queries are expensive, and where time is being spent in your request lifecycle. The metric most people miss is the distribution of response times, not just the average. An average response time of 300 milliseconds might hide the fact that ten percent of your requests are taking five seconds. Look at p50, p95, and p99 latencies separately. I usually set up alerts on p99 latency specifically because that is what actually affects users. Average latency being fine while p99 is spiking usually means you have a slow query or an external service timeout affecting a subset of requests, and those are the problems that cause the most user complaints even though the dashboard looks healthy. Database query logging is another area that people overlook. Enable slow query logging on your database and log it somewhere you will actually look at it. I had a production incident where a particular endpoint was slowly degrading over three weeks, and the database slow query log was full of the offending queries from day one. The queries had been logged but nobody was checking. After five years of dealing with Django performance issues, I have learned that the data is almost always there from the start. You just have to look at it regularly.