What actually changed in memory architecture over the last decade
The shift wasn't dramatic at first glance. DRAM moved from 2D planar cells to 3D stacked structures, and SRAM got tighter tapers on the fin geometries. But the real story is in the interconnects and the timing margins, which is where people get confused when they try to design around high performance memories. I worked through a design last year where we were pushing DDR5-6400 on a custom board and kept hitting intermittent ECC errors that only appeared under thermal load. The issue wasn't the memory itself. It was the trace impedance mismatch between the SoC I/O and the DIMM slot, compounded by the fact that DDR5's on-die ECC handles single-bit correction differently than the older off-package controllers did. We ended up length-matching the CA bus traces to within 5 mils instead of the usual 10, and the errors stopped. That kind of thing doesn't show up in any spec sheet.
High Performance Memories New Architecture Drams And Srams Evolution And Function
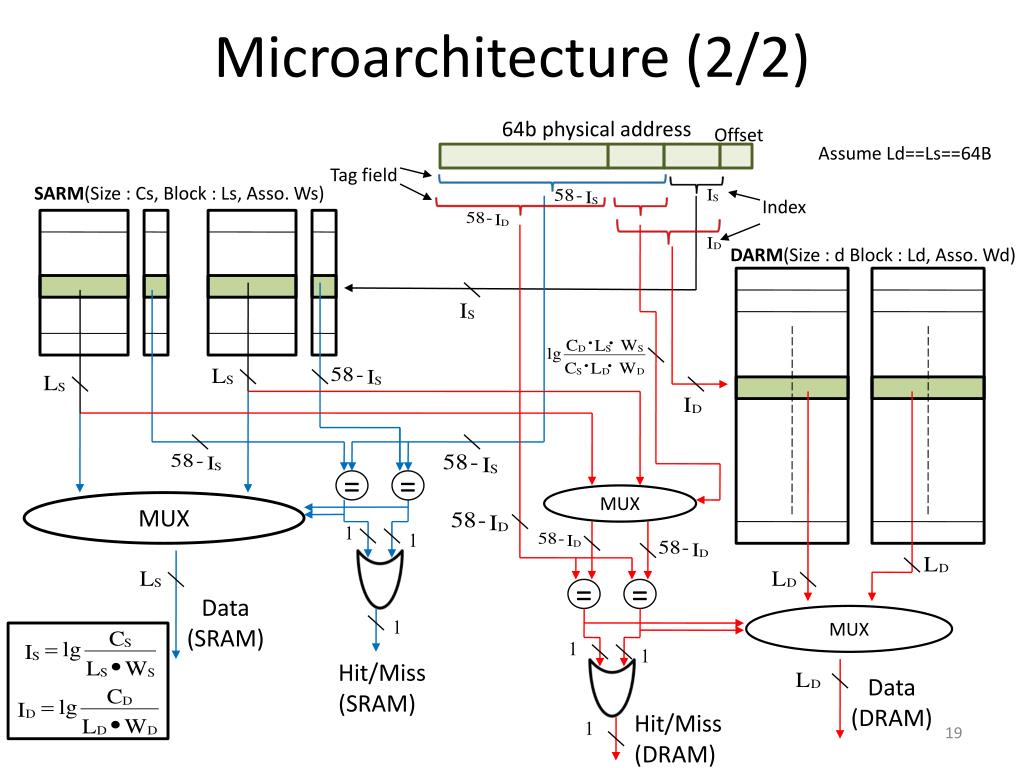
Here's how the current landscape breaks down without the marketing gloss. DRAM architecture has moved through several identifiable phases. The early 2010s were dominated by 2D bulk planar cells running at 1T1C (one transistor, one capacitor) structures. Address multiplexing split row and column access across multiple cycles to cut pin count. Then we hit the scaling wall around 20nm where leakage through the tunnel gates made planar designs untenable. Samsung jumped to 3D stacking first with their V-NAND concept, then applied the same vertical approach to DRAM with HBM and 3D DRAM packages. The key difference is that 3D DRAM doesn't just stack cells vertically; it uses through-silicon vias to create a wide memory bus directly to the package substrate. SRAM evolution followed a parallel but distinct path. The 6T cell remained the workhorse for decades, but as nodes shrank below 7nm, researchers started exploring 8T and even 10T variants for better stability under low voltage operation. The problem with the standard 6T cell is that the read static noise margin and write ability pull against each other. You can't optimize both simultaneously without compromising one. The 8T cell decouples the read and write paths entirely, which is why you see it in cache designs where power efficiency matters more than raw density. It costs roughly 33% more area per bit but lets you run at significantly lower voltages.
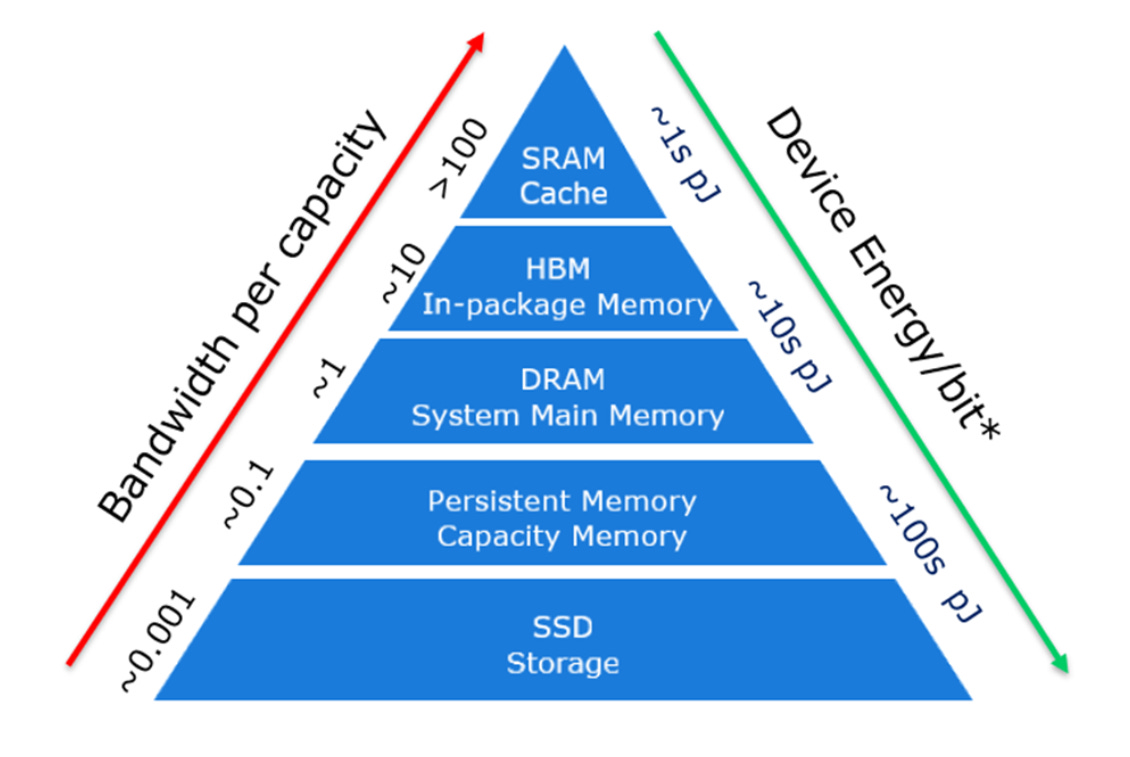
HBM changed the game for bandwidth-bound applications. Instead of chasing frequency, HBM trades frequency for width. A single HBM stack gives you 1024 bits of data bus width per channel at maybe 2-3 GHz. Compare that to DDR5 running at 4800-6400 MT/s on a 64-bit bus and you get dramatically different performance characteristics. The latency is worse, yes, but the bandwidth per watt is orders of magnitude better for the right workload. I've seen people try to use HBM as a drop-in replacement for DDR in server designs. It doesn't work that way. The memory controller has to be designed around it from the silicon level up. MRAM and STT-MRAM are the other direction entirely. They're non-volatile, which means they sit somewhere between DRAM and NAND in the performance hierarchy. Access times are in the nanosecond range compared to DRAM's sub-nanosecond, but they don't lose data when power cuts. I tested a prototype board with a Spin Transfer Torque MRAM buffer layer between HBM and the main memory controller for a real-time inference system. The idea was to preserve model state across power cycles without writing to disk. It worked, but the write endurance is still a limitation. We're talking about 10^12 to 10^15 cycles depending on the cell design, which is fine for infrequent checkpoints but terrible if you're doing heavy write patterns. For that workload, you'd be better off looking at ReRAM or just sticking with regular DRAM and accepting the volatile tradeoff. The emerging architecture trend I find most interesting is the chiplet-based memory integration. Instead of putting all memory on a single substrate, you're seeing disaggregated memory dies connected via UCIe or similar protocols. This lets you mix different memory types on the same package - HBM for the compute cores, LPDDR for the control processors, and NVMe-class storage for the persistence layer. The latency penalty for cross-die communication is real but manageable if you architect around it. The bigger problem is signal integrity across the package interconnect, which brings us back to those trace matching issues I mentioned earlier.
Get the Full Details
Testing these systems requires a different approach too. Traditional memory testers like the ones from Teradyne or Advantest work fine for standalone DRAM or SRAM characterization, but once you're dealing with heterogeneous memory stacks and chiplet architectures, you need protocols that can validate both the individual dies and the inter-die links. I found that a lot of teams skip the interconnect validation step because it slows down production testing. That's where you get the kind of latent failures that show up six months after deployment. The workaround isn't pretty - you run accelerated life testing on the interconnect at elevated temperature and voltage, then correlate the failure rates with your production test data. It adds maybe two weeks to your cycle time but catches issues that would otherwise cost you a recall. For anyone actually designing with these architectures, the practical advice is straightforward but not intuitive. First, don't assume the memory controller's timing specs are sufficient for your board layout. The controller guarantees timing at the package pin, not at the DIMM or the BGA pad. Your PCB parasitics matter enormously, especially at DDR5 speeds and above. Second, thermal management isn't just about keeping the memory cool. It's about keeping it thermally uniform. Hot spots cause timing drift across the array, and that drift shows up as marginal failures that are nearly impossible to reproduce in a lab setting. Third, when you're evaluating new memory technologies like MRAM or SOT-MRAM for embedded applications, ask the vendor for worst-case retention data at your target temperature range, not the typical spec. The typical numbers are often measured at 85C or lower. If your application runs at 105C or 125C, the retention time can drop by an order of magnitude or more. The bottom line is that high performance memory design has shifted from component selection to system integration. The individual memory parts are well characterized. The challenge is making them work together reliably across process corners, temperature ranges, and board-level variations. That's where most teams stumble, and it's not something you can debug with a logic analyzer after the fact. You have to plan for it during the architecture phase.