Understanding Histograms Beyond the Basics
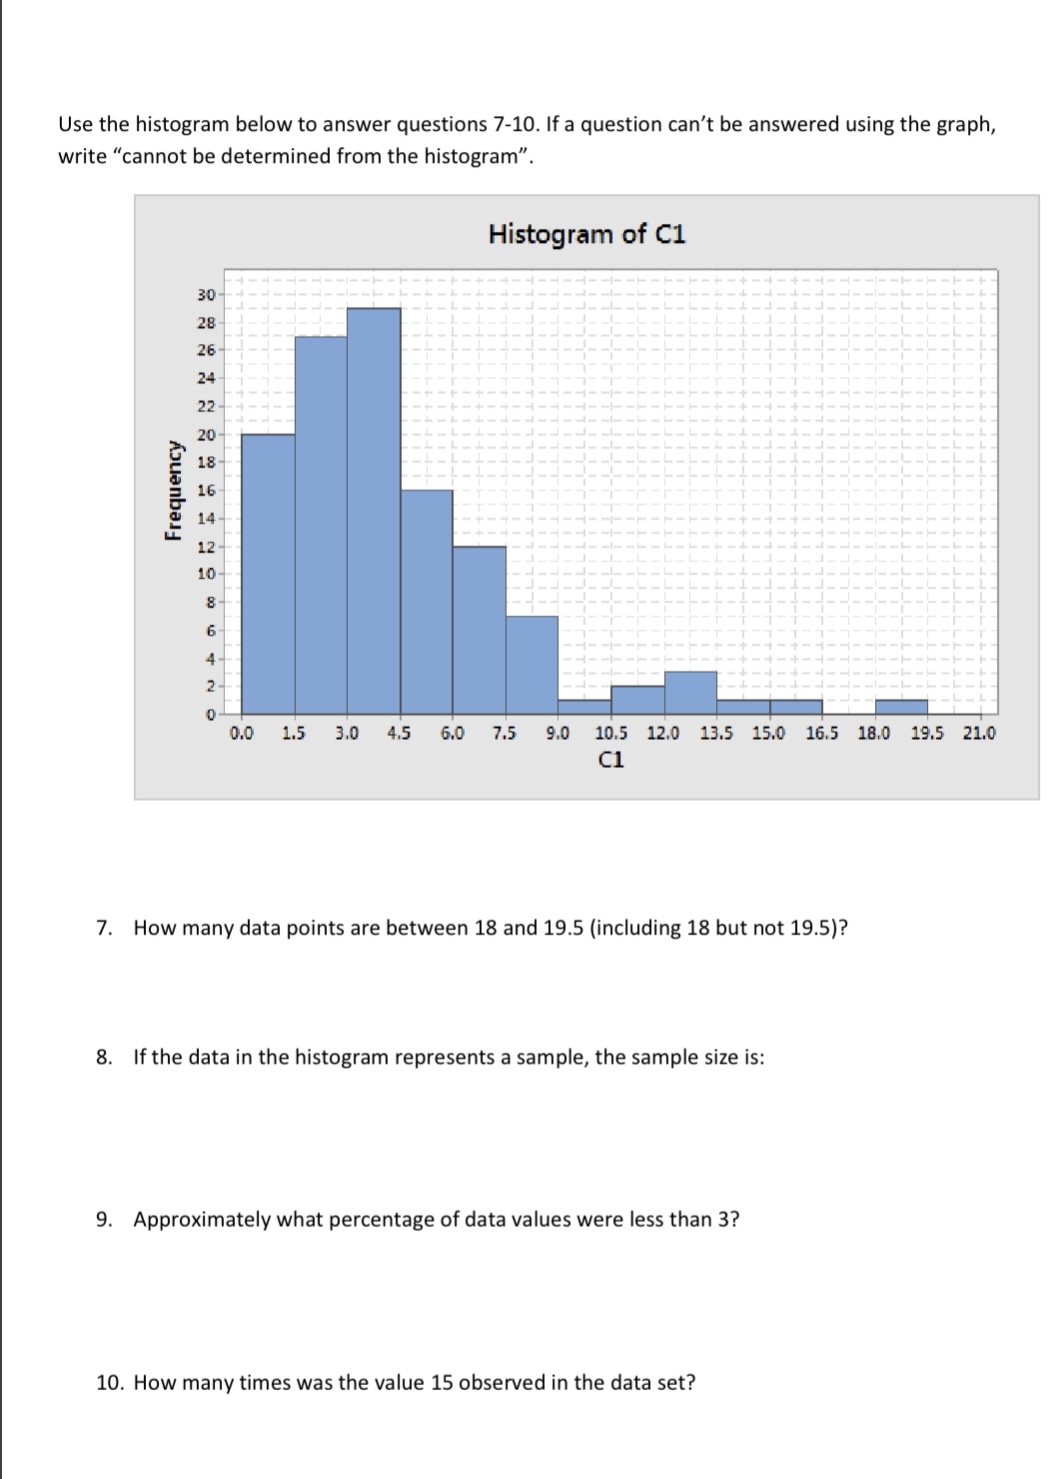
Histograms are one of those tools everyone learns early on and almost nobody actually understands well enough to use correctly. They look simple - bars next to each other showing where your data sits - but there are enough landmines in there that I've seen people produce completely misleading visualizations that passed peer review. The core idea is that you're taking continuous data and binning it into ranges. The height of each bar represents how many observations fall within that range. That's it. Everything else is decisions you make about how to bin, whether your bins are equal width, and what story you're accidentally telling by the choices you make. I spent months cleaning up histogram work from junior analysts at a logistics company where we tracked delivery times across regions. The numbers looked fine on the surface, but someone had set the bin width to one day across a dataset spanning three years. What should have shown a clear bimodal distribution - express versus standard shipping - just looked like random noise with two fat bars in the middle. The fix was recalculating bins using the Freedman-Diaconis rule, which adjusts bin width based on your interquartile range and sample size.
Common Histogram Questions And Answers
Why do my histogram bins look different depending on the tool I use? Every program has a default binning algorithm, and they're not the same. Excel uses Sturges' rule by default, which is basically 1 plus log base 2 of your observation count. It tends to under-bin with large datasets. Python's matplotlib defaults to the square root of n, which is a bit more aggressive but still rough. R's default is Sturges too. If you care about accuracy, don't trust defaults - calculate the bin width yourself using Freedman-Diaconis or pick something based on domain knowledge. Can I use a histogram for categorical data?
No. That's a bar chart. Histograms are for continuous or at least ordinal data where the bins represent ranges on a real number line. The touching bars in a histogram signal that the data is continuous - there's no gap between the bin for 10 to 20 and the bin for 20 to 30. Bar charts have gaps because the categories are discrete. This distinction matters more than people think, and judges, reviewers, and editors notice when you mix them up. What does a right-skewed histogram actually tell me? It means most of your observations are clustered at the lower end with a long tail of higher values. Salary data is the classic example. But here's the counter-intuitive part that trips people up: the mean gets pulled toward that tail, so the mean will be higher than the median. If you're making decisions based on the average from a right-skewed histogram, you're probably overestimating what a typical observation looks like. Report the median instead, or better yet, show both and explain the difference.
Get the Full Details
How do I handle outliers in a histogram? This is where it gets annoying. A few extreme values can stretch your axis so far that the actual distribution becomes unreadable. One approach is to use a log scale on the x-axis, which compresses the tail. Another is to cap the axis at a reasonable percentile - show everything up to the 99th percentile and note that values beyond that exist. I once had to present a histogram of server response times where three requests took over 30 seconds and the rest were under 2 seconds. With a linear scale, the interesting part was crushed into the first three bars. I switched to a log scale and the pattern became obvious - there was a secondary cluster around 800 milliseconds that suggested a second process was competing for resources. Is bimodal distribution always meaningful?
Often, yes, but not always. Two humps usually suggest two underlying populations mixed together. But sometimes it's an artifact of your bin width. I once saw a histogram that looked clearly bimodal, and when I adjusted the bin width by just one unit, the second hump disappeared entirely. It was just a sampling artifact. Always test whether your bimodality is stable across different bin widths before concluding there are two groups in your data. What's the difference between relative frequency and density histograms? A relative frequency histogram shows proportions instead of counts - each bar's height is the fraction of total observations in that bin. A density histogram goes further and scales the bars so the total area equals one. This matters when you want to overlay a theoretical distribution curve or compare histograms with different total sample sizes. If you're comparing a dataset of 100 observations against one of 10,000, raw counts are meaningless for comparison. Density histograms fix that.
How many bins should I actually use? There's no single right answer, but there are wrong answers. Too few bins and you smooth away important structure. Too many and you see noise that isn't signal. The Freedman-Diaconis rule gives you a starting point: bin width equals two times the interquartile range divided by the cube root of n. The Scott rule is similar but uses standard deviation instead of IQR, which makes it more sensitive to outliers. For most practical purposes, I pick between five and twenty bins depending on my dataset size and what I'm trying to show. If someone asks me to justify my choice, I show three different bin counts side by side and pick the one that's stable across variations. Can I compare two histograms visually?

You can, but doing it well requires the same axis scales and the same bin edges. Overlaying two histograms with different scales or different binning is misleading. Density plots overlaid on the same axes tend to work better for comparison because they're not constrained to discrete bins. If you must use histograms, plot them as a back-to-back or dodged histogram with shared axis limits. I usually go with overlaid density curves for quick comparison and reserve histograms for showing the actual data distribution when exact bin counts matter. What about stacked histograms? Stacked histograms are tricky because the top edge of each bar doesn't represent the count for that group - it represents the cumulative total. This makes it hard to compare individual groups across categories. Side-by-side or dodged histograms are almost always clearer. I use stacked only when the total is the story and the individual group breakdown is secondary. Even then, I usually add a legend and label the groups directly on the bars.
One thing I wish more people understood is that histograms are exploratory tools first and presentation tools second. The values you get from a histogram change depending on your starting point and bin width. That's not a bug - it's a feature. You're supposed to iterate. Run the histogram with different bin counts, look for stable features, and only report what persists across reasonable variations. Anything that appears and disappears when you tweak the bin width is probably not worth building a narrative around.