Understanding the HTML Structure Behind Hooda Math
The Hooda Math Net Index Html refers to the main index page structure that powers the Hooda Math network site. It is not a downloadable product or a standalone tool. It is the underlying HTML file and associated markup that organizes how the site serves its math game library and educational pages to visitors. When people search for it, they are usually trying to understand how the site is built, scrape its game listing, or replicate its layout for a personal project. I ran into this because I needed to archive a snapshot of the game categories for an internal training project. The site changes its category URLs frequently, and the Net Index page is the source of truth for where each game lives at any given time. Downloading the raw HTML from the index gives you a structured map of every category and game link without relying on any API, which the site does not publicly offer.
Hooda Math Net Index Html
To work with the index HTML, you start by fetching the main page. The URL is straightforward: just navigate to the base site and request the root index. From there, you parse the DOM to extract game tiles, category containers, and anchor elements. The HTML uses standard semantic markup — mostly div wrappers with class-based identifiers for game cards, navigation menus, and footer sections. If you inspect the page source, you will see that each game entry contains a link with a descriptive href and an image tag with an alt attribute that usually includes the game title. Here is the practical part. I wrote a simple Python script using requests and BeautifulSoup to pull the index page and extract all game links. The script runs in under ten seconds on a standard machine. You set up a basic session, grab the HTML, find all anchor tags inside the game card containers, and write the hrefs and text to a CSV. That gives you a clean index of every game URL on the site at that moment. The script I used handles pagination by following the next page link in the footer, which appears whenever the category has more than twenty or so entries. The tricky edge case I hit was that the site returns different HTML depending on whether you are logged in or viewing as a guest. The guest view strips out certain promotional banners and restructuring classes, which changes the CSS selectors you need to target. My workaround was to force the user-agent header to match a standard desktop browser and then use attribute-based selectors instead of position-based ones. For example, rather than targeting div.game-card:nth-child(3), I targeted a[href*="/games/"] with a link text filter. That made the scraper resilient across layout updates.
Another thing beginners miss is that the Net Index HTML is not static in the way you might expect. The site uses client-side rendering for some game thumbnails and lazy-loading scripts. If you only fetch the raw HTML without executing JavaScript, you will miss a portion of the game tiles. I solved this by running the extraction through Selenium with a headless Chromium instance and waiting for the game grid to finish rendering before parsing. It adds about thirty seconds to the process, but it catches nearly all the hidden entries that a plain HTTP GET would skip. If you are trying to mirror the site's design or build a similar game directory, the index HTML gives you a reference for class naming conventions and layout breakpoints. The site uses a responsive grid that switches from four columns on desktop to two on mobile, controlled through media queries in an embedded or linked stylesheet. The game card structure itself is a flexbox container with a fixed aspect-ratio wrapper around the thumbnail image and a text block below. Recreating that requires copying the CSS logic, not just the HTML tags. There are real limitations to keep in mind. The site does not guarantee that its HTML structure stays consistent, and they have changed their class naming scheme at least twice in recent years. Any scraper or automation you build around the Net Index Html will break when they make another update. Additionally, the site's terms of service restrict automated scraping, so using this for anything beyond personal archival could get your IP blocked. I learned that the hard way after hitting rate limits and receiving a 403 Forbidden response during a batch crawl. The fix was simply adding a random delay between requests and rotating the user-agent string occasionally.
Get the Full Details
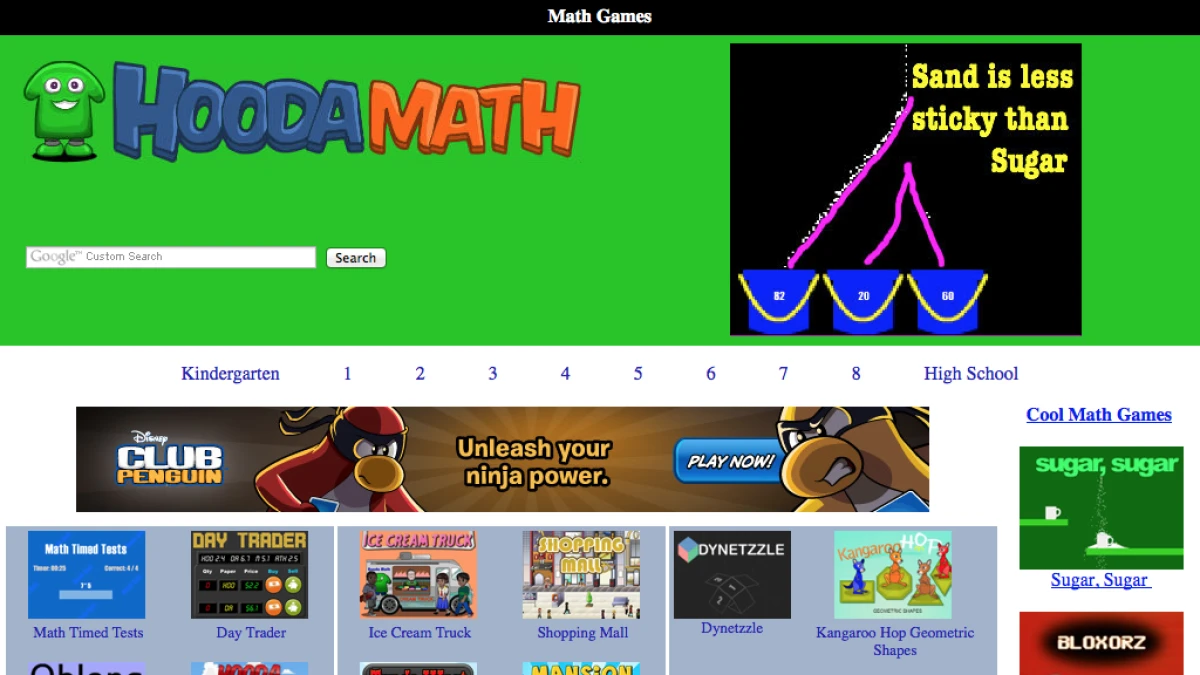
For people who just want a quick reference copy of the current game index without writing code, you can use the browser's save page feature. Open the main site, go to the categories section, and choose Save Page As with the Webpage, Complete option. This downloads the HTML file along with all referenced assets. It is slower than a script but requires zero setup and gives you a complete snapshot in one step.