Getting Peer Groups Right Is The Hardest Part Of Ratio Analysis
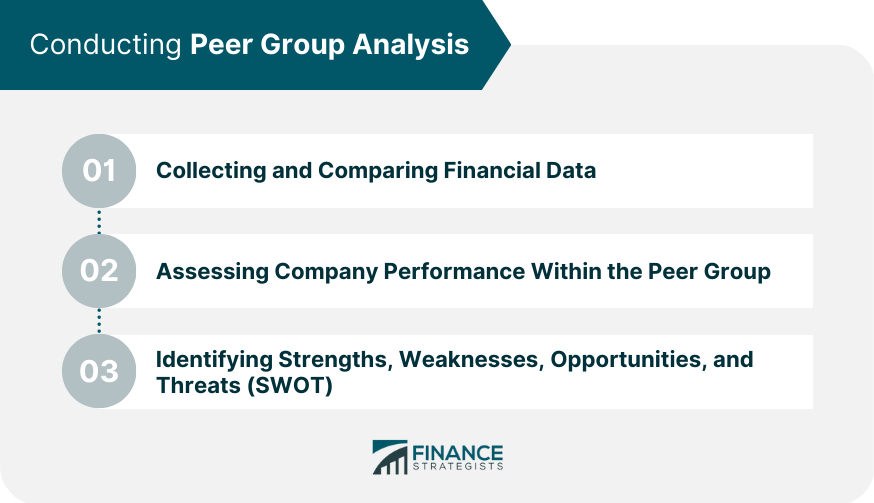
Most people think matching companies together is just looking up a GICS code and calling it done. That is wrong. When I first started building comparable sets for valuation work, I assumed standard industry classifications would give me clean results. They did not. The problem was deeper than anyone admits. The standard approach starts with industry classification systems like GICS or SIC codes. You pull a list of companies in the same four-digit SIC category and call it a peer group. It is technically defensible, but it is often useless. A company classified under retail trade could be a warehouse club, an electronics superstore, or a small specialty retailer. The ratios between those three groups look nothing alike. Revenue multiples will diverge by factors of three or more. Book value ratios break entirely. The better approach uses multiple classification layers. First, you anchor on a broad industry category. Then you layer in revenue size bands. A company generating five billion in revenue operates under very different cost structures than one generating two hundred million. You do not mix them. Then you add a qualitative filter for business model differences. Asset-heavy versus asset-light. Recurring revenue versus transactional. Geographic concentration versus global diversification. Each of these filters carves out a tighter set.
I keep a working spreadsheet that tracks SIC code, revenue tier, capital intensity, and revenue predictability for every company in my watchlist. It takes about twenty minutes per new company to fill out. The actual peer selection usually takes another fifteen minutes once that data exists. Without the initial setup, every selection job stretches to two hours minimum because you are digging for basic operational characteristics from scratch.
The Practical Mechanics
Start by pulling your universe from a screening tool. Bloomberg, FactSet, Morningstar, or even free screens on Finviz will give you a starting list. Export the data. Do not work inside the platform. Export it to Excel so you can manipulate it freely. Apply your first filter. Pick the industry code. If you are analyzing a regional bank, do not include national money-center banks. Their ratio profiles diverge in ways that matter. Net interest margin, loan loss provisions, and capital ratios all move differently. The classification system put them in the same industry group. Your analysis should not treat them as peers. Apply a revenue band. Within your industry slice, break the companies into quartiles or deciles by market cap or total revenue. Keep the band narrow. A ten-to-one spread in revenue size is usually the outer limit for meaningful comparison. Beyond that, the ratios distort because of operating leverage differences that have nothing to do with relative efficiency.
Get the Full Details
Apply the business model filter. This is where most people skip and ruin their work. Look at the actual operations. Does the company lease its stores or own them? Is revenue mostly subscription-based or one-time? How much of its assets are intangible? These details are not captured in any classification code. You have to read the annual reports or press releases to verify them. I typically spend five to eight minutes per company on this step. It prevents the kind of misclassification that silently corrupts every metric you calculate afterward.
A Specific Problem I Ran Into
During a 2019 assignment, I needed peer groups for a mid-market software company that sold both on-premise licenses and a growing cloud subscription product. The GICS code placed it with pure-play software firms. The pure-play software firms had very different margins because their cost structures were almost entirely variable after development. This company still had significant on-premise implementation costs embedded in its COGS. Every EBITDA margin comparison was misleading by twelve to eighteen percentage points. The workaround was to exclude the pure-play software firms entirely and rebuild the peer set from companies with hybrid license-and-service revenue profiles. I found them by manually scanning the segment disclosures in 10-Ks. It added roughly forty-five minutes to the project. The resulting valuation spread tightened from a forty-percent range down to eighteen percent. The original broad peer group had produced a valuation conclusion that was wrong by nearly a third. The extra research time saved the client from a bad decision and me from explaining why the initial analysis was flawed.
Common Pitfalls
The biggest mistake is using public classification codes as the final step instead of the first step. GICS and SIC were built for regulatory and statistical purposes, not for financial analysis. They group by primary revenue source at a level of aggregation that swallows important operational differences. Using them alone produces peer groups that look correct on paper and fail under scrutiny. A second mistake is ignoring company lifecycle stage. A high-growth startup in an industry will have negative free cash flow, high revenue growth, and thin margins. A mature player in the same industry will have stable cash flows and wide margins. Comparing their operating margins directly is meaningless. The ratio tells you nothing about relative efficiency. It tells you about growth phase. Always annotate lifecycle position when you build your peer set. A simple tag like early, growth, or mature prevents this error. A third mistake is assuming peer groups are static. They should not be. Industry boundaries shift. A company might pivot its revenue mix. Mergers change competitive dynamics overnight. I update my peer classifications quarterly at minimum. If a major deal closes or a company reclassifies its segments, I revise the group immediately rather than waiting for the next reporting cycle. The cost of a stale peer group is a ratio comparison that reflects last year's market structure instead of today's.
When Classification Breaks Down
There are cases where peer group classification cannot save you. Conglomerates are the clearest example. A company with unrelated business units has no meaningful peer group because each segment competes in a different industry with different return profiles. The consolidated ratios are a blend that matches no single business model. The workaround is segment-level analysis. Break the company into its reportable segments, find peers for each segment individually, and evaluate the pieces separately. If segment data is insufficient, you cannot do proper ratio analysis on that company. Accept that limitation rather than forcing a broken comparison. Private companies present another breakdown point. They are not subject to the same reporting requirements. Financial statements are often unaudited, incomplete, or prepared under different accounting frameworks. Attempting to build a peer group that mixes private and public companies introduces noise that is nearly impossible to quantify. I recommend keeping private companies in a separate analytical track or relying on transaction comps instead of ratio analysis when the peer set is predominantly private.
What To Do Instead When Standard Classification Fails
If you cannot find a clean peer group through classification alone, fall back to transaction comparables. M&A deal multiples, public offerings, and strategic investments reflect what actual buyers have paid for similar businesses. The data is less abundant than public company multiples, but it is more relevant when industry boundaries are blurry or companies have unique characteristics. I use this approach whenever my manual peer screening yields fewer than five meaningful comparables. Five is the practical floor for ratio analysis. Fewer than that and the statistical signal is too weak to support a conclusion. Another fallback is factor-based clustering. Run a principal component analysis on key ratio dimensions like profitability, leverage, growth, and efficiency across your candidate universe. The output groups companies by financial similarity rather than industry code. It is an objective supplement to manual classification, not a replacement. I run it once when building a new coverage universe to spot outlier groupings that the standard codes miss. The process takes about ten minutes once you have the data extracted. It catches misclassifications that would otherwise go unnoticed.
The Bottom Line
Peer group classification is not a lookup exercise. It is a multi-step filtering process that requires industry knowledge, operational diligence, and periodic revision. The standard codes are a starting point, not an endpoint. Spending an extra thirty to forty-five minutes per peer group during the build phase prevents hours of rework and prevents conclusions that look precise but are fundamentally wrong. The companies that pass your filters should resemble each other in how they make money, not just in what a bureau calls their industry.