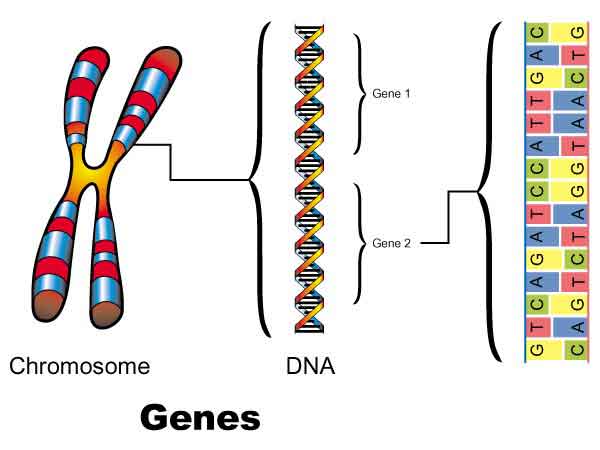
So You Want to Know How Genes Are Produced
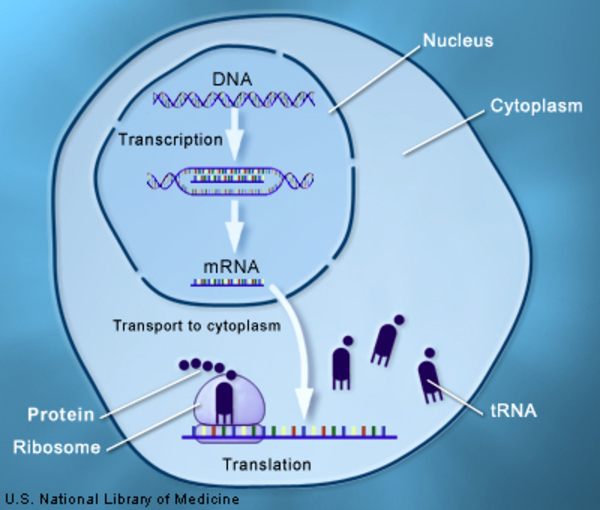
Genes don't just appear out of nowhere. They go through a sequence that most biology textbooks oversimplify into a neat two-step diagram, but anyone who has actually worked with gene expression knows it is messier than that. The basic outline is transcription followed by translation, but the reality involves splice variants, epigenetic regulation, RNA modifications, and quality control checkpoints that can silently kill your entire output before you notice anything wrong. When I first started working with recombinant gene production in a lab setting, I assumed the central dogma was all I needed to understand. That lasted about three weeks. The actual process of getting a gene expressed in a usable quantity starts with the DNA template. That template has to be clean, properly amplified, and free of contaminating sequences that could interfere with transcription. From there, RNA polymerase moves along the DNA, reading the template strand and building a complementary messenger RNA molecule. In prokaries this happens in the cytoplasm. In eukaryotes it happens in the nucleus and the RNA has to be processed before it ever reaches a ribosome. The processing step is where things get complicated. Eukaryotic pre-mRNA gets a 5' cap added, a poly-A tail tacked onto the 3' end, and introns spliced out. The splicing itself is not always clean. Alternative splicing means a single gene can produce multiple different protein products, and the ratio of those products varies by cell type, developmental stage, and environmental conditions. I once spent two weeks troubleshooting a protein that kept coming out as the wrong molecular weight. The gene was being transcribed fine, but the cell line I was using was producing a different splice variant than the reference sequence I had cloned from. The workaround was straightforward but frustrating: I switched to a cDNA template that had the introns already removed and mapped the exact isoform I needed against the genomic coordinates. That cut my troubleshooting time from weeks to about a day.
After the mRNA is mature, translation begins. Ribosomes read the codons in groups of three and recruit the corresponding aminoacyl-tRNAs. The growing polypeptide chain emerges from the ribosome and starts folding. This folding is not always correct. Misfolded proteins get tagged for degradation through the ubiquitin-proteasome pathway or, in the case of secreted proteins, through ER-associated degradation. Chaperone proteins like Hsp70 and the chaperonin complexes help guide folding, but they are not infallible. One thing most people miss when they are learning about gene production is that transcription and translation are not simply rate-limited by how fast RNA polymerase or the ribosome moves. They are heavily influenced by codon usage bias. If your gene has a sequence rich in rare codons for the host organism you are expressing it in, the ribosome will stall. Those stalls trigger premature termination, truncated products, and overall very low yields. The fix is usually codon optimization, but even that has limits. Over-optimizing a gene by swapping every rare codon for the most common synonym can actually make things worse because it removes natural pausing sites that are important for proper protein folding. I have seen people waste months on expression constructs that looked perfect on paper but produced nothing because they had over-optimized past the point of utility. Another counter-intuitive point: having the right gene sequence does not guarantee the gene will be produced at the right level. Promoter strength, enhancer elements, chromatin state, and transcription factor availability all matter. In mammalian cell culture, a gene inserted randomly into the genome often sits in heterochromatin and gets silences over successive passages. The standard workaround is using site-specific integration systems like piggyBac or CRISPR-mediated targeted knock-in to a safe harbor locus like AAVS1 or CCR5. These are more work upfront but they give you stable, predictable expression over many passages instead of the kind of drift that makes batch-to-batch comparison impossible.
Common Pitfalls in Gene Production
The biggest practical problem I see is people treating gene production as a linear pipeline. It is not. There are feedback loops everywhere. Protein product can repress its own transcription through negative feedback. Accumulated misfolded protein triggers the unfolded protein response, which downregulates general translation and upregulates chaperones. Metabolic burden from high-level expression slows cell growth and can select for mutants that have deleted or mutated your gene entirely. I have had cultures where the plasmid-bearing cells were outcompeting the plasmid-free cells for the first five passages and then the plasmid-free fraction took over completely because the metabolic cost of maintaining the insert was too high. Removing antibiotic selection pressure is the usual trigger for that, so if you are doing long-term culture without selection, expect instability. Bacterial expression systems are faster and cheaper but they lack post-translational modifications like glycosylation. Mammalian systems handle glycosylation correctly but grow slowly, are expensive, and have lower throughput. Yeast sits somewhere in the middle and can do some glycosylation, but the glycan structures are typically high-mannose and differ from human patterns unless you engineer the strain. If you need a therapeutically relevant glycosylation profile, you are usually looking at HEK293 or CHO cells, and you should budget accordingly in terms of time and cost. Quantitative real-time PCR is the standard way to measure gene expression at the RNA level, but it only tells you about transcript abundance, not about how much functional protein you actually got. Western blotting gives you protein-level data but is semi-quantitative at best unless you run proper standards. Mass spectrometry is the most accurate for absolute quantification but requires specialized equipment and expertise. I recommend running at least two of these methods in parallel rather than relying on any single readout.
Get the Full Details
A Note on Industrial-Scale Production
Scaling from a lab flask to bioreactor is where theory falls apart completely. What works in a T75 flask does not translate directly to a 500-liter stirred tank. Oxygen transfer rates, mixing gradients, shear stress, and foam formation all change the expression profile. I once saw a clone that gave excellent results in shake flask but produced less than five percent of the target protein in a pilot bioreactor because the promoter was sensitive to dissolved oxygen levels and the bioreactor conditions happened to repress it. The solution involved shifting to a different promoter system and adjusting the aeration strategy, but it required running a full design-of-experiment matrix rather than just scaling up parameters linearly. If you are working on gene production for research purposes, the main bottlenecks are usually around vector design, host strain selection, and expression condition optimization. If you are working toward a commercial product, you also have to deal with regulatory requirements, batch consistency, and analytical method validation. Those layers add months or years to the timeline and require a different skill set than pure molecular biology. The bottom line is that gene production is a multi-variable system with a lot of room for silent failures. The sequence matters, the host matters, the culture conditions matter, and the readout method matters. Understanding how each layer interacts with the others is what separates someone who gets reproducible results from someone who spends their career chasing artifacts.