Understanding Large Numbers Without Losing Your Mind
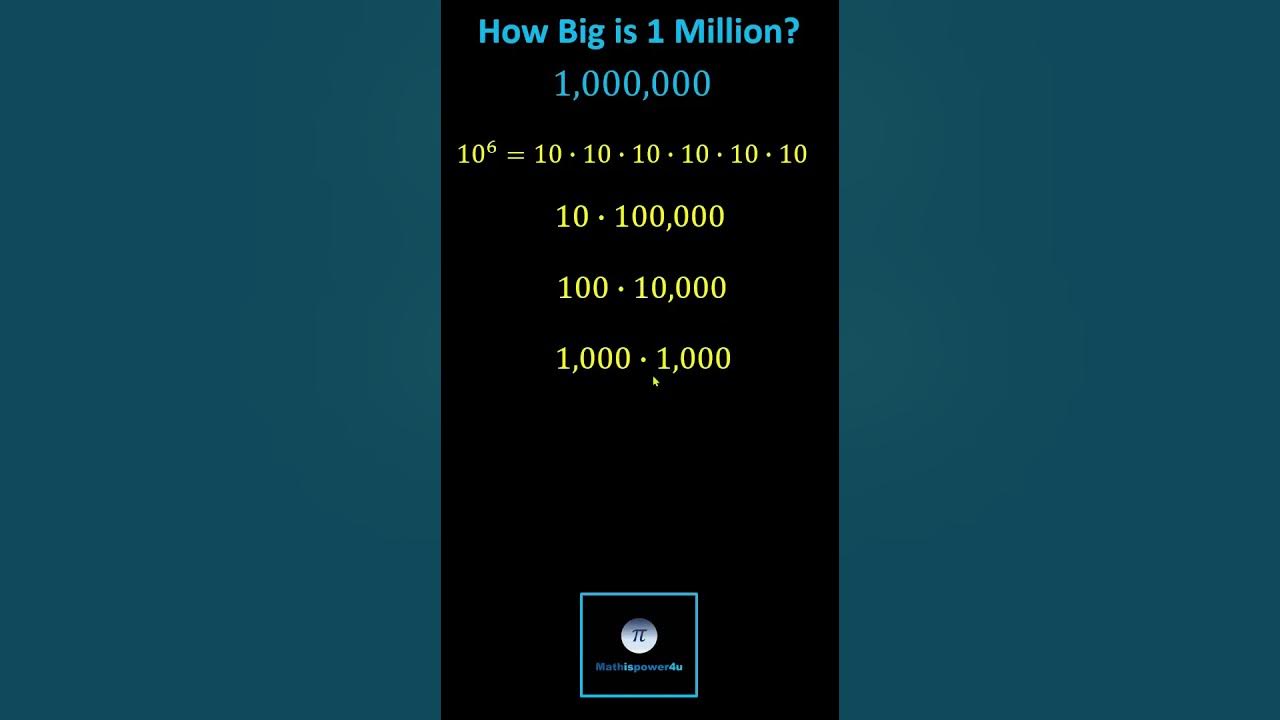
A million is 1,000 times 1,000. That's the basic arithmetic. The reason people struggle with it isn't the math, it's that human brains are wired for small-scale intuition. We evolved to track packs of animals, not seven-figure sums. When someone says "a million dollars" or "a million views," most people just sort of feel like it's a lot and move on. That's fine in casual conversation. It falls apart fast when you're actually working with these numbers. I used to work in data processing, and one of my early jobs was reconciling transaction logs for a payments platform. We hit a case where a vendor's billing system was generating duplicate invoices at roughly 1.4 million per month. On paper, it looked like a minor glitch. In practice, the sheer volume meant our reconciliation pipeline couldn't keep up, and we were sitting on $8 million in unprocessed transactions before anyone caught it. The workaround was straightforward but ugly: I wrote a script that flagged duplicate merchant IDs and transaction timestamps within a 30-second window, then batch-flushed them into a holding queue for manual review. It took me about six hours to write and test. The fix cut our monthly processing backlog from roughly 40 hours of manual work down to maybe two. You learn pretty quickly that when numbers get that big, the problem stops being mathematical and starts being logistical.
How Big Is A Million
There are a few practical ways to internalize the scale, and most of the usual shortcuts don't actually help. The most reliable method I've found is temporal anchoring. Counting one number per second, a million seconds works out to roughly 11.57 days. Not a year. Not forever. About two weeks of nonstop counting. This matters because people routinely conflate millions with years when they're thinking about budgets or project timelines. A million seconds is two weeks. A billion seconds is about 31.7 years. That gap between how these numbers feel and how they actually behave is where mistakes happen. Another useful frame is money, but only if you use physical money. Stack a million dollar bills. A single bill is about 0.0043 inches thick. Multiply that out and you get roughly 358 feet. That's taller than the Statue of Liberty from pedestal to torch. Now stack a million pennies instead. Same count, way less height because pennies are thicker and you need a million of them for only $10,000. The visual difference matters because it shows why people underestimate the weight of large counts when units change. A million something isn't always the same kind of effort depending on what the something is worth.
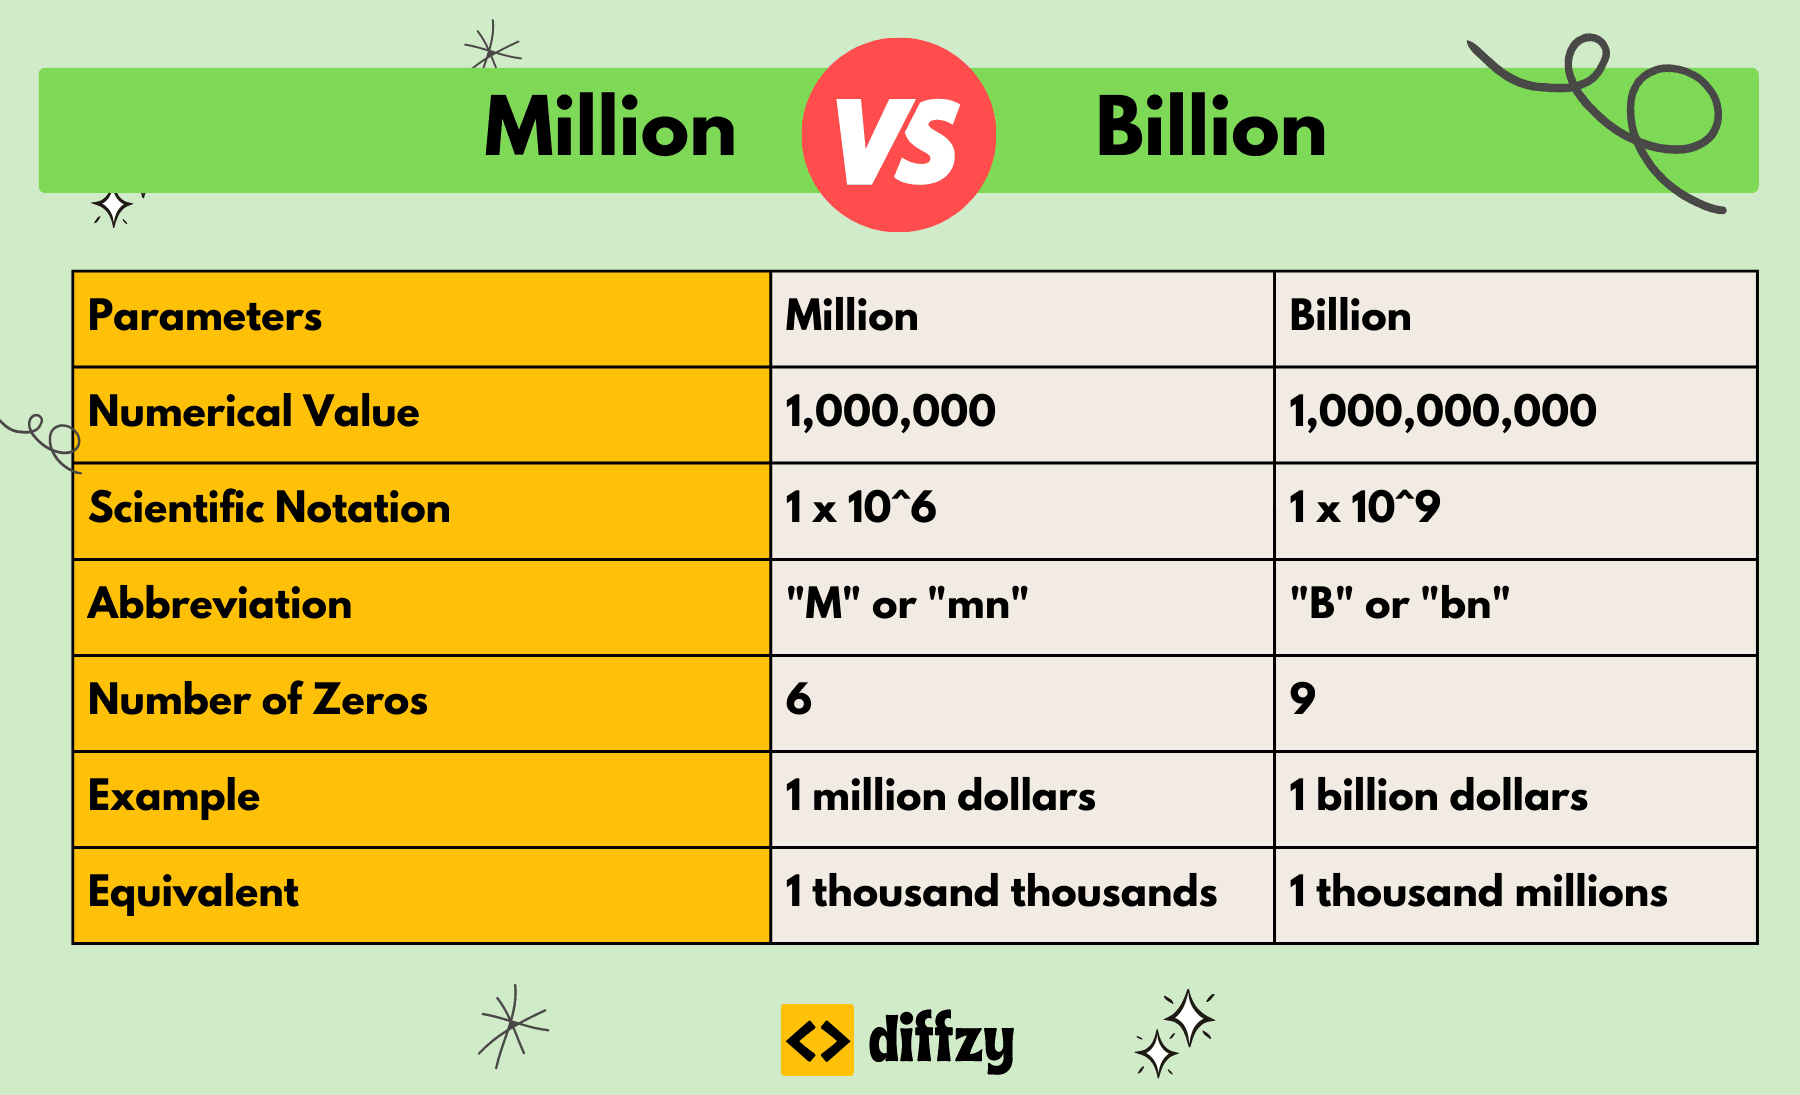
Scale drift is the real trap here. It's the gradual numbness that sets in once you stop paying attention. You see a report saying a project has a million user interactions and your brain automatically categorizes it as "big" without checking whether that million is concentrated or spread thin. In my experience, a million interactions spread across three years looks completely different from a million interactions in a single quarter. The first one is background noise. The second one will crush your support team and your incident response process if you aren't prepared for it. I've seen both versions of this play out, and the quarter-concentrated version is always the one that surprises people. For quick mental math, you can use the powers-of-ten trick. A million is 10 to the 6th power. A billion is 10 to the 9th. A trillion is 10 to the 12th. Each jump is exactly 1,000x. If you ever need to estimate comparisons, just count the zeros. Six zeros, nine zeros, twelve zeros. No calculator required. This also helps you catch when someone is mixing scales accidentally. I once reviewed a marketing deck that claimed a campaign would reach "a billion people" but the actual math on their funnel only supported about 800,000 impressions. They were off by a factor of roughly 1,250. Someone just miscounted zeros. This happens more often than you'd think, especially in slide decks where the numbers get larger between revisions without anyone rechecking.
Get the Full Details

When the Numbers Break Down
Millions are straightforward until they interact with systems that weren't built for them. Database indexing becomes a real concern past a few million rows if you're not careful about your schema. Query times climb in ways that aren't linear, so a query that takes 200 milliseconds on a test database with a hundred thousand rows might take 12 seconds on production with eight million rows, even on the same hardware. I learned this the hard way when we moved a reporting table from staging to production and a handful of analytics queries that had always completed in under a second suddenly queued behind each other and started timing out. The fix was adding a composite index on the two columns that the queries filtered on, which brought execution times back down to roughly 300 milliseconds. Indexing isn't magic. It has write-cost overhead and maintenance requirements. But for read-heavy workloads at this scale, it's usually the right call. Financial modeling with millions introduces its own set of issues. Compound interest calculations become sensitive to rounding errors when you're running them across millions of accounts. A tiny per-unit rounding discrepancy compounds across the population. We saw this with a rewards program where the system rounded fractional points down to the nearest whole number at the transaction level. Across roughly 2 million active accounts, that meant we were silently redistributing about $40,000 per month in fractional point value that never actually reached users. It wasn't intentional, just an oversight in the rounding logic. Switching to a rounding mode that distributed the fractional remainder proportionally eliminated the discrepancy. The point isn't that rounding is evil. It's that at million-scale, small rounding decisions accumulate into material financial differences. There's no clean solution for every situation. When you're dealing with massive datasets, sometimes the honest answer is "don't process it all at once." Sampling, stratified or otherwise, can get you 95 percent of the insight with 5 percent of the compute cost. I use this approach whenever I need a quick read on a dataset that's genuinely too large to iterate on comfortably. Grab a random stratified sample, run your analysis, then validate the results against a second sample if the stakes are high. It's not ideal for regulatory or compliance work where you need full population coverage, but for exploratory analysis it saves hours every single time.
Online calculators exist for converting between units at million-scale, and they're fine for rough work. The Calculator.net million tool gives quick conversions for time, distance, and currency equivalents. It's not precise enough for accounting, but it's useful for sanity checks when you're knee-deep in a spreadsheet and need to know whether a number you're looking at is reasonable. I keep it bookmarked for that exact purpose. The bottom line is that a million is a specific quantity, not a vague impression. Once you start working with it regularly, you develop a sense for when it's small, when it's large, and when it's going to cause problems. The problems almost always come from treating the number as abstract rather than operational. A million records is a database problem. A million dollars is a cash-flow problem. A million users is an infrastructure problem. The number itself doesn't change. What changes is what you actually have to do with it.