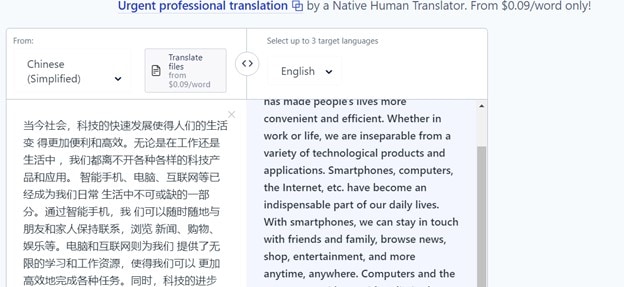
The Honest Way To Translate Chinese Text Without Wasting Hours
How Can I Translate Chinese Writing To English
Picking the right tool matters more than you think. If you paste raw Chinese into Google Translate and copy the output verbatim, you get something readable enough to understand the gist but unusable for anything formal. I learned that the hard way back in 2019 when a client sent me a 40-page product manual in simplified Chinese and I assumed machine translation would cover it. It did not. The opening paragraph alone had three mistranslated technical terms that made the assembly instructions read like nonsense. I spent six hours manually fixing errors that a slightly better workflow would have caught instantly. The process breaks down into three stages: detection, segmentation, and post-editing. You skip one of those at your own risk. Machine translation engines today handle Chinese remarkably well for straightforward content, but Chinese is structurally different from English in ways that matter. There are no spaces between words. There is no verb conjugation or tense marker built into the grammar. Punctuation conventions differ. Classical Chinese idioms and four-character phrases carry meaning that literal word-for-word translation destroys. Start by identifying what type of text you are working with. Is it conversational, legal, technical, literary, or marketing copy? The tool you pick should match the genre. For technical documentation, DeepL tends to produce more coherent results than Google Translate, mostly because its training data includes more bilingual technical manuals. For casual content, Google is fine. I run a personal rule here: never trust raw MT output for legal or medical text without a professional human review pass.
Tools That Actually Work
DeepL remains my default for most work. The free tier gives you 500,000 characters per month. The pro tier runs about €8.49 monthly. You can also use their desktop application, which supports drag-and-drop documents in DOCX, PDF, and PPT format without losing most of the original formatting. I find that saving the original document as DOCX before uploading preserves table structures better than converting to PDF first. Google Translate has improved substantially since 2020. The neural machine translation model they deployed handles collocations better now. Their API pricing is more generous for high-volume work if you need it. You pay roughly $20 per million characters, which is cheaper than DeepL pro for large projects. I do not use Google Translate directly in the browser anymore. I route it through Google Cloud Translation API so I can batch-process documents and script automated quality checks. For classical or highly formal Chinese, neither tool performs adequately. You will need a human translator or at minimum a hybrid workflow where MT does the first pass and a native speaker fixes the output. This is not a failure of the technology. It is a limitation of the source material. Classical Chinese compresses information so densely that any sentence can legitimately map to multiple English interpretations. An algorithm picking the highest-probability rendering will occasionally choose wrong, and you cannot reliably predict which one.
The Segmentation Problem
This is where most people fail. Chinese text has no word boundaries marked by spaces. MT engines attempt word segmentation internally, but they make mistakes, especially with proper nouns and domain-specific terminology. A single incorrect segmentation decision can cascade into a completely wrong translation downstream. The fix is to pre-segment or post-edit the segmentation. I keep a running glossary file in CSV format with my project-specific terms and their approved English equivalents. When using the DeepL API, you pass these terms through the formality and glossary parameters. Google Cloud Translation API accepts a term set via TMX or a simple key-value list in the request payload. If you are using the desktop apps instead, export your term list from a spreadsheet and manually cross-check the output against it. It takes time, but catching a mistranslated product name once saves you from repeating the same error fifty times across a document. I worked on a localization project last year where the source text contained the Chinese brand name "" referring to NIO, the electric vehicle company. The MT consistently translated it as "" with a pinyin note, which the client rejected outright. After adding the term to the glossary, the engine started outputting "NIO" consistently. One glossary entry fixed a problem that would have required manual correction in seventeen different paragraphs.
Get the Full Details
Post-Editing Workflow
After the MT output lands, you need a second pass. This is called post-editing, and the depth depends on your use case. Light post-editing aims for communicative adequacy. The reader understands the intended message. Heavy post-editing approaches publishable quality. For most business communication, light post-editing is sufficient. For legal contracts, you need heavy post-editing plus a separate legal review by a qualified professional. I structure my post-editing in two passes. First, I read through the entire translated document focusing only on meaning accuracy. I fix mistranslated terms, incomplete sentences, and obvious omissions. Second, I do a language pass for fluency, checking for awkward phrasing that technically conveys the right meaning but reads like translationese. Chinese tends to produce run-on sentences in English because Chinese syntax allows longer clauses without punctuation breaks. I break those into shorter English sentences. Not every MT error is obvious on first read. I typically spend twenty to thirty minutes on a fifty-page document for light post-editing, depending on the text complexity.
When Machine Translation Fails Completely
There are scenarios where MT should not be used at all. Poetic or literary Chinese writing depends on rhythm, historical allusion, and phonetic patterns that no engine reproduces. Song dynasty poetry, modern Chinese literature, and advertising slogans with wordplay are examples. I encountered this with a literary translation project where the author used classical references woven into contemporary dialogue. The MT rendered the references literally, stripping all contextual meaning. The translator on that project spent more time researching the allusions than translating the dialogue itself. That is the nature of the work. MT provides nothing useful as a starting point for literary translation. Another hard case is highly localized dialect content. Standard Mandarin translates reasonably well. But if your source text contains Shanghainese, Cantonese, or regional slang embedded in otherwise standard Chinese, the MT will either ignore the dialectal coloring or translate it into generic Mandarin-equivalent English. There is no reliable workaround except direct translation from the dialect, which requires a bilingual translator comfortable with both the regional Chinese and the target English variety.
A Practical Setup
Here is what I actually use for most projects. I take the source document, check its format, convert to DOCX if needed, upload to DeepL with the glossary applied, download the result, and run it through a light post-edit pass in Word. For very large batches, I automate the upload-download cycle with a Python script calling the DeepL API, process the output with a basic regex filter to catch any remaining untranslated segments, and then do the human post-edit pass. The automation saves me about forty percent of the time compared to manual upload and download for a hundred-page document. If you need to translate Chinese to English on a regular basis, investing in the DeepL pro plan plus building a project-specific glossary will save you more time than any shortcut. The upfront effort of compiling that glossary pays for itself after the third document you process with it. I still maintain a glossary that has grown over seven years of this work. It is probably the single most useful artifact in my workflow.