Getting the Mean Right Without Overcomplicating It
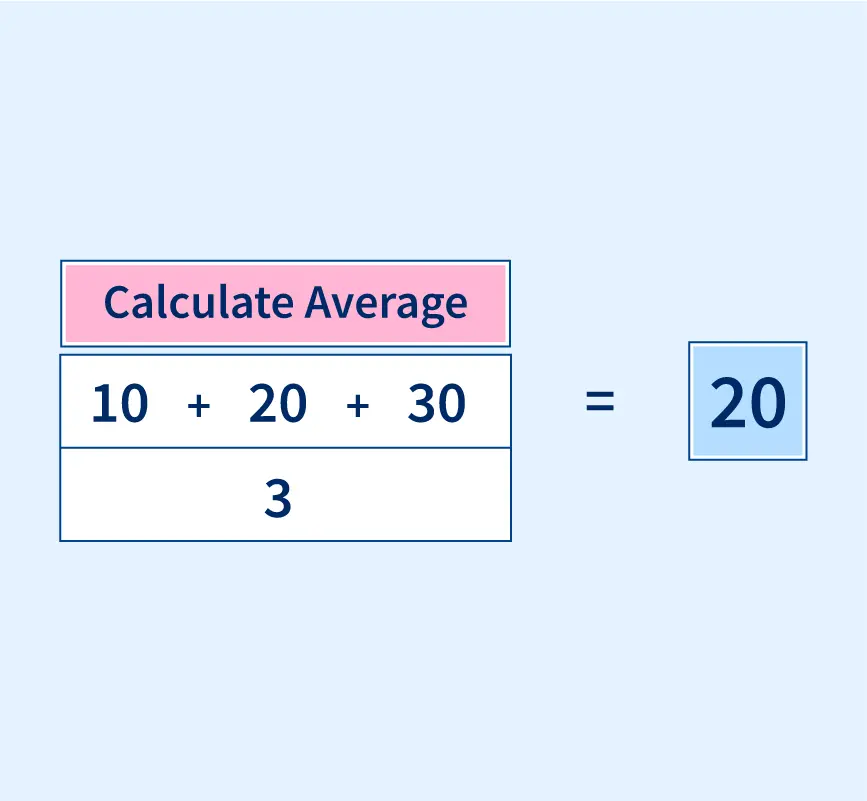
Most people treat the average like it's just addition and division. It is, in the simplest case. But anyone who's actually worked with real data sets knows that "average" means something very different depending on what you're looking at and why. I've spent years watching people use averages incorrectly in business reports, scientific studies, and casual conversations, and the mistakes are usually either about which average to pick or how to handle edge cases before you even start crunching numbers. The arithmetic mean is what everyone learns in school. Add up all your values, divide by how many values there are. If you have the numbers 4, 7, 12, 3, and 14, you sum them to get 40, divide by 5, and your average is 8. That's straightforward enough. The problem comes when you assume this is the only way to calculate average, or when your data set has features that make the standard approach misleading.
How Can We Calculate Average in Real-World Scenarios
There are three main types of averages you need to know about, and picking the wrong one is the most common mistake I see. The mean, the median, and the mode serve different purposes. The mean is sensitive to outliers. If you're calculating average salary at a company where most people make between $40,000 and $60,000 but one executive makes $2 million, the mean will be nowhere near what a typical employee earns. The median, which is just the middle value when you sort everything in order, would tell you something much more useful in that situation. The mode is the value that appears most frequently, which matters when you're dealing with categorical data or when you need to know the most common outcome rather than the central tendency. I remember working on a project a few years back where we were calculating the average processing time for a batch of transactions. The numbers looked fine at first glance, but when I plotted the distribution, I saw a long right tail caused by a handful of extremely slow queries. The mean came out to about 2.3 seconds, but the median was closer to 0.8 seconds. Using the mean for capacity planning would have been a disaster because 90% of our transactions were well under that 2.3 second figure. I ended up going with the median plus the 90th percentile for our benchmarks instead, and that gave us a much more realistic picture of what our users actually experienced.
Dealing with Weighted Averages
Simple averages assume every data point carries equal importance. That's almost never true in practice. When you're looking at things like grade point averages, stock indices, or cost calculations, some values matter more than others. A weighted average accounts for this by multiplying each value by a weight that reflects its relative importance, summing those products, and then dividing by the sum of the weights. For example, if you're calculating a student's GPA and they take a 4-credit math course and a 3-credit English course, the math grade should count more toward the overall average. Say they got a B (3.0) in math and a B+ (3.3) in English. The weighted average would be (3.0 times 4 plus 3.3 times 3) divided by 7, which gives you about 3.13, not the simple average of 3.15. The difference seems small, but it matters when you're making decisions based on these numbers, especially over larger datasets. I once reviewed a financial model where someone was averaging monthly expenses across departments without weighting for headcount. A department with 50 people having an average expense of $200 per person looked the same as a department with 5 people averaging $2,000 each. The unweighted average of the two department figures was $1,100, which made it seem like spending was normal across the board. The truth was one department was spending four times per person compared to the other. Weighting by employee count changed the picture entirely and revealed a budget issue that would have been invisible otherwise.
Get the Full Details

Common Pitfalls and What to Watch For
One issue that comes up constantly is the difference between averaging averages. If you have multiple groups and someone gives you the average for each group, you can't just average those averages together unless all the groups are the same size. This sounds obvious but I see it all the time in reports. A company might report average customer satisfaction scores from five regions and then an analyst averages those five scores to get a company-wide number. If one region has 10,000 customers and another has 500, the smaller region's score gets equal say in the final number, which distorts the result completely. Missing data is another practical headache. What do you do when a few values in your dataset are missing? The naive approach is to just exclude those entries and calculate the average from what's left. That works fine when the missing data is random, but if the missingness is related to the values themselves, you introduce bias. I encountered this when analyzing server uptime logs. The missing entries weren't random gaps in the data, they were situations where the monitoring system failed and didn't log anything. Excluding those entries made the uptime look artificially high because the system was actually down during periods it simply stopped reporting. I had to cross-reference with other monitoring sources and estimate the gaps before computing the average. Time-based averages also deserve attention. If you're averaging monthly sales figures over a year, each month has equal weight regardless of how many days it has. February contributes the same as July even though it's shorter. This rarely matters for rough estimates, but if you need precision, daily averages or a simple sum divided by total days will give you a more accurate picture.
Practical Tools and Approaches
You don't need a statistics degree to compute averages correctly these days. Spreadsheet software handles basic means and weighted averages without any trouble, and it does the arithmetic reliably so you don't risk calculation errors. Excel and Google Sheets both have built-in functions for mean, median, and mode, as well as weighted average capabilities through formulas. For larger datasets, programming languages like Python with libraries such as NumPy or pandas make the process faster and less error-prone, especially when you need to handle messy real-world data with missing values or outliers. When I'm working with raw data that needs cleaning before averaging, I usually run through a quick pipeline. First, I load the data and inspect the distribution to understand what I'm dealing with. Then I handle missing values based on whatever pattern I can identify. After that, I decide whether the mean, median, or a trimmed mean makes the most sense for my use case. A trimmed mean, which removes a certain percentage of the highest and lowest values before calculating the average, is useful when you suspect outliers but still want to use the mean's properties. I typically trim around 5 to 10 percent from each end, depending on how noisy the data is. For the average calculation itself, the method depends on your environment. In a spreadsheet, the AVERAGE function covers the basics, AVERAGEIF lets you filter by conditions, and you can construct weighted averages with SUMPRODUCT divided by SUM. In Python, numpy.mean gives you the arithmetic mean quickly, numpy.average handles weights, and pandas has similar functions integrated into DataFrames with groupby capabilities that are helpful when you need to calculate averages across categories. Database queries can compute averages directly with SQL's AVG function, which is efficient when your data lives in a database and you don't need to move it elsewhere.
When Averages Lie to You
The most important thing to understand is that an average can completely obscure what's happening in your data. Two datasets can have identical means but wildly different distributions. One might have values tightly clustered around the average, while the other could be bimodal with most values at the extremes. This is sometimes called Simpson's paradox when aggregation reverses an apparent relationship, but even simpler cases can be misleading. If you're making decisions based solely on an average without understanding the underlying distribution, you're probably making suboptimal choices. Range and variance matter just as much as the average in many situations. Two teams might both average 100 units of output per day, but one team consistently hits 100 while the other alternates between 50 and 150. For resource planning, the second team is much harder to work with even though the averages are identical. I always recommend looking at standard deviation or at least the min and max values alongside whatever average you calculate. It takes about thirty seconds more and prevents a lot of costly misunderstandings. Geometric means come up in specific situations that the arithmetic mean doesn't handle well. Growth rates are the classic example. If your investment goes up 50 percent one year and down 50 percent the next, the arithmetic average of those returns is 0 percent, suggesting you broke even. But you actually lost money because you started with $100, went to $150, and then dropped to $75. The geometric mean of the growth factors (1.5 and 0.5) gives you the correct average annual return, which in this case is about -13.4 percent. This distinction matters in finance, biology for average growth rates, and any domain where compounding effects are present.

The Bottom Line
Calculating an average sounds simple because it often is, but getting it right requires paying attention to what your data actually looks like before you run any formulas. Know whether your values should be weighted equally. Check for outliers and decide whether to exclude or transform them. Make sure your averaging method matches the question you're actually trying to answer. The difference between a reliable average and a misleading one is rarely the math, it's usually the choices you make before and after the calculation.