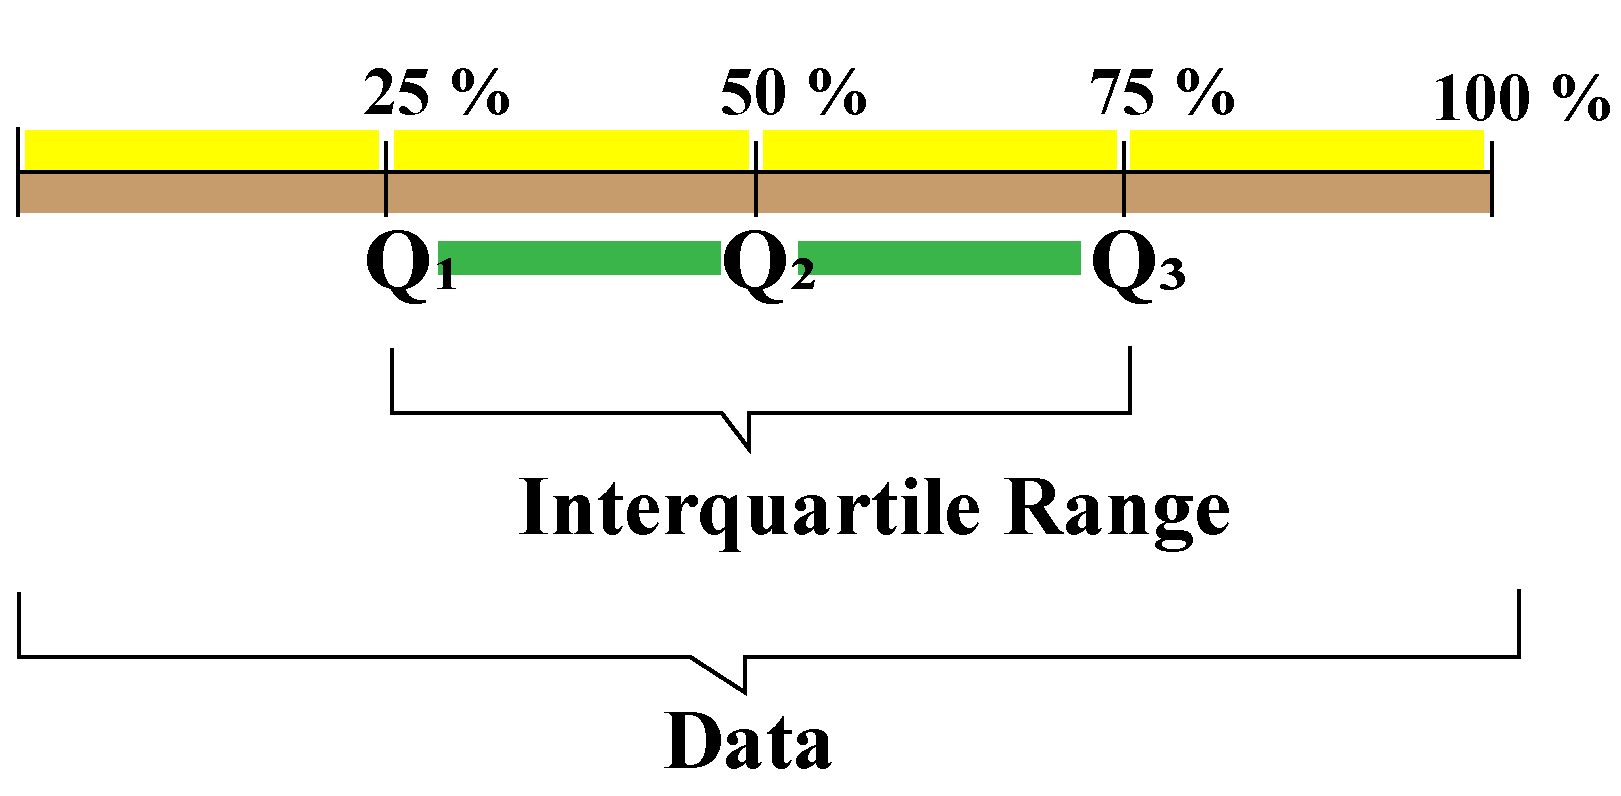Working with Quartiles in Real Data
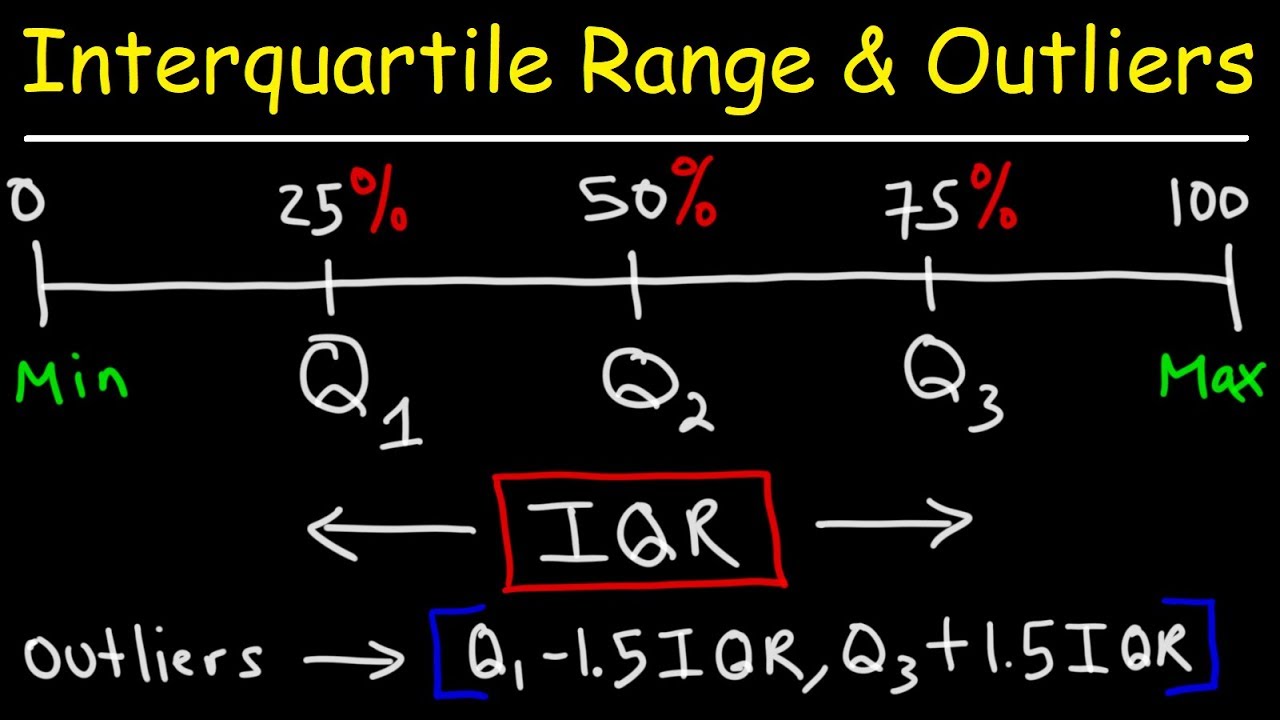
The interquartile range is just the spread between the 25th percentile and the 75th percentile of a dataset. Most people I see online are confused because their textbook and their calculator give different answers for Q1 and Q3. That's not a bug, it's a feature of how different methods handle the middle value when the dataset has an odd number of items. You need to pick one method and stick with it, because switching between them mid-analysis will change your results without you realizing it. Here's what actually happens when you're processing data in practice. I spend a lot of time cleaning survey data and financial records, and IQR comes up constantly for outlier detection. The method I use is the exclusive method, which excludes the median from both halves when you're splitting the data. There's also the inclusive method where the median gets folded back into each half. The difference matters more than most people think, especially with small datasets under 20 observations.
How Do I Find The Interquartile Range in Practice
Take your raw numbers and sort them from smallest to largest. This sounds obvious but I've lost count of the times I've seen people skip this step and get completely wrong answers because they were working with unsorted data from a spreadsheet dump. Once sorted, find the median, which splits your data in half. If you have an odd count of values, the median is the middle number itself. If you have an even count, it's the average of the two middle numbers. Now split the data into a lower half and an upper half. Using the exclusive method, the median value does not belong to either half. So if your sorted data is 3, 5, 7, 9, 12, 15, 18, the median is 9. The lower half is 3, 5, 7 and the upper half is 12, 15, 18. Q1 is the median of the lower half, which is 5. Q3 is the median of the upper half, which is 15. IQR equals 15 minus 5, giving you 10. With an even count like 2, 4, 6, 8, 10, 12, 14, the median is 8. The lower half becomes 2, 4, 6 and the upper half becomes 10, 12, 14. Q1 is 4, Q3 is 12, IQR is 8. Same structure, just a different split point.
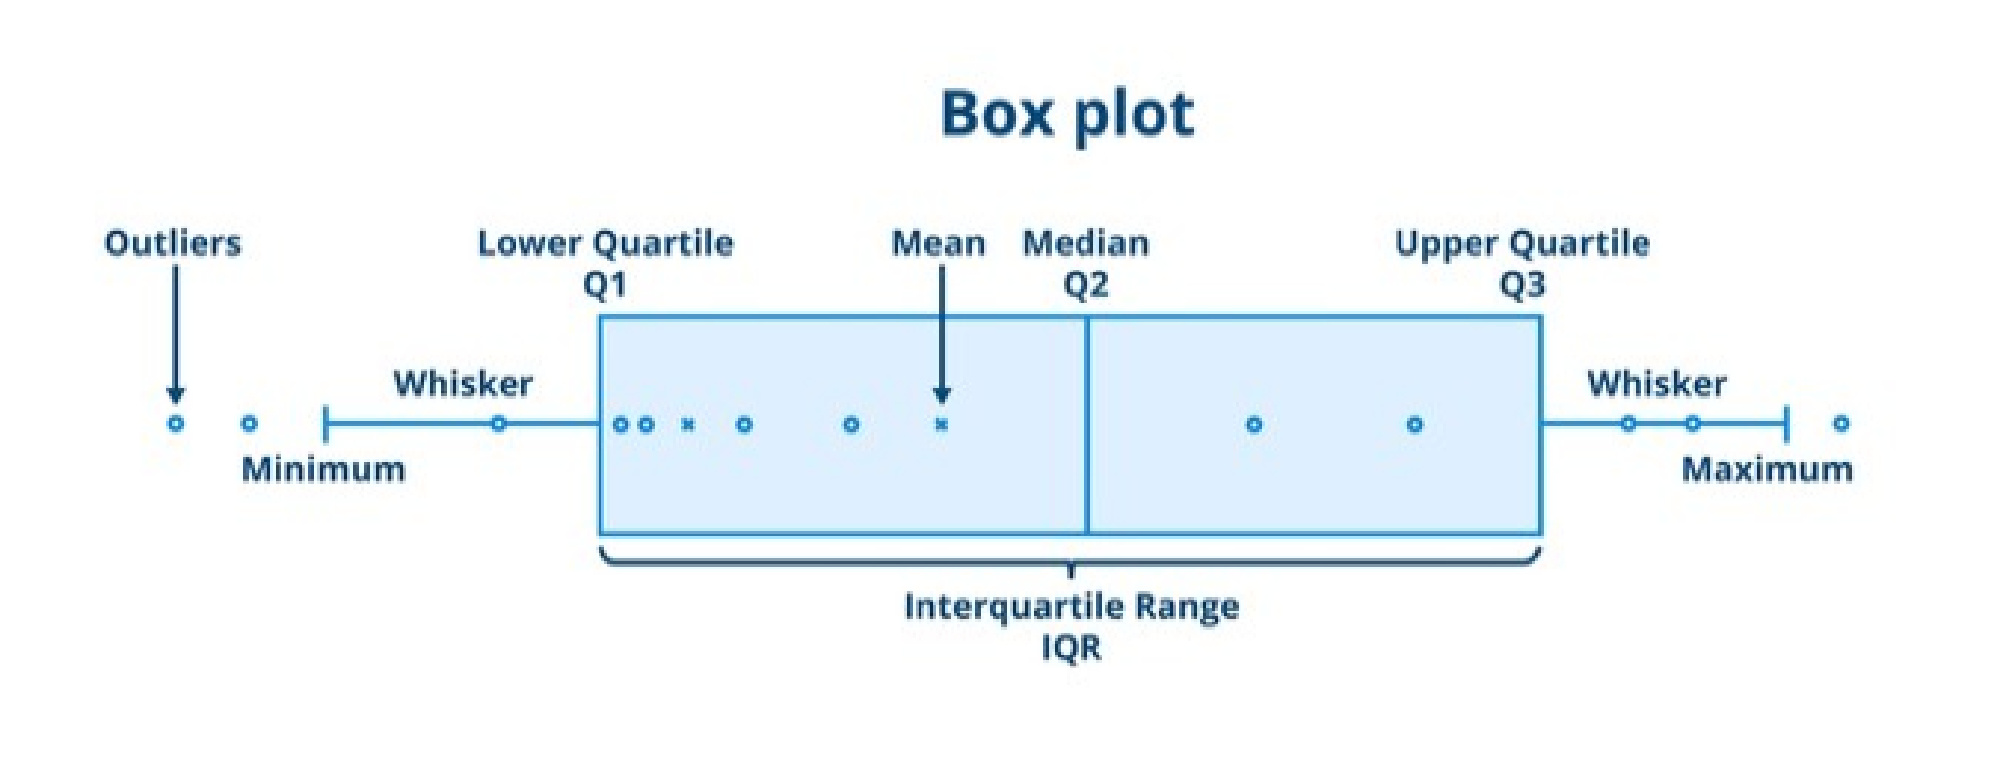
One thing that trips people up is when your dataset has duplicate values at the quartile boundaries. Say you're looking at response times and your sorted data has multiple entries of the same number right around where Q1 should fall. The percentile calculation doesn't break, but the interpretation changes. Two datasets can have the same mean and standard deviation but wildly different IQRs because one has clustered outliers and the other has them spread out. That's why IQR is actually more useful than standard deviation for many real-world datasets, which is something most intro stats courses get backwards. I ran into a specific problem recently with a dataset of customer churn times measured in days. The distribution was heavily right-skewed with some extreme values around 900 plus days. The standard deviation was completely useless for identifying typical outliers, sitting at over 400 days. I calculated Q1 as roughly 45 days and Q3 as roughly 210 days, giving an IQR of 165. Using the standard fence method, any value below Q1 minus 1.5 times IQR or above Q3 plus 1.5 times IQR is a mild outlier. That put my upper fence at about 457 days and my lower fence below zero, which is impossible for this type of data. The outliers were clearly the people who left after 600 to 900 days, which made intuitive sense once I stopped looking at the mean and standard deviation. Had I used standard deviation alone, the fences would have been somewhere around 1100 days, flagging almost nothing as an outlier because the SD itself was inflated by those same extreme values. There's a subtlety worth noting about interpolation. Many software packages including Excel's QUARTILE.EXC and QUARTILE.INC functions use different algorithms. Excel's older INC version includes the median in both halves, while the newer EXC version excludes it. Python's numpy and scipy also have their own defaults. If you're sharing results with someone using different software, your IQR might look different even though you're analyzing the same data. Always check which method your tool uses and document it. I've spent hours tracking down discrepancies that turned out to be nothing more than a function name change between software versions.
Get the Full Details

The biggest practical limitation of IQR is that it only captures the middle 50 percent of your data. If your distribution is bimodal or has multiple clusters, the IQR will fall entirely within one of those clusters and tell you almost nothing about the overall spread. It also doesn't account for sample size the way confidence intervals do, so with very small datasets under 10 values, the IQR can be unstable and misleading. For those cases, bootstrapped confidence intervals around the quartiles give you a much better sense of uncertainty, though they take longer to compute. Another thing nobody warns you about is tied ranks. When you have a lot of repeated values, the position-based quartile methods break down in subtle ways. You might get the same Q1 and Q3 for two completely different distributions just because the tie structure is similar. Weighted interpolation methods handle this better but they're not available in basic spreadsheet tools, so you end up writing custom code or accepting the approximation. If you want to automate this, most statistical environments have built-in functions. In Python you can use numpy.percentile with interpolation='linear' or scipy.stats.iqr. In R, the IQR function handles it natively. For Excel users, QUARTILE.EXC is generally preferred over QUARTILE.INC for research purposes since it matches the exclusive method used in most academic literature. Just remember that both require your data to be free of non-numeric entries, which is always the first thing you need to clean before running any of this.
The raw computation itself takes about as long as sorting the data manually, which for a few hundred rows is basically instantaneous on any modern machine. The real time investment is usually in the data cleaning that comes before it. I'd estimate that for a typical analysis project, maybe 10 to 15 percent of the time is spent on the actual IQR calculation while the rest is spent figuring out why the data isn't in the right format in the first place.