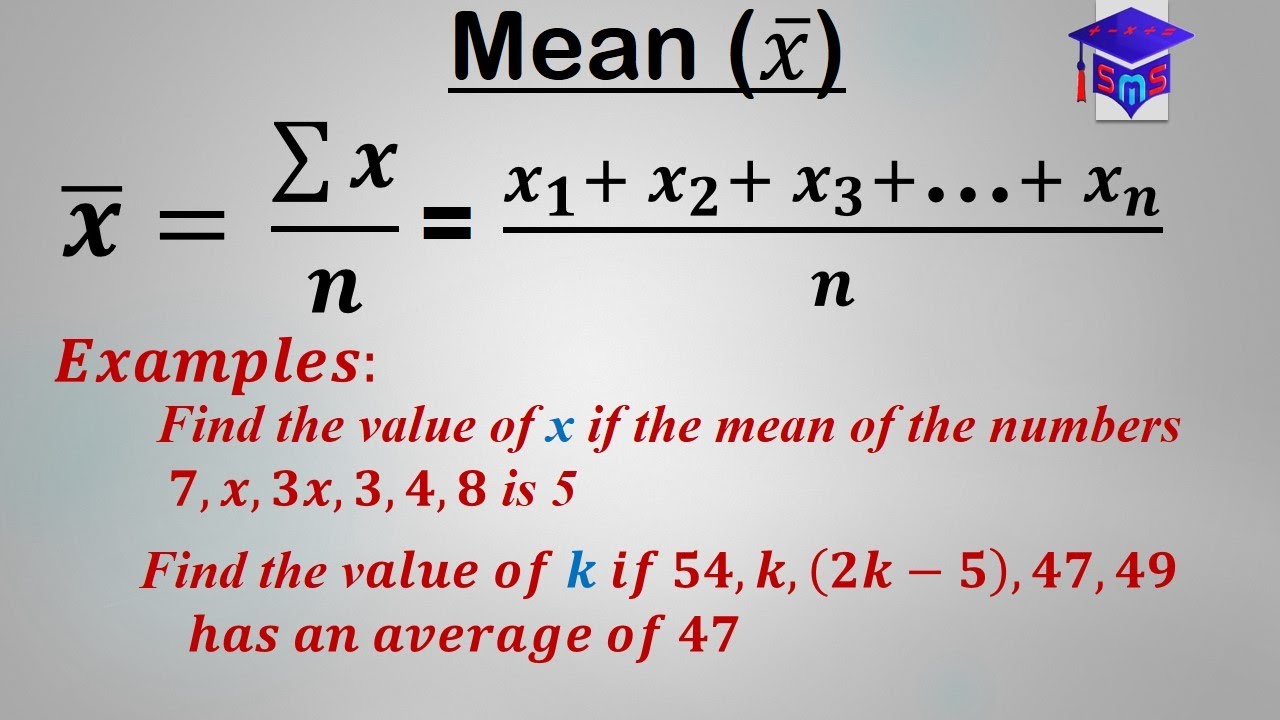
So You Need to Find the Mean
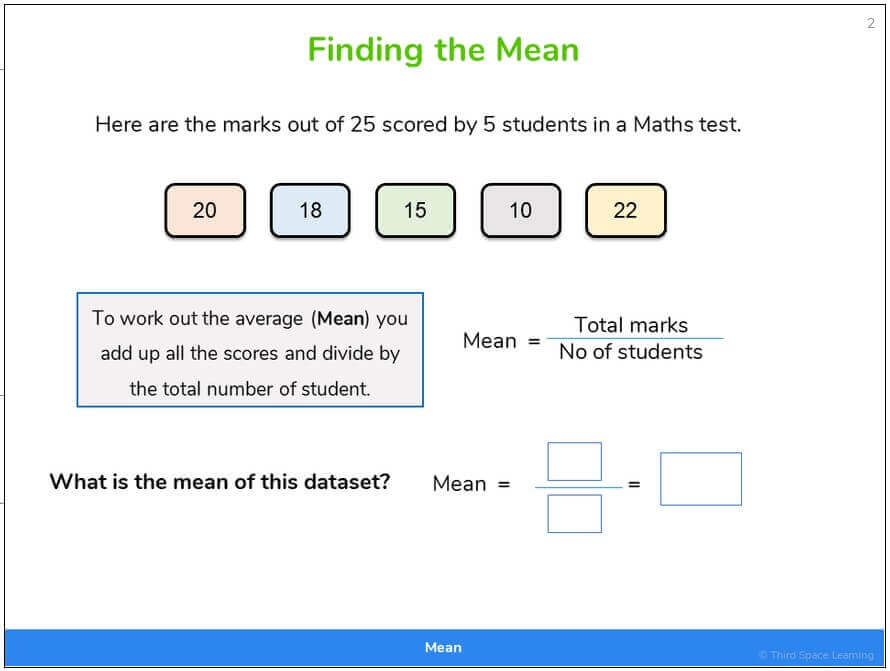
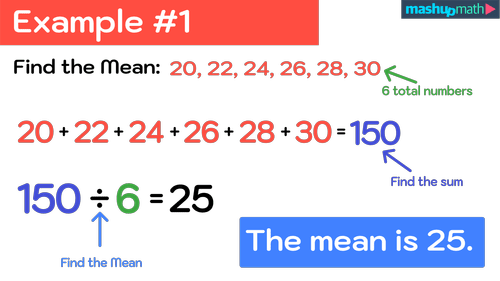
The mean is just a fancy word for average. You add everything up and divide by how many items there are. That is literally it. Most people trip up on the "how many" part when they forget to count every data point, especially zero values or outliers that seem like mistakes but aren't. Step one: write down your dataset. Let's say you have the numbers 4, 7, 12, 3, and 9. Step two: add them all together. 4 plus 7 is 11. 11 plus 12 is 23. 23 plus 3 is 26. 26 plus 9 is 35. Step three: count your data points. Five numbers. Step four: divide the sum by the count. 35 divided by 5 equals 7. The mean is 7. Nothing mystical about it. I remember dealing with a payroll dataset once where someone had entered -1 for missing values instead of leaving the field blank. The mean came out completely wrong because that negative was pulling the average down by almost two full hours per employee. I had to go through and filter out the negative entries before calculating. It took maybe twenty minutes to clean the data, but it saved me from submitting garbage numbers to the CFO. Always check your data for impossible values first.
Here is what beginners usually miss: the mean is extremely sensitive to outliers. If you have a dataset like 2, 3, 4, 5, and 50, the mean is 12.8. That number does not represent anything close to most of your data. In those cases, the median is a better measure of central tendency. The median would be 4, which actually tells you something useful about the typical value. Another nuance people overlook is weighted means. If you are calculating the average grade in a class where the final exam counts for 40 percent and homework counts for 60 percent, you cannot just average the exam score and the homework score. You need to multiply each by its weight, add them up, and that gives you the weighted mean. Standard mean calculation breaks down completely here if you ignore the weights. The mean also fails when your data is heavily skewed, like income distribution or house prices. You have ever seen those articles about average income being $80,000 while most people make between $40,000 and $55,000? That is the mean lying to you because a few billionaires on the list pull the number way up. Median would have been honest.
For grouped data, you use midpoints. If your data is in bins like 0-10, 10-20, 20-30, you take the midpoint of each bin, multiply by the frequency in that bin, sum everything, and divide by the total frequency. It is an approximation but it is the standard approach when raw data is unavailable. Computational tip: if you are working with large datasets, do not do this by hand. Excel, Google Sheets, any statistical software will calculate it instantly and without arithmetic errors. I have seen people spend 45 minutes adding thirty-seven numbers by hand and then still get the wrong answer. Software eliminates that entire category of mistakes. One more thing worth noting: the mean minimizes the sum of squared deviations. That is the property that makes it useful for regression analysis and standard deviation calculations. It is not just a descriptive statistic. It is mathematically tied to how variance works, which is why it appears everywhere in statistics even when it is the wrong tool for simple description.
Get the Full Details