Getting the Naming Right
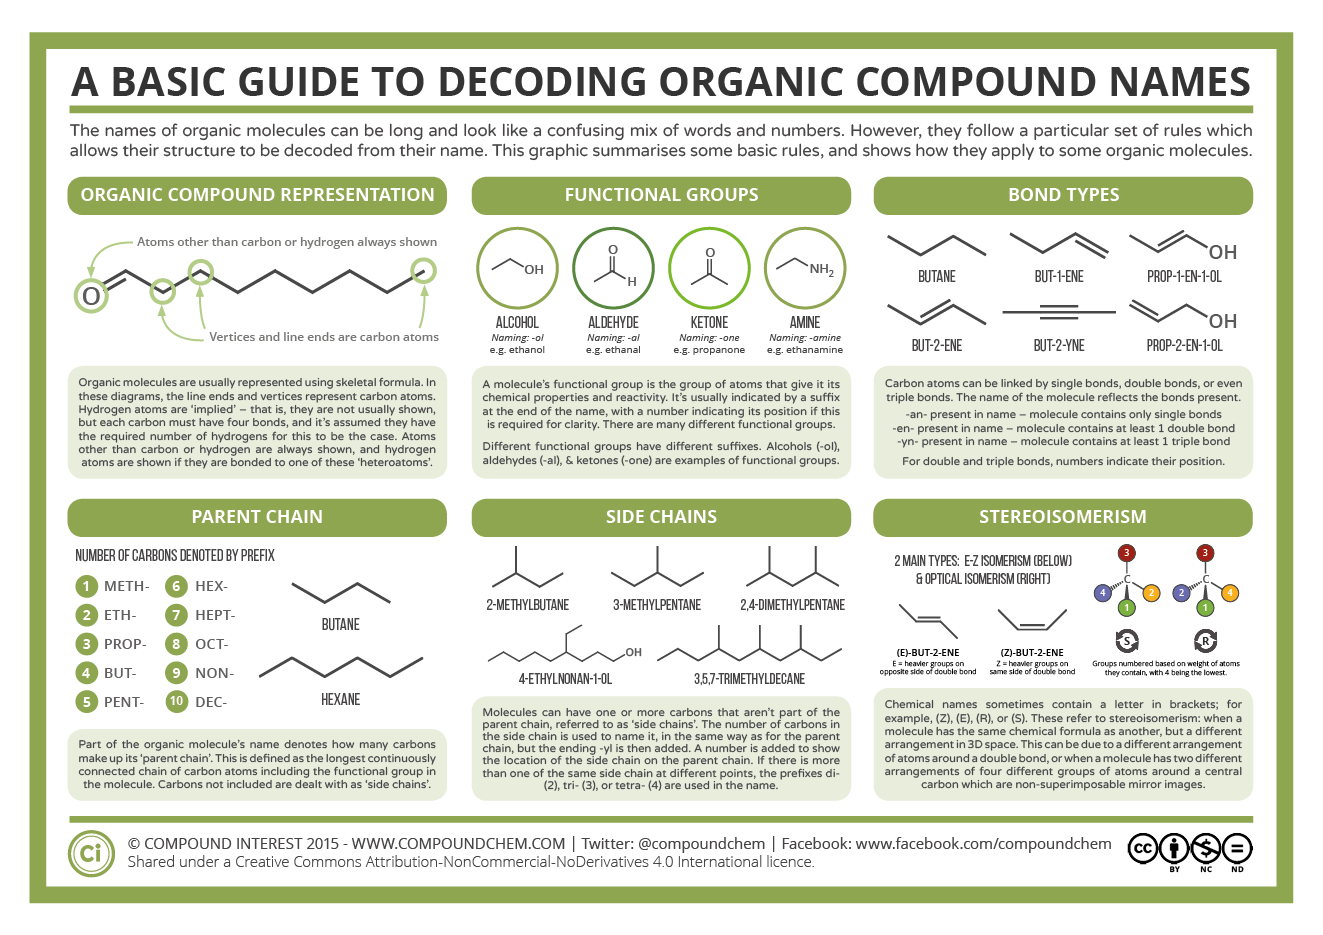
Most people learn IUPAC nomenclature by memorizing the hierarchy of priority groups and then trying to apply it to every molecule they encounter. It works fine for textbook examples. When you actually sit down with a real compound, it's messier than that. The method is straightforward in principle. You identify the principal functional group, find the longest carbon chain that includes it, number from the end that gives the lowest locants to the substituents, and then assemble the name in a specific order. Prefixes come before the parent, substituents are listed alphabetically, and locants go right before what they modify. Stereochemistry gets handled separately with R/S, E/Z, cis/trans notation placed at the front. How Do We Name Compounds when the rules start contradicting each other is where this gets interesting. I ran into this recently with a bicyclic compound that had a carboxylic acid on one bridge and a ketone on the other. The acid should win priority, but the longest chain rule for the parent got tangled because the bridges created competing options. What I ended up doing was drawing out both possibilities with the full numbering scheme and checking the IUPAC Blue Book tables for bicyclic systems. The rule that settled it was the one about lowest set of locants applied to the principal group, not just any functional group. It's easy to miss that distinction when you're working under time pressure.
Some Things They Don't Emphasize
The biggest mistake beginners make is thinking alphabetical ordering matters for the whole name. It doesn't. It only matters for the substituents in the prefix section. The parent chain name and the principal functional group suffix stay fixed. So 3-chloro-2-methylbutane is correct, not 2-methyl-3-chlorobutane, and the reason has nothing to do with "alphabetical priority for the entire molecule." That misconception alone trips up half the students I've seen in labs. Another thing people gloss over is the handling of complex substituents. When a substituent itself has branches or functional groups, it becomes a multiparent structure and gets its own numbering. Parentheses go around it. It's not rare to see someone write 2-(1-methylethyl)pentane when they should have just called it 2-methylpentane. The parentheses are only necessary when the substituent name itself would be ambiguous without them. Overusing them clutters names and introduces errors. Here's a practical workflow I use that's faster than reading through the full rules each time. I start by identifying the highest priority group using the standard sequence: carboxylic acids, esters, amides, nitriles, aldehydes, ketones, alcohols, amines, alkenes, alkynes, ethers, halides. Everything below that becomes a prefix. Then I count carbons in every possible chain that includes the principal group. Not just the longest one visually — the one that gives the lowest locants. Numbering direction matters more than chain length in several edge cases.
The whole process for a moderately complex molecule takes me about twelve to fifteen minutes if I know the structure well. If I'm still learning it, maybe forty. The bottleneck is always deciding between competing principal groups or choosing the right parent chain when rings and chains are both present. In those situations I've found it useful to sketch the structure, label every possible numbering, and compare the locant sets digit by digit. It's slower upfront but prevents the rework that happens when you get the name wrong and have to redraw everything. There are situations where IUPAC naming just doesn't cut it. Natural products with intricate ring systems often have trivial names that are universally used in the literature. Caprolactam, quinine, morphine — nobody calls these by their systematic names in conversation or even most papers. The systematic names exist and are correct, but they're so long they're functionally useless for communication. Same with peptides and oligonucleotides where three-letter amino acid codes or base abbreviations are standard. Trying to force full IUPAC names there just creates unreadable text. Another real limitation is that IUPAC nomenclature assumes you already know the structure. If you're working from spectral data and the connectivity isn't fully resolved, you can't generate a precise name. You end up with partial descriptors or placeholder labels until the structure is confirmed. This comes up regularly in organic synthesis when you're isolating an unknown byproduct. The name will sit there incomplete until NMR and mass spec fill in the gaps.
Get the Full Details

For quick reference while you're working through problems, the official IUPAC Blue Book is available as a free download from the IUPAC website. It's dense and not designed for casual reading, but it's the definitive source when rules conflict. Most people never need it, but when you hit a case that isn't covered in the standard textbook, it's the only thing that resolves it authoritatively.