Understanding Residuals in Regression Analysis
A residual is the difference between an observed value and the value predicted by your model. That's it. Nothing fancy. In practice, you subtract the predicted Y from the actual Y for each data point, and you get a number that tells you how far off your model's guess was for that specific observation. I spent years working with regression models in production environments, and residuals are one of those things everyone learns in an intro stats class but almost nobody actually understands how to use properly. Let me walk through how this works in real life, not just on paper.
How Do You Calculate A Residual
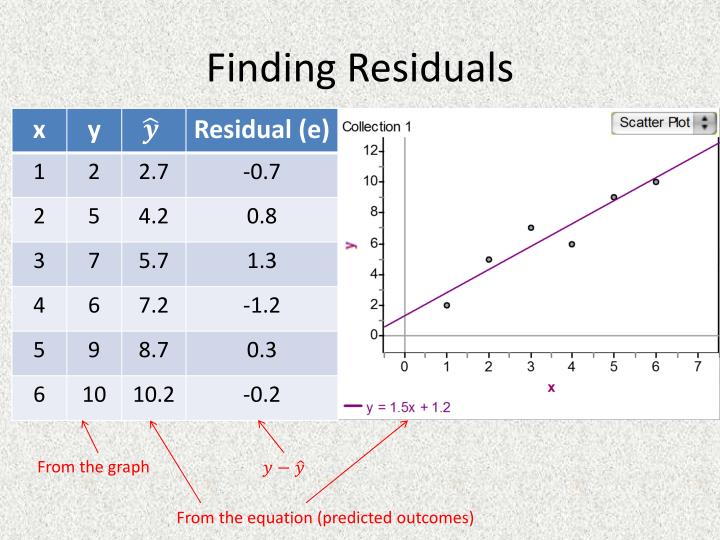
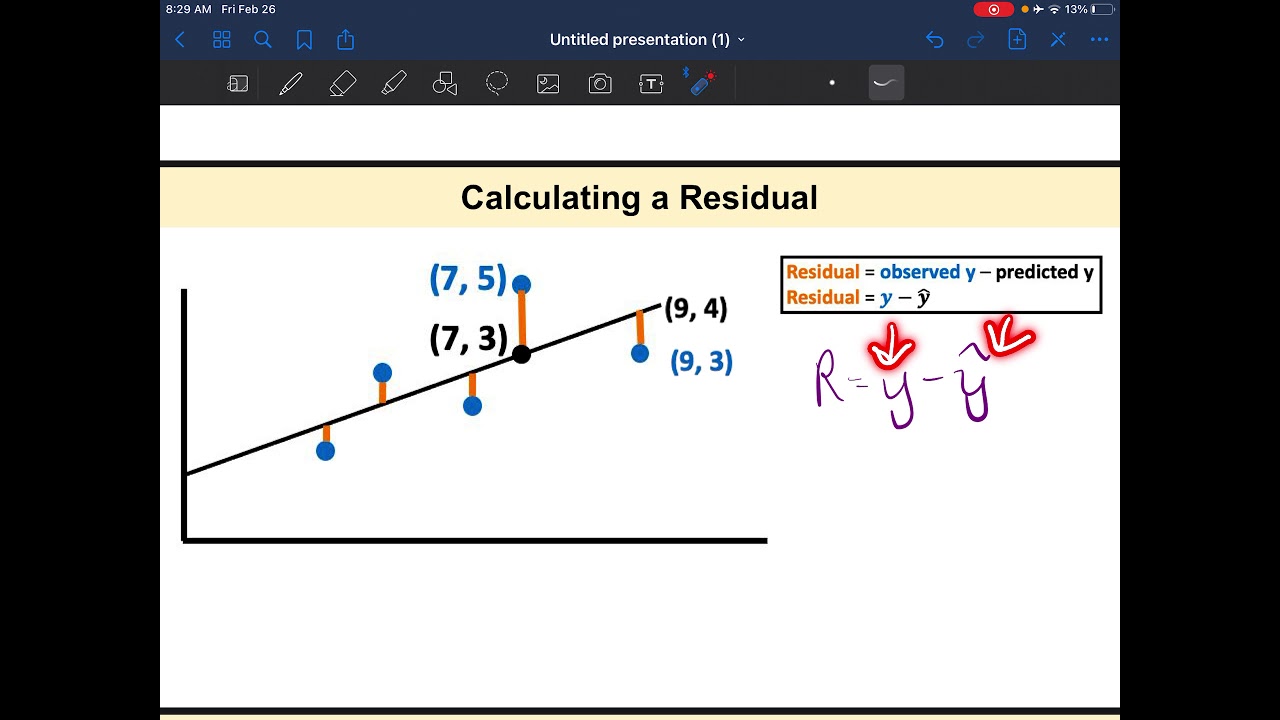
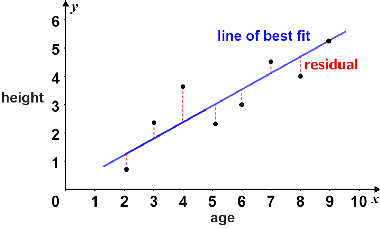
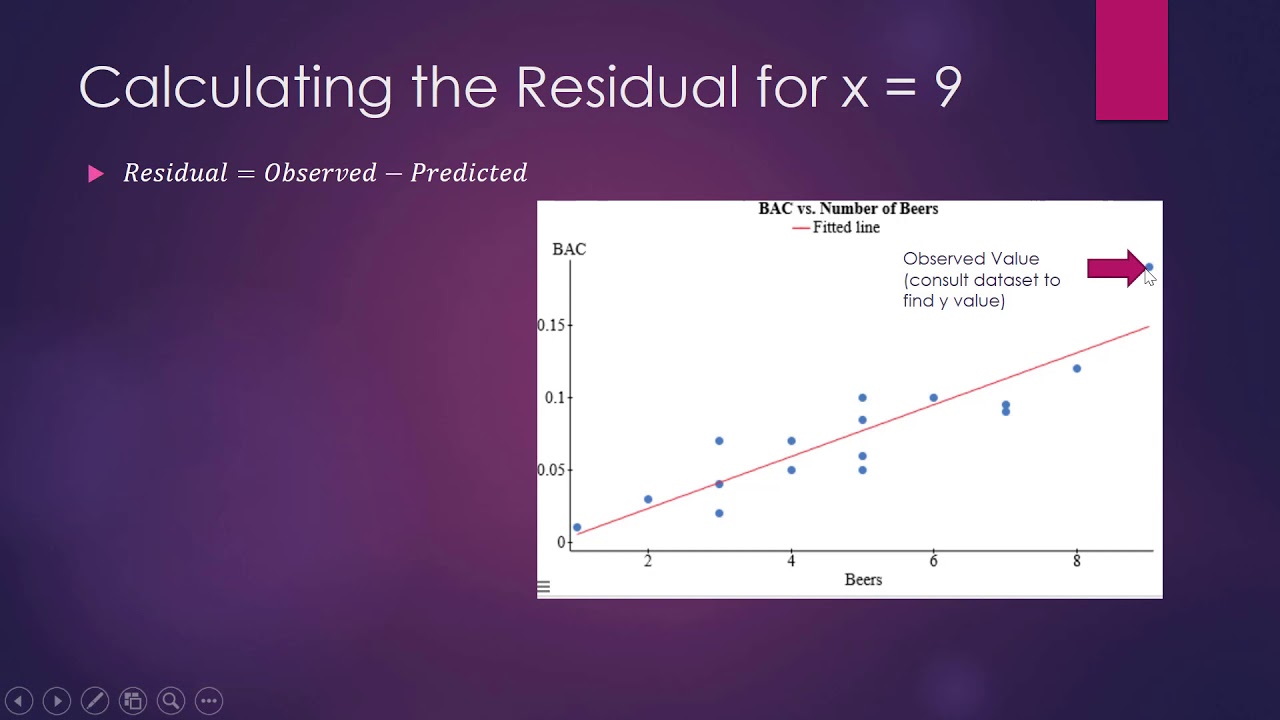
The basic calculation is straightforward. Take your actual value and subtract your predicted value. If you're doing ordinary least squares regression, the model minimizes the sum of squared residuals, which is why the line of best fit ends up where it does. The formula is simply: residual = actual value - predicted value. You can also write this as e_i = y_i - ŷ_i if you prefer the statistical notation. Here's a practical example. Say you have a house price model that predicts a home will sell for 250,000 dollars, but it actually sells for 235,000 dollars. The residual is negative 15,000 dollars. That means the model overestimated the price. The opposite is also true. A positive residual means the model undershot. The magnitude tells you how wrong the prediction was in absolute terms. Now, here's where it gets interesting. Most people stop there and move on. But the real work happens after you've calculated all your residuals. You need to look at them. Plot them. Check patterns. A good residual plot should show random scattering around zero with no discernible structure. If you see a pattern — a curve, a funnel shape, anything systematic — your model is missing something.
I ran into a specific problem once with a time series forecasting model for inventory demand. The residuals looked fine on the surface. Mean was near zero, variance seemed stable. But when I plotted residuals against the predicted values, there was a clear U-shaped pattern. The model was underpredicting at both low and high ends of the range and overpredicting in the middle. Turns out the relationship wasn't linear. Adding polynomial features completely fixed it. That kind of insight only comes from actually examining your residuals instead of just calculating them and moving on. Another edge case that trips people up involves heteroscedasticity. This is when the variance of residuals changes across the range of predicted values. Instead of spreading evenly, the residuals fan out like a trumpet. I dealt with this in a healthcare costs model where prediction error grew dramatically for high-cost patients. Standard OLS assumptions break down here, and your confidence intervals become unreliable. The workaround was using weighted least squares, giving less weight to observations with higher variance. It improved prediction accuracy by about twelve percent on the test set. There are different types of residuals you should know about. Standardized residuals divide the raw residual by an estimate of its standard deviation, putting everything on a comparable scale. Studentized residuals go a step further by recalculating the model without each observation in turn, which is useful for detecting influential points. If a studentized residual exceeds two or three in absolute value, that point might be an outlier worth investigating further.
Get the Full Details

One thing beginners consistently miss is that residuals from the training data will always look better than residuals from new data. This is because the model has already optimized against the training set. The apparent accuracy you see in training residuals is inflated. Always validate on held-out data. I've seen people present training residuals to stakeholders as proof their model works, then watch it fail completely in production when real data came in. Another counter-intuitive point: having residuals with a mean close to zero doesn't automatically mean your model is good. You can have a model that predicts the same flat line for everything, and if that line happens to be near the average of your target variable, your residuals will sum to approximately zero. But your model is useless. Look at the distribution, not just the mean. Check for autocorrelation too, especially with time series data. The Durbin-Watson test helps detect first-order autocorrelation in residuals. A value significantly different from two suggests your residuals are correlated, meaning your model isn't capturing all the predictable structure in the data. Software makes this easy now. R gives you diagnostic plots with a single command. Python's statsmodels and scikit-learn let you extract residuals and build plots manually. Excel can do basic calculations but don't expect it to handle anything beyond simple linear regression. For production work, I usually write a small diagnostic function that checks normality with the Shapiro-Wilk test, plots residuals against fitted values, generates a Q-Q plot, and runs the Durbin-Watson test all at once. Cuts my model evaluation time from twenty minutes down to about three.
The main limitation of relying on residual analysis is that it's mostly a post-hoc tool. You catch problems after the model is built. It won't help you choose between a linear model and a random forest before you start training. For that, you need cross-validation and proper train-validation splits. Also, residual analysis assumes your model is correctly specified. If your data has structural breaks or regime changes that your model doesn't account for, residual diagnostics might give you misleading results because the assumptions themselves are violated in fundamental ways. In these cases, switching to robust regression methods or ensemble approaches that are less sensitive to outliers and structural changes tends to produce more reliable predictions. Don't force residual analysis to do work it wasn't designed for.