The actual decision process
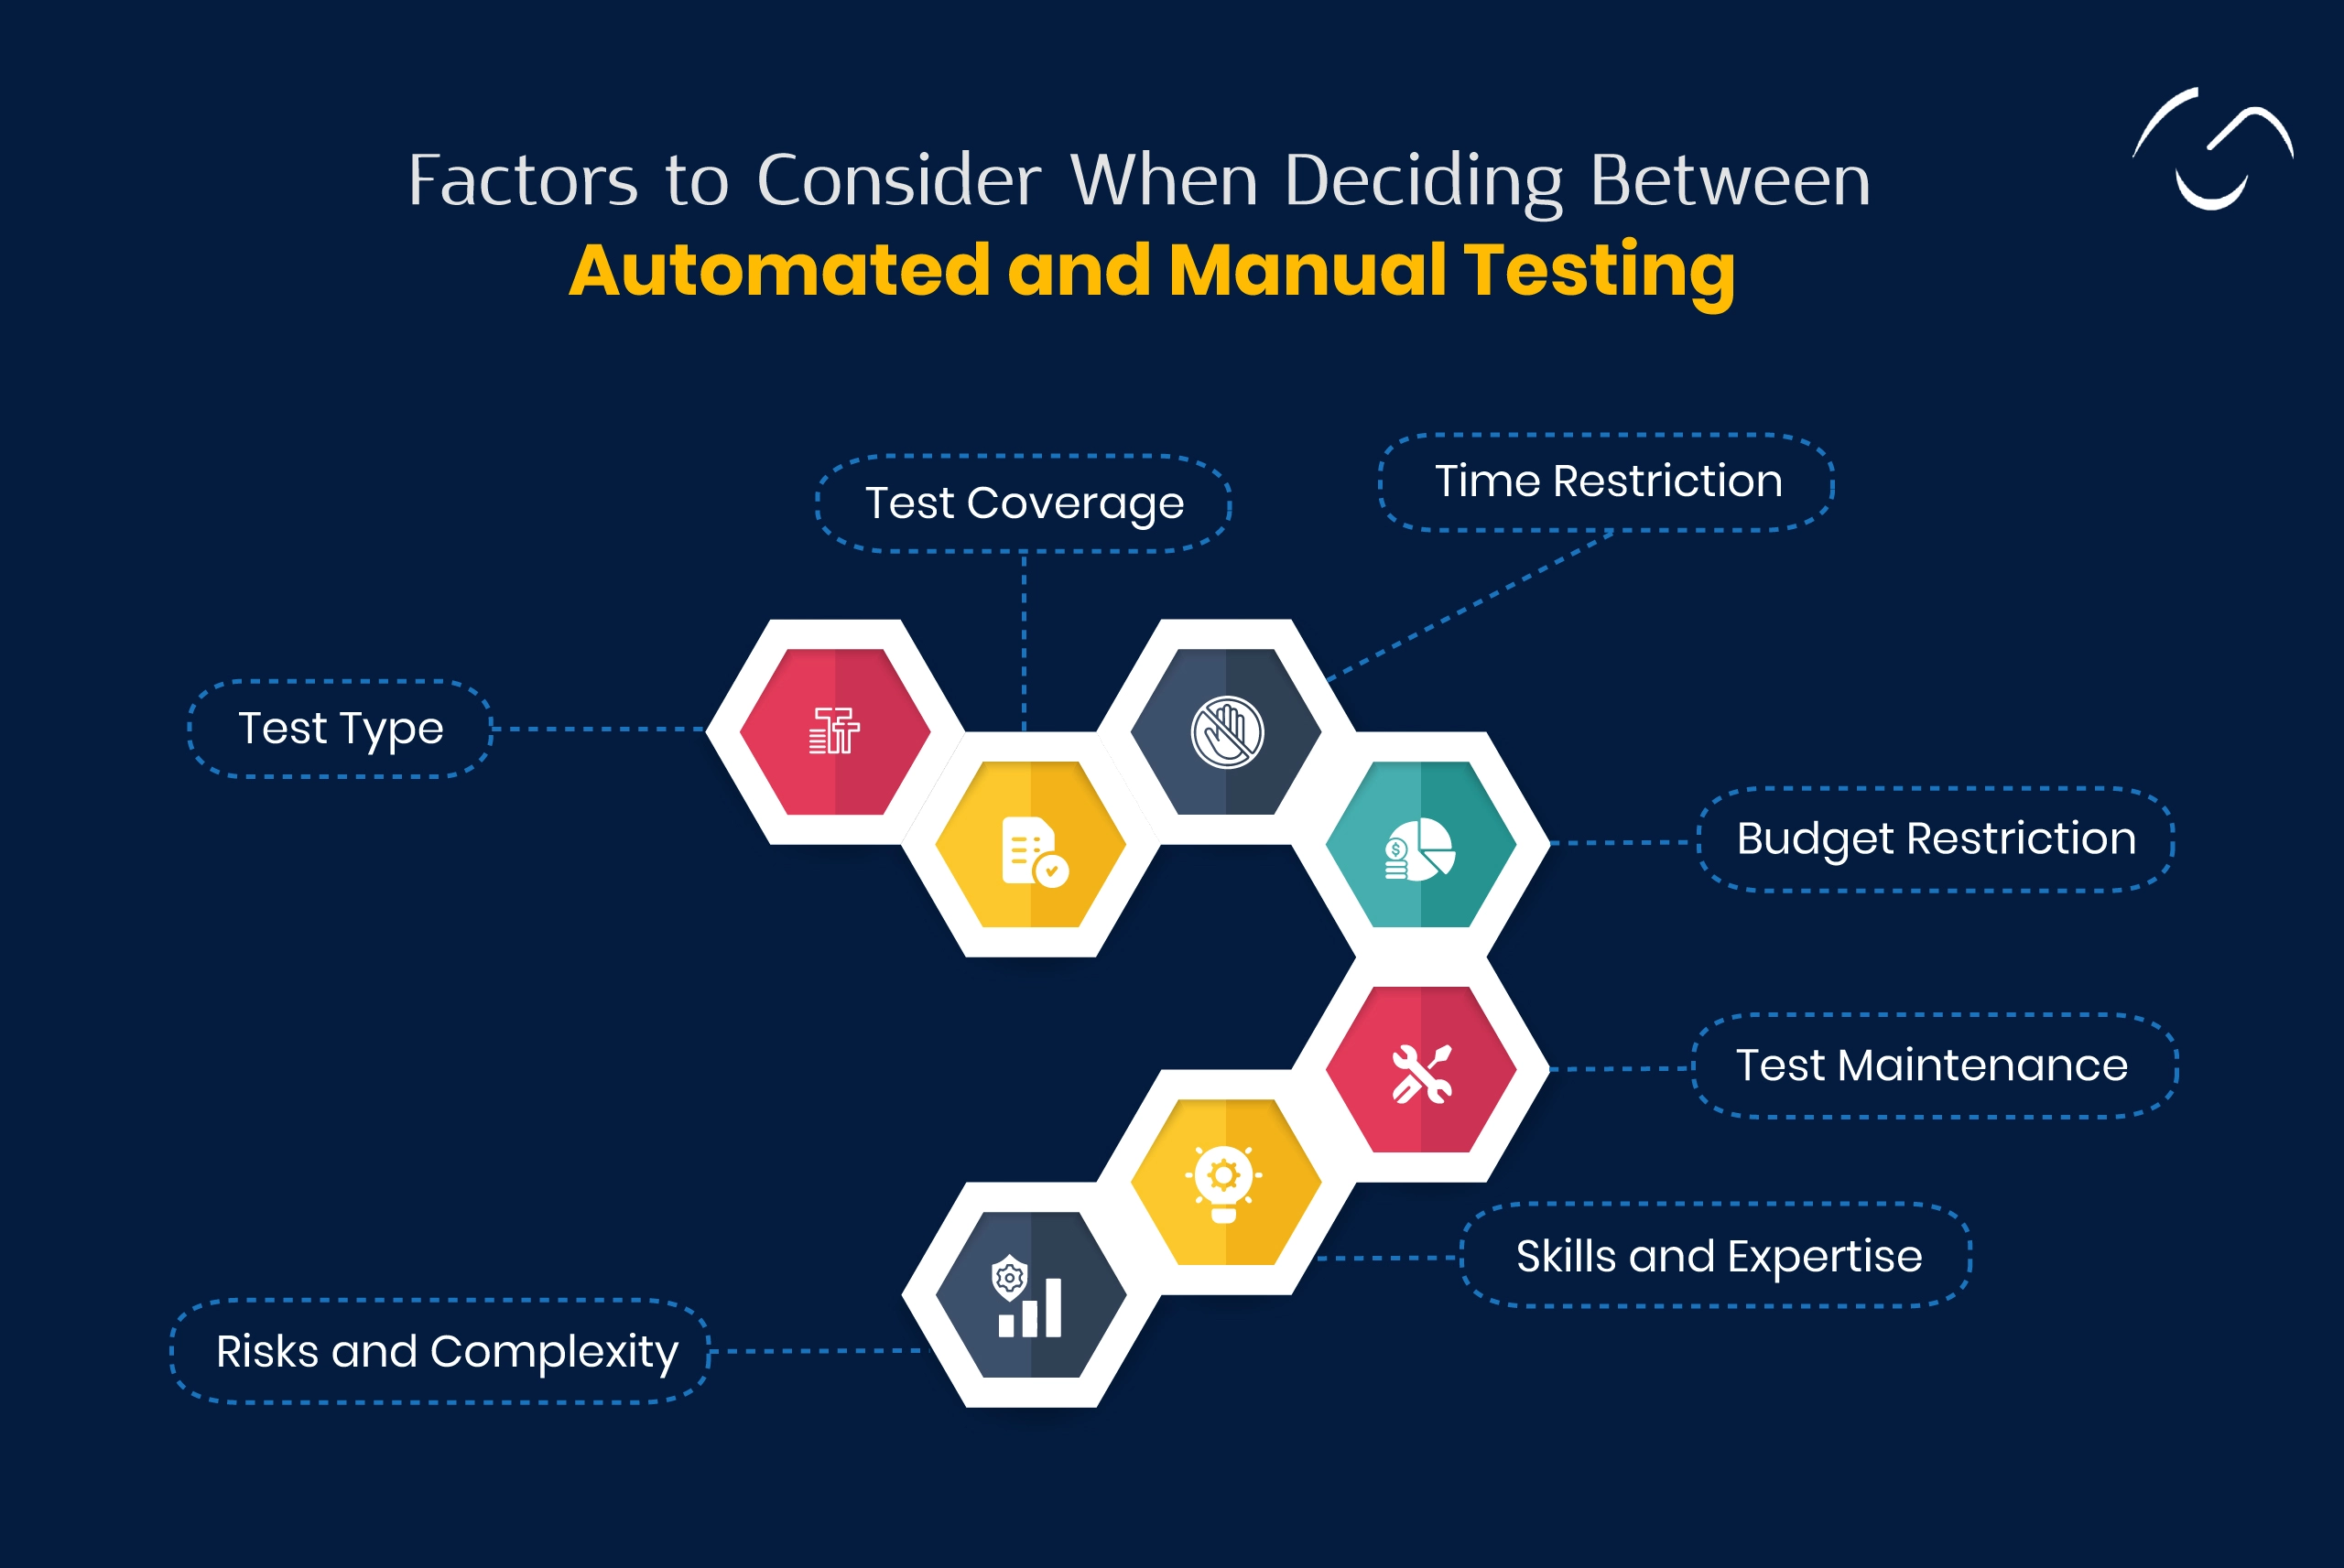
I used to write every regression test by hand because it felt safer. Then I spent three days manually retesting the same checkout flow after a deployment and realized I was just paying someone to be a robot. The switch didn't happen overnight, but the framework for deciding which path to take is pretty straightforward once you've actually lived through the pain of both approaches. It starts with volume and repetition. If a test case runs more than four times per release cycle, it's probably worth automating. I work with a team that does roughly six deployments a week across staging and production, so anything that touches the payment gateway gets scripted. We don't touch the A/B experiment UI variations with code though. Those change weekly and the selectors break constantly. Those stay manual. The real question is whether the test is deterministic. Automated tests fail when the thing being tested is unpredictable by design. We learned this the hard way with a feature that randomly shuffled card positions in our dashboard based on user behavior. Every time someone touched the page differently, the DOM changed. We tried to automate it anyway. It failed at a 40 percent rate. Wasted about two weeks fixing flakes before we admitted the test wasn't actually testing anything useful. Took it to manual and paired it with a screen recording tool for the edge cases. Done.
Here's what most people miss when they're picking between the two. Coverage isn't the point. You want to automate the things that are boring and dangerous to do by hand. Repetitive data validation, large-scale performance benchmarks, API contract checks. The kind of work where a human will get tired around test case 18 and start making mistakes. Not the exploratory stuff. Not the one-time edge cases that exist because some third-party API decided to return an error code that doesn't appear in the documentation. There's also the maintenance tax. For every hour you save running a test automatically, you spend about twenty minutes maintaining it. This sounds extreme until you've had a frontend update rename three classes and your entire test suite breaks. I've seen teams spend more time fixing their Selenium scripts than the original manual testers would have spent running the cases. The ratio isn't fixed though. Well-structured tests with stable selectors and good abstraction layers keep maintenance closer to five minutes per hour of runtime. The difference comes down to whether you wrote the test like a short-term script or like a piece of production code. Our current split is roughly 70 percent automated, 30 percent manual. The manual portion covers new feature exploration, visual regression checks that require human judgment, and anything involving user sessions that take more than forty-five seconds to set up. The automated portion handles login flows, data migration verifications, API endpoint validation across thirty-two different routes, and our nightly performance regression suite. We run the automated suite in about twenty-two minutes end to end across four parallel browser instances. Running it by hand takes our QA person roughly six hours and she still misses things.
The counter-intuitive part is that automation often catches fewer bugs than careful manual testing. Not because the machines are worse, but because they only test what you tell them to test. A human testing the login page might notice the error message looks wrong, or the button alignment is off, or the loading spinner never stops. An automated test will only tell you whether the login returned a 200 status code and a session token. Those are different kinds of quality. You need both. One thing that trips people up is the assumption that you need to automate everything at once. Don't. Start with the smoke tests. The ten or twelve cases that prove the application didn't completely break overnight. Once those are stable and running reliably in your CI pipeline, add the regression suite. Then tackle the data-heavy validation cases. Then think about performance. Every layer adds complexity and fragility. Getting the smoke tests right is worth more than getting the full suite running with a fifty percent flake rate. There are also hard limits where automation just doesn't work. Accessibility testing beyond the basic axe-core scans needs a real person with a screen reader. Usability testing requires watching how someone interacts with your interface. Compliance verification sometimes needs manual sign-off regardless. No script will convince an auditor that your data handling meets GDPR requirements. Save the bots for the tasks they're built for and stop pretending they can replace judgment.
Get the Full Details

The tooling choice matters less than people think. We run Cypress for the frontend, pytest with requests for the API layer, and k6 for performance. It worked. We also tried Playwright and TestCafe before settling on what we have. The tools are close enough in capability that the decision should come down to team familiarity and existing infrastructure, not features. A test written in the wrong language but maintained by people who understand it will outperform a perfectly chosen tool that nobody wants to touch. If you're starting from zero, measure your current manual effort first. Track how many test cases exist, how often each runs, and how long each takes. The candidates for automation will jump out of that data immediately. You'll find that roughly a quarter of your manual cases are actually not worth automating because they run once a quarter or require setup that takes longer than the test itself. Ignore those. Automate the high-frequency, low-complexity cases first. The ROI shows up fastest there.