Finding Range Is Simpler Than Most People Make It
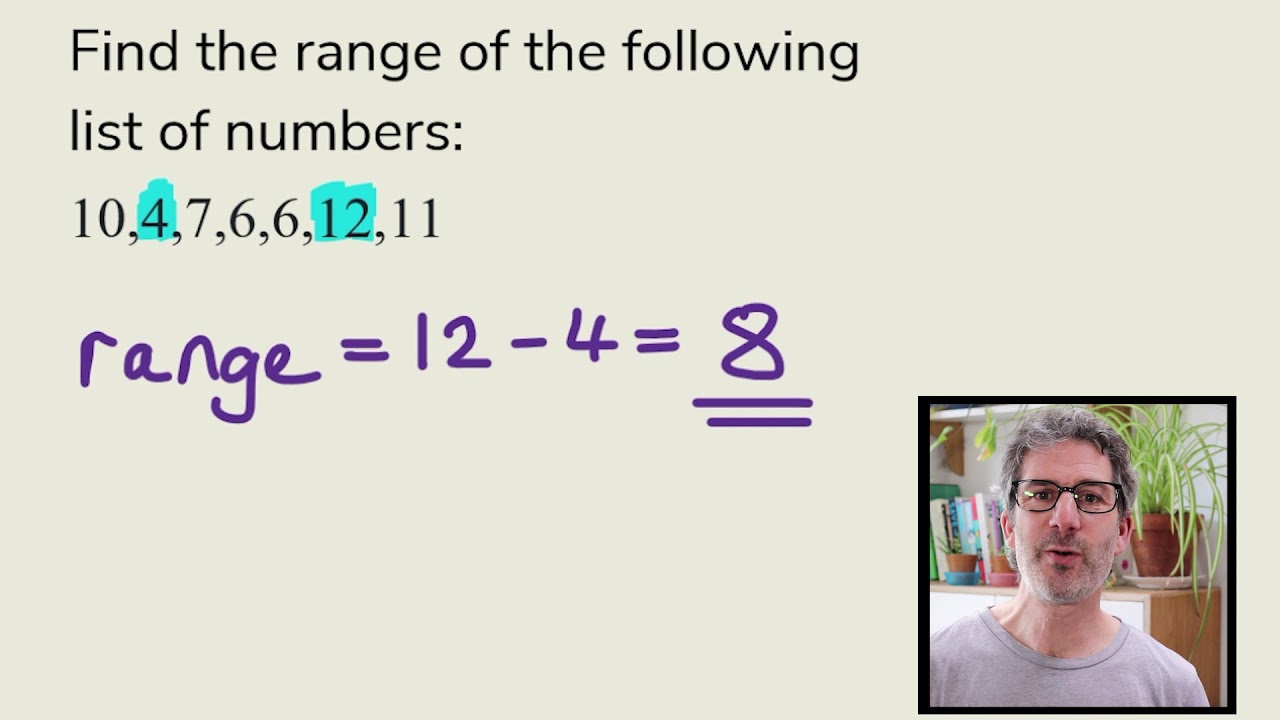
The range of a dataset is the difference between its maximum and minimum values. That's the definition, and most guides stop there. The part they don't tell you is that knowing the formula doesn't mean you actually get the right answer when you apply it to real data. I spent years watching people plug numbers into formulas without checking their data first, then getting confused by results that made no sense. Take your dataset. Identify the highest value. Identify the lowest value. Subtract the lowest from the highest. That gives you the range. In a spreadsheet, if your data sits in cells A1 through A500, you'd use something like =MAX(A:A)-MIN(A:A). In Python with pandas, it's df['column'].max() - df['column'].min(). In SQL, it's MAX(column) - MIN(column). Same operation, different syntax. That's the mechanical part. It takes about five seconds once your data is loaded. The actual work is figuring out whether the number you're getting is meaningful.
Here's a case that cost me two days once. I was working with temperature sensor data from an outdoor monitoring station. The calculated range came out to something like negative four thousand degrees. Turns out one of the sensors had failed mid-record and started outputting null values that the export function treated as zero. The dataset's minimum was zero instead of thirty-two. The range was completely wrong, and the formula couldn't catch that on its own. I had to filter out records where the sensor reported values below a physically impossible threshold before calculating range. Now I run a sanity check on min and max values before anything else, always. People miss a few things when they're first learning this. One is that range only uses two data points. Everything between the maximum and minimum is ignored, which means range tells you nothing about how the data is distributed. A dataset with values 1, 50, 51 and another with 1, 2, 3, 4, 5, 48, 50, 51 both have a range of 50, but they look nothing alike. If someone asks you to describe the spread of their data and you only report range, you're giving an incomplete picture. It's better to also mention the interquartile range or standard deviation, since those account for more of the distribution. Another thing that trips people up is outliers. Range is extremely sensitive to them. A single anomalous value can blow the range up so much that it becomes useless as a descriptor. I worked on a project where a couple of data entry errors inflated the range of customer transaction amounts by a factor of ten. The range was in the millions when the actual typical spread was under five hundred dollars. We ended up using a trimmed range instead, removing values above the 99th percentile and below the 1st percentile before calculating. That gave us something that actually reflected the bulk of the data.
If you're working with streaming data or datasets that arrive continuously, the standard max-minus-min approach requires you to hold the entire dataset in memory or recompute from scratch each time. There's no cheap incremental update for raw range the way there is for mean or sum. Some people use a bounded index structure or a sliding window with a min-max heap to handle this efficiently. It adds complexity but saves significant time when you're processing millions of records per day instead of batch-loading them once a week. Range becomes essentially meaningless with constant data. If every value is the same, the range is zero. That's technically correct but not useful. In those cases, saying the range is zero is the entire story, and you should just move on to other metrics or note that the variable has no variability at all. When your data has missing values, how you handle them changes the result. Dropping nulls is the default in most tools, but if missingness isn't random, you're introducing bias. In one of my projects, missing temperature readings were concentrated during nighttime hours when sensors were more likely to malfunction. Dropping them shifted the apparent minimum upward and shrank the range artificially. I ended up flagging those periods separately rather than silently excluding them.
Get the Full Details

For quick manual calculation with a small dataset, sort the numbers and subtract the first from the last. It's faster than you might think for fewer than fifty values. For anything larger, use a script or spreadsheet. The sort-then-subtract method breaks down around fifty elements because you start making arithmetic errors or wasting time. Range is a foundational statistic, not a complete analysis. It answers one narrow question: how far apart are the extremes? Use it as a first pass, then dig deeper with other measures if the story needs more detail.