The Mechanics Nobody Teaches You Right
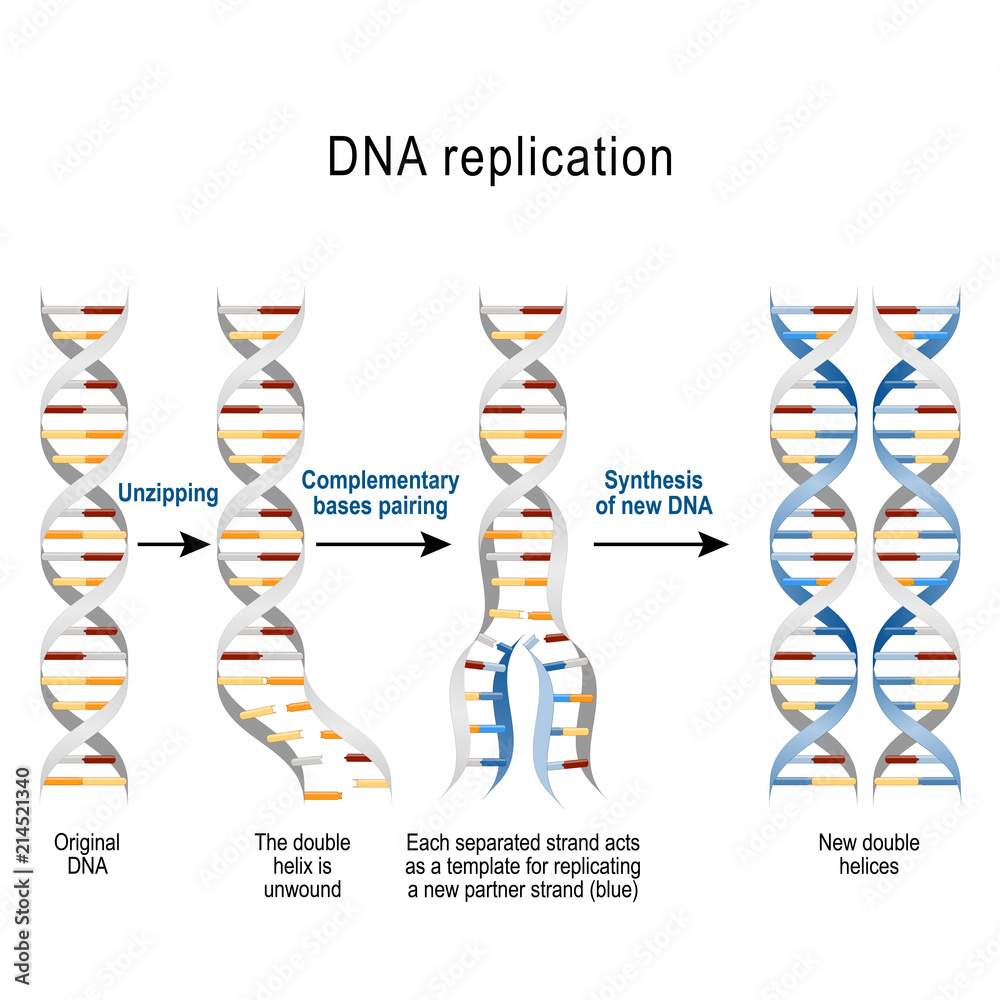
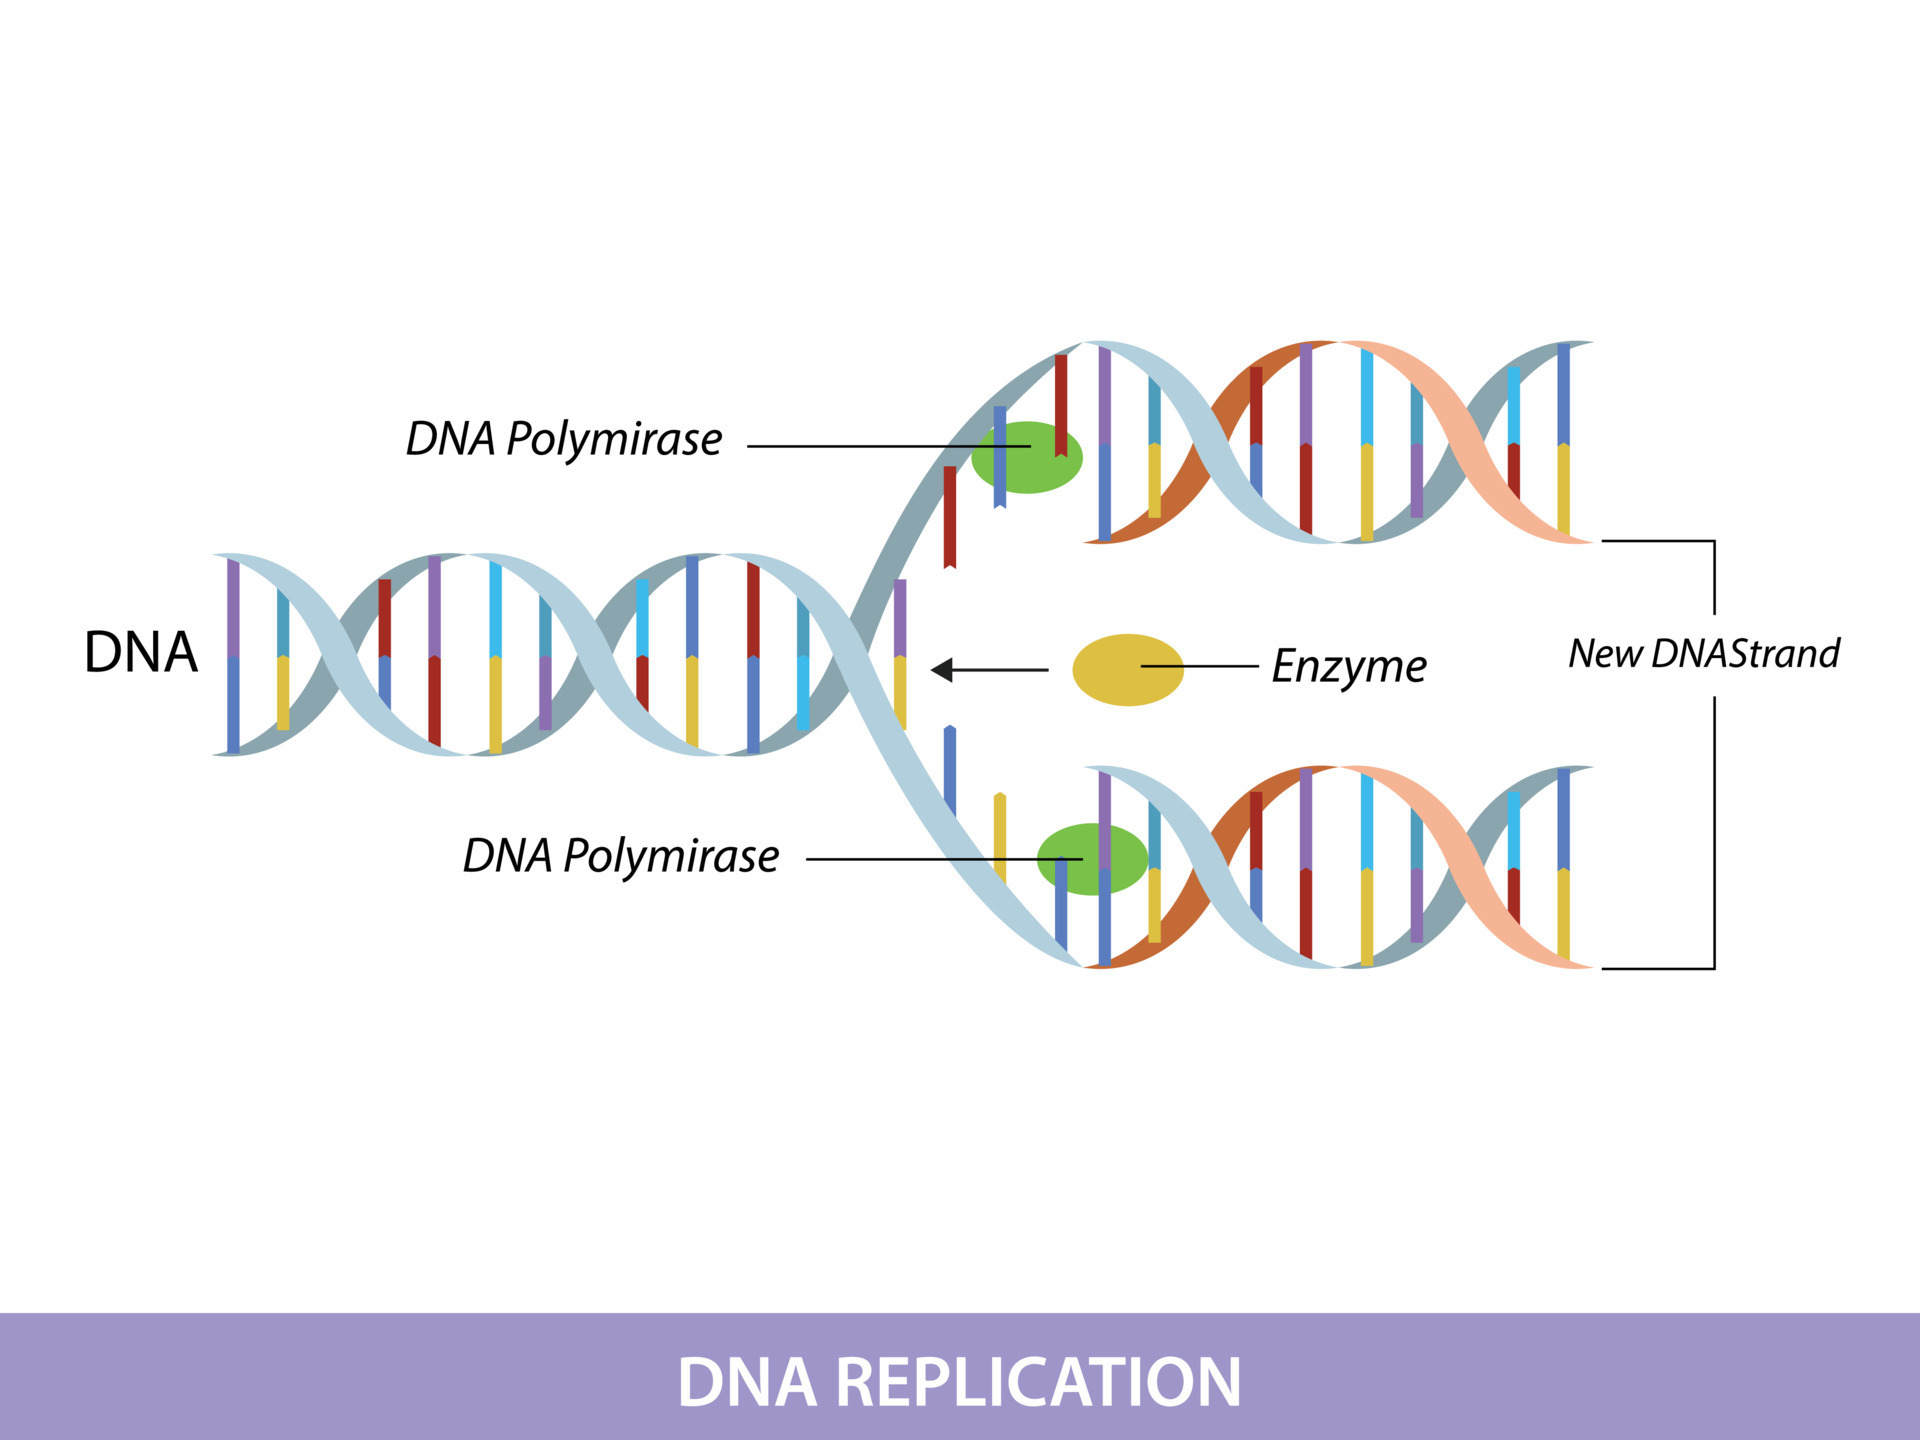
DNA replication is semi-conservative, which means every new double helix contains one old strand and one newly synthesized strand. The enzyme that does the heavy lifting is DNA polymerase, and it only works in the 5' to 3' direction. That directional constraint is what makes the whole process interesting, and honestly, it's what trips people up when they first try to diagram it on a whiteboard.
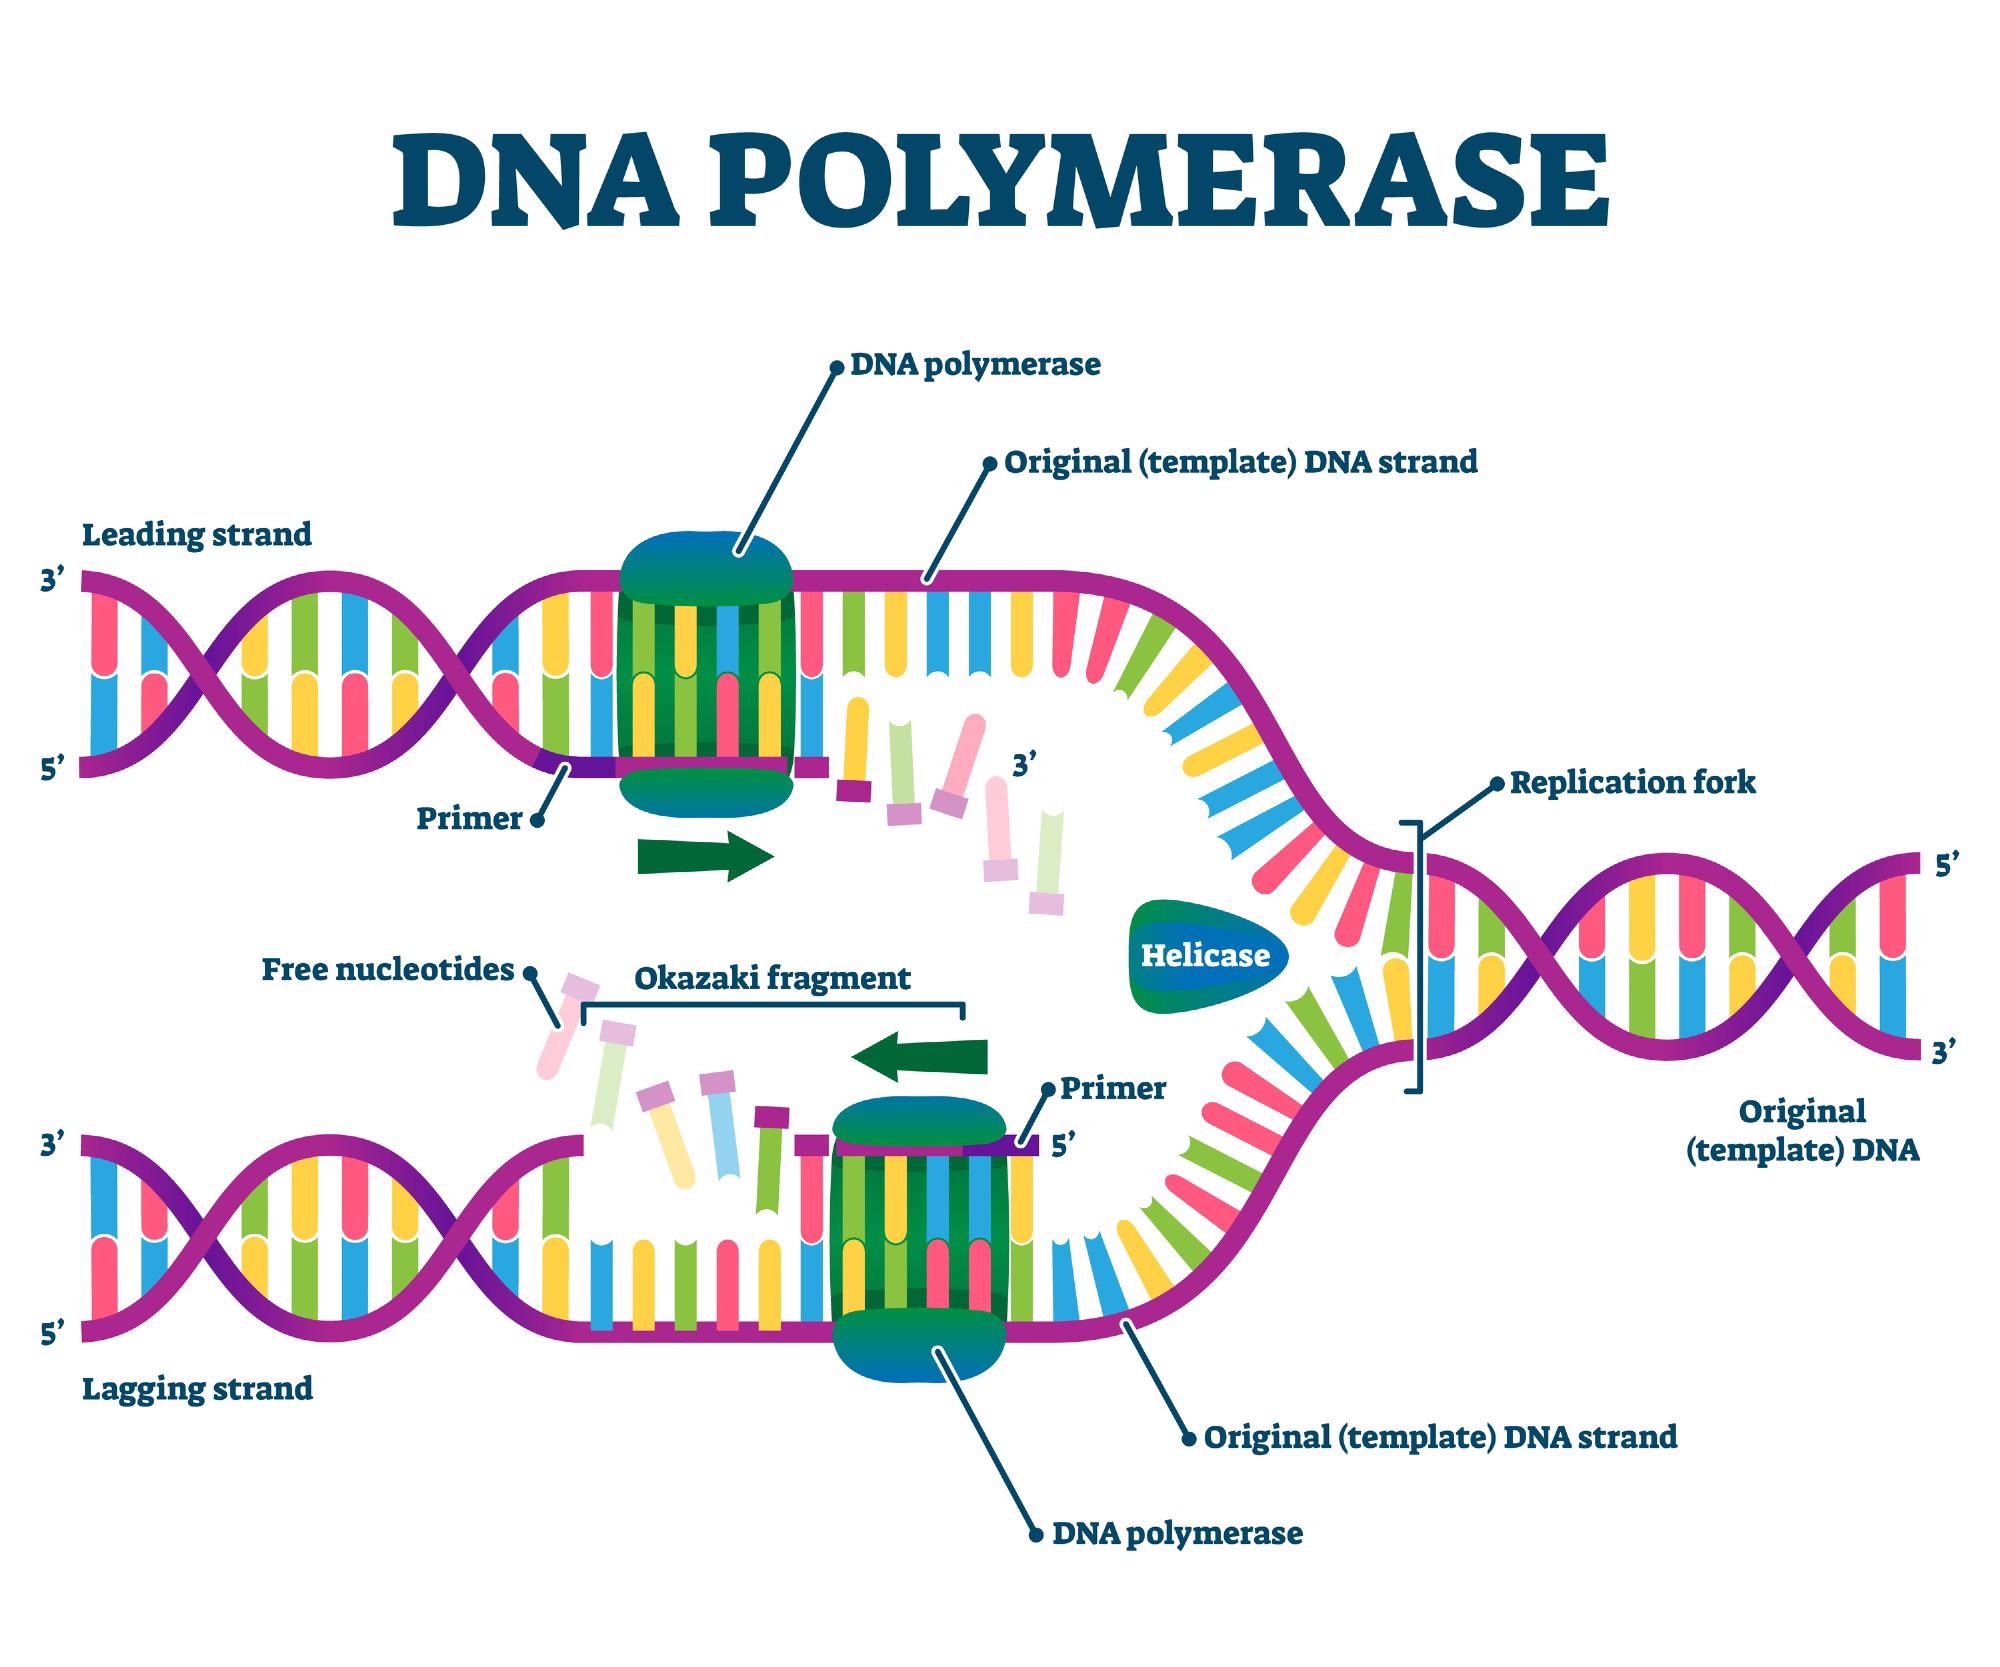
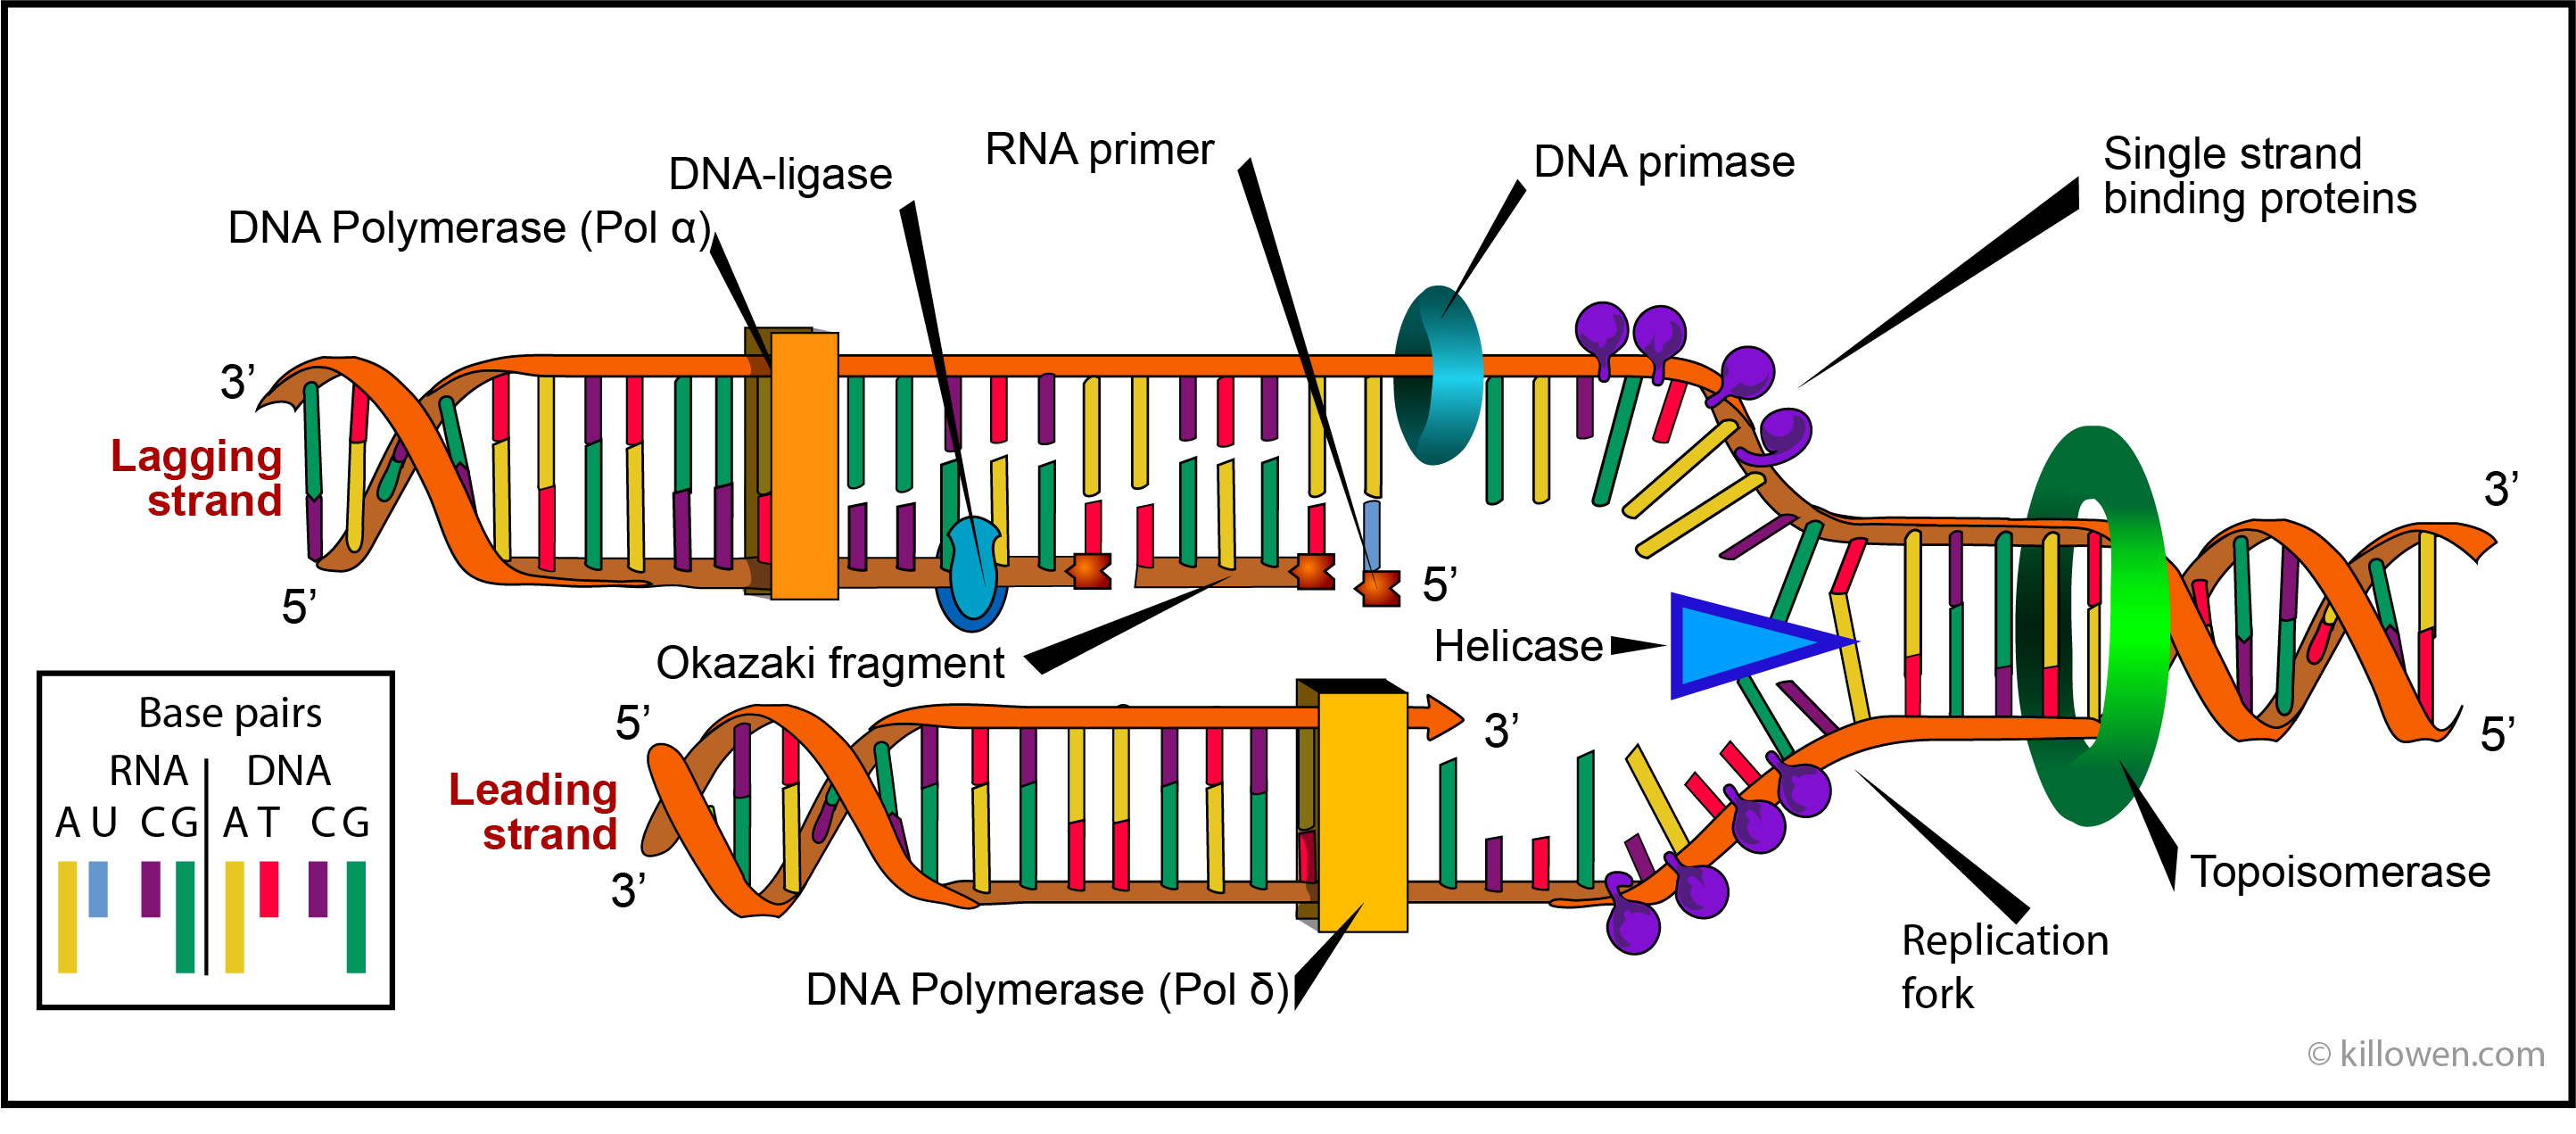
Here's the sequence as it actually happens in a cell: helicase unwinds the double helix at the origin of replication, creating a replication bubble. Single-strand binding proteins keep the strands apart so they don't snap back together. Topoisomerase relieves the supercoiling tension that builds up ahead of the fork — without this, the helix would twist itself into a knot and replication would stall completely. Primase then lays down a short RNA primer, and DNA polymerase III extends from that primer by adding complementary nucleotides. This is where most explanations get sloppy. The leading strand is easy — polymerase just marches forward continuously in the 5' to 3' direction, following the opening fork. The lagging strand goes the opposite way relative to fork movement, so polymerase has to work backwards in little bursts. Each burst starts with a new RNA primer, then extends until it hits the previous fragment. These are Okazaki fragments, named after the Japanese biochemist who discovered them in the 1960s. In prokaryotes, Okazaki fragments run about 1,000 to 2,000 nucleotides long. In eukaryotes they're much shorter, roughly 100 to 200 nucleotides. The difference matters because it reflects the complexity of packaging DNA around histones. You can't just unwind eukaryotic chromatin the way you unwind naked bacterial DNA — nucleosomes have to be disassembled ahead of the fork and reassembled behind it, and that adds a whole layer of coordination that doesn't exist in E. coli.
What Actually Goes Wrong in Practice
I spent a few years working in a molecular biology lab running PCR assays, and the replication machinery that matters most in practice isn't the cellular version — it's the artificial version you set up in a thermocycler. The principles are the same, but the failure modes are where you learn something. One specific issue I ran into repeatedly involved GC-rich templates. Regions with high guanine-cytosine content form stronger hydrogen bonds and tend to fold into secondary structures like hairpins and G-quadruplexes. Standard Taq polymerase would stall at these sites, producing truncated products that showed up as smears on a gel instead of clean bands. The workaround was switching to a blend polymerase with proofreading capability and adding betaine — a chemical that equalizes the melting behavior of A-T and G-C base pairs, effectively lowering the effective melting temperature of problematic regions. Another thing nobody warns you about: template purity. If your DNA prep has even trace amounts of ethanol from the precipitation step, it inhibits polymerase activity. I once spent three days troubleshooting why my reactions weren't working, only to realize the pellet hadn't been fully air-dried. A quick 10-minute spin in a vacuum concentrator fixed it. You learn to respect the small stuff because the big concepts don't fail you — the impurities do.
The Proofreading Problem
DNA polymerase III has a 3' to 5' exonuclease activity that acts as a proofreading mechanism. When it misincorporates a nucleotide, the enzyme backs up, cuts out the wrong base, and resumes synthesis. This drops the error rate from about 1 in 10,000 nucleotides to roughly 1 in 10 million. But even that isn't good enough for complex organisms, which is why mismatch repair systems kick in after replication is complete, catching errors that polymerase missed. The counter-intuitive part is that proofreading comes at a cost. Pol III with proofreading active is slower than without it. There's a trade-off between speed and fidelity that evolution has already optimized for most organisms. When you're doing synthetic biology work and you need high-fidelity amplification, you choose a polymerase like Phusion or Q5 that has both high speed and strong proofreading — they're engineered versions that break the normal trade-off. They cost about five times more than standard Taq, but you save money on cleanup when the products actually work.
Get the Full Details
Where the Model Breaks Down
The textbook replication fork model works fine for standard linear chromosomes under ideal conditions. It doesn't account well for telomere shortening, which is a real problem in eukaryotic cells because DNA polymerase can't fully replicate the extreme 3' end of linear DNA. Telomerase solves this in stem cells and germ cells, but most somatic cells lack sufficient telomerase activity, which is why telomeres shorten with each division and eventually trigger senescence. If you're studying aging or cancer, this is the part of replication that actually matters, not the basic mechanism. Replication also fails completely under certain conditions. Hydroxyurea blocks ribonucleotide reductase, depleting the dNTP pool, and replication stalls within minutes. Caffeine at high concentrations inhibits ATM kinase, which disrupts the checkpoint response, so cells with damaged DNA continue replicating and accumulate mutations. These aren't edge cases in research — they're standard tools for arresting cells or forcing mutagenesis depending on what you're trying to study. The biggest misconception is that replication is error-free because the machinery is so elaborate. It's not. Errors still happen, and most of the time the repair systems catch them. But when they don't, that's where mutations come from, and that's where things like hereditary cancers and genetic disorders originate. The system is good, not perfect, and treating it as perfect is the kind of simplification that causes real problems in applied work.