What Actually Causes Mutations
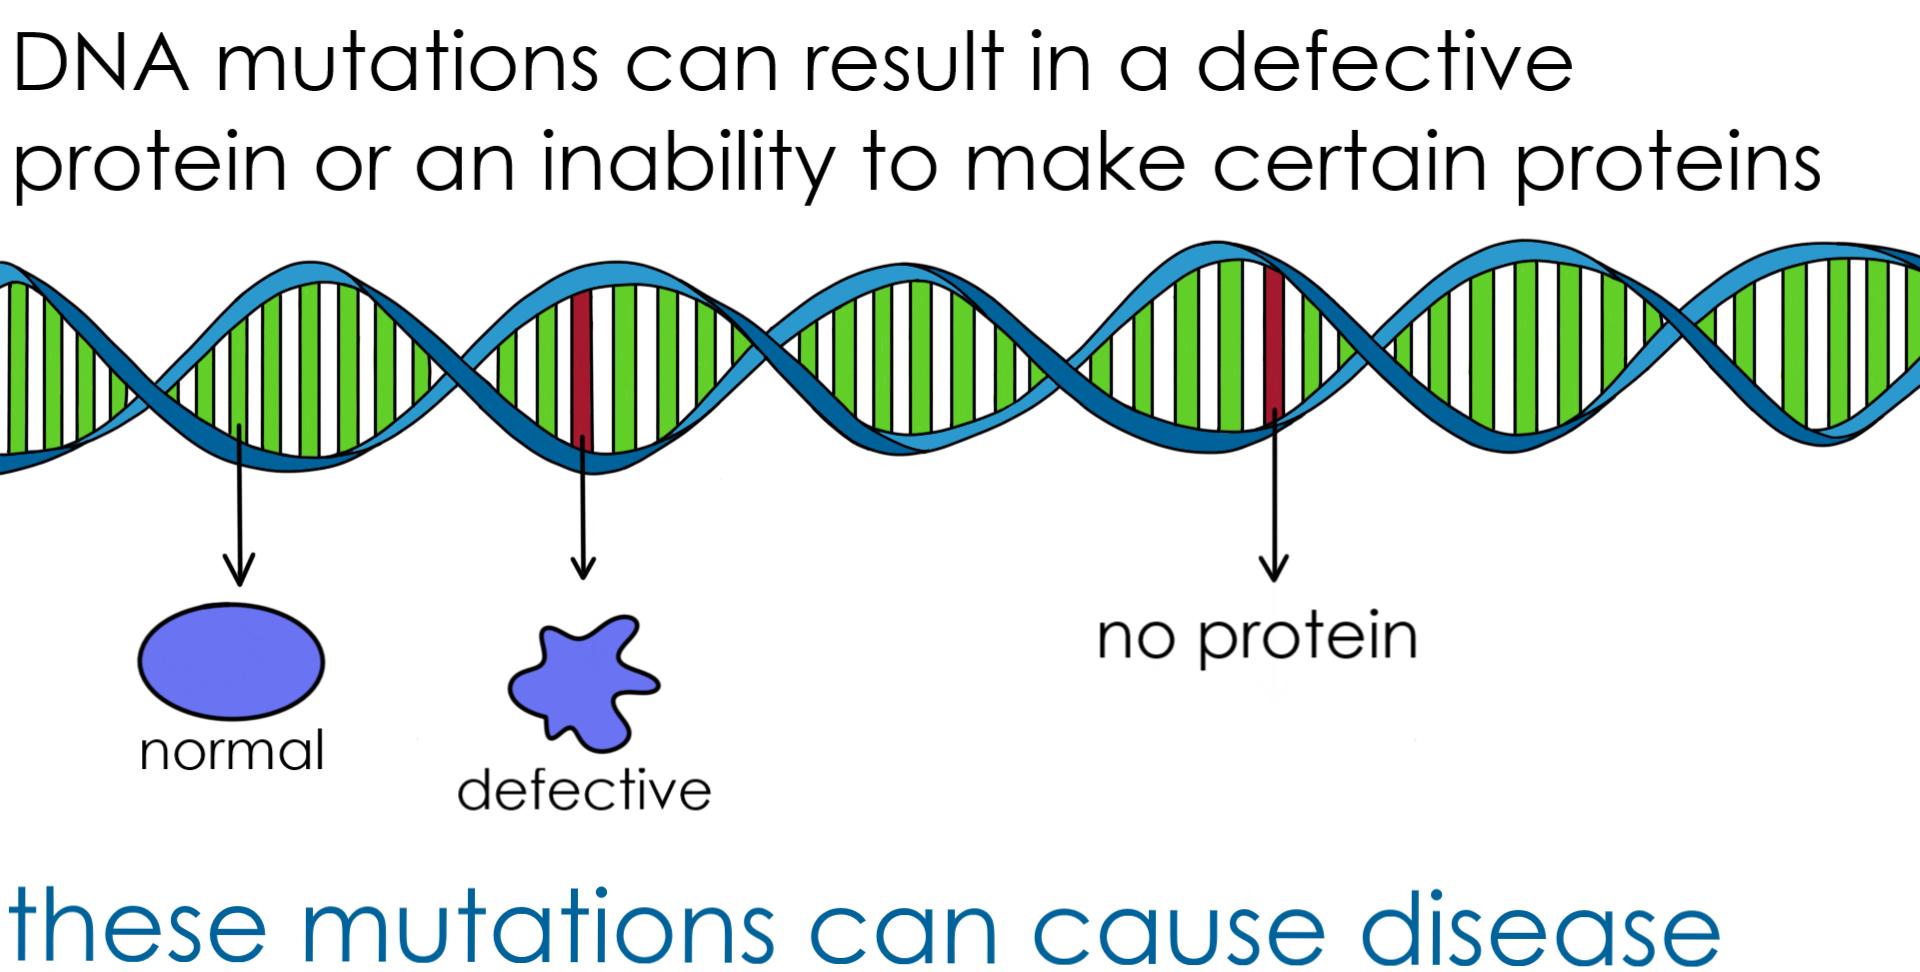
Gene mutations happen because DNA replication isn't perfect, and cells are constantly exposed to things that damage their genetic material. That's really the short version. The mechanisms are more specific than that though, and understanding them helps if you're working in a lab or studying genetics seriously. There are several distinct pathways through which mutations occur. The most common one is during DNA replication, where polymerase enzymes copy the genome and occasionally slip up. Human DNA polymerase makes roughly one mistake per billion nucleotides copied, and while proofreading mechanisms catch most of those, some get through. That baseline error rate is why spontaneous mutations exist in every population. Then there are environmental mutagens. UV light causes thymine dimers, where adjacent thymines bond to each other instead of pairing with adenines. Alkylating agents add methyl or ethyl groups to bases, changing their pairing behavior. Ionizing radiation shatters the sugar-phosphate backbone, creating double-strand breaks that are painful for the cell to repair correctly.
Reactive oxygen species from normal metabolism also cause damage. Superoxide radicals oxidize guanine to 8-oxoguanine, which pairs with adenine instead of cytosine. Every cell dealing with aerobic respiration is slowly cooking its own DNA unless antioxidant systems keep up, and they don't always keep up. Transposons are another factor. Jumping genes move around the genome and can disrupt coding sequences when they land in them. They're a significant source of structural variation in many organisms.
Practical details most textbooks gloss over
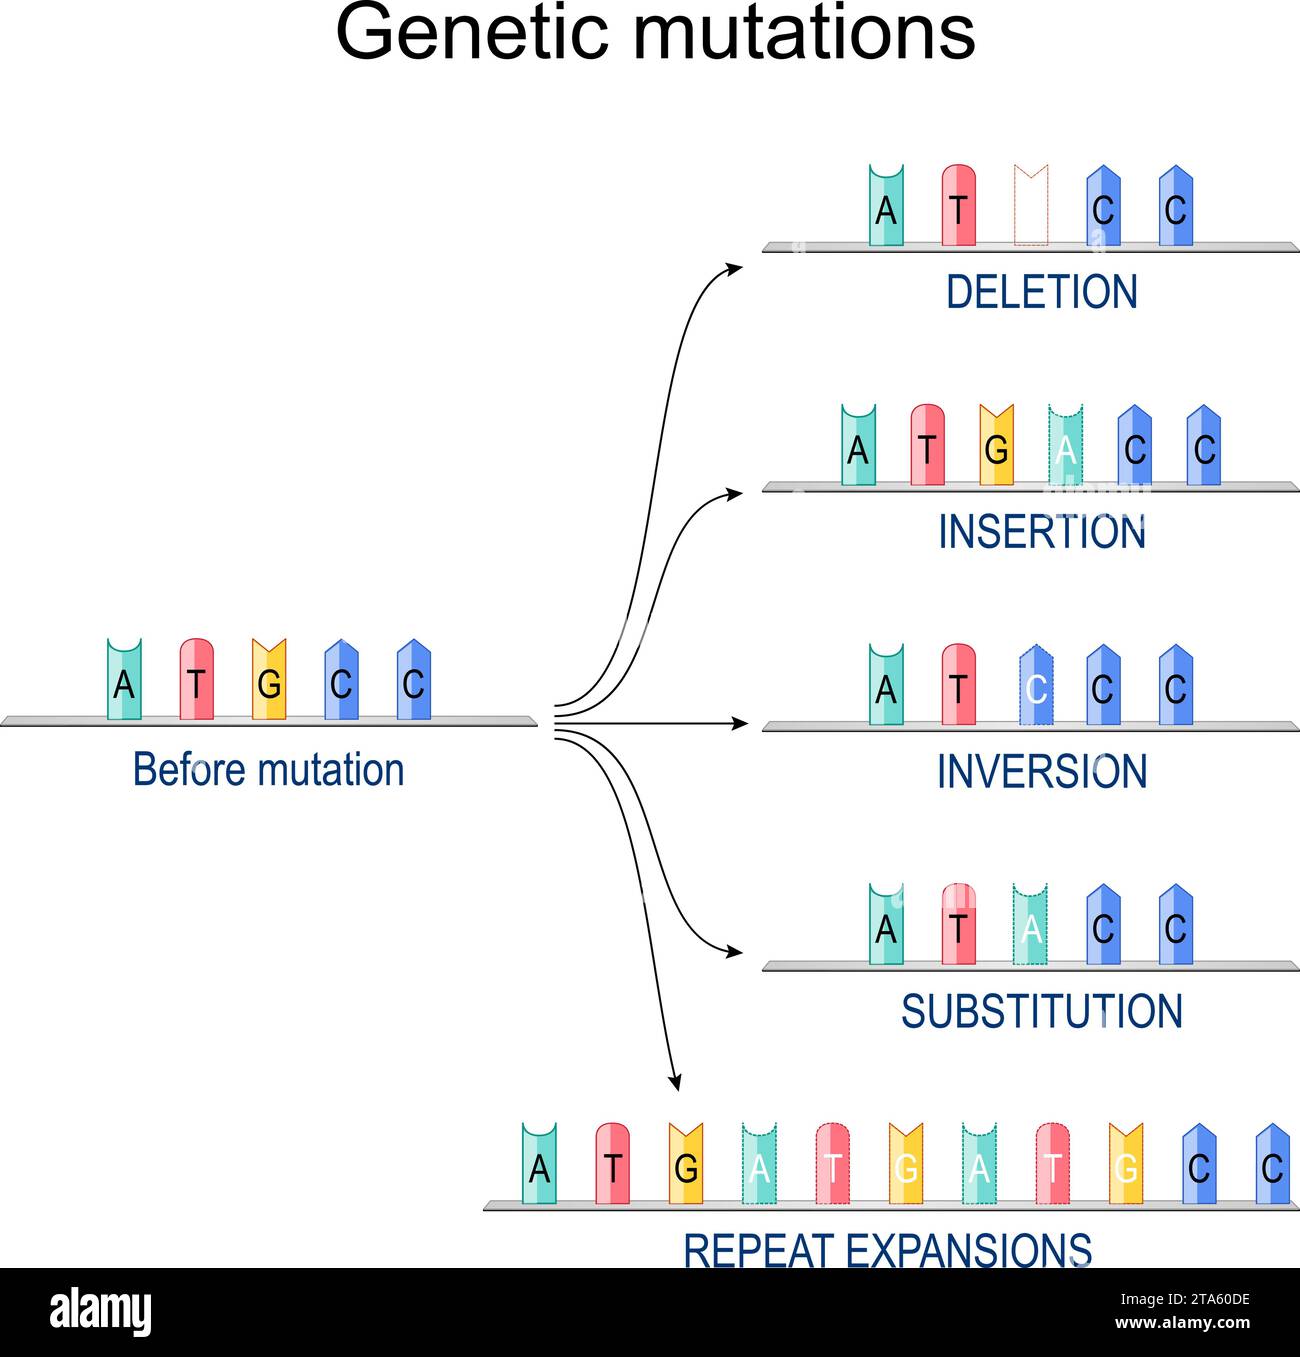
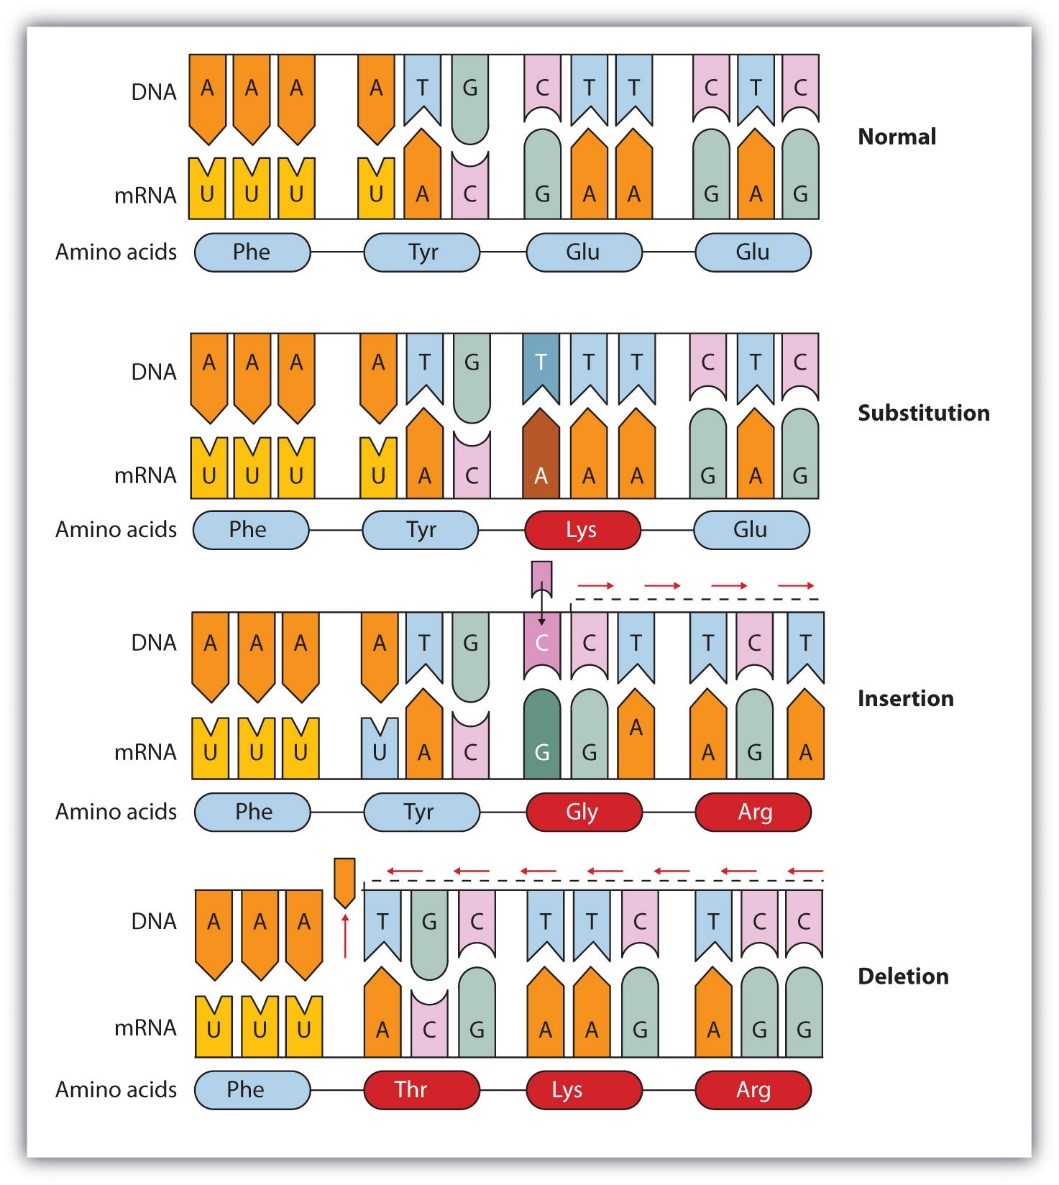
One thing beginners consistently misunderstand is the difference between a mutation and a polymorphism. A mutation is any change to the DNA sequence. A polymorphism is just a mutation that's common enough to be considered normal variation in the population, usually above a 1 percent allele frequency threshold. Same mechanism, different categorization based on prevalence. The distinction matters mostly for medical genetics where calling something a polymorphism rather than a pathogenic mutation changes how you interpret clinical significance. Another counter-intuitive point: most mutations that actually occur are neutral. The human genome is roughly 3 billion base pairs, but only about 1 to 2 percent codes for proteins. Even within coding regions, the degeneracy of the genetic code means many nucleotide changes don't alter the resulting amino acid. Synonymous mutations are everywhere and largely invisible to selection unless they affect splicing or mRNA stability in ways that aren't obvious from the sequence alone. I ran into a specific problem once while analyzing a set of whole genome sequencing data from a cancer study. We kept seeing what looked like germline variants in tumor samples, but they didn't match the patient's matched normal tissue. It turned out the alignment pipeline was mis-mapping reads in a region with a segmental duplication. The variant caller reported a heterozygous SNP that was actually an artifact of reads from a paralogous region aligning to the wrong copy. The fix was switching to a more aggressive duplicate-aware alignment and using a decoy genome to absorb those mis-mapped reads. Without that, we would have spent weeks chasing false positive mutations and drawing wrong conclusions about clonal evolution.
Get the Full Details
Repair mechanisms and why they matter
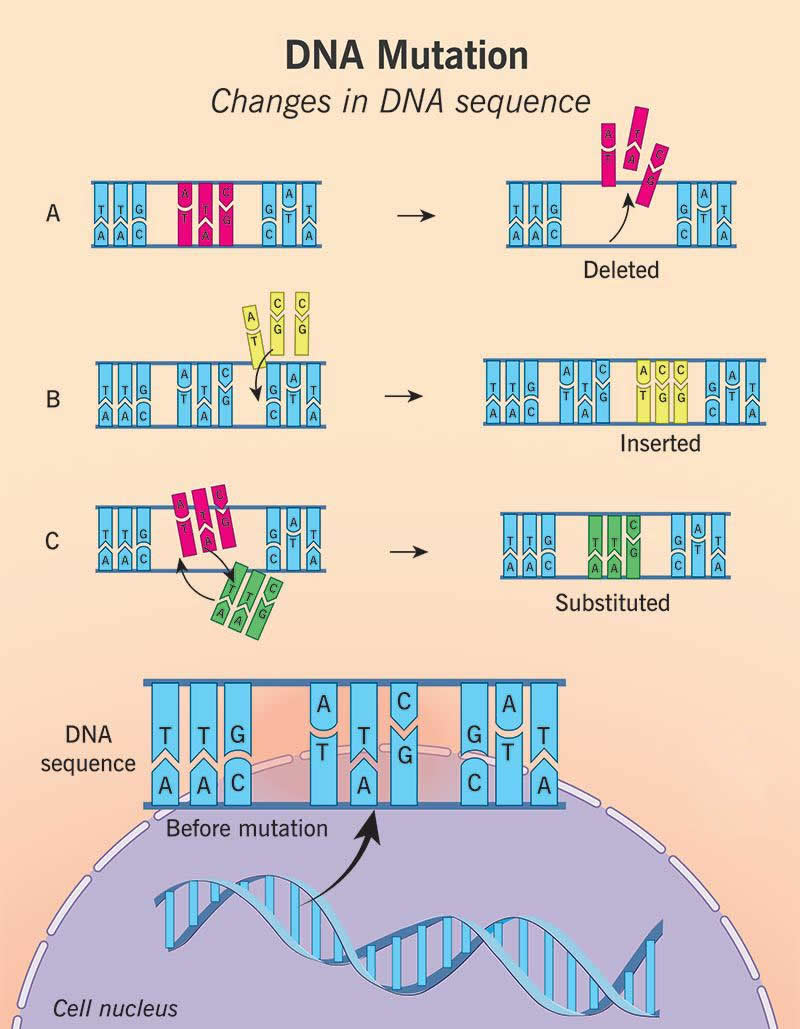
Cells have multiple repair pathways, and which one handles a given lesion determines the mutation outcome. Mismatch repair catches replication errors and can reduce the error rate by another hundredfold. Defects in mismatch repair genes like MLH1 or MSH2 lead to microsatellite instability, which is a hallmark of certain Lynch syndrome cancers. Base excision repair handles damaged bases like 8-oxoguanine. Nucleotide excision repair deals with bulky lesions like thymine dimers. Double-strand breaks are the most dangerous kind of damage, and the cell can fix them through non-homologous end joining or homologous recombination. NHEJ is fast but error-prone, often introducing small insertions or deletions at the break site. HR is accurate but only available during S and G2 phases when a sister chromatid is present as a template. The choice between these pathways isn't random. ATM and ATR kinases sense damage and coordinate the response, but under replication stress or in rapidly dividing cells, error-prone repair wins out more often. That's why tissues with high turnover rates accumulate mutations faster, and it's also why radiation therapy works for cancer, by pushing cells into using those error-prone pathways until they cross a threshold where they can't survive.
When mutation rates aren't constant
Sometimes mutation rates spike locally. Stress-induced mutagenesis is a real phenomenon where cells under nutrient starvation or antibiotic pressure increase their mutation rate through mechanisms like the SOS response in bacteria. In eukaryotes, the concept is less well-defined but hypermutation does occur at immunoglobulin loci during somatic hypermutation in B cells, where AID enzyme deliberately introduces point mutations to drive antibody affinity maturation. The AID mechanism is fascinating and terrifying in equal measure because off-target activity contributes to lymphomas. AID can deaminate cytosines outside of Ig loci, creating mutations in proto-oncogenes. I've seen cases where the mutation signature in a lymphoma biopsy pointed directly to AID-mediated damage far from the Ig heavy chain locus, confirming that the enzyme had gone rogue. Replication timing also influences mutation patterns. Late-replicating regions tend to have higher mutation rates, likely because they spend more time in a vulnerable single-stranded state and have less time for repair before the cell divides. This creates a predictable mutational signature that depends on when during S phase a given region is copied.
What this means for practical work
If you're interpreting sequencing data, understanding mutation mechanisms helps you distinguish real variants from artifacts. UV-induced mutations show a strong C to T transition signature at dipyrimidine sites. Smoking-related mutations show characteristic C to A transversions. Different mutagens leave different footprints, and those footprints are what mutation signature analysis is built on. The limitation everyone hits is that correlation doesn't equal causation. A mutational signature might match tobacco exposure, but other environmental factors can produce overlapping patterns. You need clinical context alongside the molecular data to make reliable inferences. And no current method can reliably detect every class of mutation from sequencing alone. Large structural variants, repeat expansions, and complex rearrangements often require orthogonal validation through long-read sequencing or cytogenetic methods. For most people studying this, the takeaway is that mutations are just chemistry and physics acting on DNA over time. The machinery exists to repair damage, but it's imperfect, and in certain conditions that imperfection becomes visible as disease or evolutionary change. Nothing dramatic about it, just the way biology works.