Getting into genetic engineering isn't complicated once you stop watching sci-fi movies
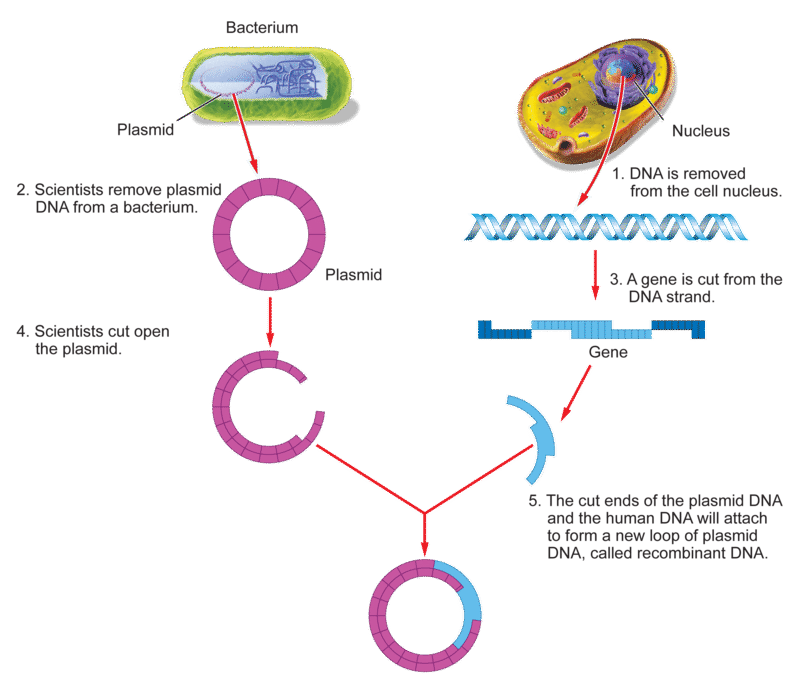
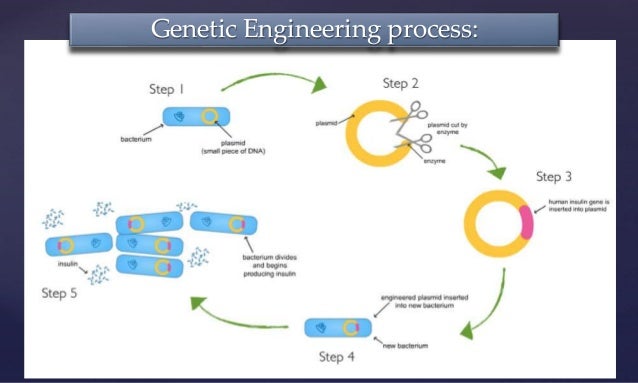
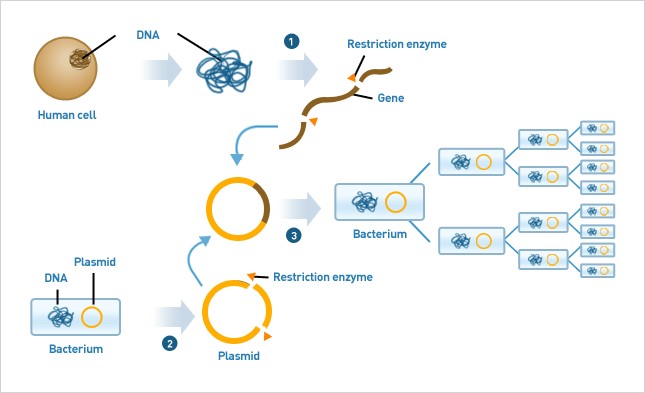
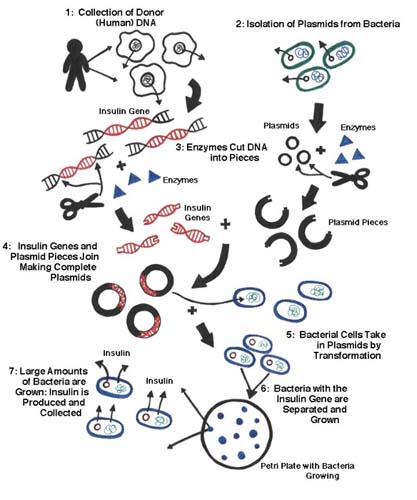
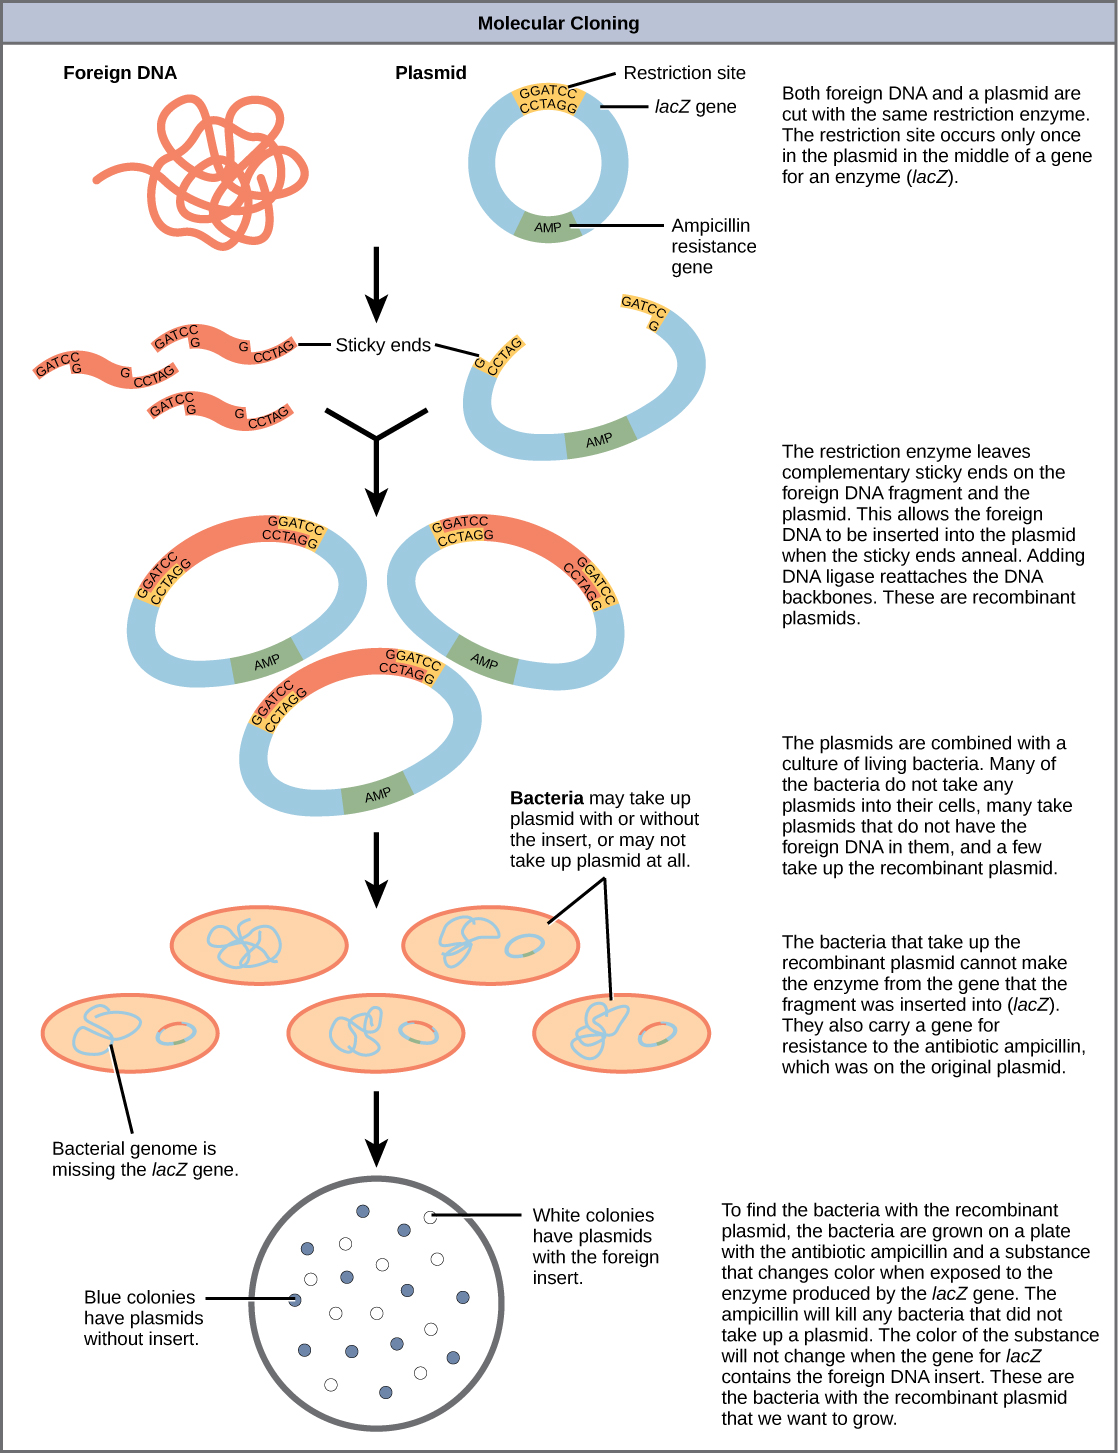
I spent seven years working in molecular biology before moving into bioinformatics. The lab bench part taught me something most tutorials skip: the difference between what you read in textbooks and what actually happens when your plasmid prep goes sideways at 2 AM. Let me walk through the actual process. At its core, genetic engineering means taking DNA from one organism and putting it into another. The DNA gets read by the host cell's machinery just like native DNA. This sounds simple but the execution requires understanding three separate steps: cutting, pasting, and verifying the insert stays where you put it. Most people learn about restriction enzymes first. These are bacterial proteins that cut DNA at specific sequences. The classic example is EcoRI, which recognizes GAATTC and cuts between the G and the A. You digest your vector and your insert with the same enzyme, creating compatible sticky ends. The single-stranded overhangs base-pair with each other. This happens fast at room temperature, maybe 15 to 30 minutes depending on the enzyme lot and buffer conditions.
Then you ligate the pieces together. T4 DNA ligase seals the nicks in the backbone. You typically set this up for one hour at room temperature or overnight at 16 degrees Celsius. The molar ratio matters more than most beginners realize. A 3-to-1 insert-to-vector ratio usually works, but I have seen successful ligations at 1:1 and failed ones at 10:1. It depends on how clean your ends are and whether your insert has internal restriction sites that might re-cut after ligation. The transformation step is where things get interesting. You take your ligation product and introduce it into competent E. coli cells. Chemical competence using calcium chloride works for routine cloning, but electroporation gives you 100 to 1000 times better efficiency. I switched to electroporation when I started working with large constructs because chemical methods just did not give me enough colonies to pick from. You spread the cells on antibiotic selection plates and wait 12 to 16 hours for colonies to appear. Each colony comes from a single cell that took up a recombinant plasmid. But here is the thing nobody tells you: not every colony has the right insert. You need to verify by colony PCR, restriction digest, or sequencing. I learned this the hard way when I spent three days trying to express a protein that turned out to be the wrong reading frame because I skipped the sequencing step.
The verification part deserves more attention than it gets. Colony PCR with vector-specific primers flanking the insertion site gives you a quick size check in about 3 hours including setup and run time. But PCR alone will not tell you if there are point mutations in your insert. For that you need Sanger sequencing, which costs about 20 dollars per reaction and takes 24 to 48 hours. I always sequence both directions to catch any artifacts from the polymerase. Modern genetic engineering has moved beyond restriction-based cloning. Gateway recombination uses bacteriophage attachment sites to move DNA between vectors without restriction enzymes. Golden Gate assembly uses Type IIS restriction enzymes that cut outside their recognition sequence, allowing you to assemble multiple fragments in a single reaction. These methods cost more per reaction but save you 2 to 3 days of optimization when you are doing high-throughput cloning. CRISPR-Cas9 changed the field but it is not a magic bullet. The system works by using a guide RNA to direct the Cas9 nuclease to a specific DNA sequence. The enzyme creates a double-strand break that the cell repairs through non-homologous end joining or homology-directed repair. Non-homologous end joining is error-prone and usually creates small insertions or deletions. Homology-directed repair requires a donor template and works efficiently only in dividing cells.
Get the Full Details
I ran into trouble with off-target effects when I was doing gene knockouts in human cell lines. The guide RNA sometimes bound to related sequences with a few mismatches. I solved this by using truncated guide RNAs that were 17 to 18 nucleotides instead of the standard 20, which reduced off-target binding by about 60 percent according to GUIDE-seq analysis. It was a pain to design all new guides but the results were cleaner. Gene delivery is the bottleneck that everyone underestimates. Viral vectors like lentivirus give you stable integration but require BSL-2 containment and take 2 to 3 weeks to produce. Adeno-associated virus gives you long-term expression without integration but has a small payload capacity of about 4.7 kilobases. Non-viral methods like lipofection are fast but give you transient expression that fades in 3 to 5 days. I spent six months troubleshooting low transduction efficiency in primary T cells before realizing the issue was receptor down-regulation. The cells lost CD4 and CCR5 expression during expansion. I solved this by selecting for highly expressing cells using fluorescence-activated cell sorting before viral infection. The sorted population showed 10 to 50 times better transduction efficiency, though it meant I could only work with about 10 to 20 million cells per experiment.
The quality control part is where most projects fail. You need to verify your construct by Sanger sequencing across the entire insert and both junctions. You need to check for contamination by mycoplasma testing, which can take 24 hours but saves you from wasting months on infected cultures. You need to confirm functionality by expression analysis, usually Western blot or flow cytometry. I encountered a problem with silent mutations in my expression vector that created a cryptic splice site. The protein ran at the wrong molecular weight on SDS-PAGE, about 15 kilodaltons smaller than expected. I spent two weeks troubleshooting before sequencing revealed the mutation I had introduced during PCR. The workaround was redesigning the construct using overlapping extension PCR to remove the problematic region, which added 3 to 4 days to the timeline but saved the project. Digital PCR and next-generation sequencing have made genotyping faster but they do not replace careful planning. You need to think about your reading frame, your tag placement, and your cleavage sites before you order primers. The cost of oligonucleotides is cheap, maybe 5 dollars per primer, but the cost of starting over because you missed a restriction site is 2 to 3 weeks of lost time.
Genetic engineering works because cells are generic DNA readers. They do not care where the DNA came from. What matters is that your construct has the right elements: a promoter the host recognizes, a ribosome binding site in bacteria, a start codon in the correct frame, and a terminator. Everything else is optimization and troubleshooting.