Logarithms Are Just Exponentiation in Reverse
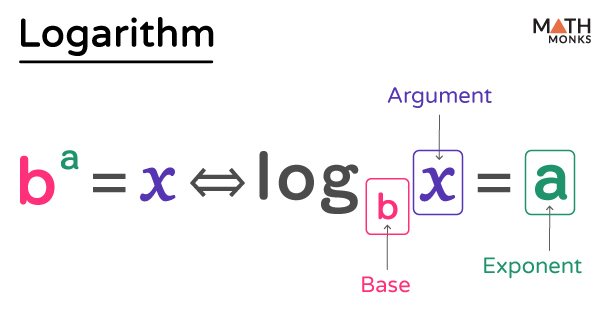
You already know exponents. 2 to the 3rd power is 8. A log asks the opposite question: what power do I raise 2 to, in order to get 8? The answer is 3. That's it. log base 2 of 8 equals 3. Every log problem is that same rearrangement, repeated at scale. I started using logs in engineering school and honestly didn't grok them until I was debugging a signal processing pipeline and kept running into decibel calculations at 2 AM. The math wasn't the problem. The problem was I was treating them like abstract symbols instead of a tool for compressing ranges. Once I stopped trying to memorize rules and just thought about them as "what exponent do I need," everything clicked.
How Does Log Work
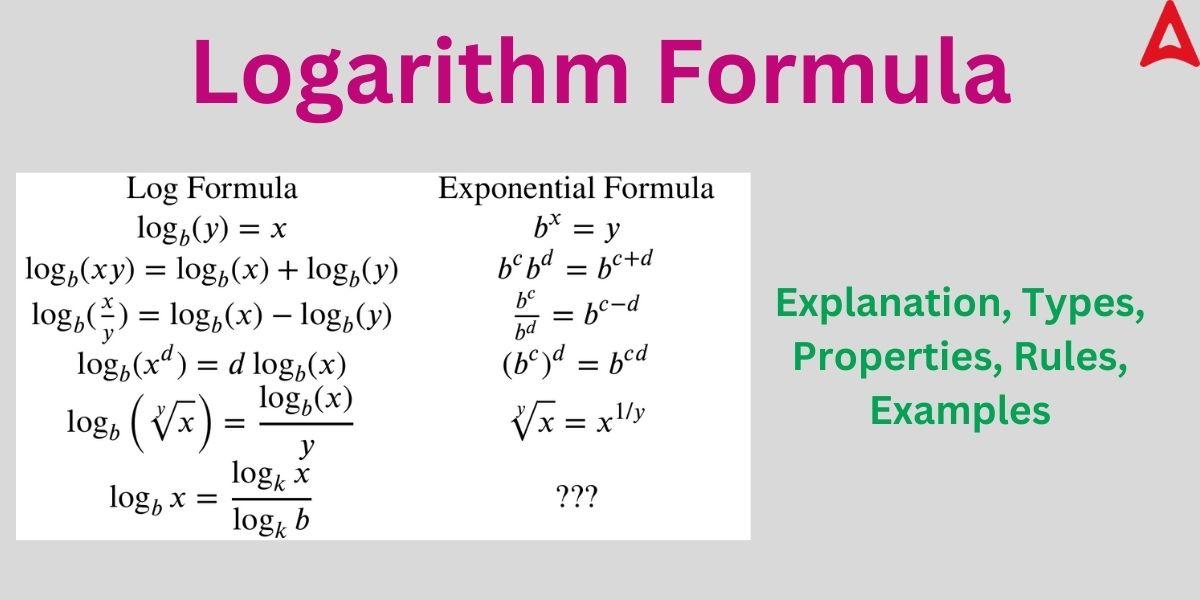
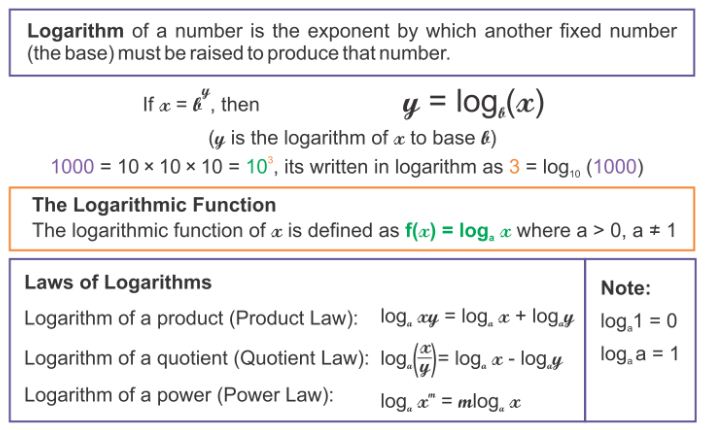
The formal definition is straightforward but easy to screw up in practice. For a base b, log_b(x) = y means b^y = x. The base has to be positive and not equal to 1. The input has to be positive. If either condition breaks, you're working outside real numbers and you need to pivot to complex logarithms or just stop and rethink your approach. There are three bases you'll actually encounter in the wild. Base 10 is the common log, used in pH calculations and earthquake magnitudes. Base e, roughly 2.71828, is the natural log, written ln, and it's the one that shows up in growth models, half-life problems, and basically any differential equation you'll ever care about. Base 2 is the binary log, and it's everywhere in computer science—algorithm complexity, information theory, data structures. When someone says "log" without specifying a base in a CS context, they almost always mean base 2. In calculus, they mean base e. In a chemistry lab, they mean base 10. Context does the heavy lifting. Here's the core mechanic. Logs turn multiplication into addition. log(ab) = log(a) + log(b). They turn division into subtraction. They turn exponentiation into multiplication: log(a^b) = b * log(a). This is why they exist as a thing. Before calculators, people used log tables to multiply huge numbers by looking up their logs, adding those logs, and looking up the antilog of the sum. Google's slide rule did the same thing mechanically. The principle hasn't changed, only the tool has.
Let me give you a concrete example that isn't from a textbook. Say you're modeling user growth and your daily active users go from 1,000 to 64,000 over a certain period. You want to know the doubling time. You set up the equation 1000 * 2^t = 64000. Divide both sides by 1000 and you get 2^t = 64. Take log base 2 of both sides and t = log_2(64) = 6. Six doublings. If each doubling took roughly 30 days, that's about five months of growth. You didn't need a fancy solver. You needed to recognize the pattern and apply the inverse relationship. One thing that trips people up consistently is the change of base formula. Not every calculator has a log base 2 button. The formula is log_b(x) = log_k(x) / log_k(b) for any base k you can compute. In practice, you just use base 10 or base e. log_2(100) = ln(100) / ln(2) 4.605 / 0.693 6.644. You can verify this by checking that 2^6.644 100. This formula is also why all log functions share the same shape, just scaled differently on the axes. They're the same curve wearing different hats. I ran into a real edge case once while working on a machine learning feature scaling pipeline. I was applying log transforms to skewed features before feeding them into a model. Standard approach: take the log of each value to compress the long right tail. The problem was zero and negative values in the dataset. Log of zero is undefined. Log of a negative number is complex. My first instinct was to drop those rows, but that introduced selection bias that wrecked the model's calibration on the minority class. The workaround was straightforward but took me three iterations to land on: add a small constant before logging. log(x + c) where c is something like 1 or the smallest positive value in your data minus epsilon. I ended up using c = 0.5 after cross-validation showed it minimized distortion while preserving the relative ordering. It's a hack, not a theorem, but it's what the literature recommends and it works in production.
Get the Full Details

Here are some properties you should actually memorize because you'll reach for them constantly. log(1) = 0 for any base. log(b) = 1. The log of a product splits into a sum. The log of a quotient splits into a difference. The log of a power pulls the exponent out front. These aren't optional. They're the engine. If you can't manipulate these fluently, you're going to struggle with anything beyond introductory problems. Another thing beginners miss is that logs grow incredibly slowly. log_2(1024) = 10. log_2(1,048,576) = 20. You multiplied the input by a million and the output only doubled. This is why log scales are useful for data that spans many orders of magnitude. Your financial dataset with incomes ranging from $20,000 to $20,000,000 looks like a mess on a linear scale. On a log scale, it's ten steps. Plotting with a log y-axis doesn't change the data. It changes how your eyes read the data. The derivative of ln(x) is 1/x. That's unusually clean for calculus and it's the reason natural logs dominate throughout mathematics. The derivative of log_b(x) is 1/(x * ln(b)). The chain rule applies normally. Integration works the other direction: the integral of 1/x dx is ln|x| + C. The absolute value matters because the domain of 1/x includes negative numbers, and the antiderivative needs to be defined there too. I've lost points on exams for forgetting that absolute value bar more times than I'm willing to admit.
There are limits you need to know. As x approaches 0 from the right, log(x) approaches negative infinity. As x approaches infinity, log(x) approaches infinity, but agonizingly slowly. This asymptotic behavior at zero is why log transforms can't handle zero natively without the constant shift I mentioned. It's also why log-likelihood functions in statistics can go to negative infinity, which matters for optimization algorithms that need to converge. Common mistakes. Treating log(a + b) as log(a) + log(b). That's wrong and it's wrong in the same way that sqrt(a + b) isn't sqrt(a) + sqrt(b). Logs don't distribute over addition. Another mistake is assuming log(-5) is a valid real number. It's not. If you end up with a negative argument after simplifying a log expression, you've made an error somewhere or you're in complex territory. A third mistake is confusing log(x^2) with 2*log(x). They're only equal when x is positive. For negative x, log(x^2) = 2*log(|x|). The domain matters. For practical computation, if you're doing this by hand, natural logs and common logs have tabulated values. If you're doing this in code, almost every language provides log (natural) and log10. Python's math.log(x, base) lets you specify any base directly. JavaScript's Math.log is natural log only, so you'd use Math.log(x) / Math.log(base) for other bases. Excel and Google Sheets have LOG and LN functions. The built-in functions are accurate to machine precision, so there's no reason to approximate unless you're working in an environment without standard libraries.
The bigger picture is that logarithms are a change of perspective. They let you trade multiplicative relationships for additive ones, exponential growth for linear growth, and enormous ranges for manageable numbers. That trade is almost always worth it. The situations where it isn't worth it are when your data has zeros or negatives and you're unwilling to handle the shift, or when the interpretability of the original scale matters more than the mathematical convenience. In those cases, stick to the raw numbers or consider a square root transform as a gentler alternative that still compresses variance without the domain issues. If you want to build intuition, pick a base and compute ten values by hand. Pick base 2. Compute log_2(1), log_2(2), log_2(4), log_2(8), log_2(16), log_2(32), log_2(64), log_2(128), log_2(256), log_2(512). Then pick a non-power-of-two like 10 and figure out that log_2(10) sits between 3 and 4 because 2^3 = 8 and 2^4 = 16. You can estimate it as roughly 3.32 by thinking about where 10 falls between 8 and 16 on a multiplicative scale. This kind of exercise makes the function feel real instead of like a set of rules to memorize for a test. Resources for going deeper. Paul's Online Math Notes has a solid calculus section on logarithms with worked examples. Khan Academy covers the algebra side thoroughly. For the computational angle, the Python documentation for the math module shows you the available functions and their behavior with edge cases. If you're working in statistics, Gelman's lectures on regression with log-transformed variables are worth watching because they address the back-transformation bias problem that most introductory courses skip over entirely.