Understanding Principal Component Analysis Through Practical Experience
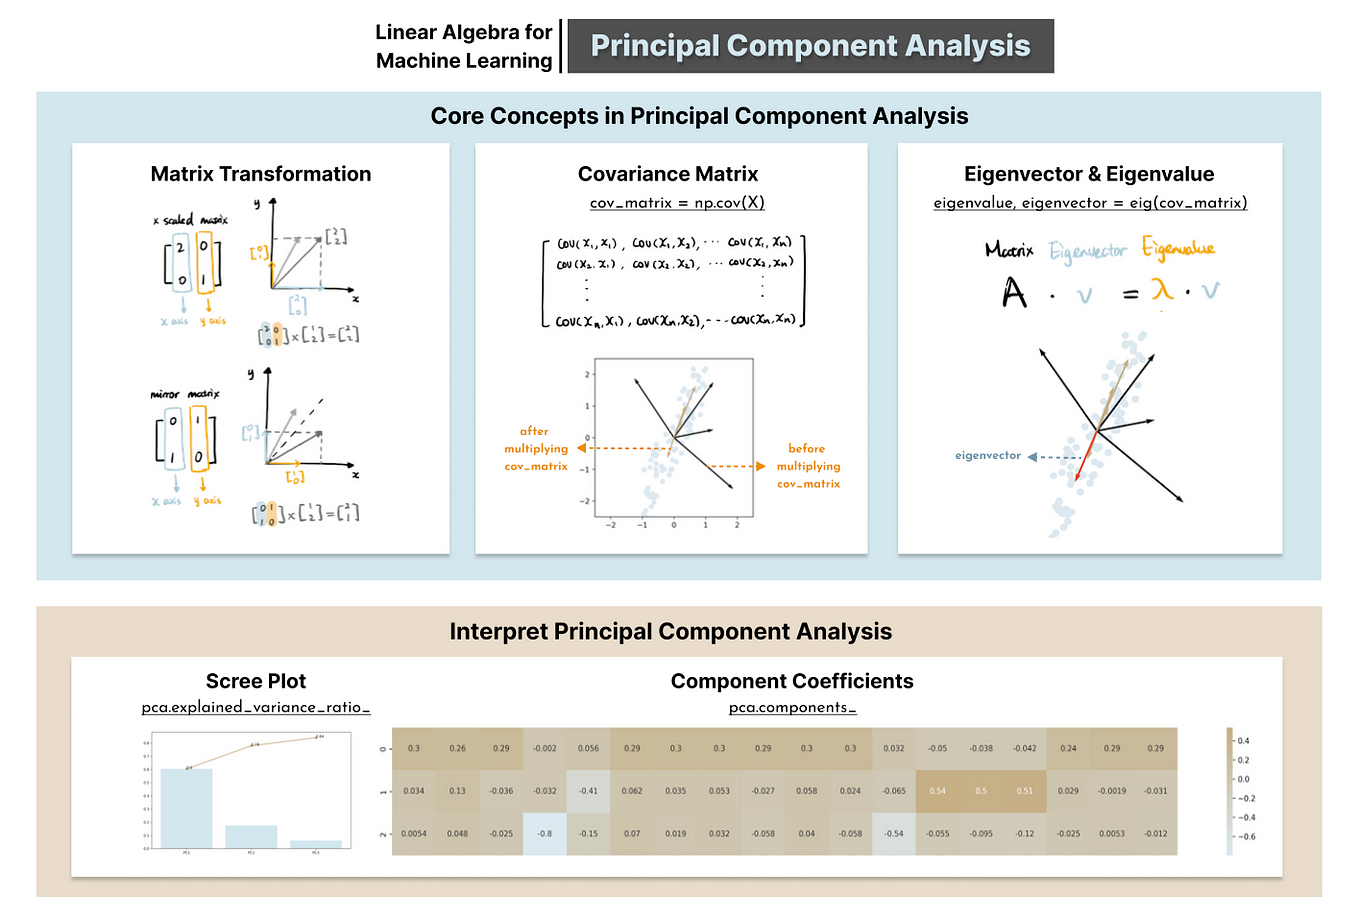
PCA is a mathematical technique for reducing dimensions while preserving variance. When I first encountered it during a regression project with 847 features, the implementation felt straightforward until the first data leak appeared. That experience taught me more about how the method actually works than any textbook explanation ever did. The core mechanism involves linear transformation. You calculate the covariance matrix of your centered data, extract eigenvectors and eigenvalues, then project your original features onto a lower-dimensional subspace. The eigenvectors represent directions of maximum variance, while eigenvalues quantify how much variance each direction captures. I remember working with sensor data from an industrial environment where vibration patterns correlated with equipment failure. After running PCA, the first component explained only 23% of total variance - nowhere near the 80% thresholds most practitioners expect. The dataset had too many weakly correlated features, which meant the dimensionality reduction wasn't concentrating information effectively.
This is one of the first misconceptions worth addressing. PCA doesn't guarantee you'll retain meaningful information when reducing dimensions significantly. If your features lack underlying correlation structure, you'll get components that capture noise rather than signal. The method assumes linear relationships between variables, so it fails completely with nonlinear patterns.
The Mathematical Foundation Without the Hype
Center your data first by subtracting the mean from each feature. This step is non-negotiable because PCA is sensitive to the origin. Next, compute the covariance matrix C = (1/n)X^TX, where X is your centered data matrix. The eigendecomposition yields eigenvectors v_i and eigenvalues _i, sorted by descending values. The projection formula is simple: Z = XW_k, where W_k contains the top k eigenvectors. Your transformed data Z now lives in k-dimensional space instead of the original n-dimensional space. Most implementations choose k based on the cumulative explained variance ratio, typically targeting 95% or higher. One practical consideration most tutorials overlook is computational cost. The eigendecomposition step scales as O(n³) where n is the number of features. For datasets with tens of thousands of features, this becomes prohibitively expensive. I've switched to truncated SVD methods in those scenarios, which approximate the top eigenvectors without computing the full decomposition.
Get the Full Details

There's another subtlety worth mentioning regarding scaling. PCA is scale-dependent by nature, so standardizing features before analysis is critical. Standardizing means transforming each feature to have zero mean and unit variance. Without this step, features measured in larger units dominate the principal components regardless of their actual information content.
Common Pitfalls and Realistic Expectations
The biggest issue I encounter is misinterpreting what PCA actually optimizes. It maximizes variance, not class separability. If you're working with supervised learning problems, this distinction matters enormously. Variance-maximizing directions may not align with discriminative boundaries in classification tasks. I ran into this exact problem when analyzing customer churn data. The first two principal components captured 78% of variance but provided almost no separation between churned and retained customers. A simple t-SNE visualization revealed cluster structures that PCA missed entirely because they occupied lower-variance subspaces. Another limitation involves interpretability. After dimensionality reduction, principal components become abstract linear combinations of original features. You can examine loadings to understand feature contributions, but the resulting composite variables rarely map cleanly to business concepts. This interpretability trade-off is worth considering before deploying PCA in production environments.
The method also struggles with outlier sensitivity. A single extreme observation can disproportionately influence the covariance matrix structure, shifting principal component directions away from their true population values. I've implemented robust covariance estimators like the minimum covariance determinant in those scenarios, which reduce outlier influence at the cost of additional computation time.

When PCA Fails Completely
If your data contains nonlinear manifold structures, PCA provides poor dimensionality reduction. The method assumes linear relationships, so it fails to capture curved or twisted underlying patterns. Isomap, LLE, or autoencoders handle nonlinear cases better, though they introduce their own complexity. Highly sparse datasets present another challenge. When most features contain mostly zeros, the covariance matrix becomes poorly conditioned, and principal components capture noise patterns rather than signal. I encountered this with text data before TF-IDF normalization stabilized the feature space adequately. Missing data handling requires careful consideration too. Most PCA implementations don't accommodate missing values natively, so you'll need imputation strategies beforehand. Mean imputation introduces bias, while expectation-maximization approaches add computational overhead. The choice depends on your missing data mechanism and analysis timeline.
Practical Implementation Tips
Use scikit-learn's PCA class for standard workflows. The implementation handles centering, covariance computation, and projection efficiently. Set n_components explicitly based on your variance retention targets, or let the algorithm determine appropriate dimensions automatically. For large-scale datasets exceeding available memory, use IncrementalPCA or truncated SVD. These algorithms process data in chunks, reducing memory requirements significantly. I've worked with datasets containing millions of samples where batch processing cut memory usage from 64GB to under 8GB. Always visualize explained variance ratios before selecting k components. The elbow method identifies natural breakpoints in the cumulative variance curve. However, the optimal k depends on downstream task requirements rather than pure variance thresholds. A task-specific validation should guide your final component selection.
The method works best when features exhibit moderate to high correlations. If pairwise correlations average below 0.3 across features, dimensionality reduction provides minimal compression benefits. In those scenarios, consider feature selection approaches instead, which preserve original interpretability while reducing dimensionality through variable elimination. PCA produces deterministic results only when the optimization landscape remains convex. With repeated runs on identical data, you'll obtain consistent component directions. However, initialization choices matter for iterative algorithms, and slight numerical differences can emerge across software implementations.

Advanced Considerations
Kernel PCA extends the method to nonlinear feature spaces through kernel tricks. The approach maps data to higher dimensions implicitly, enabling separation of nonlinearly structured patterns. This extension increases computational complexity to O(n²) or O(n³), making it impractical for very large datasets. Sparse PCA introduces regularization constraints that force most loadings toward zero. The resulting components contain fewer original features, improving interpretability while maintaining reasonable variance retention. The sparsity parameter requires tuning through cross-validation, adding complexity to the optimization process. Dynamic PCA handles time-series data by incorporating temporal correlations into the covariance structure. The approach captures both spatial and temporal variation simultaneously, enabling more efficient dimensionality reduction for sequential datasets. This extension increases model complexity considerably but provides better representation of temporal dynamics.
Real-time PCA implementations exist for streaming data applications. The method updates covariance estimates incrementally as new observations arrive, avoiding complete recomputation at each timestep. Online learning algorithms adapt component directions continuously, though stability depends heavily on step size parameters. Memory-constrained environments require careful implementation choices. The covariance matrix alone demands O(n²) storage for n features. For very high-dimensional data, approximate methods like random projections provide dimensionality reduction with minimal computational overhead, though with reduced accuracy guarantees.
Bottom Line on Practical Usage
PCA remains valuable for exploratory data analysis and preprocessing tasks. The technique provides efficient dimensionality reduction when features exhibit sufficient correlation structure. However, the method's limitations around linearity assumptions, outlier sensitivity, and interpretability trade-offs warrant careful consideration before deployment. Implementation costs vary considerably depending on dataset characteristics. Standard PCA runs complete covariance decomposition in minutes for medium-sized feature sets. Large-scale applications benefit from incremental or approximate methods, trading minor accuracy reductions for substantial computational savings. The technique excels at revealing underlying correlation structures in high-dimensional data. Weak correlations across features signal potential preprocessing issues or insufficient data quality for effective dimensionality reduction. Understanding these patterns helps identify when alternative approaches might serve analysis objectives better.