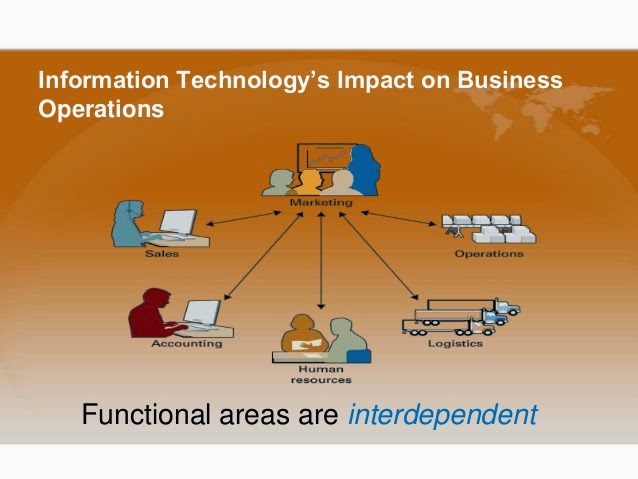
Functional regions and the tech layer underneath them
A functional region is an area organized around a core activity—commuter shed, delivery radius, service catchment—where the boundary isn't fixed by law but by how far something can practically reach. That practical reach has shifted every time a new transport or comms technology matured, and the shift is usually slower than people expect on the ground. I worked on a logistics routing project a few years back where the client insisted their "functional region" for same-day delivery was a 25-kilometer radius from the warehouse. GPS telemetry over six months showed the actual reachable zone was more like 18 kilometers in winter, 22 in summer, and dropped to about 14 during peak traffic hours. The mismatch came from treating distance as a circle when road network topology, toll barriers, and even one frequently closed overpass were doing the real shaping. I ended up running a time-distance matrix against the open road graph and used that to redraw the operational boundary. It saved us from staffing two extra vans that would have sat idle half the day anyway.
How Does Technology Impact Functional Regions
Let me put the method first since that tends to clarify the definition better than starting from scratch. To measure a functional region these days you generally pull origin-destination data—phone pings, transit card taps, GPS traces, or delivery logs—and convert it into isochrones or congestion-weighted service areas using a network analysis tool. Then you compare the resulting shape against the administrative or market-boundary your stakeholders assumed they were working with. The gap between those two is where the actual impact lives. The result is rarely a clean circle. Road hierarchy, signal timing, bridge clearances, and even pricing barriers like tolls carve the reachable space into something that looks more like an amorphous blob with fingers extending along high-capacity corridors and receding in gridlock zones.
Where the impact actually shows up
Transportation technology changed functional regions most visibly. High-speed rail collapsed travel time between mid-sized cities in ways that made previously distinct labor markets overlap. A commuter shed that used to radiate 30 kilometers from a station now extends 60 or 80 kilometers because the train makes the core hour. That creates secondary functional regions around stations that weren't on anyone's map five years ago. Bicycle infrastructure does something similar at a finer grain—protected lanes reshape the walking-distance catchment of grocery stores, clinics, and schools in ways that matter more at the neighborhood level than the regional one. Communications technology altered the boundary conditions for service regions. Telemedicine expanded the functional region of a specialist hospital from the driving radius of its patients to the coverage area of its video platform. That doesn't mean every patient now travels virtually; it means the hub can absorb cases that would have overflowed to a neighboring county before, which reconfigures referral patterns and changes which rural clinics stay viable. Broadband rollout similarly reshapes where commercial activity concentrates—fiber presence is a stronger predictor of small business formation in exurbs than zoning changes in many markets I've seen. Platform and algorithmic technology introduced a different kind of distortion. Ride-hailing and food-delivery apps create dynamic functional regions that shift minute by minute based on supply, surge pricing, and driver positioning. A restaurant's effective delivery zone can expand or contract by three kilometers within an hour depending on how many couriers are online. This makes traditional static catchment analysis obsolete for anyone relying on those platforms, and it also means regulatory boundaries based on fixed service areas are measuring something that doesn't exist in practice.
Get the Full Details
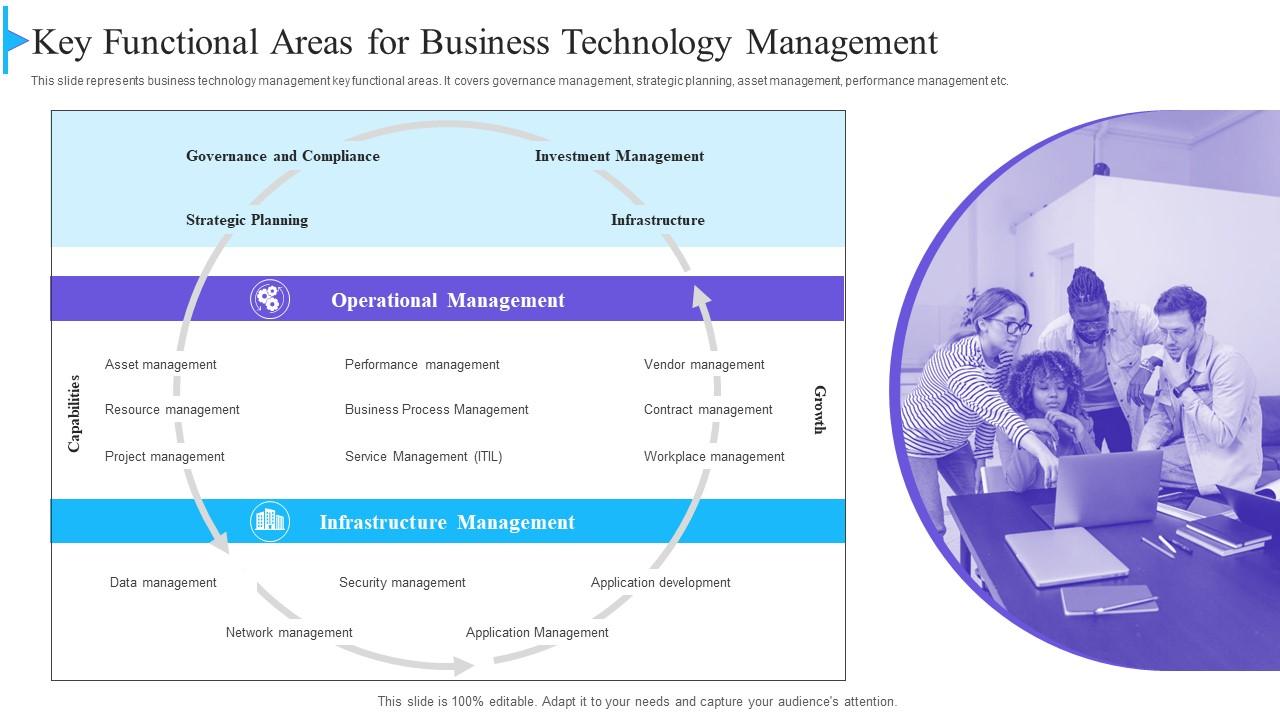
Counter-intuitive points most beginners miss
One thing people get wrong is assuming technology always expands functional regions. It often contracts them instead. Contactless payment and automated checkout shrink the functional region of a physical retail store because the friction that used to keep marginal customers coming decreases—once you remove the line, the nearby competitor's convenience advantage evaporates, and you realize you're competing with a farther location that now feels equally accessible. Delivery lockers and pickup points have a similar contraction effect on home-delivery footprints; they let carriers serve denser nodes without extending van routes, which tightens the practical radius. Another misconception is that digital technology makes geographic proximity irrelevant. It doesn't. It changes which proximity matters. Distributed teams still cluster around reliable power, legal frameworks, and time-zone overlap. Cloud services reduce the need for co-location, but they increase the need for low-latency interconnects, which means functional regions reorganize around fiber hubs and exchange points rather than away from them. The map didn't flatten; it just redrew itself around different anchors.
When the approach fails
Network isochrone analysis breaks down when the underlying OSM or proprietary road graph is stale. I've seen projects where a newly opened highway interchange or a closed pedestrian bridge wasn't in the dataset, producing a functional region that looked plausible until field validation revealed a 12-minute detour that disqualified half the supposed catchment. Always spot-check edge cases against recent mapping commits or, if the project is large, maintain your own supplemental graph layer for known infrastructure changes. Temporal variation is another failure mode. A single snapshot isochrone tells you nothing about whether the region holds during the hours that matter. Peak-hour congestion, school-zone closures, and seasonal road restrictions can halve the usable area compared to midday estimates. Run your analysis at multiple time windows and report the union or intersection depending on whether you're optimizing for worst case or average case. Most clients want the latter until they get burned by the former. Data availability limits the whole exercise too. Phone-ping data is rich but privacy-compliant versions are aggregated and noisy. Transit card data is cleaner but only covers users who tap, which biases toward urban cores and regular commuters. Delivery log data is precise but proprietary and rarely shared. If you're working with incomplete sources, triangulate across at least two to avoid building a functional region that reflects the gap in your data rather than the gap in human behavior.
A practical workflow
Start by defining the activity you're measuring—the region isn't meaningful without it. Commuting, shopping, healthcare access, and emergency response each produce different shapes even over the same territory. Then gather the origin-destination data that maps to that activity. Build a cost-surface or time-distance matrix using a realistic road network, not Euclidean distance. Generate isochrones at multiple thresholds. Validate against ground truth. Iterate. The tooling is straightforward now. GraphHopper, Valhalla, and OSRM handle the routing. PostGIS or similar spatial databases manage the isochrone polygons. Python or R scripts can automate the batch runs. The hard part isn't the code; it's knowing which assumptions are costing you accuracy and where to spend the effort. If you need a quick reference, the ORS API documentation covers isochrone generation well, and the OpenStreetMap community maintains several example datasets for testing routing graphs before you commit to production data.
What to watch next
Autonomous vehicle deployment will shift commute shed boundaries again, probably widening them for suburban origins where current transit gaps constrain today's functional regions. Real-time traffic integration into routing engines is already making dynamic isochrones feasible, which means static catchment maps may become archival rather than operational within a few years. The underlying principle hasn't changed—functional regions are defined by reach, and reach is defined by the technology you have available—but the resolution at which you can measure and update those regions keeps improving. The people who treat functional regions as fixed boundaries tend to make decisions that look reasonable on paper and fail in practice. The people who treat them as measurable, revisable outputs tend to build systems that adapt when the technology layer shifts beneath them. The difference is mostly habits around data hygiene and validation.