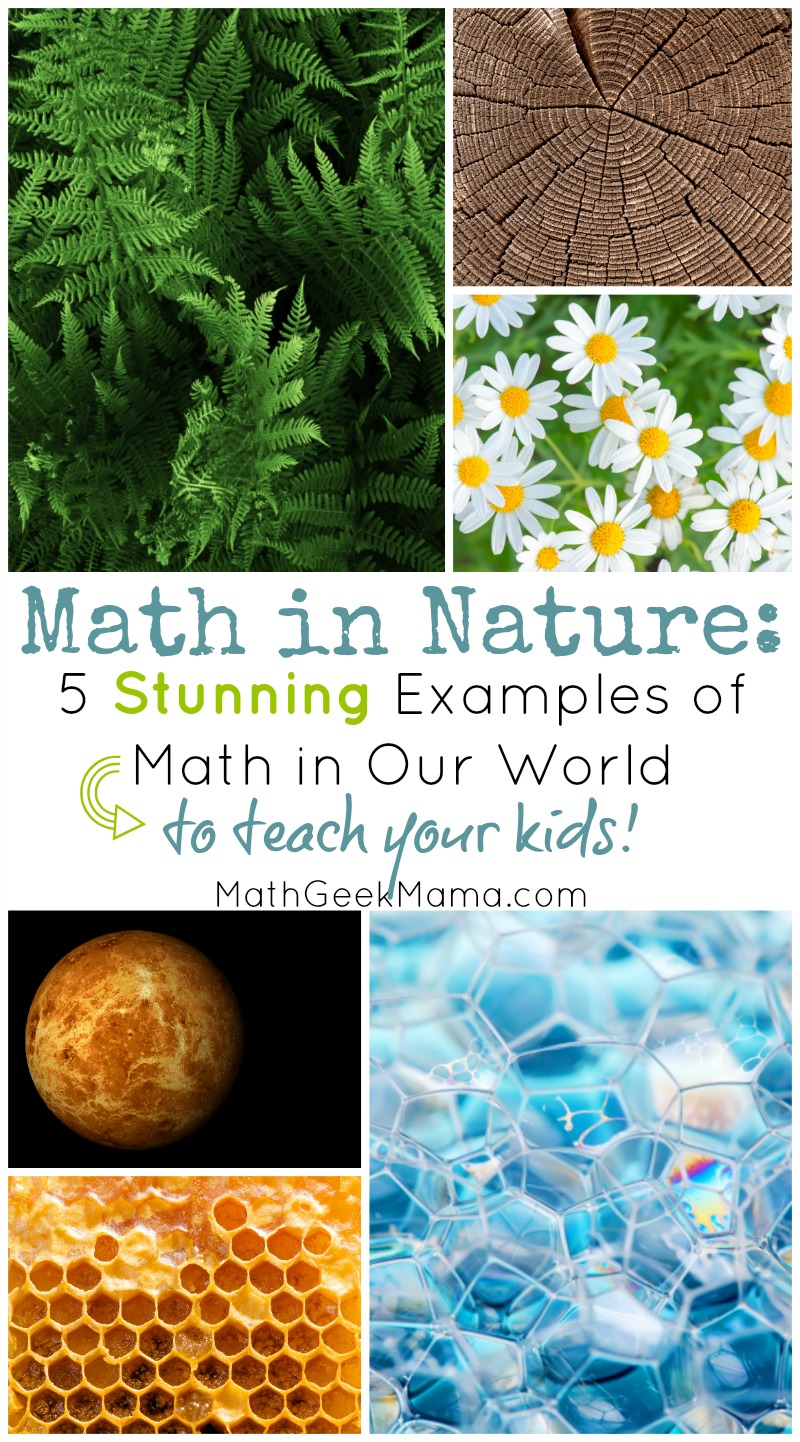
I've spent years building and breaking mathematical models of natural systems. The practical method is deceptively simple: you identify the dominant processes in a system, write them as equations, and solve for what the system does over time. That's it on paper. In practice, the gap between "write it down" and "it predicts anything useful" is where most people fail.
The core mechanism goes like this. You pick a system — say, a forest ecosystem — and list the conserved or flow-based quantities. Mass, energy, nutrients, population counts. Then you express the relationships between those quantities as rate equations. Most natural systems are governed by ordinary or partial differential equations. The simplest starting point is the logistic growth equation, dN/dt = rN(1 - N/K), which captures how a population grows when resources are unlimited and then slows as it hits carrying capacity. It's not glamorous. It's not going to make anyone cry. But it describes the majority of biological population curves you'll ever encounter.
The deeper the system, the more coupled equations you need. Predator-prey dynamics use the Lotka-Volterra equations. Heat diffusion through soil uses the heat equation. Chemical reactions in a stream use reaction-diffusion systems. Each equation is a statement about cause and effect. The variables are the things you can measure. The parameters are the things you have to estimate.
How Is Math Used To Explain Nature
The Actual Workflow
You start with observation. Not theory. You go out, measure something, and notice a pattern. Maybe water flow rates correlate with rainfall in a way that looks exponential. Maybe tree ring widths track temperature across decades. The math comes second. You don't derive equations from first principles and then check if they match reality. That rarely works. You observe reality and then find the equation that matches it.
Once you have a candidate equation, you parameterize it. This is where people get stuck. Parameters are constants like growth rates, diffusion coefficients, decay constants. You estimate them from your data. A least-squares fit will get you close. Maximum likelihood estimation is better if your data has known error distributions. Bayesian methods are worth learning if you have sparse data and want to quantify uncertainty in your parameters, though they add significant computation time.
Then you validate. Split your data into training and testing sets. Run the model on the test set. If the predictions fall within your error bounds, you have a working model. If they don't, you go back and either add terms or remove them.
I learned this the hard way. In an early project modeling phosphorus runoff from agricultural land, I built a model with seventeen parameters. It fit my calibration data with an R-squared of 0.94. I was proud. Then I ran it against independent data from a neighboring watershed and it completely diverged. The model was overfitted. It had memorized noise instead of learning the underlying process. I spent three months stripping parameters down to the five that actually had physical meaning, and the model went from beautifully wrong to acceptably right. The lesson: parsimony beats complexity every time in natural systems.
Common Pitfalls That Beginners Miss
The biggest mistake is assuming that a good fit means a good model. It doesn't. You can fit a sixth-degree polynomial to any dataset and get a near-perfect curve. That doesn't mean the underlying process is polynomial. The residual structure matters more than the fit quality. If your residuals show autocorrelation, your model is missing a dynamic component. If they're heteroscedastic, your error structure is wrong.
A second mistake is ignoring dimensionality. Many natural equations become numerically unstable when parameters span several orders of magnitude. I once tried to model groundwater flow with a diffusion coefficient of 10^-5 and a reaction rate of 10^3 in the same equation. The solver blew up immediately. Rescaling the variables fixed it in ten minutes. Always non-dimensionalize before you solve.
The third mistake is treating parameters as constants. In nature, they're almost never constant. A growth rate changes with temperature. A diffusion coefficient changes with soil moisture. If you're doing steady-state analysis, this doesn't matter much. If you're doing dynamic simulation, you need to parameterize those dependencies. The workaround is to embed them as functions of state variables or external drivers.
Counter-Intuitive Reality About Natural Modeling
Most natural systems are better described by stochastic equations than deterministic ones. The reason is simple: natural systems are noisy. Measurement error, environmental variability, demographic stochasticity — all of it adds up. A deterministic model will give you a single trajectory. A stochastic model will give you a distribution of possible trajectories. For decision-making, the distribution is infinitely more useful.
The Lorenz equations are the famous example of chaos in nature. Three variables, six terms, no randomness built in, and the output is unpredictable beyond a short horizon. What's interesting is that the chaos emerges from the nonlinearity, not from external noise. This means that even simple equations can produce behavior that looks complex without any hidden variables. Don't assume that complexity in output requires complexity in the model.
Another thing people don't expect: sometimes the best model is a negative one. A model that predicts nothing new is still valuable because it tells you what processes are irrelevant. I spent weeks trying to build a model of algae bloom timing that included light intensity, temperature, and nutrient concentration. The final model showed that only nutrient concentration mattered. The other two were decoys — correlated with nutrients but causally inert. That result saved us from expensive monitoring programs that would have measured irrelevant variables.
Practical Tools and Setup
Python is the standard tool. Scipy provides odeint and solve_ivp for integration. NumPy handles the linear algebra. Matplotlib or Seaborn for visualization. If you're working with spatial systems, consider FiPy for finite-volume methods on grids. For agent-based models, Mesa is straightforward. R is still relevant for statistical fitting and time series analysis.
The learning path is: differential equations first, numerical methods second, statistics third. Most people try to jump to the software without understanding the math underneath, and the software becomes a black box that produces confident-looking garbage. I'd suggest starting with a textbook like Strogatz's Nonlinear Dynamics and Chaos, then moving to numerical work with simple equations before tackling real data.
For someone wanting to try this immediately, install Python with Anaconda, open a Jupyter notebook, and run this minimal example:
import numpy as np
from scipy.integrate import odeint
import matplotlib.pyplot as plt
def logistic(y, t, r, K):
return r * y * (1 - y / K)
y0 = [1, 5, 10]
t = np.linspace(0, 20, 200)
solutions = [odeint(logistic, yi, t, args=(0.5, 100)) for yi in y0]
for sol in solutions:
plt.plot(t, sol)
plt.show()
This runs a logistic growth model with three different starting populations. You'll see convergence to the carrying capacity regardless of starting point. It's the simplest possible demonstration of how a differential equation describes a natural process.
Where This Approach Breaks Down
Mathematical modeling fails when the system has too many interacting components with poorly understood mechanisms. Ecosystems are the classic example. You can model a single species population well. Try modeling an entire forest ecosystem and you'll hit a wall within months. The number of variables explodes. The interactions are nonlinear and poorly quantified. The parameters are unknown. The model becomes an exercise in confident guessing.
Another failure mode is when the timescale of interest doesn't match the timescale of the dominant processes. If you're studying geological formation but modeling with hourly data, you'll miss the relevant dynamics. If you're studying viral spread but modeling with yearly data, same problem. Always check your timescales before you build.
Deterministic chaos is a third limitation. The Lorenz system showed us that even simple deterministic equations can produce effectively unpredictable behavior. This isn't a modeling flaw. It's a property of the system. No amount of better data or more computing power will let you predict the exact state of a chaotic system beyond its Lyapunov time. You can predict the attractor structure. You can predict statistical properties. You cannot predict individual trajectories past the horizon.
Finally, there's the issue of scale emergence. Equations that work at one scale often fail at another. Fluid dynamics equations break down at the molecular scale. Population equations break down at the individual level. This is called the upscaling problem and it's unsolved for most systems. If your model works at the scale you care about, use it. If you need to bridge scales, expect to introduce new parameters and new equations at each level.
The honest conclusion is that math explains nature the way a map explains a territory — usefully but incompletely. The maps that matter most are the ones where you know exactly where the edges are.
Gallery How Is Math Used To Explain Nature
Why Is Math Important In Nature at Gemma Mate blog
What Is Nature In Mathematics
Nature - asrferttryh - Mathematics in Nature Mathematics in Nature is a science and mathematics ...
Why Is Mathematics Important In Nature at Joseph Cornwall blog
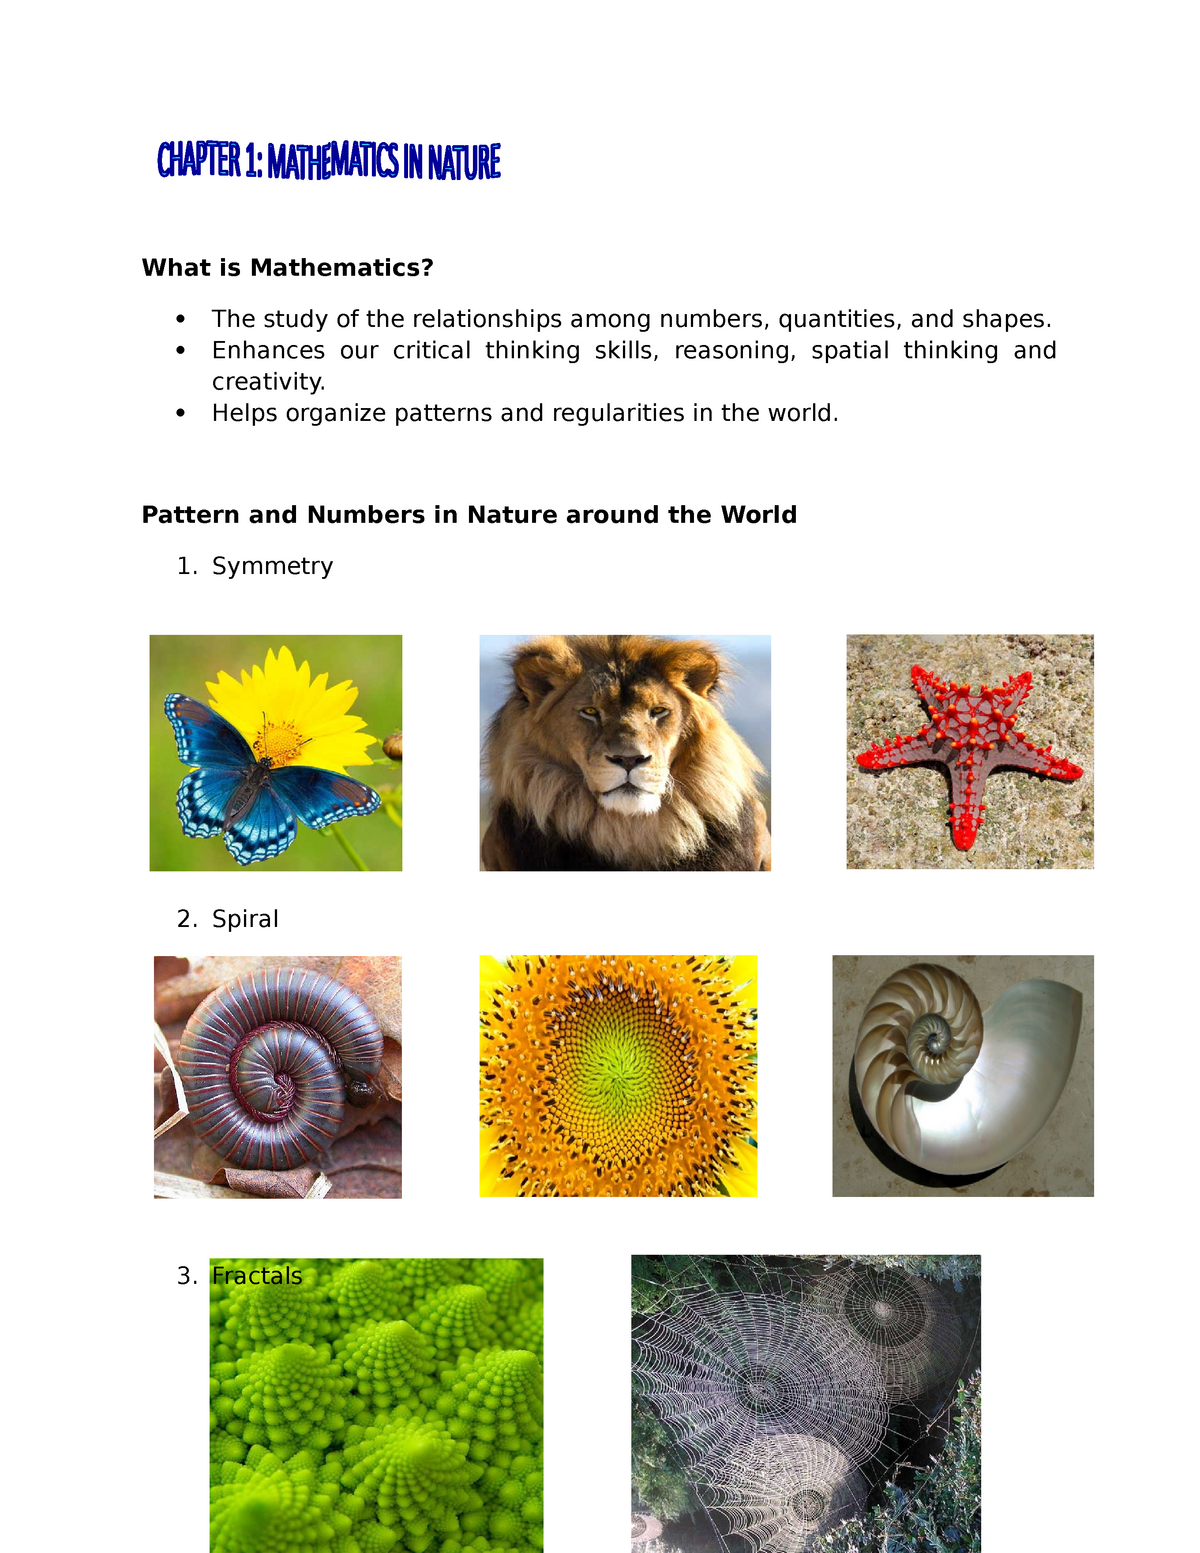
Activity 1 Nature of Mathematics - What is Mathematics? The study of the relationships among ...