Getting the data out of the database before you can actually think about it
Most people treat SQL as a filtering tool, which it is, but that is only the surface level. The real work happens in how you shape the query to match what the business is actually asking. I have spent years watching analysts write six-hour Python scripts when a single well-written CTE could have done the same job in eight minutes. It comes down to one thing: SQL runs inside the database engine where the data already lives, so you avoid moving gigabytes across the network just to do basic aggregations. When I started working with large datasets back in 2018, my first project was analyzing e-commerce purchase behavior across three regional warehouses. The raw data sat in a PostgreSQL instance at about 14 million rows. Every attempt to pull it into R or pandas required a full table export, which took forty-two minutes and frequently timed out during peak hours. The workaround was simple enough once I figured it out: write the entire aggregation pipeline in SQL and only extract the summarized result set. Instead of exporting fourteen million rows, I exported roughly 3,000 aggregated records. What used to take an afternoon with manual processing dropped to about eleven minutes from start to finish.
How Is Sql Used In Data Analysis
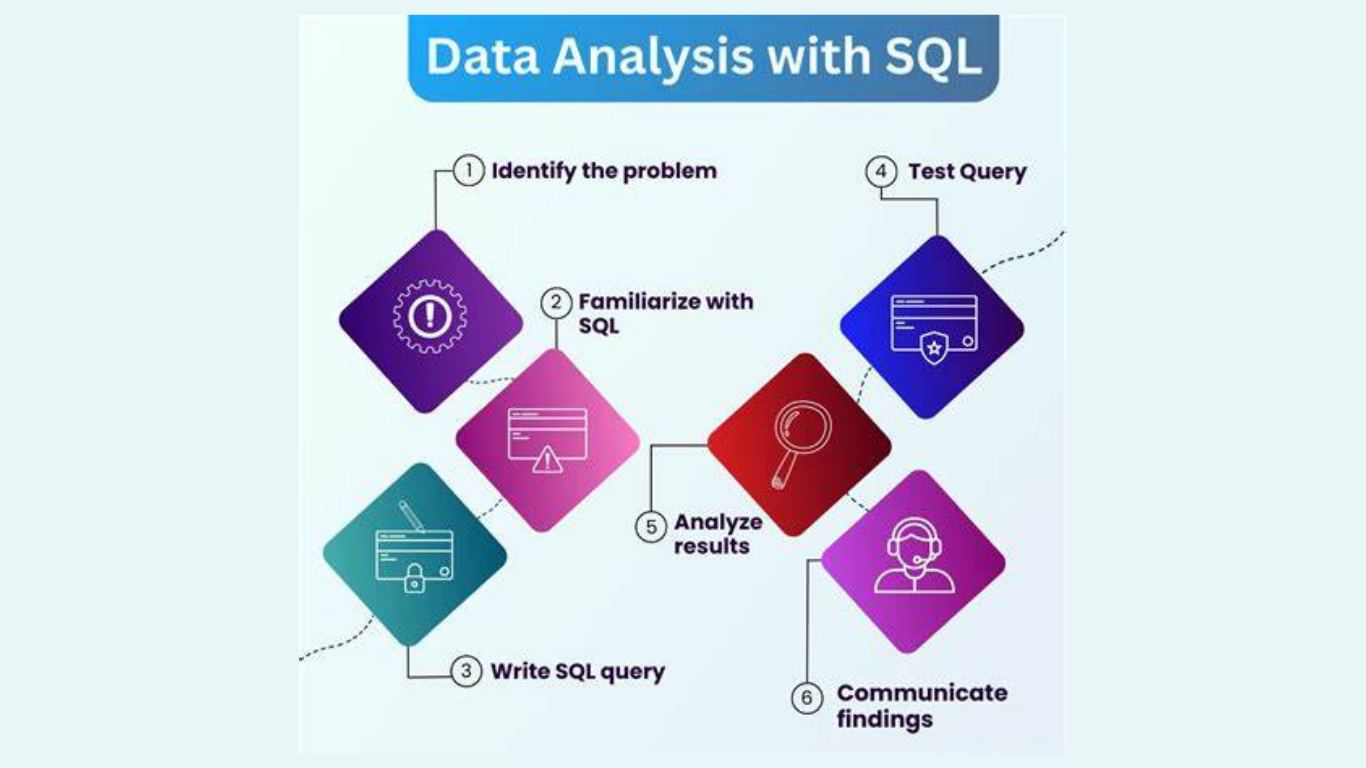
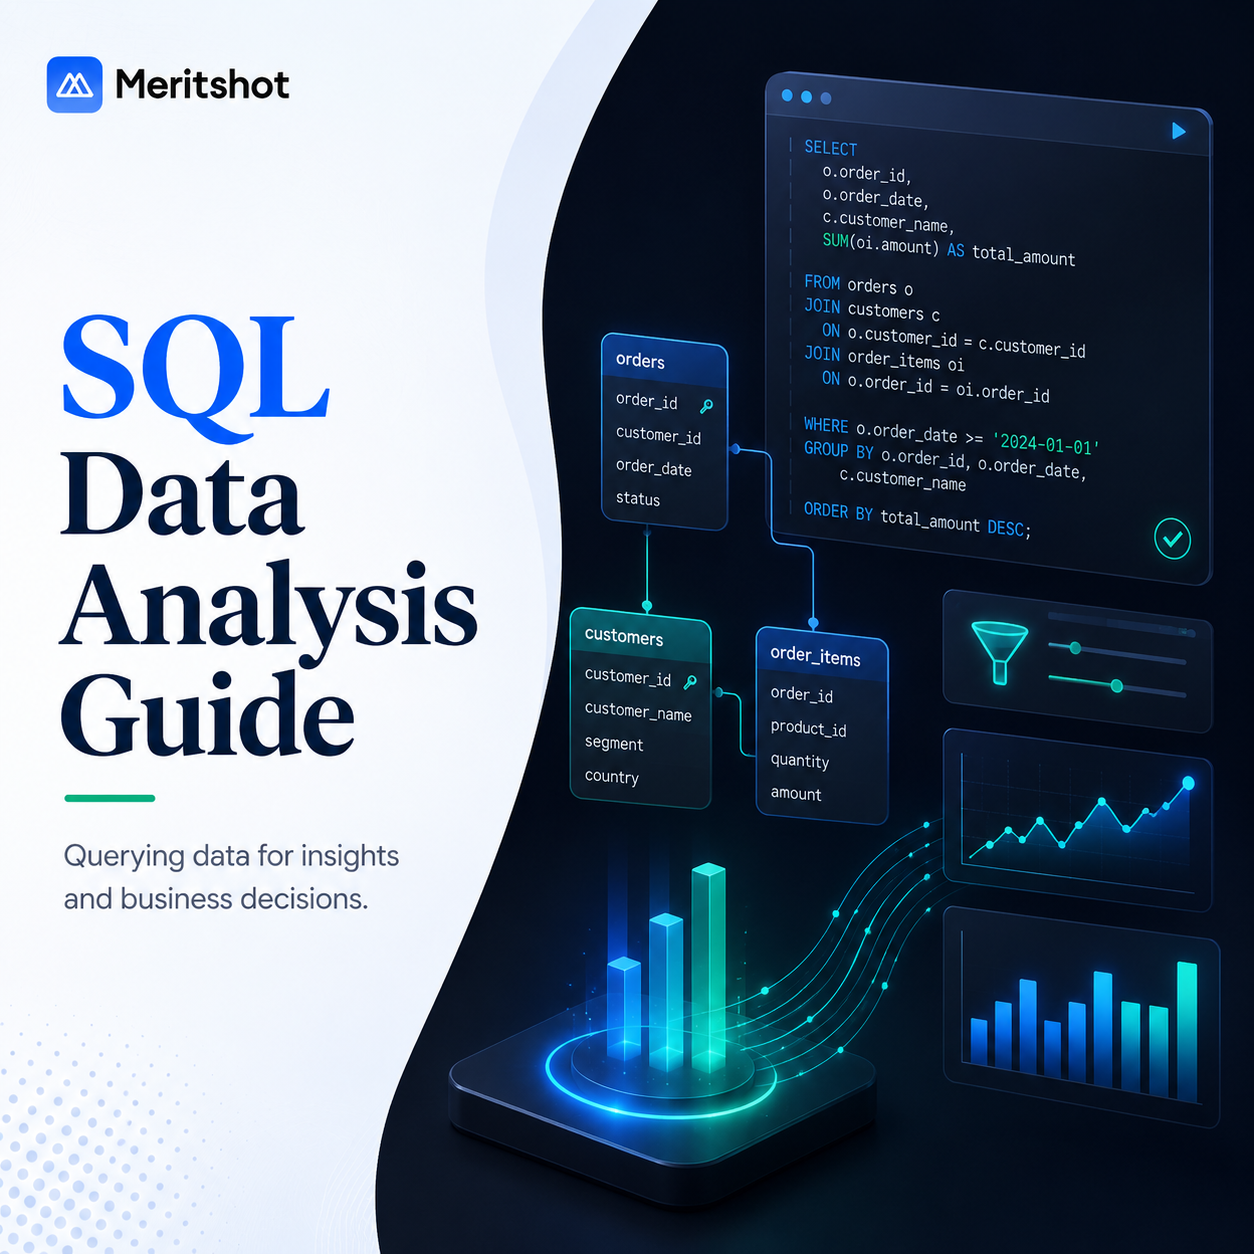
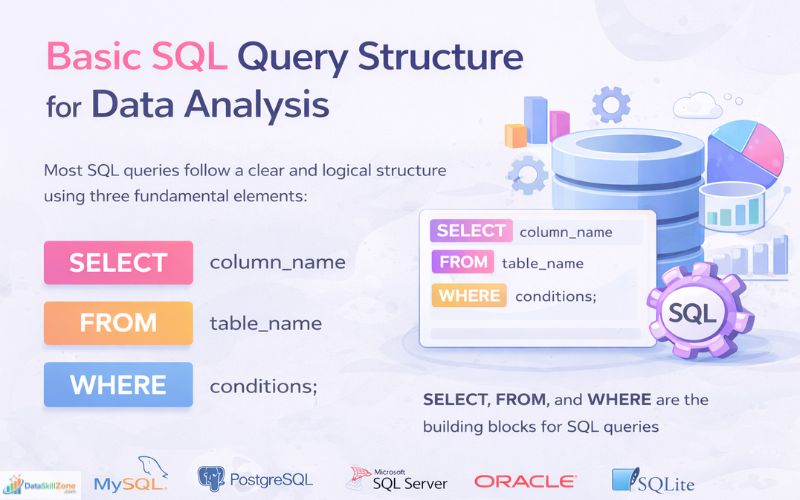
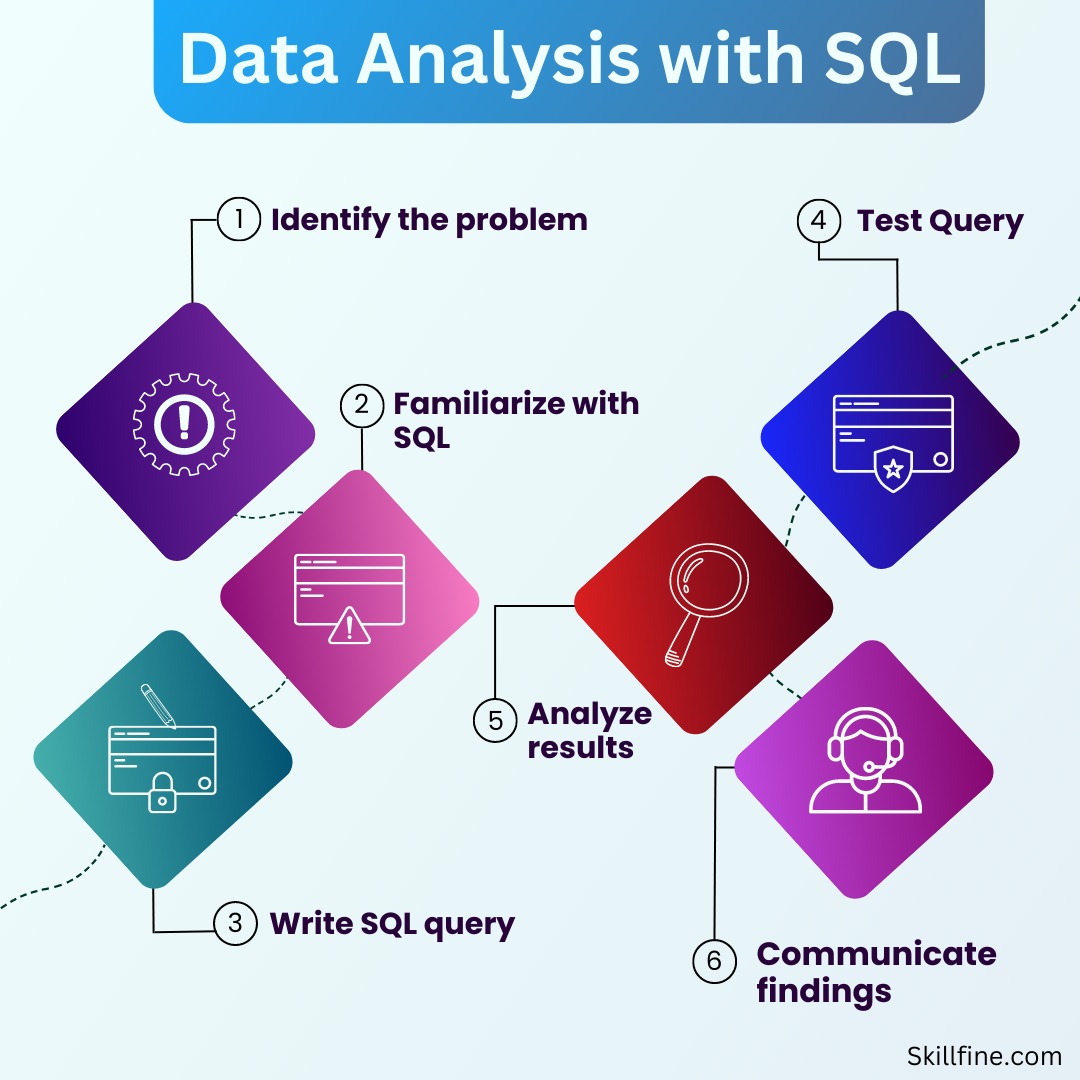
The core workflow looks like this. You connect to the source database, usually through a tool like DBeaver, pgAdmin, or an IDE like DataGrip, and then you run queries against the tables that hold your data. A typical analysis path starts with SELECT statements to inspect the data, moves into WHERE clauses for filtering, then GROUP BY for summarization, and eventually joins if you need to combine multiple tables. That is the skeleton. The muscle is in window functions, CTEs, and subqueries that let you compute running totals, rank values within segments, or calculate month-over-month changes without touching any external tool. One thing beginners almost never grasp is that the order of operations inside a SQL query is not the same as the order you write them. The database engine processes FROM and JOIN first, then WHERE, then GROUP BY, then HAVING, then SELECT, and finally ORDER BY and LIMIT. This matters because you cannot reference a column alias defined in your SELECT clause inside a WHERE clause. I have seen the same mistake repeated in production environments countless times. The fix is to wrap the problematic query in a CTE or subquery and apply the WHERE filter after the alias is materialized. Window functions are where SQL really separates itself from basic spreadsheet-style analysis. Functions like ROW_NUMBER, RANK, DENSE_RANK, LAG, LEAD, and cumulative aggregates like SUM() OVER() let you compute things that would otherwise require self-joins or iterative loops. For example, if you need to calculate the trailing twelve-month revenue per customer, a standard GROUP BY will not get you there alone. You use a window frame specification with ORDER BY and a row range clause, and the database engine computes it in a single pass. On a dataset of roughly five million transactions, this kind of query typically runs in under thirty seconds on a properly indexed column store.
Joins are another area where people make avoidable mistakes. An inner join only returns matching rows from both tables, which sounds obvious until you need to preserve all records from the left table and include matches where they exist. That is a LEFT JOIN. I once worked on a campaign attribution project where the wrong join type silently dropped about eighteen percent of the records because certain user segments had no matching transaction history. The result set looked clean, which is the whole problem. The numbers were internally consistent but completely incomplete. Adding a COUNT(*) grouped by join match type helped identify the gap quickly. Indexing is the factor most analysts ignore and then complain about performance. If you are filtering or joining on unindexed columns in a large table, your query will scan the entire table every time. A covering index on the join key and the filter columns can reduce read time from something like forty-five seconds down to roughly 200 milliseconds on the same data. The tradeoff is write performance, since every INSERT and UPDATE has to maintain the index structure as well. For read-heavy analytics workloads, this is almost always worth it. There are scenarios where SQL is simply the wrong tool. When you need machine learning model training, unstructured text processing, or complex graph traversal, a database engine is not built for that. I recently encountered a project that required sentiment classification on customer support transcripts stored in a relational database. The natural approach would have been to run the inference inside the database, but Postgres has no native ML inference layer. I ended up extracting the relevant text chunks into a Parquet file, running the model in Python with a GPU instance, and then reinserting the results. It was slower than I wanted, but trying to force SQL to do something it was not designed for would have been worse.
Get the Full Details
Another limitation I run into regularly is memory pressure on window functions with large partitions. If you apply a RANK() OVER(PARTITION BY customer_id) on a table where one customer has two million rows, the database engine may spill to disk or run out of temporary tablespace depending on your configuration. The workaround is usually to pre-filter the partition before applying the window function, or to use approximate ranking functions if exact precision is not required. In one case, switching from RANK to DENSE_RANK on a partitioned set reduced memory usage by about thirty percent because the internal sort structure was simpler. Data quality is another area where SQL helps more than most people realize. Running COUNT(DISTINCT column_name) against critical keys, checking for NULL distributions, and comparing row counts between source and target tables after an ETL run are all things you can do with straightforward SQL. I maintain a routine query suite that runs before any major analysis begins, checking for duplicate primary keys, out-of-range timestamps, and unexpected NULL spikes in columns that should be mandatory. These checks usually catch problems that would otherwise surface hours later as incorrect business metrics.
A practical example from a real project
Last year I was working on a churn prediction dataset for a SaaS product. The data lived across three tables: user subscriptions, feature usage logs, and billing events. The goal was to build a feature set that captured each user's activity pattern over their last ninety days. A naive approach would pull all the raw logs into Python and compute the features there. That approach required about 6.2 GB of memory and took roughly twenty-two minutes to complete on a decent workstation. Instead, I wrote a SQL query using multiple CTEs. The first CTE joined subscription data with billing events to establish the active period for each user. The second CTE aggregated the usage logs by user and by fifteen-day windows. The third CTE applied window functions to compute rolling averages and trend slopes. The final SELECT pulled everything together into a flat feature table. The total query runtime on the production database was about 4.7 minutes, and the result set was roughly 340 MB. Moving that into the analysis pipeline was significantly faster than waiting for the in-memory computation. The query itself was not elegant. It had some redundancy in the date calculations and the window frames overlapped slightly more than necessary. But it worked, and it was maintainable. Another analyst could pick it up and modify the date ranges without needing to understand the Python ecosystem dependencies that would have been required otherwise.
One subtle issue came up during validation. The usage logs table had a partial index on the event_timestamp column but not on the user_id column, which was the join key. The initial query plan showed a sequential scan on the usage logs for every user in the outer query, which is a classic nested loop problem. Adding a composite index on (user_id, event_timestamp) changed the execution plan entirely. The query time dropped from 4.7 minutes to 52 seconds. This is the kind of thing that does not show up in any tutorial and only becomes obvious when you are waiting around for a query to finish. For people starting out with SQL for data analysis, the most useful progression is to master CTEs and window functions before worrying about stored procedures or query optimization. Once you can express your analysis logic clearly in a single readable query, performance tuning becomes a secondary concern rather than a source of confusion. I also recommend getting comfortable with EXPLAIN ANALYZE output. Reading the actual query plan tells you more about what the database is doing than any documentation can. It will show you where sequential scans are happening, where index usage is suboptimal, and where the join order is forcing unnecessary work. The bottom line is that SQL is not the most flexible tool available, but it is the most efficient one for structured data that already lives in a database. If your data is already in a relational system and your analysis involves aggregation, filtering, and joining, writing the logic in SQL will almost always be faster and more resource-efficient than pulling everything out and processing it elsewhere. The exceptions are real, but they are the exceptions, not the rule.