The Number Itself Isn't As Simple As You Think
The standard answer is 28 letters in the Arabic alphabet. That's what you'll find in any basic textbook. But the reality is messier than that number suggests, and anyone who's actually worked with Arabic long enough knows the 28-letter count hides some uncomfortable details. I ran into this issue head-on when I was localizing a legal document system for a client in the UAE. We were building an automated sorting feature that needed to handle names. The algorithm treated ta marbuta () as just another letter, but in practice, names spelled with and can be the same person depending on regional dialect. One candidate's application kept getting rejected because the sorting algorithm placed her name in a completely different section from her brother's. We ended up writing a normalization layer that stripped diacritics and treated and as equivalent for sorting purposes, then fell back to a secondary comparison on the rest of the name. Took about two days to debug.
How Many Letters In Arabic Alphabet Actually Count As Real Letters?
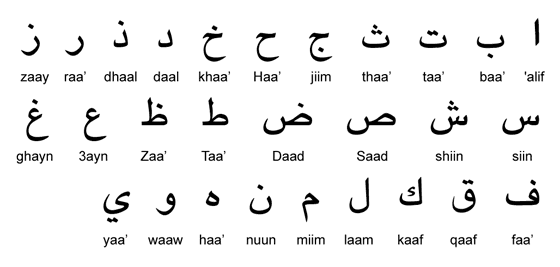
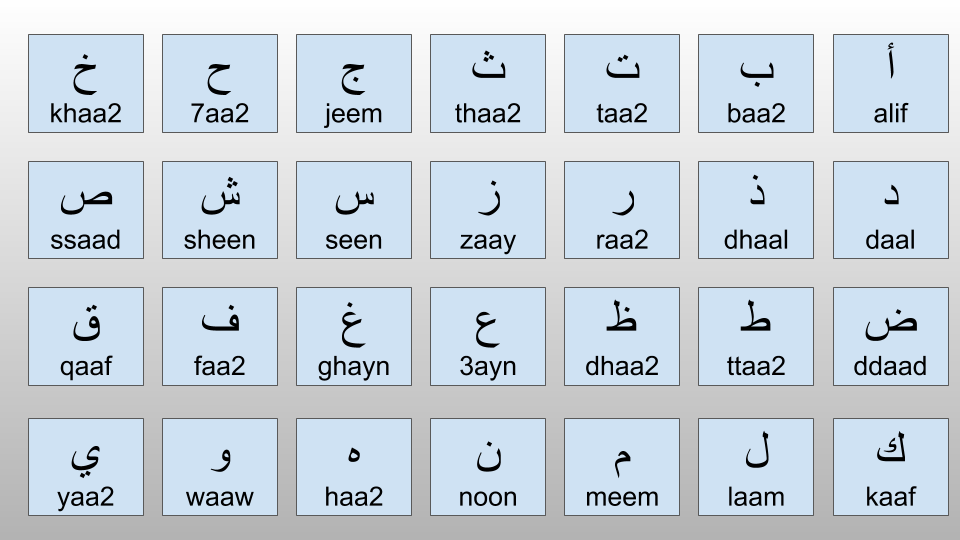
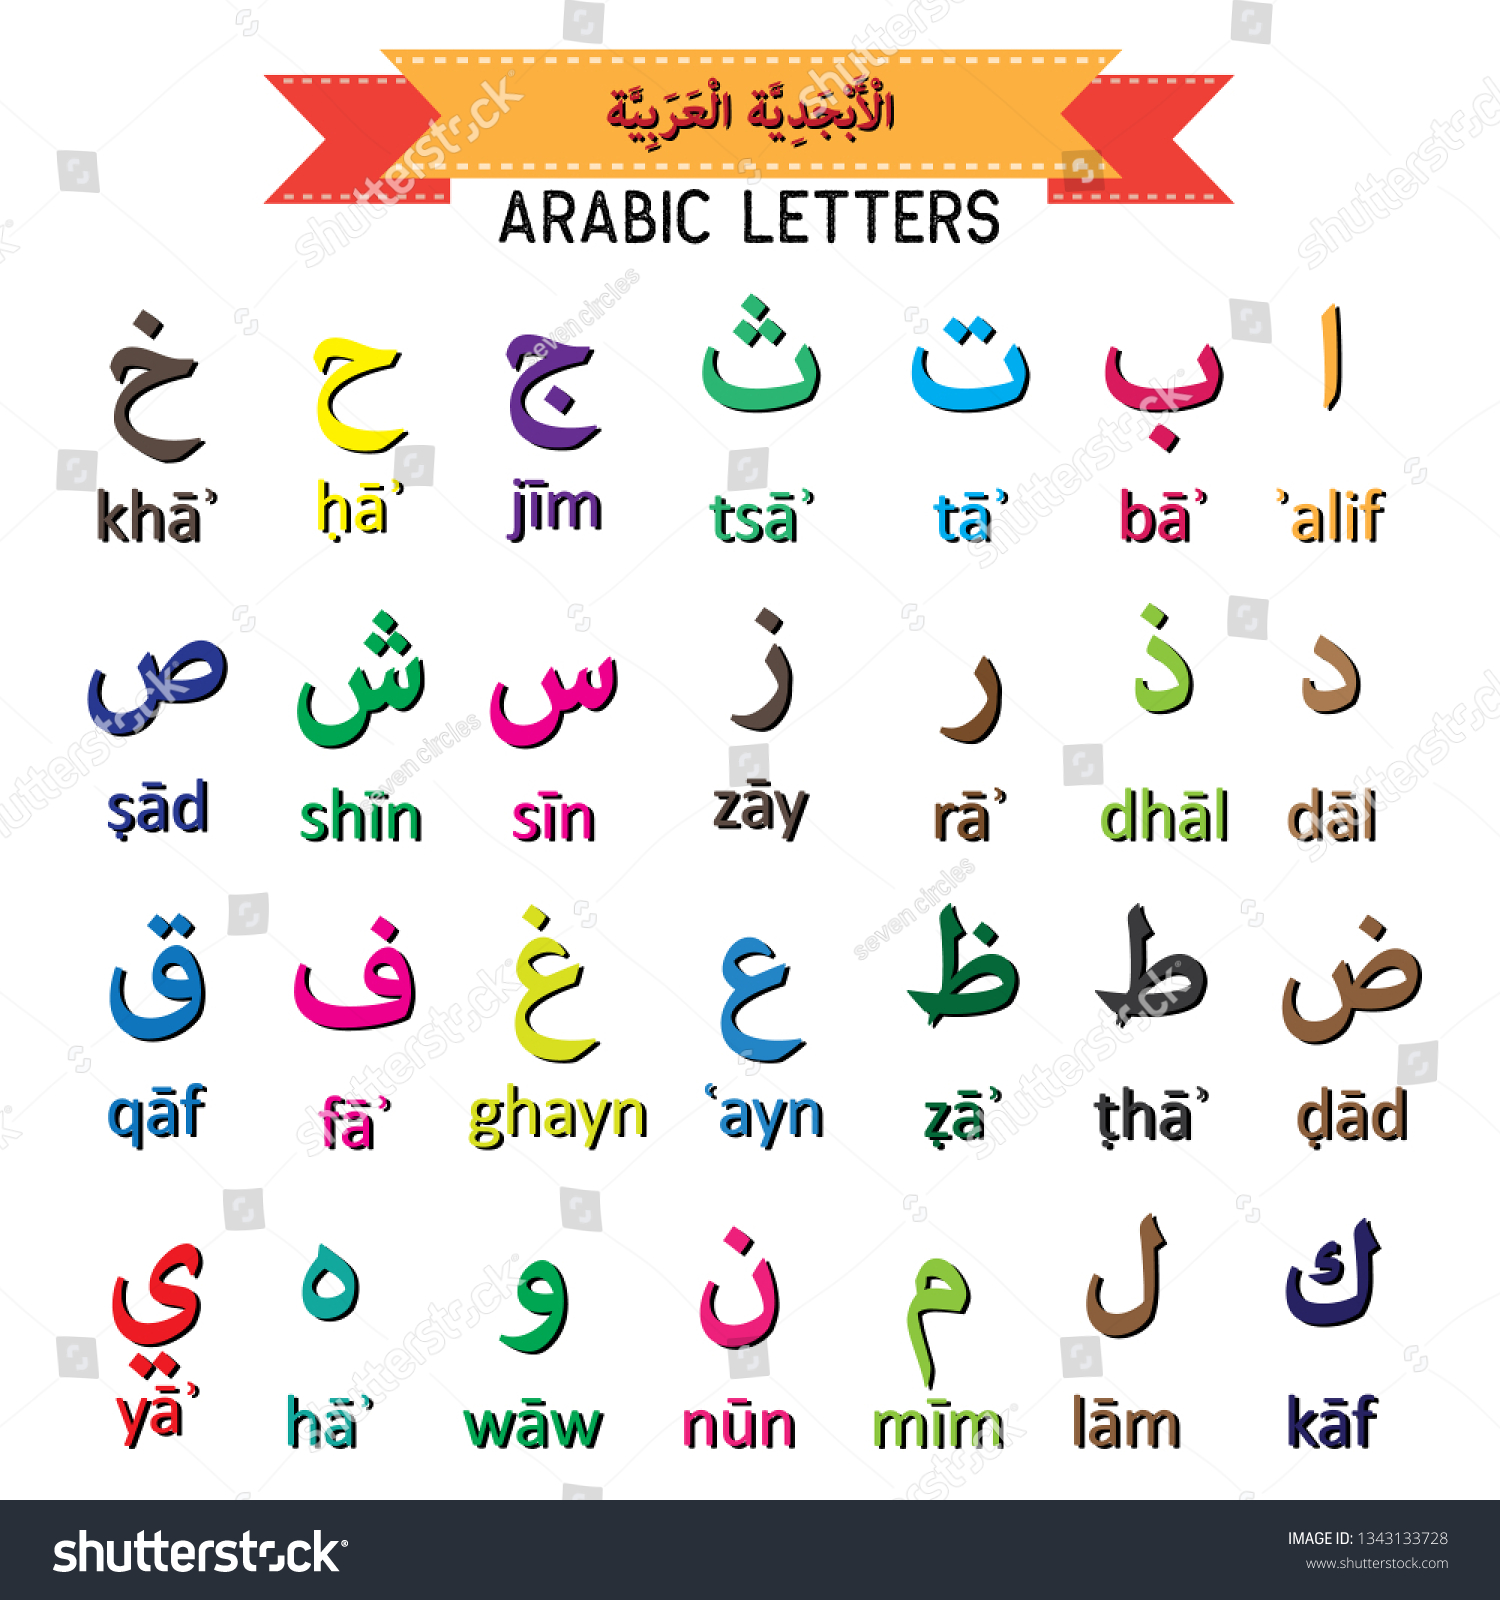
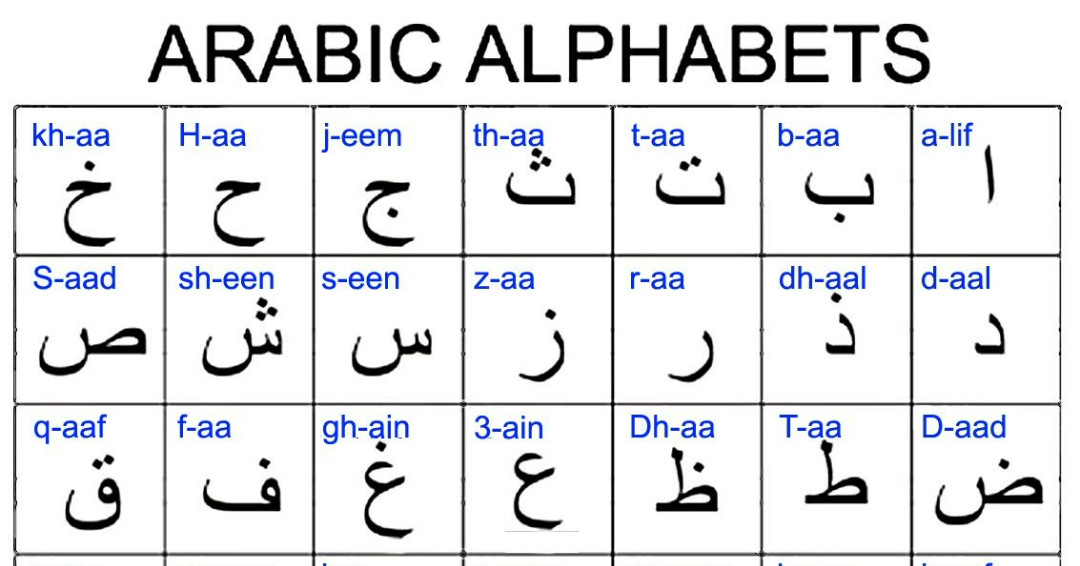
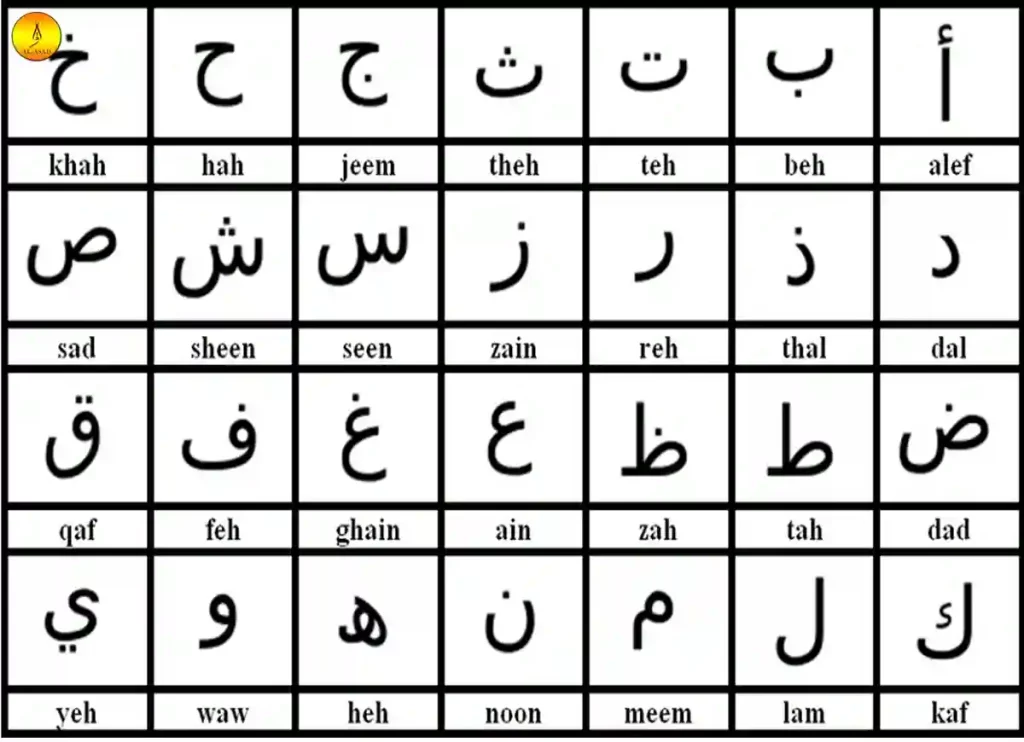
Twenty-eight is the baseline. Each one has a distinct name, a consistent sound value, and a role in the traditional order. The letters are: (alif), (ba), (ta), (tha), (jim), (ha), (kha), (dal), (thal), (ra), (zay), (sin), (shin), (sad), (dad), (ta), (tha), (ain), (ghain), (fa), (qaf), (kaf), (lam), (mim), (nun), (ha), (waw), (ya). That's straightforward enough. The complications come from how these letters behave in actual usage.
Letters That Don't Stay Still
The Arabic script is cursive by design. Almost every letter changes shape depending on its position in a word. Alif never changes because it doesn't connect to the right. Ba, ta, and tha each have four forms: isolated, initial, medial, and final. Some letters like waw and ya behave similarly but have additional quirks. Here's something most beginners miss: the letters and can function as both consonants and vowel carriers depending on context. When they appear as long vowels in written Arabic without diacritical marks, they're technically still counted as the same letters in the 28. A text without any tashkeel (vowel marks) relies entirely on your ability to recognize whether a waw is acting as a /w/ consonant or a /u/ long vowel. That ambiguity causes real problems in NLP applications and even in basic name matching. I spent three weeks troubleshooting a search engine that kept returning zero results for common phrases. The issue wasn't the database. The issue was that users were typing words with hamza variations that didn't match the stored forms. There are roughly a dozen common hamza positions in Arabic, and none of them change the 28-letter count, but they absolutely break naive string matching. We ended up implementing a Unicode normalization form that mapped all common hamza variants to a canonical representation before running comparisons. The fix reduced false negatives from about 40 percent down to under 3 percent.
Get the Full Details
Alif Maqsura and the Edge Cases
Alif maqsura () looks identical to ya without dots in most fonts. In modern printed Arabic it's often indistinguishable without examining the Unicode code point. The letter appears primarily in poetry and at the end of certain verb forms and nouns. It's not counted as a separate letter from ya in the 28, but functionally it behaves differently enough that you'll occasionally see it listed separately in older orthographic references. There's also the question of digraphs. The combination of shin with three dots () and teh with three dots () are single letters with diacritics, not letter pairs. Some people mistakenly count the dot patterns as separate letters. They're not. The same goes for the dots on nun, jeem, khah, dah, and zad. Those dots are diacritic markers that distinguish one consonant from another within the same letter family.
Practical Implications for Sorting and Encoding
When you're working with Arabic text in any kind of software system, the 28-letter model breaks down immediately. Unicode has over 300 code points just for Arabic characters when you include diacritics, vowel marks, and presentation forms. The Presentation Forms area alone contains separate encoded shapes for nearly every letter in isolated, initial, medial, and final contexts. That means the same conceptual letter can appear as completely different Unicode values depending on where it sits in a word. If you're doing anything that requires collation or sorting, don't assume a simple alphabetical comparison will work. The Arabic collation order isn't identical to the alphabetical order I listed earlier. Traditional Arabic sorting follows a slightly different sequence, and different regions use different standards. The UAE generally follows one variant, while Gulf countries may use another. We learned this the hard way when a client complained that our sorting output didn't match their internal reference lists. Their reference lists were using a regional collation rule that our library didn't support out of the box. We switched to ICU collation with the ar_AE locale and the problem went away.
What You Should Actually Remember
The Arabic alphabet has 28 core letters. Beyond that, you're dealing with positional variants, hamza diversity, diacritic systems, and encoding complexity that no casual explanation covers. If you're building anything that processes Arabic text, budget time for normalization, collation, and character mapping before you write a single line of logic. The theory is clean. The practice is not. Most resources online stop at the 28-letter number because that's what fits in a quick FAQ. If you need a deeper reference on Arabic character encoding or collation rules for a specific project, the Unicode Standard Annex #9 and the ICU documentation cover it in detail. The basic count is easy. Working with the script in any real system is where things get complicated.