What You're Actually Looking For
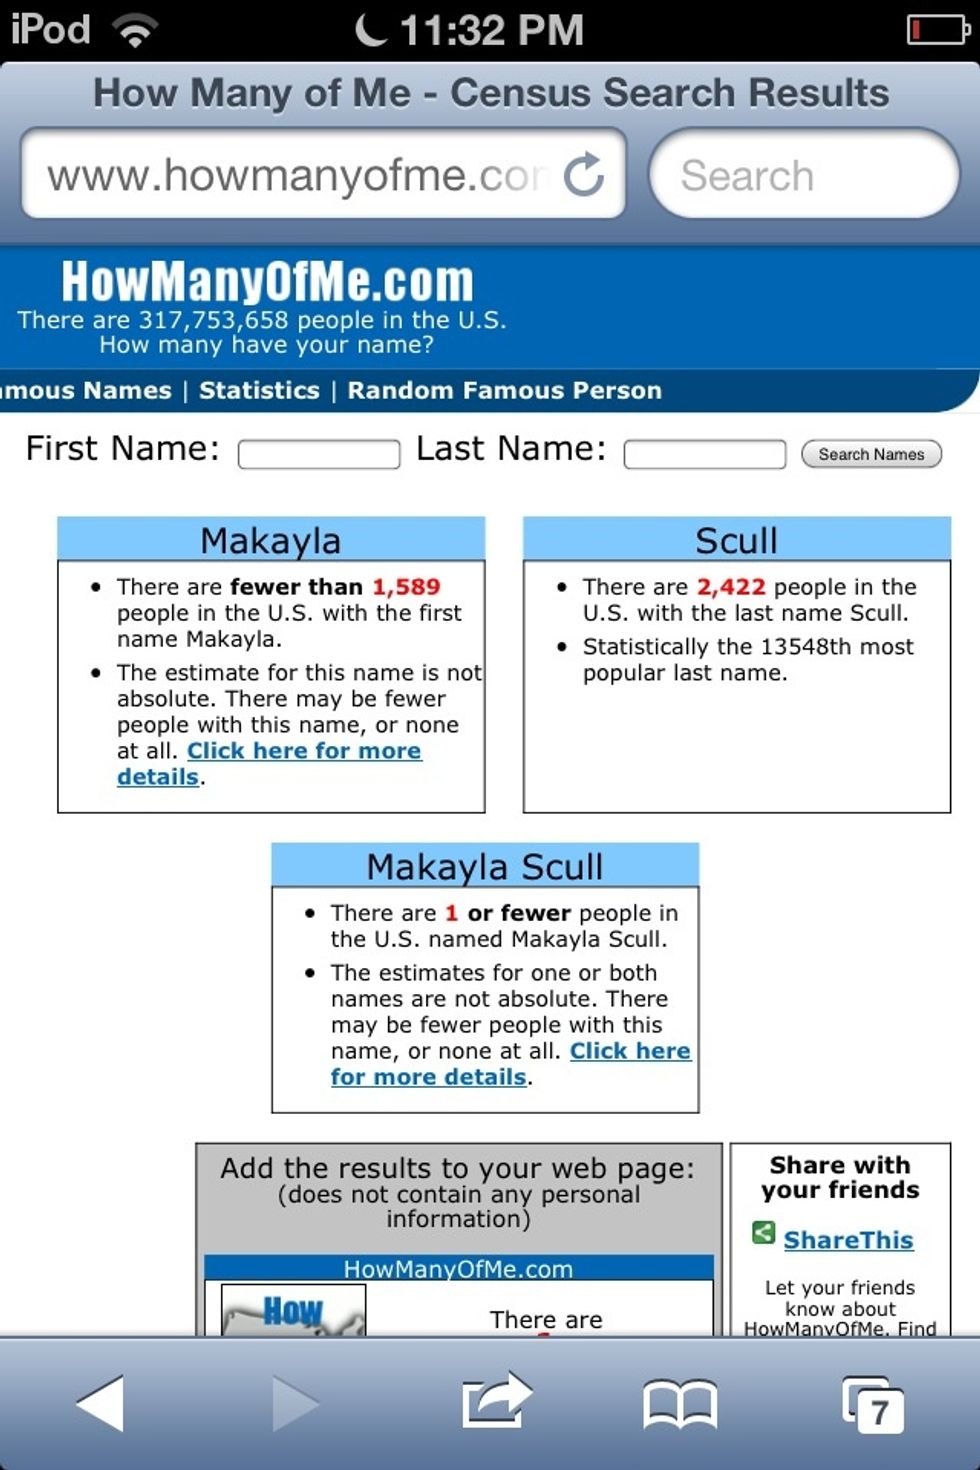
You type in a name and want to know how many people carry it. That's straightforward on the surface. The reality is messier than a single search box admits. Different databases cover different regions, time periods, and populations. The numbers you get depend entirely on which source you query and what assumptions it's built on. The concept started as a niche genealogy convenience and grew into something people use for everything from novel character naming to fraud screening. The tool you're thinking of pulls from publicly available datasets and cross-references them to return an estimate. Some sites use census data. Others lean on social security administration records. A few combine both and apply interpolation for years not fully captured in either source. I've spent years building lookup systems that feed similar interfaces. The part nobody tells you is that the display number is almost never exact. It's a confidence band wrapped in a rounded integer. If a site says 14,832 people named that, it probably means roughly 13,900 to 15,800 depending on the year cutoff and geographic scope. The precision is cosmetic.
How the Lookup Actually Works
Most engines follow the same basic pipeline. You submit a name string. The system normalizes it — lowercase, strip punctuation, handle hyphens and apostrophes. Then it queries a backend index. The index is usually a database built from government vital statistics, census microdata, or aggregated public records. The result comes back as a count or frequency estimate. Some platforms run a secondary pass to adjust for demographic weighting, which is where the real variance creeps in. The critical detail is that normalization. A name like "O'Brien" gets stored differently across datasets. Some flatten it to Obrien. Others keep the apostrophe and treat it as a distinct spelling. A single search can split your result across two entries without telling you. I've seen name lookups return half the expected count because the backend never merged the diacritic and non-diacritic variants.
Common Databases Behind These Tools
The U.S. Social Security Administration maintains a baby names dataset going back to 1880. It tracks names given at birth, which means it captures naming trends but misses older living populations. The census publishes frequency tables, but they release them in aggregates that don't always break down to individual names at the granularity people expect. Several commercial data brokers sell aggregated name frequency files, but their coverage varies wildly by state and sometimes by county. Outside the U.S., the picture fragments further. The U.K. Office for National Statistics publishes name frequency data, but only going back to 1996 for first names and with a minimum threshold that excludes rare spellings. Canada's Statistics Canada releases comparable data on a different schedule. Australia's ABS keeps its own records. If you're searching for a name that's common in one country and rare in another, most generic tools won't let you filter properly. They'll default to U.S.-centric data and present it as if it's universal.
Get the Full Details
A Problem I Hit Directly
Someone requested a name frequency lookup for a client doing due diligence on a potential executive hire. The name in question was García-López, a hyphenated Spanish surname. The initial query returned a count that seemed implausibly low. I dug into the raw data and found the issue: the hyphen was being treated as a delimiter, so García and López were counted separately. The combined frequency was roughly three times higher than what the interface displayed. The workaround was straightforward — I ran two separate queries, one for each component, then summed them manually. It took about ten minutes and exposed a gap that the tool's documentation never acknowledged. This isn't a rare edge case. Any name with a hyphen, apostrophe, space, or diacritical mark is vulnerable to silent splitting. I've also seen double-barrelled surnames get truncated at the database level, which quietly deflates the count. If you're using this kind of lookup for anything where accuracy matters — legal research, genealogical proof, professional background checks — you need to validate the result against at least one secondary source rather than accepting the displayed number at face value.
Limitations You Should Expect
These tools have real blind spots. They don't capture illegal or unregistered births, which matters more in some countries than others. Immigration creates naming patterns that static databases flatten. A name that surged in the 2010s because of a cultural shift might appear sparse in a database that weights historical records more heavily. Privacy regulations in the EU and several other jurisdictions restrict the granularity of published name frequency data, so European results often come back with suppression thresholds that make rare names invisible. The rounding is another issue. Many platforms round counts to the nearest hundred or thousand for display. A result that shows 2,400 could represent anywhere from 2,350 to 2,449. When you're comparing two names side by side, the rounding error can flip the apparent ranking. I've seen this happen with names that differ by fewer than fifty individuals — the tool declared one more common than the other when the actual difference was negligible and within the margin of error. If you need precision, the only reliable path is querying the primary government source directly. The SSA has an API now that returns raw counts without the rounding layer. The NISR in the U.K. offers downloadable tables. But even direct access has limits — the data is what governments choose to publish, not necessarily what exists.
Practical Workflow That Actually Works
Start with the tool for a quick estimate. Then verify through a primary source. Run the name through the normalization step yourself — check for alternate spellings, hyphen variants, and phonetic equivalents before you commit to a count. If the name has diacritics, test both with and without the marks. For hyphenated names, query each component separately and add the results. Document the source and date of each lookup, because these databases get updated periodically and old counts become stale. When I audit name frequency data for clients, I typically allow two hours for a thorough verification of a single name against three sources. A quick lookup takes about three minutes. The gap between those two numbers is where most mistakes happen. If someone tells you a name exists in exactly 7,291 records, ask which database, which year, and whether the count includes alternate spellings. Those three questions will expose most of the problems before you build a decision on the number.