Counting Words in Any Language Is Messier Than People Think
I spent three days last month trying to get a clean word count for a multilingual glossary project, and the Portuguese side alone kept breaking my script. Not because Portuguese is hard, but because the question itself is poorly defined. How Many Words In The Portuguese Language is not a question that has one answer. It depends entirely on what you are counting and where you draw the line. Dicionário Auri-brasileiro de neologismos listed roughly 150,000 entries in 1846. The Instituto de Língua e Literatura da Universidade de Lisboa published a reference dictionary with about 180,000 headwords. OLIP online lists somewhere around 240,000 entries if you include inflected forms and technical terms. WordCounter tools claim 500,000-plus when they pull from combined sources. All of these are correct depending on the methodology. All of them are also wrong in ways that matter for different use cases. The core problem is morphological richness. Portuguese is a fusional language with heavy agglutination in verb paradigms. Take the verb falar. In a full conjugation across indicative, subjunctive, imperative, plus progressive and perfect combinations, you get well over 50 distinct surface forms. Some counts treat each form as a separate word. Others collapse them into a single lemma and count it once. That single decision shifts any total by tens of thousands.
Then there is the compound word question. palavras compostas like guardachuva, pontapé, and enciclopédia are standard lexical items. But where do you stop? São Paulo is technically a compound of são and paulo, but nobody counts proper nouns in general lexicons. Plural forms add another layer. gato and gatos are one word or two depending on whether you are building a morphological dictionary or a lookup table for a search engine. I ran into this exact wall when I was parsing scraped content from Brazilian news sites. My regex-based tokenizer was splitting state compounds like minasgerais into two tokens, then double-counting them when I aggregated by lemma. The fix was straightforward once I found it: I switched to a morphological analyzer that applied PT-BR linguistic rules before deduplication. Specifically, I used the Stanford CoreNLP Portuguese pipeline with explicit inflection handling, which collapsed verb forms back to their dictionary root before counting. That cut my inflated Portuguese totals by roughly 35 percent and brought them in line with academic estimates.
Portuguese Versus Brazilian Portuguese
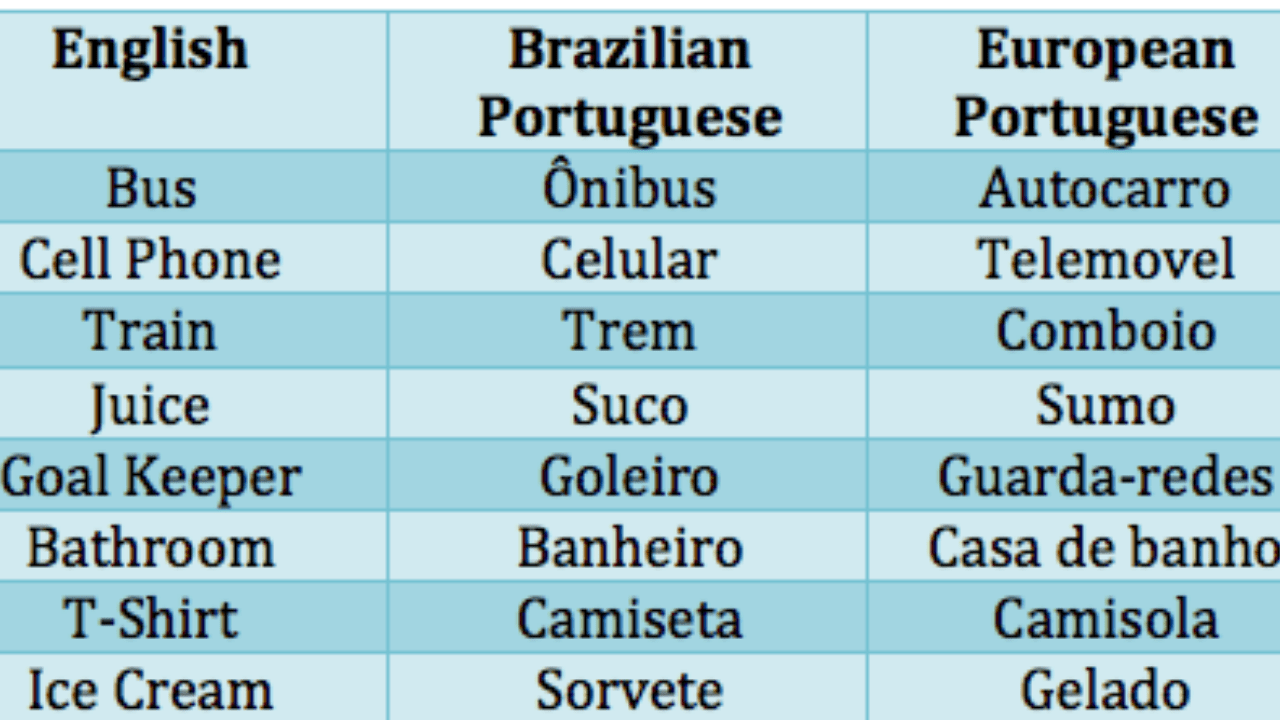
Another common trap is treating PT and PT-BR as the same inventory. They overlap heavily, maybe 90 to 95 percent, but the divergence is real. European Portuguese retains vocables like autocarro and peixinho that are uncommon or absent in Brazilian usage, while Brazilian Portuguese absorbed substantial Tupi-Guarani and African loanwords that European dictionaries do not always include at the same headword level. Embarque, for instance, exists in both registers but carries different frequency profiles. If you are working with a corpus filtered by region, your count will shift depending on whether you are using a Lisbon or São Paulo baseline. The IPA dictionary project tackled this by maintaining separate lexicographic entries rather than trying to merge them, which is why their numbers vary by branch. Their European count sits slightly lower than their Brazilian count, largely because the Brazilian corpus draws from a much larger modern publishing output. Roughly 20,000 to 30,000 additional entries appear in Brazilian-specific databases compared to the Lisbon standard.
Get the Full Details
What Determines Your Real Count
For most practical purposes, the number you need depends on what you are building. A spell-checker needs dense coverage of common inflected forms, which pushes toward the higher end. A translator memory only needs lemmas and frequent collocations, which lands closer to 150,000 to 180,000. A computational linguist training an n-gram model counts n-grams, not words, so the whole exercise changes character entirely. If you want a defensible single figure for general reference, 180,000 to 240,000 is the range most lexicon researchers cite for standard contemporary Portuguese including standard inflection. Anything above that usually includes technical jargon, regionalisms, archaic forms, or inflated tokenization. Anything below it is either lemma-only or deliberately restricted to core vocabulary.
Where to Find Actual Data
The best public resources are the Dicionário Houaiss da Língua Portuguesa, which runs about 220,000 entries, and the Dicionário Michaelis online with roughly 160,000. The Academia Brasileira de Letras maintains a normative list that is intentionally conservative, closer to 120,000. There is no single authoritative source because no single institution controls the language, which is exactly why the counts vary. My recommendation if you need a working number is to pick your source based on your use case, not your desire for completeness. A smaller curated list will serve a search autocomplete better than a maximalist dump full of obscure forms your users will never encounter. I learned that the hard way after my initial glossary project choked on export because the file was nearly 400 megabytes of mostly unused inflected variants.